
LLMs

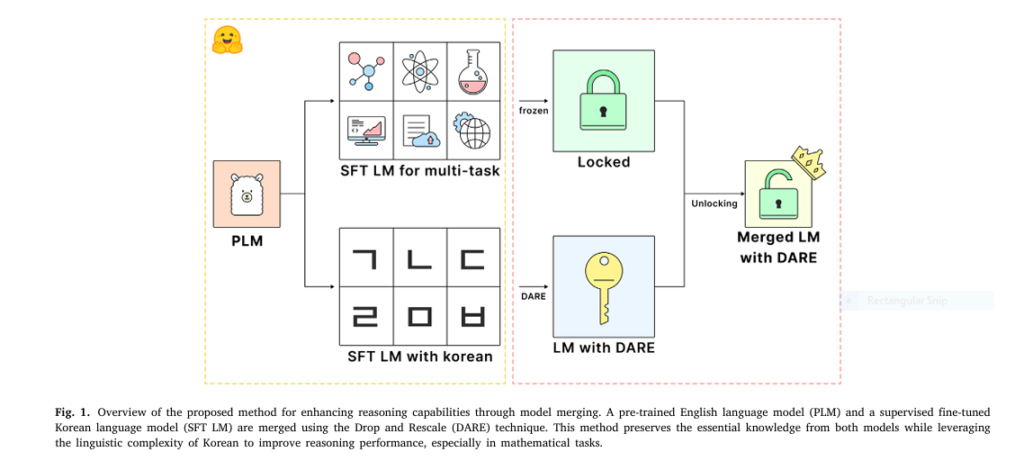
Infographic showing a neural network merging English and Korean language models with dramatic performance increase arrows and a red warning sign for cultural bias.

7 Shocking Ways Merging Korean Language Models Boosts LLM Reasoning (And 1 Dangerous Pitfall to Avoid)

In the rapidly evolving world of artificial intelligence, Large Language Models (LLMs) are hitting performance ceilings—especially when it comes to complex reasoning tasks like math and logic. But what if the key to unlocking their next-level intelligence lies not in bigger data or more compute, but in a surprisingly specific language? A groundbreaking 2025 study […]
7 Shocking Ways Merging Korean Language Models Boosts LLM Reasoning (And 1 Dangerous Pitfall to Avoid) Read More »

KDRL Unifies Distillation And Reinforcement Learning

KDRL Unifies Distillation And Reinforcement Learning

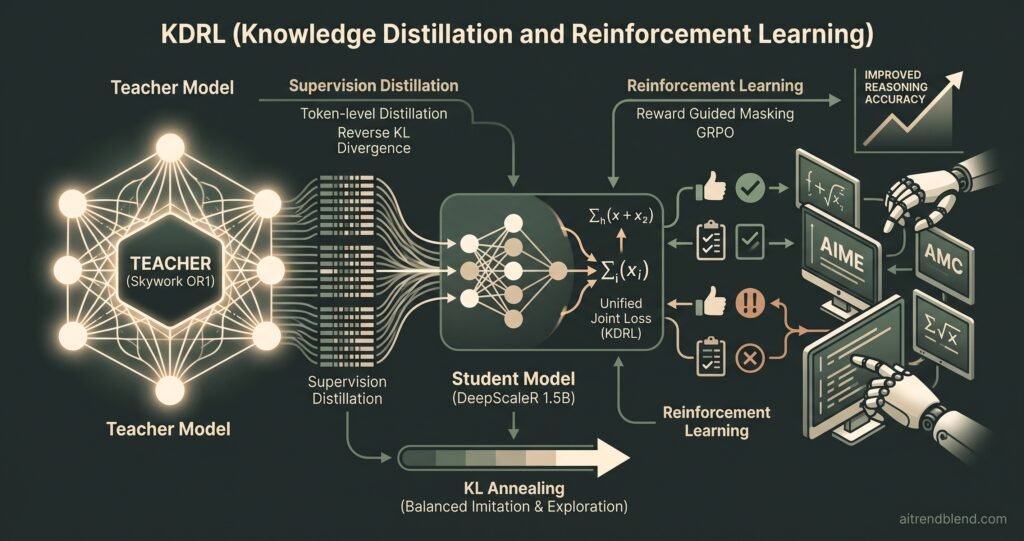
Analysis by the aitrendblend editorial team · Pillar, Knowledge distillation and model compression · Source paper, arXiv:2506.02208 Knowledge Distillation Reinforcement Learning Reasoning LLMs GRPO Post Training KDRL, one loss, two teachers, teacher supervision and reward explorationKDRL folds teacher supervision and reward driven exploration into a single training objective rather than running them as separate stages.

KDRL Unifies Distillation And Reinforcement Learning Read More »

POCL: How A Progressive Overload Curriculum Improves LLM Distillation

POCL: How A Progressive Overload Curriculum Improves LLM Distillation

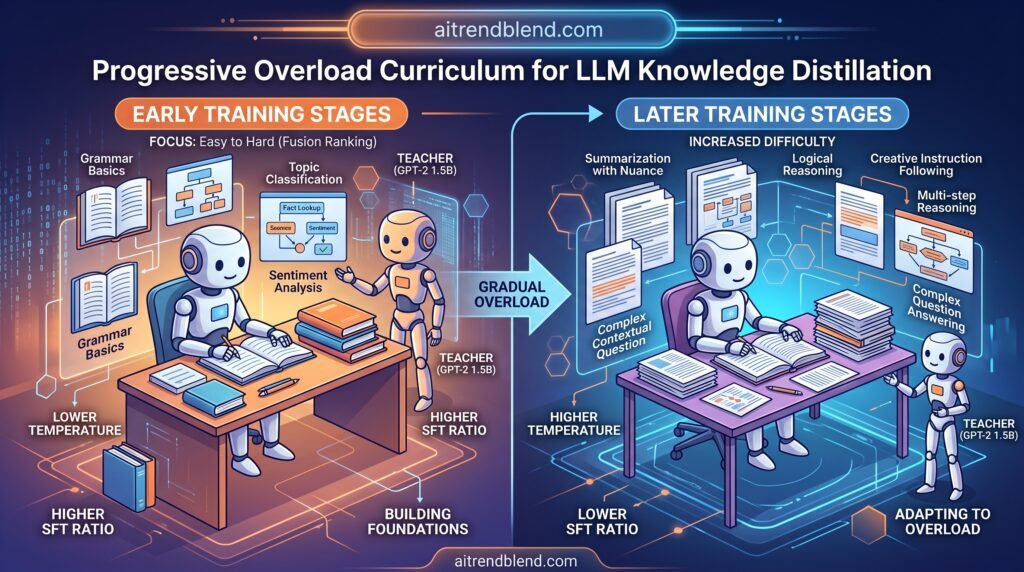
Knowledge distillation and model compression pillar. Reading time about thirteen minutes. Analysis by the aitrendblend editorial team, no clinical claims are made in this piece. knowledge distillation curriculum learning model compression large language models GPT-2 A new athlete does not start their first day at the gym with the heaviest weight on the bar, and

POCL: How A Progressive Overload Curriculum Improves LLM Distillation Read More »