vision-language models

DAIT: Distilling CLIP into Tiny Classifiers with an Adaptive Intermediate Teacher

DAIT: Distilling CLIP into Tiny Classifiers with an Adaptive Intermediate Teacher

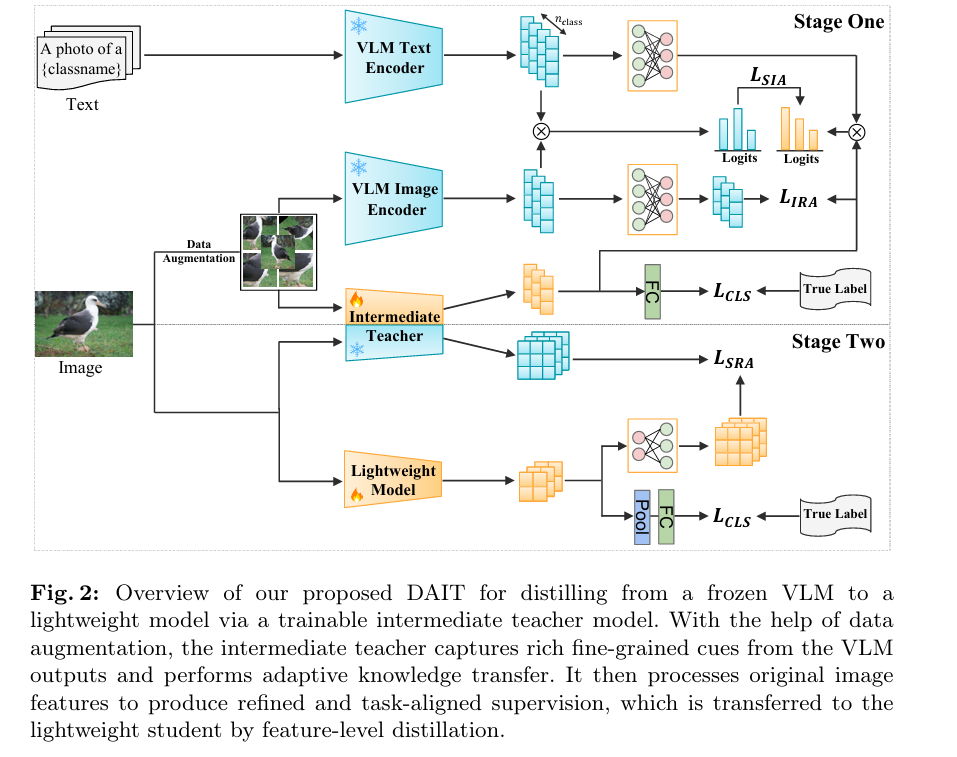
DAIT: Distilling CLIP into Tiny Classifiers with an Adaptive Intermediate Teacher | AI Trend Blend Fine-Grained Vision · Model Compression · arXiv:2603.15166 | Nanjing Normal University · Westlake University (2026) · 20 min read DAIT: Why You Should Never Ask CLIP to Directly Teach ResNet-18 — And What to Do Instead Researchers at Nanjing Normal […]

DAIT: Distilling CLIP into Tiny Classifiers with an Adaptive Intermediate Teacher Read More »
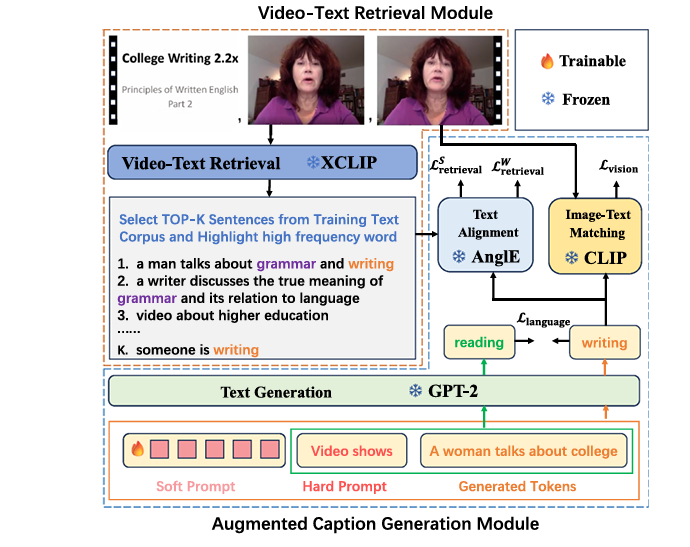
Discover RETTA: the first retrieval-enhanced test-time adaptation framework for zero-shot video captioning.

RETTA: Retrieval-Enhanced Test-Time Adaptation for Zero-Shot Video Captioning

RETTA: Revolutionizing Zero-Shot Video Captioning with Retrieval-Enhanced Test-Time Adaptation In the rapidly evolving field of vision-language modeling, the ability to automatically generate accurate and contextually relevant descriptions of video content—known as video captioning—has become a cornerstone for applications ranging from assistive technology for the visually impaired to intelligent video search engines. While supervised models have

RETTA: Retrieval-Enhanced Test-Time Adaptation for Zero-Shot Video Captioning Read More »

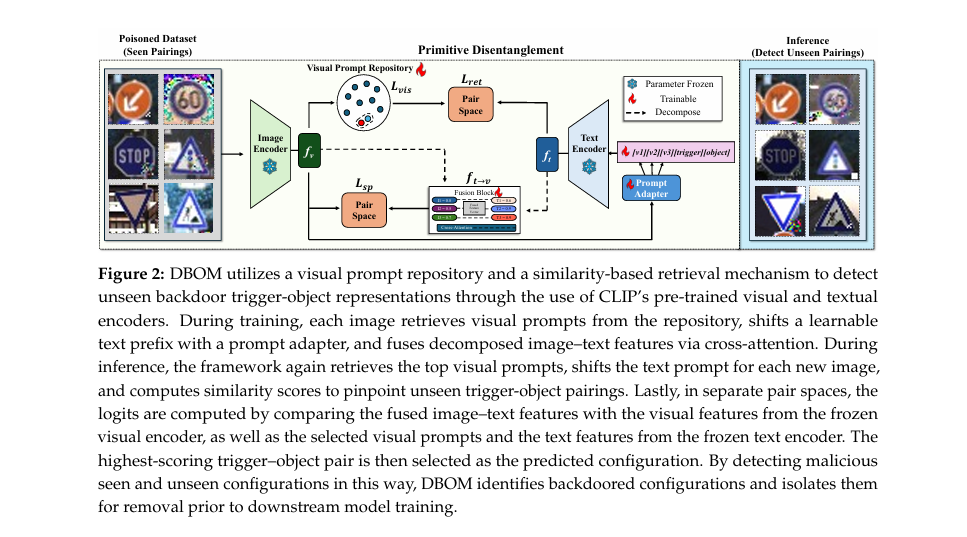
DBOM Defense framework in action: AI-powered system detecting hidden backdoor triggers in traffic signs using disentangled modeling and zero-shot learning

7 Shocking AI Vulnerabilities Exposed—How DBOM Defense Turns the Tables with 98% Accuracy

In the rapidly evolving world of artificial intelligence, security threats are growing faster than defenses—and one of the most insidious dangers is the backdoor attack. These hidden exploits allow hackers to manipulate AI models from within, often without detection until it’s too late. But now, a groundbreaking new framework called DBOM Defense (Disentangled Backdoor-Object Modeling)

7 Shocking AI Vulnerabilities Exposed—How DBOM Defense Turns the Tables with 98% Accuracy Read More »

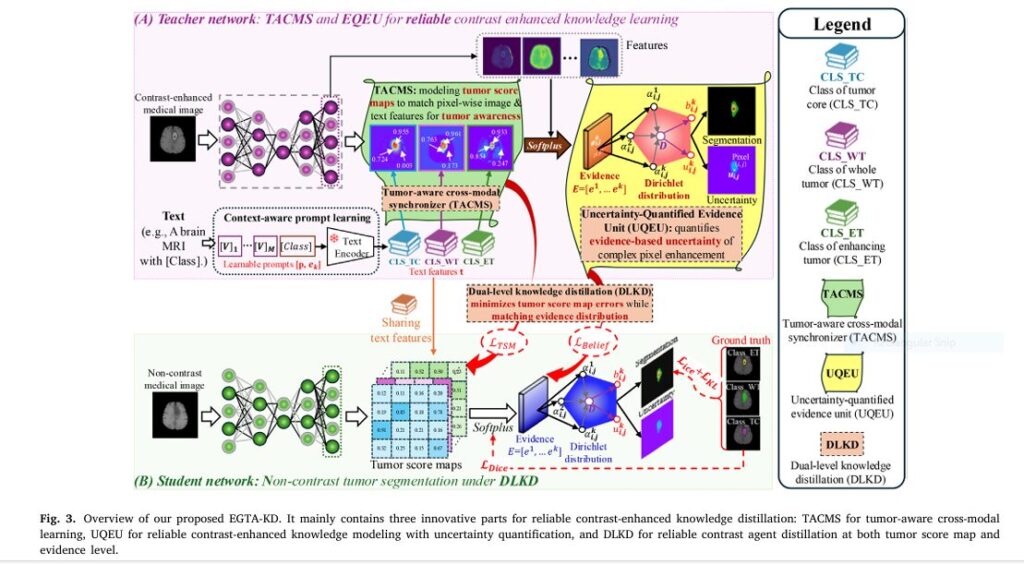
Medical AI transforming tumor segmentation with EGTA-KD technology

Revolutionary AI Breakthrough: Non-Contrast Tumor Segmentation Saves Lives & Avoids Deadly Risks

Imagine detecting deadly tumors without injecting risky contrast agents. A revolutionary AI framework called EGTA-KD is making this possible, achieving near-perfect segmentation (90.8% accuracy) on non-contrast scans while eliminating allergic reactions and kidney damage linked to traditional methods. This isn’t futuristic hype – it’s validated across brain, liver, and kidney tumors in major clinical datasets. The Deadly Cost of Current

Revolutionary AI Breakthrough: Non-Contrast Tumor Segmentation Saves Lives & Avoids Deadly Risks Read More »

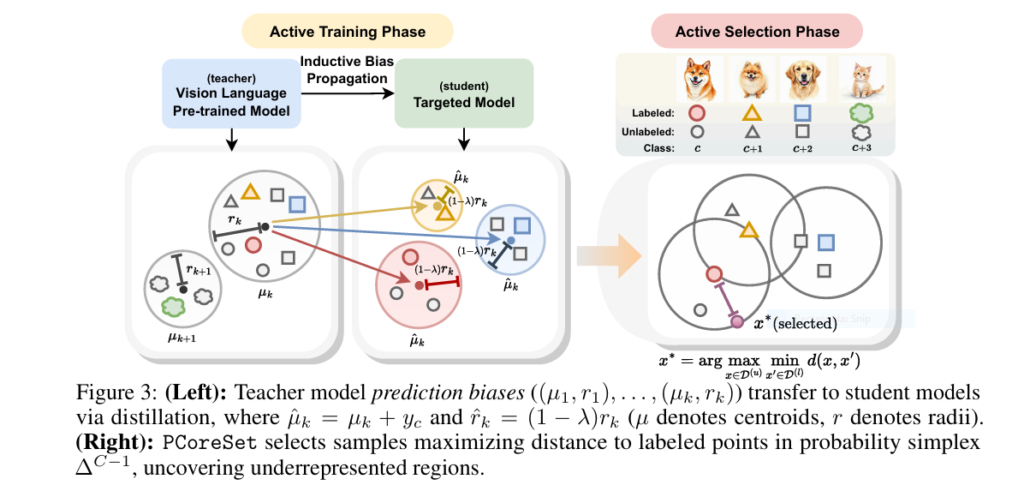
Vision-language model distilling knowledge to a compact AI, reducing training costs by 90% with ActiveKD and PCoreSet

How ActiveKD Uses VLM Bias To Guide Active Learning

Analysis by the aitrendblend editorial team · Pillar, Knowledge distillation and model compression · Source paper, arXiv:2506.00910 Knowledge Distillation Active Learning Vision Language Models CLIP Coreset Selection ActiveKD, one biased teacher, a coreset built in probability space Every active learning paper has the same starting problem. Labeling data is expensive, so you want an algorithm

How ActiveKD Uses VLM Bias To Guide Active Learning Read More »