SLGNet: Structural Priors and Language-Guided Modulation for Multimodal Object Detection
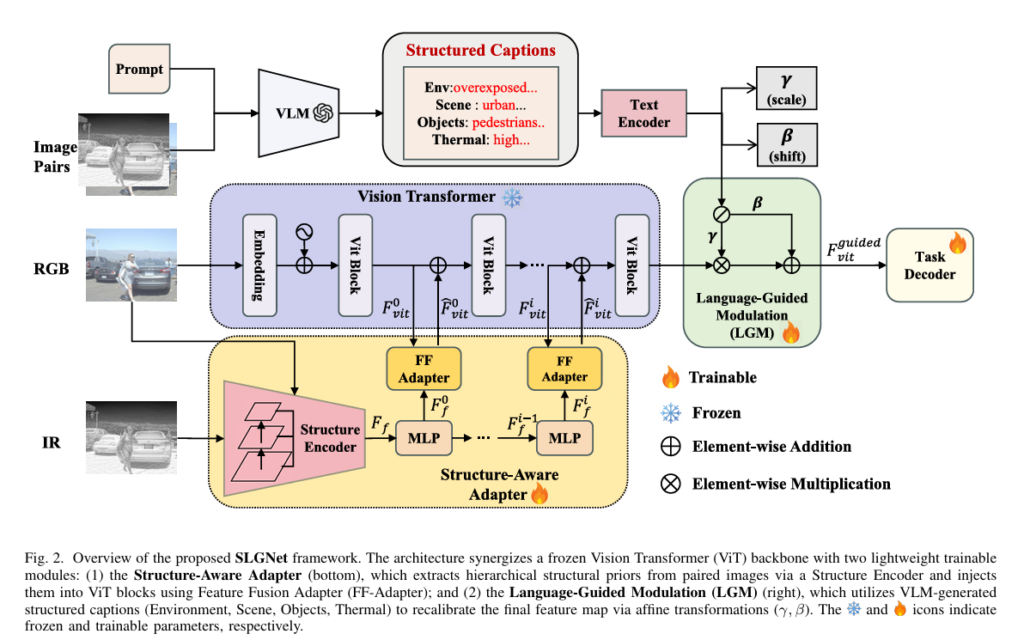
Researchers at the Chinese Academy of Sciences built a multimodal object detector that freezes 88% of its parameters, asks a language model to describe the scene, and still beats every fully fine-tuned competitor — including on aerial drone footage at…
SLGNet: Structural Priors and Language-Guided Modulation for Multimodal Object Detection Read More »