
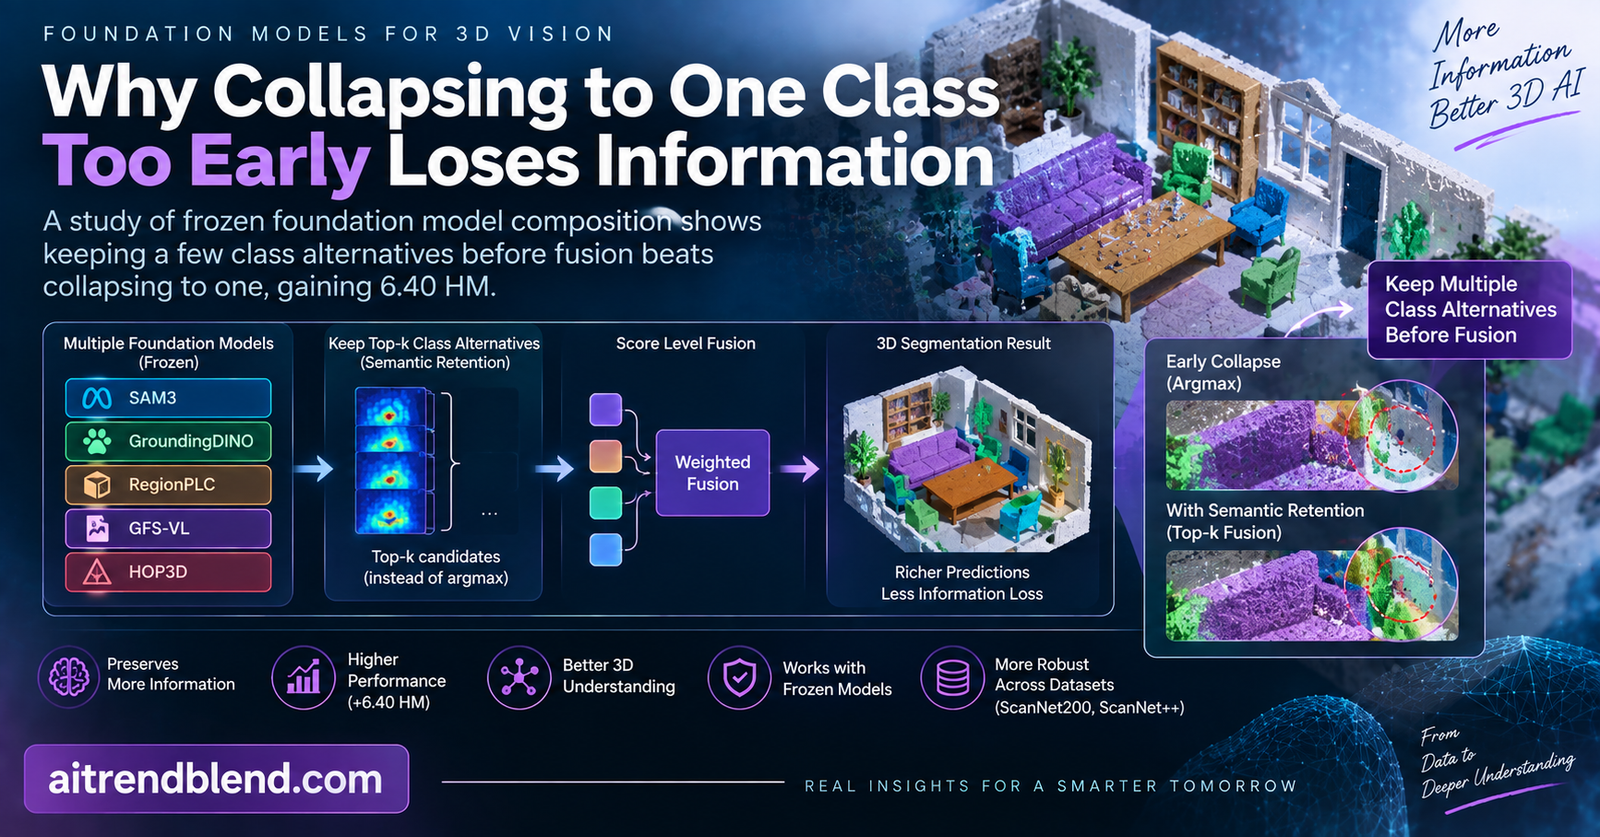
Modern perception systems are increasingly built by bolting pretrained models together rather than training one big model end to end. You take a 3D model that understands language, add an image model that can segment on command, wire them with some geometry, and let them vote. It is cheap and it reuses enormous pretrained knowledge. But a pair of researchers at the University of Ghana noticed that these systems almost always make the same quiet mistake, and that mistake throws away exactly the information the models were combined to share.
Key points
- When two frozen foundation models are combined, the usual pipeline collapses each one’s ranked guesses to a single class before they interact, which permanently deletes their second and third choices.
- The study keeps everything else frozen and varies only how many class alternatives survive before fusion, isolating that one choice as the cause.
- Keeping the full ranked list instead of the top guess raised the harmonic mean score by 6.40 points on a held out 3D benchmark, and the pattern held on a second dataset.
- The biggest jump came from keeping just one extra alternative, and a compact list of the top few actually beat keeping the whole tail, which can add noise.
- Fancier confidence weighting could not recover the lost information, which shows the problem is what gets discarded, not how the survivors are weighted.
The quiet mistake in combining models
Here is where it gets interesting. When a model classifies something, it does not just output a label. Internally it produces a distribution, a ranked list of how likely each class is. A 3D point on a chair leg might come out as 70 percent chair, 20 percent table, 5 percent stool, and so on. The final answer is whichever class is on top, an operation called argmax, but that top guess is a summary that throws away the ranking behind it.
Now combine two models. The common pipeline reduces each model to its single top guess first, and then decides which model to trust or lets them vote. The paper writes this ordering plainly, source distributions become a hard class by argmax, and only then does selection or voting happen. The alternative ordering keeps the ranked lists alive until after the models have interacted, and only collapses to a single class at the very end.
The final prediction uses argmax either way. What changes is when the irreversible collapse happens. And it matters enormously in this setting, because the two models are heterogeneous. A dense 3D vision language model can spread its belief across several related classes. A sparse image based segmenter, lifted into 3D through camera views, offers strong evidence but only for some points. If both are flattened to their top guess before they meet, any second choice that might have agreed across the two models is gone forever, unavailable to any later selector, calibrator, or reliability model. The authors call this premature semantic collapse, and their whole paper is a careful measurement of how much it costs.
They even prove it cannot be undone. A short argument shows that no rule that sees only the per source top guesses can reproduce what averaging the full distributions would give. Consider a dense model that outputs 90 percent for class one and a sparse model that outputs 51 percent for class two. Both reduce to the tuple, class one from the first, class two from the second. Now consider a different pair, 51 percent class one and 90 percent class two. That reduces to the same tuple. Averaging the real distributions gives different answers for the two cases, but any rule seeing only the collapsed tuple must treat them identically. The collapse is a genuine, irreversible loss of information.
A clean experiment
What makes the study convincing is its restraint. Rather than proposing a new fusion algorithm and claiming it wins, the authors change exactly one thing and hold everything else fixed. They take a frozen dense source, a model called RegionPLC that assigns language aligned class scores to every 3D point, and a frozen sparse source, a SAM3 concept mask stack lifted from multiple camera views. The model weights, the masks, the geometry, the class vocabulary, the scene lists, and even the fusion rule, a plain equal weight average, are all frozen and untouched.
The only knob they turn is how many class alternatives survive before the two sources are averaged. They apply a top k retention operator that keeps the k largest entries of each distribution, zeroes the rest, and renormalizes.
Setting k to one is exactly the argmax collapse, the pre collapse control. Setting k to the full vocabulary keeps everything. The fused prediction applies the same operator to both sources and averages them.
By sweeping k through the values one, two, five, ten, twenty, and full, the experiment reads off how much semantic support needs to survive before the two heterogeneous sources interact. Because everything else is identical, any change in accuracy is caused by that retention alone. It is a controlled intervention rather than a comparison between different systems.
What the retention curve shows
The main result is on ScanNet200, a 200 class 3D benchmark, evaluated on a held out half of the scenes. Performance is reported as a harmonic mean of accuracy on base classes and novel classes, which balances the two so a method cannot win by ignoring the rare novel categories.
| Retention | Base mIoU | Novel mIoU | HM | Change vs top 1 |
|---|---|---|---|---|
| Top 1 (argmax collapse) | 45.13 | 20.80 | 28.47 | 0.00 |
| Top 2 | 45.48 | 24.49 | 31.83 | +3.36 |
| Top 5 | 47.42 | 27.08 | 34.48 | +6.00 |
| Top 10 | 47.33 | 28.02 | 35.20 | +6.73 |
| Top 20 | 46.95 | 28.53 | 35.49 | +7.02 |
| Full | 44.43 | 28.70 | 34.87 | +6.40 |
Two things jump out. First, moving from the top guess to keeping just one more alternative, top 1 to top 2, delivers the single largest jump, 3.36 points of harmonic mean. That is the moment the second choices become available to agree across sources. Second, the curve is not strictly increasing. Keeping the top 20 actually beats keeping the full distribution by 0.62 points, because the very low probability tail can add noise. The lesson is not that full distributions are always best. It is that you should not collapse to a single class before heterogeneous evidence has interacted, and a compact list of plausible alternatives recovers most of the benefit while suppressing the junk.
The effect replicates on a second dataset, ScanNet++, which uses different sensors, camera poses, and a smaller 30 class space. There, full retention beats the top guess by 3.48 points, and again the biggest jump is the very first relaxation from top 1 to top 2. Because the second dataset changes almost everything about the setup, the improvement cannot be an artifact of one benchmark’s quirks. This kind of composed 3D understanding is the same territory as work on turning 3D scenes into object sequences a model can reason over.
The useful principle is not preserve every tail entry. It is do not collapse to a single class before heterogeneous evidence has interacted. A small candidate set recovers most of the benefit. Reading of the retention curves
Better weighting cannot save you
The obvious objection is that maybe the collapse is fine and you just need a smarter way to weight the two collapsed sources. The authors test this directly and the answer is no. They compare the plain equal weight average against three more sophisticated schemes, one that calibrates each source’s confidence, one that scales each source by a global reliability estimate, and one that weights each candidate by local context.
| Method | Base | Novel | HM |
|---|---|---|---|
| Frozen hard selector | 41.84 | 20.49 | 27.51 |
| Matched top 1 fusion | 45.13 | 20.80 | 28.47 |
| Uniform full distribution averaging | 44.43 | 28.70 | 34.87 |
| Calibrated probability fusion | 45.44 | 27.82 | 34.51 |
| Global reliability fusion | 45.70 | 27.56 | 34.38 |
| Contextual probability fusion | 44.06 | 20.31 | 27.80 |
| Oracle source selector | 51.94 | 36.27 | 42.71 |
The plain average of full distributions, at 34.87, edges out the calibrated and global reliability schemes and crushes the contextual one, which falls all the way back to 27.80. The interpretation is a clean negative result. Selector complexity cannot recover semantic alternatives once they have been discarded. The representation you hand to the arbitration rule matters more than the sophistication of the rule itself. And keeping the distributions is not merely about miscalibration, because even after the authors fix the sources’ badly miscalibrated confidences, the calibrated fusion still sits below plain averaging, which means calibration and semantic retention are two distinct problems, and fixing one does not fix the other. Getting reliable confidence out of composed models is its own challenge, close in spirit to work on scoring how much to trust a model’s answer.
Making sure it is not a fluke
The paper spends real effort ruling out mundane explanations. It swaps the sparse source entirely, replacing the SAM3 stack with a GroundingDINO and SAM2.1 pipeline on the same scenes, and the retention effect reappears, so the finding is not specific to one particular segmenter. It checks that the top 1 baseline is the strongest possible version of the collapse rather than a weak straw man, confirming the 6.40 point gain is the smallest honest gap, not an inflated one. It tries alternative fusion operators beyond averaging, a max rule and a geometric pooling, and every distribution level operator beats the hard collapse control. It even notes that the geometric operator scored highest of all, at 36.16, but refuses to promote it to the headline because it was tested after the main experiment was frozen, which is an unusually disciplined bit of scientific hygiene.
Honest limitations
The authors are careful about what they are not claiming. They explicitly do not claim that averaging probabilities is a new idea, because combining classifier scores rather than hard votes is a classical result from the 1990s. Their contribution is the controlled diagnosis of when the collapse happens in modern frozen foundation model systems, not a new fusion rule.
The optimal amount of retention is not fixed. Moderate top k slightly beats full retention on both datasets, but exactly how many alternatives to keep depends on the source pair, the class space, and how ambiguous the local region is, so an adaptive scheme would be needed rather than a single magic number. There is also an asymmetry baked into the second dataset, where the sparse source only carries evidence for the novel classes, so full fusion raises novel accuracy but lowers base accuracy, and the authors make no claim of improvement on every metric at once. Their own failure case is instructive, one scene where keeping the full distribution scored 12.25 points below the top guess, because there the diffuse tail of the sparse source conflicted with a confident and correct dense prediction. Preserved alternatives are not automatically helpful.
Two more honest notes. Keeping full distributions costs memory, roughly 18 gigabytes of cache for the 200 class dataset, so an on device deployment would favor the short top k lists the study also validates. And this is a study of combining frozen models at inference time, not a claim that training or fine tuning is unnecessary. The frozen system here does not match the absolute accuracy of methods that actually adapt to the few shot examples, and the authors present those trained numbers only as a scale reference, not as a competition they are trying to win.
Why the idea travels
The lesson reaches far past 3D segmentation. Any time you compose heterogeneous systems that exchange only their final decisions, you risk erasing the complementary evidence that made composing them worthwhile in the first place. The paper points at multimodal routing and language model ensembling as places the same failure could hide. Wherever cross source complementarity lives in the second and third choices rather than the top one, an early hard decision destroys it before combination has a chance to use it. The same value of keeping heterogeneous sources in a rich form until they meet drives work on state space models for multimodal fusion.
The second lesson is methodological. This paper is a model of how to isolate a mechanism. Freeze everything, vary one thing, measure the effect with confidence intervals, then attack your own result from every angle to rule out alternative explanations. The finding is modest in size and enormous in clarity precisely because the experiment was designed to attribute the effect to a single cause. That discipline is worth copying regardless of the subject.
Conclusion
This work takes a decision that almost every composed perception system makes without thinking, when to collapse a model’s ranked guesses into a single class, and turns it into an object of careful study. The answer it finds is simple and a little surprising. Collapsing too early, before the models have had a chance to compare notes, throws away information that no downstream step can recover, and simply delaying that collapse is worth a real accuracy gain.
The conceptual shift is to treat semantic retention as a variable rather than an assumption. Systems default to the top guess because it is convenient, but that convenience has a measurable cost, and the cost is largest at the very first step, keeping one extra alternative instead of none. Beyond a handful of alternatives the benefit saturates and the noisy tail can even hurt, so the right rule is to keep a compact set of plausible candidates until after the sources interact, then collapse.
The evidence is careful and bounded. Full retention beat the top guess by 6.40 points on ScanNet200 and 3.48 on ScanNet++, with confidence intervals that exclude zero, and the effect survived a change of sparse model, alternative fusion operators, and a calibration fix. The negative result on weighting is just as valuable, because it shows the gain comes from what is retained, not from how the survivors are combined, which is a sharper and more useful conclusion than a new fusion algorithm would have been.
The honest limitations keep expectations grounded. The best amount of retention depends on the sources and the scene, keeping full distributions costs memory, one dataset’s structure produces a base against novel trade off, and a frozen composition still trails methods that train on the few shot examples. None of these weaken the core diagnosis, which is that the order of collapse is a repeatable information bottleneck in heterogeneous frozen model composition.
For anyone building systems by combining pretrained models, which is more and more of applied machine learning, the practical takeaway is small and concrete. Do not reduce each model to its single best guess before the models meet. Keep a short ranked list, let the sources agree or disagree across their alternatives, and only then commit to an answer. The gain is not dramatic, but it is free, it needs no retraining, and it comes from respecting information the models already produced and that most pipelines quietly throw away.
Reference implementation in Python
The code below is a compact, runnable sketch of the paper’s core mechanism, the top k retention operator, the matched equal weight fusion of a dense and a sparse source, the final argmax prediction, the harmonic mean metric, and a retention ladder loop that shows how accuracy changes as more alternatives survive, with a smoke test on dummy distributions. It captures the intervention faithfully for study, standing in for the frozen foundation models with simple arrays.
# semantic_retention.py
# Study reference for the top k semantic retention intervention. The real study
# uses frozen RegionPLC and SAM3 sources. Here small arrays stand in so the
# mechanism runs anywhere. Ends with a smoke test on dummy data.

import numpy as np


def top_k_retain(pi, k):
    """Keep the k largest entries of a distribution, zero the rest, renormalize.
    k = 1 is the argmax collapse, k = len(pi) is full retention."""
    pi = np.asarray(pi, dtype=float)
    if k >= pi.size:
        keep = pi
    else:
        thresh_idx = np.argsort(pi)[-k:]           # indices of the k largest
        keep = np.zeros_like(pi)
        keep[thresh_idx] = pi[thresh_idx]
    total = keep.sum()
    return keep / total if total > 0 else keep


def matched_fusion(pi_dense, pi_sparse, k, has_sparse=True):
    """Apply the same top k retention to both sources, then average, eq 13.
    Where no sparse evidence exists, the dense distribution is kept as is."""
    d = top_k_retain(pi_dense, k)
    if not has_sparse:
        return d
    s = top_k_retain(pi_sparse, k)
    return 0.5 * d + 0.5 * s


def predict(pi):
    return int(np.argmax(pi))            # the final collapse still uses argmax


def miou(preds, labels, classes):
    """Mean intersection over union over a set of classes."""
    preds, labels = np.asarray(preds), np.asarray(labels)
    ious = []
    for c in classes:
        inter = np.sum((preds == c) & (labels == c))
        union = np.sum((preds == c) | (labels == c))
        if union > 0:
            ious.append(inter / union)
    return np.mean(ious) if ious else 0.0


def harmonic_mean(base, novel, eps=1e-9):
    """HM balances base and novel accuracy, eq 16."""
    return 2 * base * novel / (base + novel + eps)


def retention_ladder(dense, sparse, has_sparse, labels, base_cls, novel_cls,
                     ks=(1, 2, 5, 10, 20, None)):
    """Sweep k and report HM at each retention level. None means full."""
    n_classes = dense.shape[1]
    results = []
    for k in ks:
        kk = n_classes if k is None else k
        preds = [predict(matched_fusion(dense[i], sparse[i], kk, has_sparse[i]))
                 for i in range(len(labels))]
        b = miou(preds, labels, base_cls)
        nvl = miou(preds, labels, novel_cls)
        results.append(("full" if k is None else k, harmonic_mean(b, nvl)))
    return results


def smoke_test():
    rng = np.random.default_rng(0)
    n_points, n_classes = 400, 8
    labels = rng.integers(0, n_classes, n_points)
    # dense source, correct but spreads mass over related classes
    dense = rng.random((n_points, n_classes)) * 0.3
    dense[np.arange(n_points), labels] += 1.0
    dense /= dense.sum(1, keepdims=True)
    # sparse source, sharp and often right but only for some points
    sparse = rng.random((n_points, n_classes)) * 0.1
    sparse[np.arange(n_points), labels] += 2.0
    sparse /= sparse.sum(1, keepdims=True)
    has_sparse = rng.random(n_points) < 0.6       # sparse covers 60 percent of points
    base_cls, novel_cls = list(range(5)), list(range(5, 8))
    for k, hm in retention_ladder(dense, sparse, has_sparse, labels, base_cls, novel_cls):
        print(f"retention {k:>4}  HM {hm*100:.2f}")


if __name__ == "__main__":
    smoke_test()
Running the smoke test prints the harmonic mean at each retention level on the dummy sources, and the top 1 row is typically the lowest, echoing the paper’s central finding that collapsing to a single class before fusion leaves accuracy on the table. The top k operator is the piece to watch, since setting k to one reproduces the argmax collapse exactly while larger k keeps the alternatives that let the two sources agree.
Frequently asked questions
What is premature semantic collapse?
It is reducing a model’s full ranked list of class guesses to its single top guess before that model is combined with another one. Because the collapse is irreversible, any second or third choice that might have agreed across models is permanently lost before they interact.
What did the study actually change?
Only the number of class alternatives kept before two frozen models are averaged. The model weights, masks, geometry, class vocabulary, scene lists, and the fusion rule were all held fixed, so any change in accuracy is caused by that retention alone.
How much does keeping alternatives help?
On ScanNet200, keeping the full distribution instead of the top guess raised the harmonic mean by 6.40 points, and on ScanNet++ by 3.48 points, with confidence intervals that exclude zero. The single largest gain came from keeping just one extra alternative.
Is keeping the full distribution always best?
No. A compact set of the top few alternatives usually recovers most of the benefit, and on ScanNet200 keeping the top 20 slightly beat keeping everything, because the very low probability tail can add noise. The rule is to avoid an early collapse, not to keep every entry.
Could smarter weighting fix the collapse instead?
No. Calibrated, reliability weighted, and contextual weighting schemes all failed to beat plain averaging of the full distributions, and fixing the sources’ confidence calibration did not close the gap either. The lost information cannot be recovered by weighting what survives.
What are the main limitations?
The best amount of retention depends on the source pair and the scene, keeping full distributions costs memory, one dataset’s structure trades base accuracy for novel accuracy, and this frozen composition does not match methods that train on the few shot examples. Preserved alternatives are also not always helpful.
Read the full paper for every retention ladder, robustness check, and proof.
Read the paper on arXiv Code repository if released