Multimodal AI

Models that combine images, text, audio, and clinical signals. We cover fusion architectures, missing-modality robustness, and cross-modal alignment, with an emphasis on what actually improves when modalities are combined.

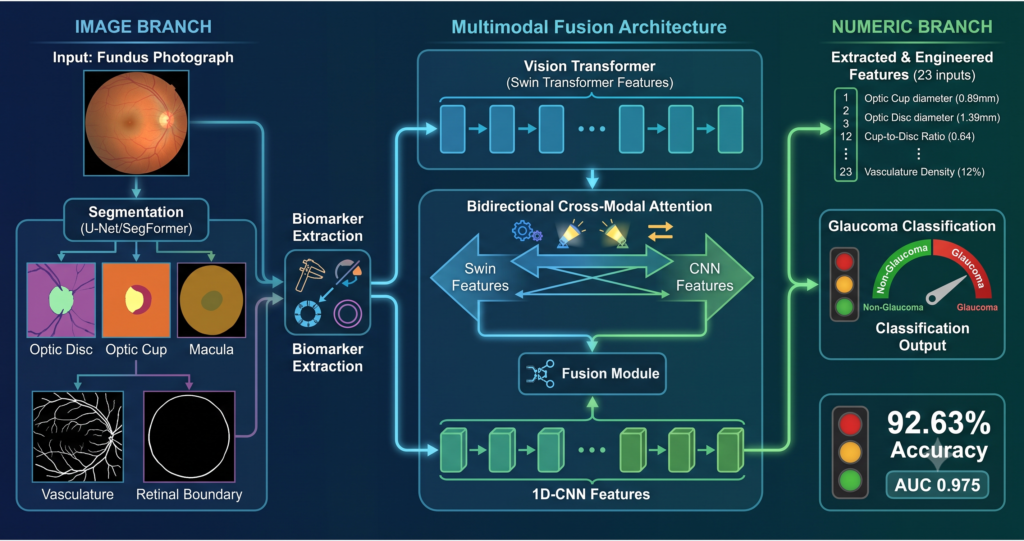
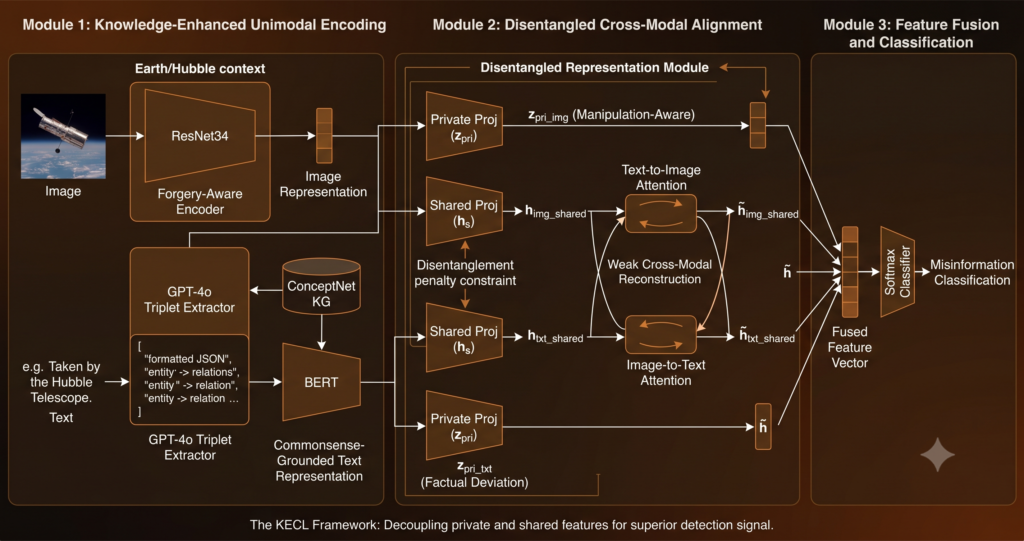
How Multimodal Glaucoma Classification Fuses Segmentation-Derived Biomarkers with Vision Transformer Features

How Multimodal Glaucoma Classification Fuses Segmentation-Derived Biomarkers with Vision Transformer Features

Glaucoma causes progressive damage to the optic nerve and often develops without any early symptoms. This makes early glaucoma detection incredibly vital because existing treatments can only halt or slow down the damage rather than reversing it. Most traditional AI…

How Multimodal Glaucoma Classification Fuses Segmentation-Derived Biomarkers with Vision Transformer Features Read More »

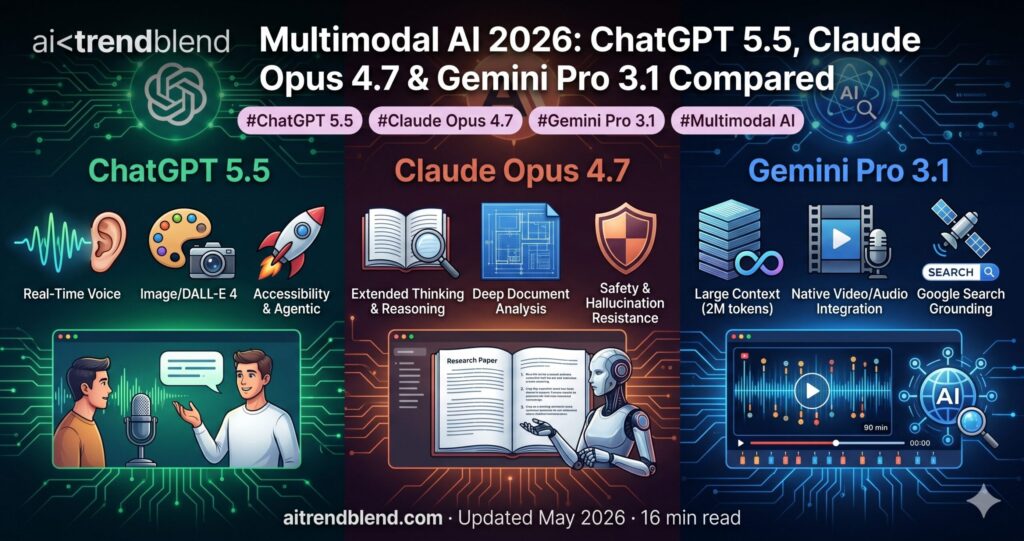
Multimodal AI 2026: ChatGPT 5.5, Claude Opus 4.7 & Gemini Pro 3.1 Compared.

Multimodal AI 2026: ChatGPT 5.5, Claude Opus 4.7 & Gemini Pro 3.1 Compared

Priya had three things open on her screen: a 90-minute product strategy video, a 180-page market research PDF, and a spreadsheet of competitor pricing data. Her deadline was in two hours. Three months ago she would have spent those two…

Multimodal AI 2026: ChatGPT 5.5, Claude Opus 4.7 & Gemini Pro 3.1 Compared Read More »

Multimodal AI in 2026: Tools That Seamlessly Integrate Text, Image, Audio, and Video.

Multimodal AI in 2026: Tools That Seamlessly Integrate Text, Image, Audio, and Video

A broadcast journalist uploads a 45-minute interview recording, three pages of handwritten research notes, and a folder of reference photographs to a single AI session — and asks for a production-ready script. Five minutes later, she has a structured 2,000-word…

Multimodal AI in 2026: Tools That Seamlessly Integrate Text, Image, Audio, and Video Read More »