Large Language Models

Large language models — architectures, training, evaluation, and the tools built on them.

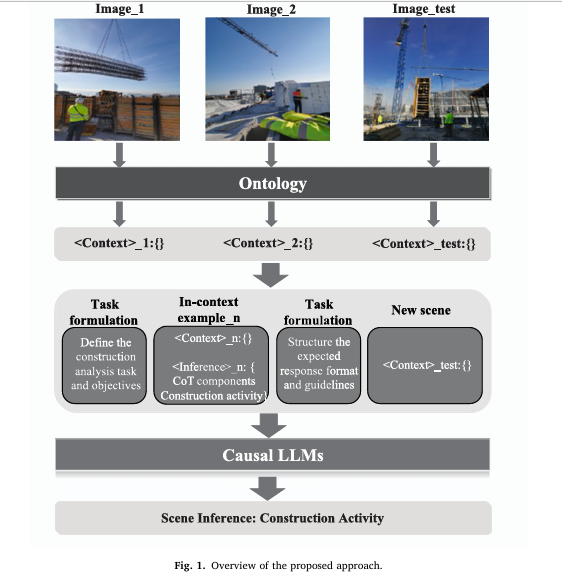
Ontology-Based LLM Prompting for Construction Activity Recognition: 73.68% Accuracy With No Training Data.

Ontology-Based LLM Prompting for Construction Activity Recognition: 73.68% Accuracy With No Training Data

Ontology-Based LLM Prompting for Construction Activity Recognition: 73.68% Accuracy With No Training Data | AI Trend Blend AITrendBlend Machine Learning Computer Vision Engineering AI About Researchers at Technische Universität Berlin and Qingdao University of Technology achieved 73.68% construction activity recognition…
Ontology-Based LLM Prompting for Construction Activity Recognition: 73.68% Accuracy With No Training Data Read More »

Agentic AI for Personalized Knee Braces: How sEMG, Facial Expressions, and LLMs Combine to Configure Rehab Devices

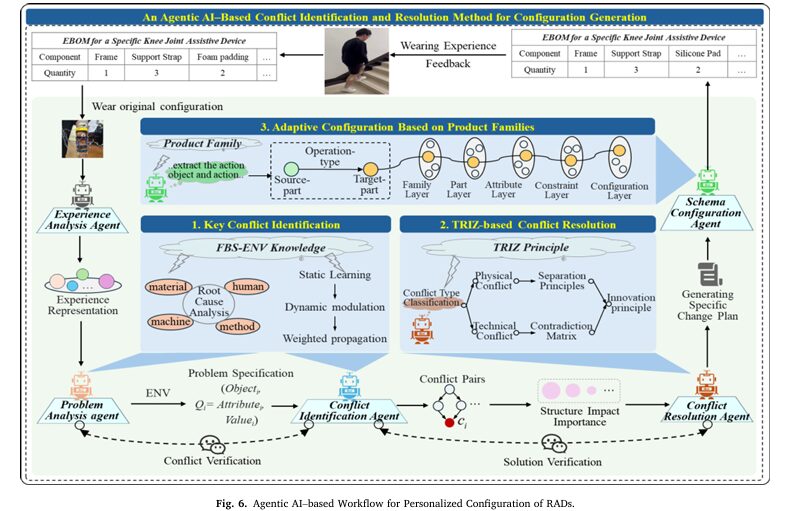
Agentic AI for Personalized Knee Braces: How sEMG, Facial Expressions, and LLMs Combine to Configure Rehab Devices | AI Trend Blend AITrendBlend Machine Learning Computer Vision About Donghua University’s five-agent AI system cross-checks muscle signals against facial expressions and verbal…

Agentic AI for Personalized Knee Braces: How sEMG, Facial Expressions, and LLMs Combine to Configure Rehab Devices Read More »

MetaClaw: The LLM Agent That Meta-Learns and Evolves in the Wild.

MetaClaw: The LLM Agent That Meta-Learns and Evolves in the Wild

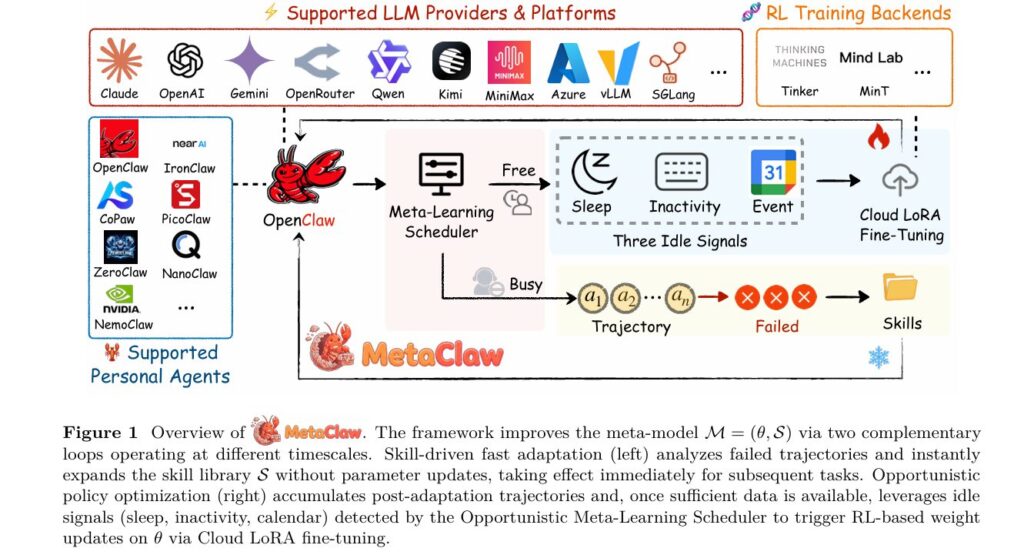
MetaClaw: The LLM Agent That Meta-Learns and Evolves in the Wild | AI Trend Blend Researchers from UNC-Chapel Hill, Carnegie Mellon, UC Santa Cruz, and UC Berkeley built a continual meta-learning framework that gives deployed language model agents two complementary…

MetaClaw: The LLM Agent That Meta-Learns and Evolves in the Wild Read More »

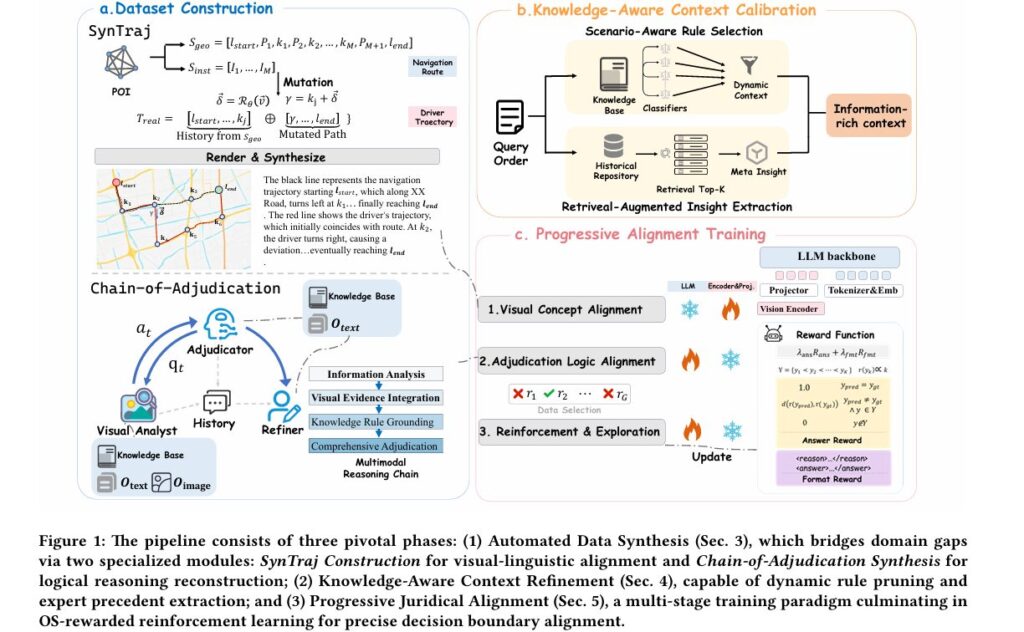
RideJudge: How an 8B Model Outperforms 32B Baselines at Ride-Hailing Dispute Resolution

RideJudge: How an 8B Model Outperforms 32B Baselines at Ride-Hailing Dispute Resolution

RideJudge: How an 8B Model Outperforms 32B Baselines at Ride-Hailing Dispute Resolution | AI Trend Blend AITrendBlend Machine Learning Computer Vision About Researchers from Nanjing University and Didi Chuxing built a multimodal LLM framework that reads GPS maps like a…

RideJudge: How an 8B Model Outperforms 32B Baselines at Ride-Hailing Dispute Resolution Read More »

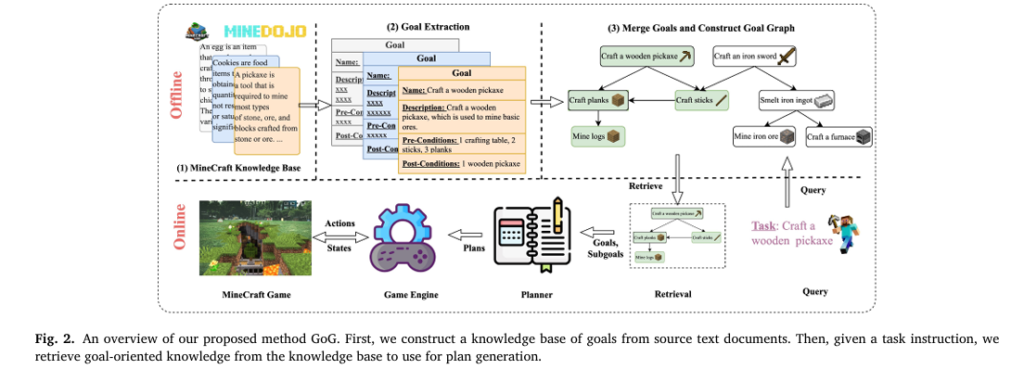
Goal-Oriented Graphs: How NTU Researchers Finally Taught LLMs to Plan Like Humans in Minecraft.

Goal-Oriented Graphs: How NTU Researchers Finally Taught LLMs to Plan Like Humans in Minecraft

Goal-Oriented Graphs: How NTU Researchers Finally Taught LLMs to Plan Like Humans in Minecraft | AI Trend Blend LLM Agents & Reasoning GraphRAG shreds procedural knowledge into thousands of disconnected fragments. A new framework from Nanyang Technological University puts it…

Goal-Oriented Graphs: How NTU Researchers Finally Taught LLMs to Plan Like Humans in Minecraft Read More »

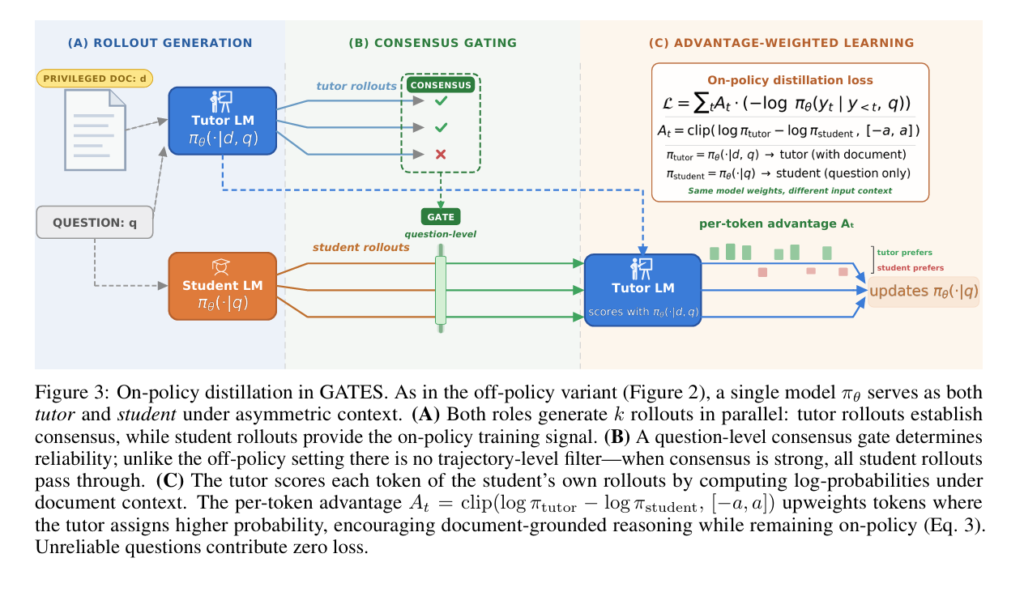
GATES: How Consensus Gating Fixed the Broken Promise of Self-Distillation in Language Models.

GATES: How Consensus Gating Fixed the Broken Promise of Self-Distillation in Language Models

GATES: How Consensus Gating Fixed the Broken Promise of Self-Distillation in Language Models | AI Trend Blend Researchers at the University of Maryland trained a model to teach itself — without any ground-truth labels, external graders, or verifiable rewards —…

GATES: How Consensus Gating Fixed the Broken Promise of Self-Distillation in Language Models Read More »

Overview of DSKD training.

DSKD: How Sense Dictionaries Are Finally Making Decoder LLMs Smarter Without Slowing Them Down

DSKD: How Sense Dictionaries Are Finally Making Decoder LLMs Smarter Without Slowing Them Down | AI Research AITrendBlend Machine Learning About How researchers at RPI and IBM Research taught generative LLMs to understand word senses, synonyms, and antonyms during training—without…

DSKD: How Sense Dictionaries Are Finally Making Decoder LLMs Smarter Without Slowing Them Down Read More »

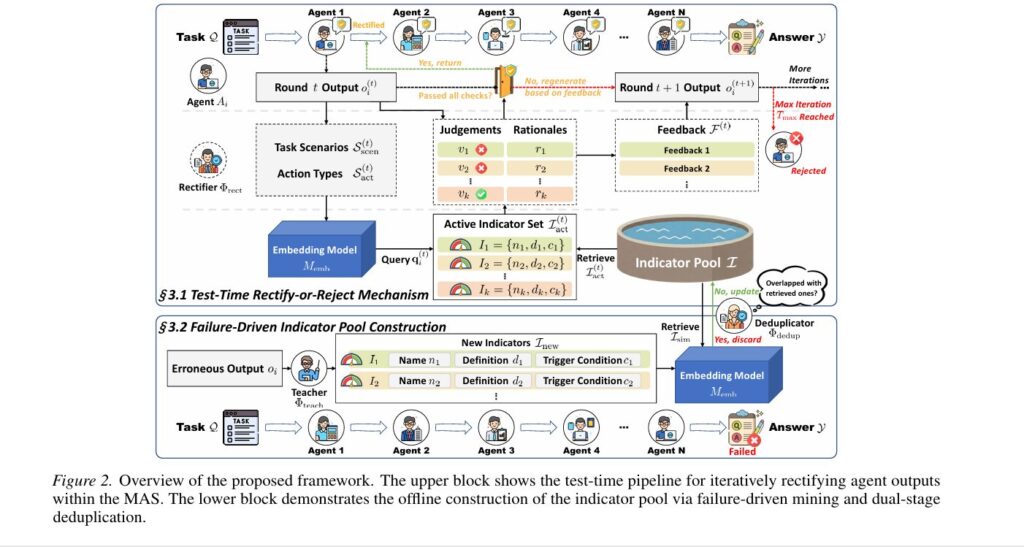
AgentDropoutV2: Test-Time Rectify-or-Reject Pruning for Multi-Agent Systems.

AgentDropoutV2: Test-Time Rectify-or-Reject Pruning for Multi-Agent Systems

AgentDropoutV2: Test-Time Rectify-or-Reject Pruning for Multi-Agent Systems | AI Security Research AISecurity Research Machine Learning About A novel test-time framework that intercepts and iteratively rectifies erroneous agent outputs using retrieval-augmented adversarial indicators, achieving 6.3% accuracy improvement on mathematical reasoning benchmarks…

AgentDropoutV2: Test-Time Rectify-or-Reject Pruning for Multi-Agent Systems Read More »

DGRM: How Advanced AI is Learning to Detect Machine-Generated Text Across Different Domains

DGRM: How Advanced AI is Learning to Detect Machine-Generated Text Across Different Domains

In an era where artificial intelligence generates text that’s increasingly indistinguishable from human writing, distinguishing authentic human content from machine-generated material has become critical. Large language models like GPT-4, Claude, and others produce remarkably coherent text, raising legitimate concerns about…

DGRM: How Advanced AI is Learning to Detect Machine-Generated Text Across Different Domains Read More »

Construction Site Intelligence with Ontology-Based LLM Prompting

Unlocking Construction Site Intelligence with Ontology-Based LLM Prompting

In the fast-paced world of construction, real-time insights into on-site activities are crucial. Understanding what workers are doing, how equipment is being used, and whether tasks align with schedules can make or break a project’s success. Traditionally, this has relied…

Unlocking Construction Site Intelligence with Ontology-Based LLM Prompting Read More »