
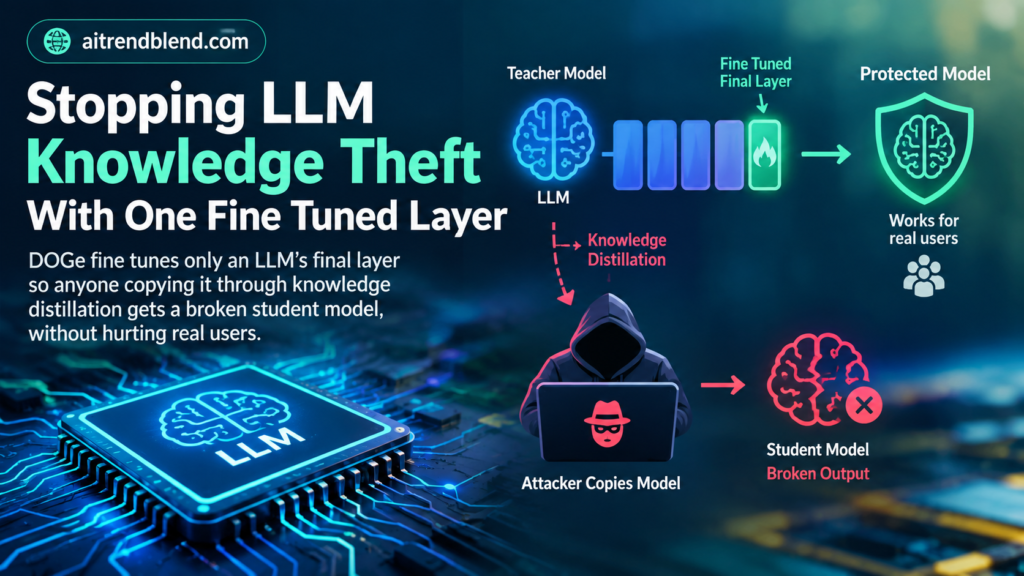
Doge: Stopping LLM Knowledge Theft With One Fine Tuned Layer
Analysis by the aitrendblend editorial team · Pillar 2, Knowledge Distillation and Model Compression · 13 minute read Knowledge Distillation Model IP Protection Adversarial Training LLM Security PyTorch DOGe retrains only the final layer of a teacher LLM so that any student model trained on its outputs learns a broken version of its reasoning. A […]
Doge: Stopping LLM Knowledge Theft With One Fine Tuned Layer Read More »