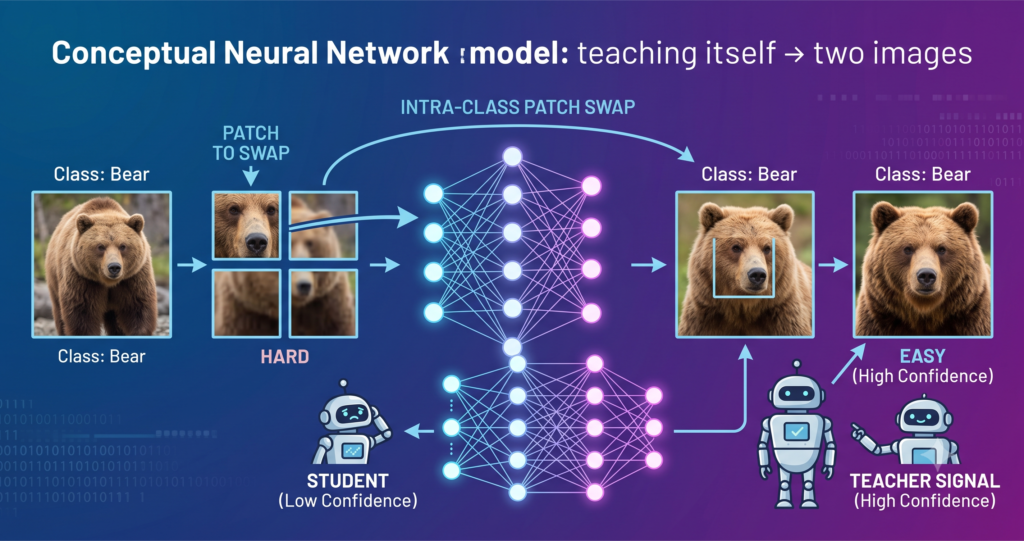
A Single Model Can Now Teach Itself Through Patch Swaps
Knowledge distillation has been one of the most reliable tools for making a smaller, deployable model perform closer to a large, expensive one. The classic recipe trains a big teacher network first, then trains a compact student to mimic the…
A Single Model Can Now Teach Itself Through Patch Swaps Read More »