
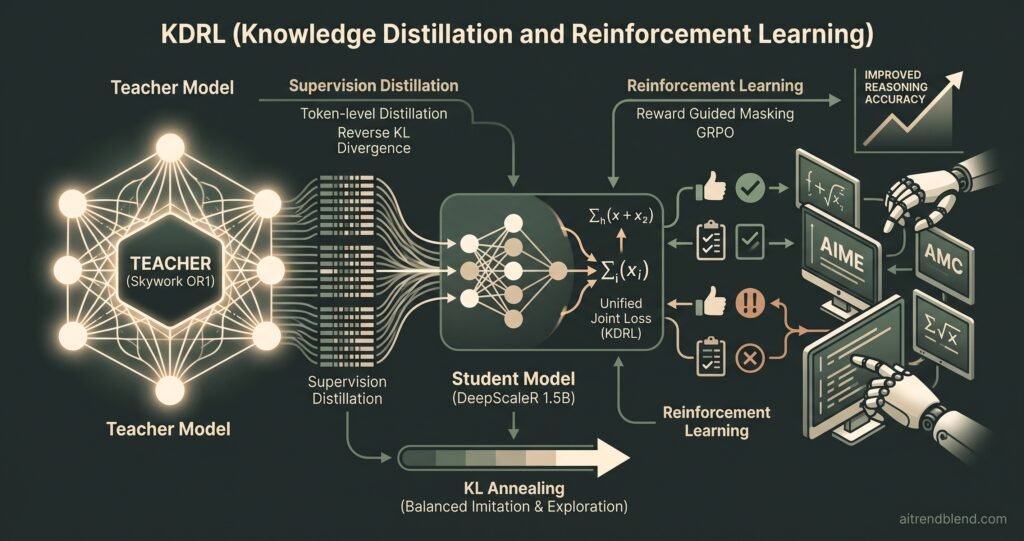
KDRL Unifies Distillation And Reinforcement Learning
DeepSeek R1 made two things obvious to anyone paying attention. Reinforcement learning can pull genuinely new reasoning behavior out of a language model that supervised training alone never produces, and distilling from a strong reasoning model is often the faster,…
KDRL Unifies Distillation And Reinforcement Learning Read More »