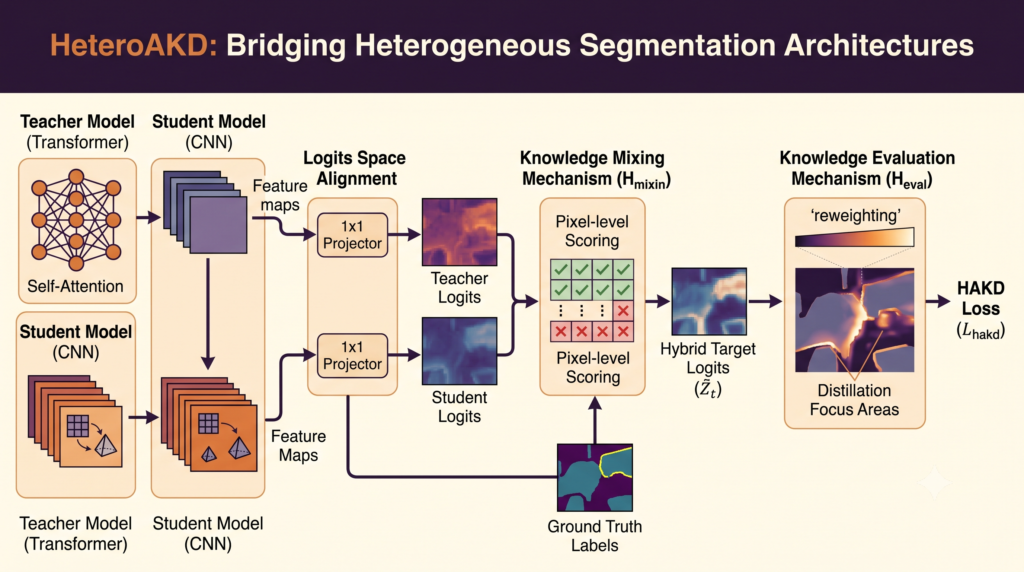
HeteroAKD Bridges CNN and Transformer Segmentation Models
Knowledge distillation for segmentation usually assumes the teacher and the student came from the same architectural gene pool. Train a big ResNet, shrink it into a small ResNet, transfer the soft labels or the intermediate features, done. That assumption made…
HeteroAKD Bridges CNN and Transformer Segmentation Models Read More »