
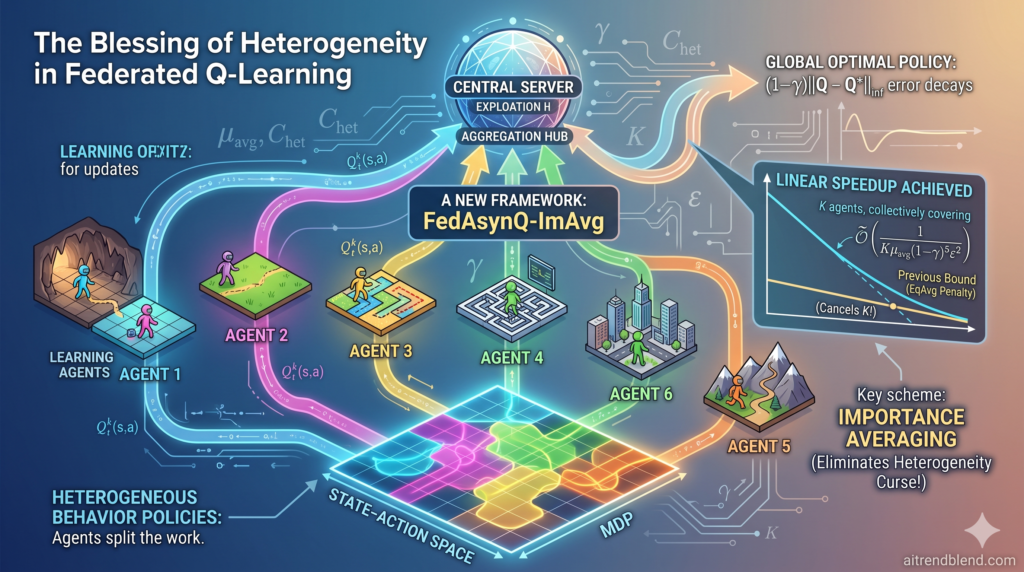
The Blessing of Heterogeneity in Federated Q-Learning: Linear Speedup and Beyond
A team from Carnegie Mellon University flipped conventional wisdom on its head — proving that agents with different behavior policies don’t just tolerate each other’s differences, they actively benefit from them. And a novel importance-averaging scheme eliminates the last remaining…
The Blessing of Heterogeneity in Federated Q-Learning: Linear Speedup and Beyond Read More »