Optimization & Learning Theory

The mathematics under the hood: optimization methods, convergence guarantees, and the theory that explains when and why deep learning works. Explainers that take proofs seriously without losing the reader.

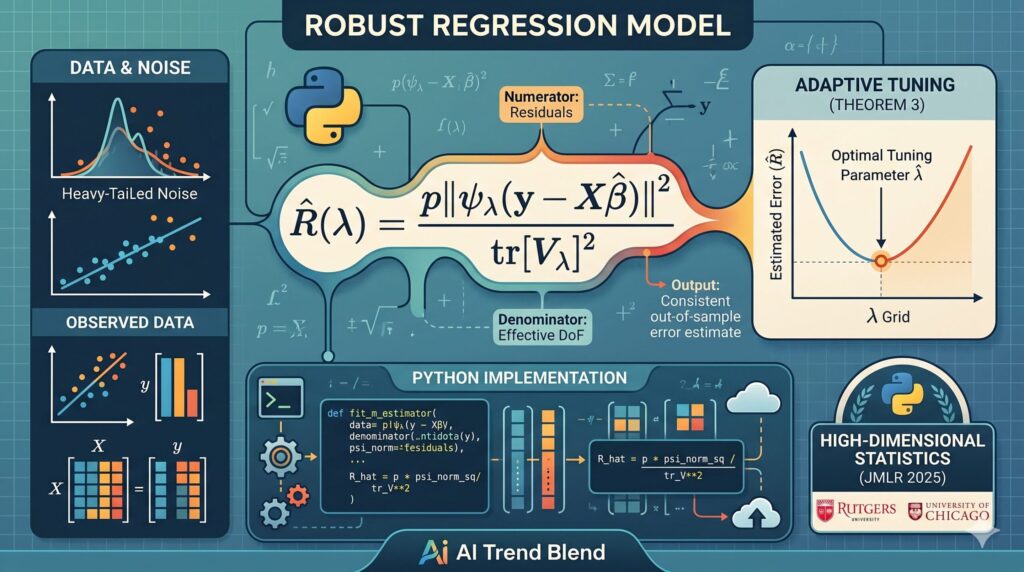
How to Tune a Robust Regression Model Without Knowing the Noise: Adaptive Error Estimation for Unregularized M-Estimators.

How to Tune a Robust Regression Model Without Knowing the Noise: Adaptive Error Estimation for Unregularized M-Estimators

Pierre C. Bellec (Rutgers) and Takuya Koriyama (Chicago Booth) prove that a simple, fully observable formula consistently estimates the prediction error of any Huber-class M-estimator in high dimensions — and that minimizing it over a grid of scale parameters automatically…
How to Tune a Robust Regression Model Without Knowing the Noise: Adaptive Error Estimation for Unregularized M-Estimators Read More »

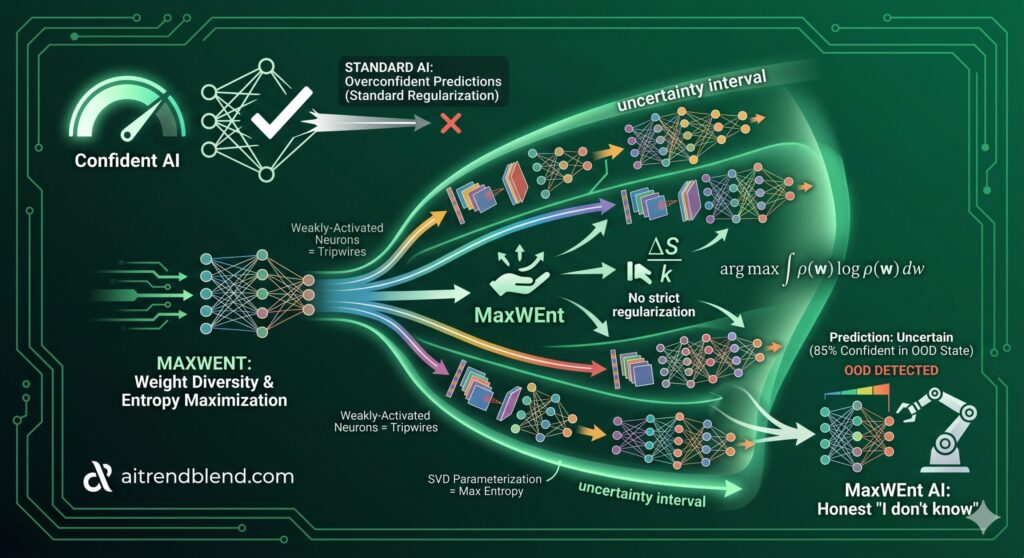
Why Your AI Says It's Confident When It Shouldn't Be — And How MaxWEnt Fixes It.

Why Your AI Says It’s Confident When It Shouldn’t Be — And How MaxWEnt Fixes It

Researchers from Michelin and the Centre Borelli at ENS Paris-Saclay have built a smarter way to make neural networks say “I don’t know” — by maximizing the diversity of possible network weights rather than relying on standard regularization that quietly…

Why Your AI Says It’s Confident When It Shouldn’t Be — And How MaxWEnt Fixes It Read More »