The Crippling Tradeoff That Held Spiking Deep Reinforcement Learning Back for Years — And How a Dynamic Replay Buffer Finally Shatters It
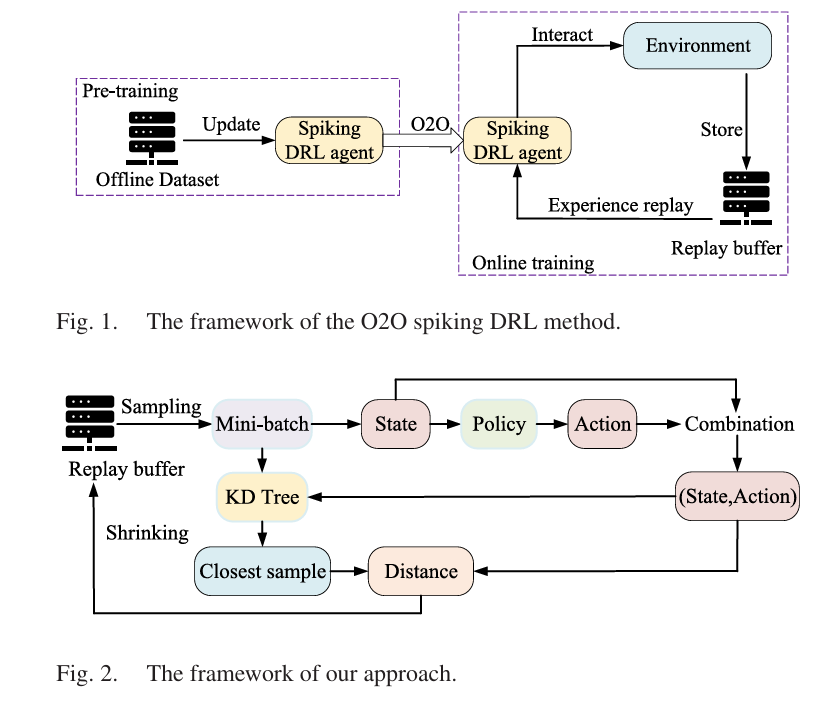
Researchers at City University of Hong Kong built a plug-and-play resilient experience replay framework that lets spiking DRL methods run at ultra-low simulation durations without the catastrophic performance collapse everyone had learned to accept.