Computer Vision

Computer vision is one of our deepest areas, covering how machines learn to see, segment, and reason about images and video. Articles here range from convolutional and transformer based architectures to dense prediction tasks like detection and segmentation, with regular coverage of medical imaging where reliable vision models carry real clinical weight. The emphasis stays on what makes a method work and where it breaks, backed by the original research.

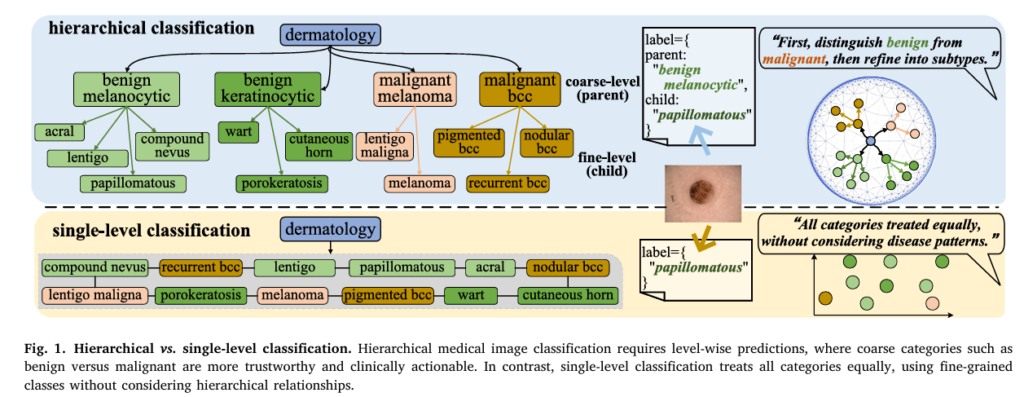
H2CL: Dual-Geometry Hyperbolic-Euclidean Image-Text Learning for Medical Hierarchical Classification.

H2CL: Dual-Geometry Hyperbolic-Euclidean Image-Text Learning for Medical Hierarchical Classification

H2CL: Dual-Geometry Hyperbolic-Euclidean Image-Text Learning for Medical Hierarchical Classification | AI Trend Blend AITrendBlend Machine Learning Computer Vision Medical AI About Medical AI · Medical Image Analysis, Vol. 112 (2026) · 20 min read Why Flat Classifiers Fail Doctors: H²CL Uses Hyperbolic Geometry to Teach AI the Clinical Hierarchy of Disease A UNSW Sydney team […]
H2CL: Dual-Geometry Hyperbolic-Euclidean Image-Text Learning for Medical Hierarchical Classification Read More »

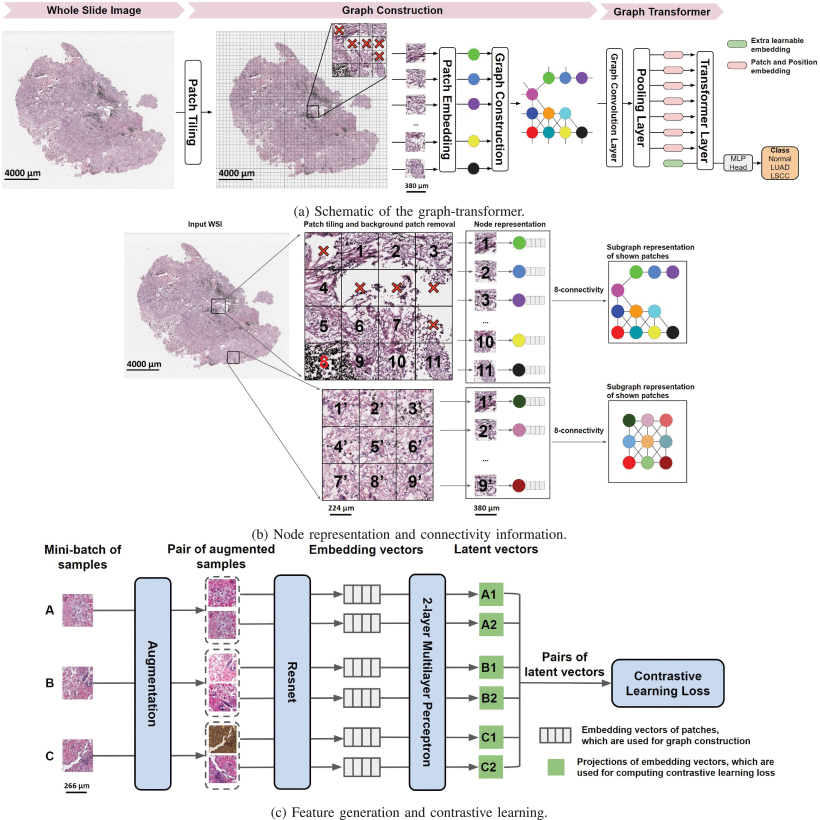
GTP: The Graph-Transformer That Reads Whole Slide Pathology Images Like a Pathologist

GTP: The Graph-Transformer That Reads Whole Slide Pathology Images Like a Pathologist

GTP: The Graph-Transformer That Reads Whole Slide Pathology Images Like a Pathologist | AI Trend Blend AITrendBlend Machine Learning Computer Vision Medical AI About Medical AI · IEEE Transactions on Medical Imaging, Vol. 41, Nov. 2022 · 22 min read GTP: The Model That Learned to Read Cancer Slides the Way a Pathologist Actually Does

GTP: The Graph-Transformer That Reads Whole Slide Pathology Images Like a Pathologist Read More »

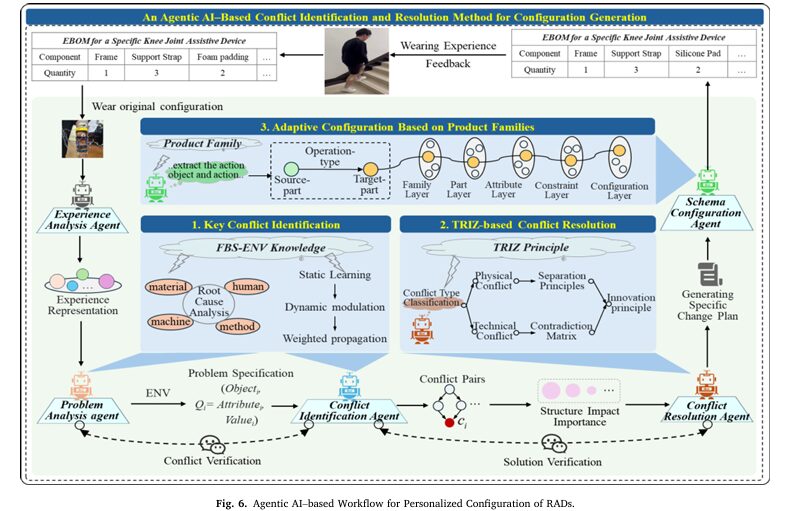
Agentic AI for Personalized Knee Braces: How sEMG, Facial Expressions, and LLMs Combine to Configure Rehab Devices

Agentic AI for Personalized Knee Braces: How sEMG, Facial Expressions, and LLMs Combine to Configure Rehab Devices | AI Trend Blend AITrendBlend Machine Learning Computer Vision About Healthcare AI · Advanced Engineering Informatics 74 (2026) 104695 · 22 min read Your Knee Brace Said It Hurts. The AI Didn’t Believe It — Until the Muscle

Agentic AI for Personalized Knee Braces: How sEMG, Facial Expressions, and LLMs Combine to Configure Rehab Devices Read More »

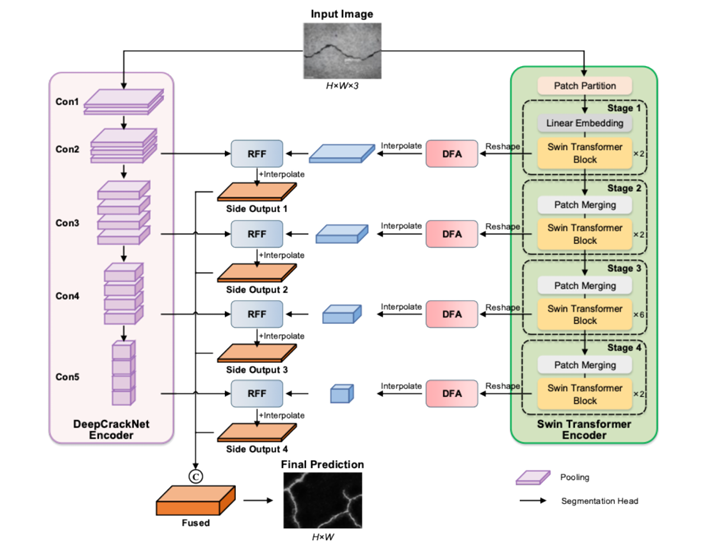
PARNet: Dual-Encoder Crack Detection with Dynamic Alignment and Residual Fusion.

PARNet: Dual-Encoder Crack Detection with Dynamic Alignment and Residual Fusion

PARNet: Dual-Encoder Crack Detection with Dynamic Alignment and Residual Fusion | AI Trend Blend AITrendBlend Machine Learning Computer Vision About Computer Vision · Advanced Engineering Informatics 74 (2026) · Shandong University · 20 min read PARNet: The Crack Detection Network That Learned to See Like a Human Inspector — and Then Outperformed Eight of Them

PARNet: Dual-Encoder Crack Detection with Dynamic Alignment and Residual Fusion Read More »

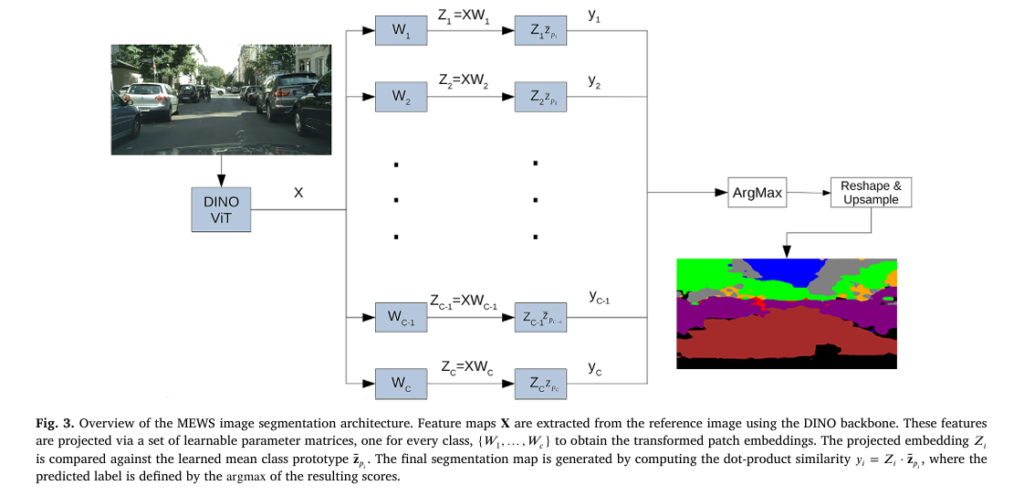
MEWS: Semantic Segmentation With Almost No Labels — A Few Pixels Per Class Is All You Need.

MEWS: Semantic Segmentation With Almost No Labels — A Few Pixels Per Class Is All You Need

MEWS: Semantic Segmentation With Almost No Labels — A Few Pixels Per Class Is All You Need | AI Trend Blend AITrendBlend Machine Learning Computer Vision Image Segmentation About Computer Vision · Neurocomputing 680 (2026) 133290 · 18 min read MEWS: The Segmentation Framework That Beats CLIP With Just a Few Pixel Clicks Per Class

MEWS: Semantic Segmentation With Almost No Labels — A Few Pixels Per Class Is All You Need Read More »

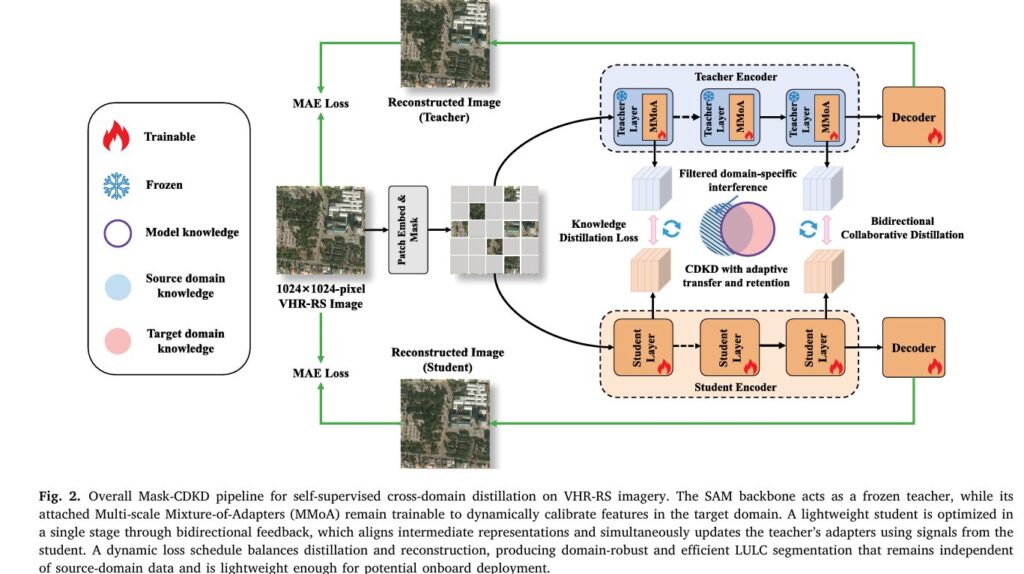
Mask-CDKD: Source-Free Knowledge Distillation from SAM for Satellite Onboard Land Cover Mapping.

Mask-CDKD: Source-Free Knowledge Distillation from SAM for Satellite Onboard Land Cover Mapping

Mask-CDKD: Source-Free Knowledge Distillation from SAM for Satellite Onboard Land Cover Mapping | AI Trend Blend Satellite AI & Remote Sensing · ISPRS J. Photogramm. Remote Sens. 236 (2026) 1–21 · Wuhan University / Emory · 28 min read Teaching a Satellite to See the World Without Labels: How Mask-CDKD Squeezes SAM Into a 30M-Parameter

Mask-CDKD: Source-Free Knowledge Distillation from SAM for Satellite Onboard Land Cover Mapping Read More »

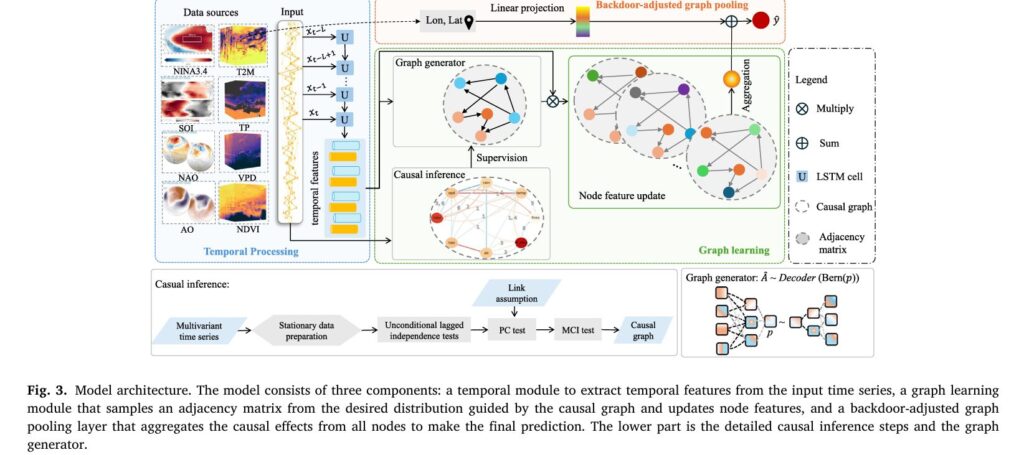
Causal Graph Neural Networks for Wildfire Forecasting Across Geographic Shifts.

Causal Graph Neural Networks for Wildfire Forecasting Across Geographic Shifts

Causal Graph Neural Networks for Wildfire Forecasting Across Geographic Shifts | AI Trend Blend Earth Observation & Climate AI · ISPRS J. Photogramm. Remote Sens. 236 (2026) 654–667 · TU Munich / NOA Athens · 27 min read Why Your Wildfire Forecast Fails in Europe When It Was Trained in the Middle East — and

Causal Graph Neural Networks for Wildfire Forecasting Across Geographic Shifts Read More »

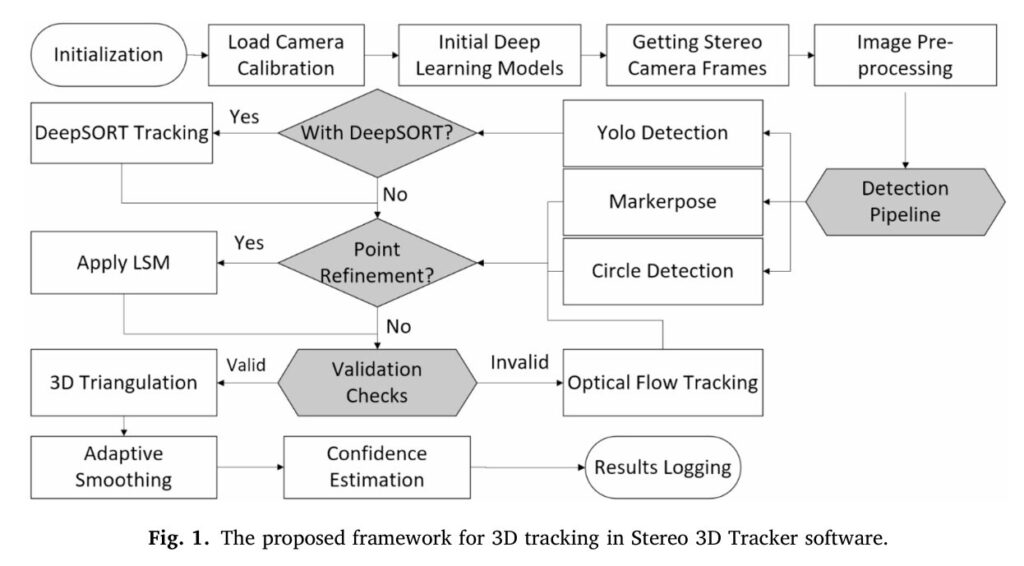
Stereo 3D Tracker: Real-Time 3D Point Tracking in Fisheye Stereo Photogrammetry.

Stereo 3D Tracker: Real-Time 3D Point Tracking in Fisheye Stereo Photogrammetry

Stereo 3D Tracker: Real-Time 3D Point Tracking in Fisheye Stereo Photogrammetry | AI Trend Blend AITrendBlend Machine Learning Computer Vision About 3D Vision & Photogrammetry · ISPRS J. Photogramm. Remote Sens. 236 (2026) 438–455 · K.N. Toosi University of Technology · 25 min read Sub-Millimeter Tracking for $1,000: How the Stereo 3D Tracker Beats Commercial

Stereo 3D Tracker: Real-Time 3D Point Tracking in Fisheye Stereo Photogrammetry Read More »

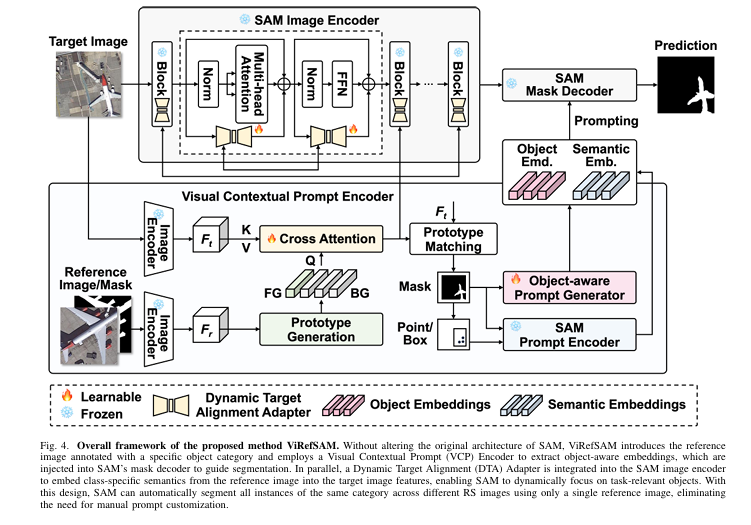
ViRefSAM: How Visual Reference Images Are Finally Making SAM Work for Remote Sensing.

ViRefSAM: How Visual Reference Images Are Finally Making SAM Work for Remote Sensing

ViRefSAM: How Visual Reference Images Are Finally Making SAM Work for Remote Sensing | AI Trend Blend Computer Vision · arXiv:2507.02294 · Remote Sensing & Foundation Models · 20 min read ViRefSAM: Teaching SAM to Segment Anything in Satellite Imagery — Without You Drawing a Single Box Researchers from the Chinese Academy of Sciences built

ViRefSAM: How Visual Reference Images Are Finally Making SAM Work for Remote Sensing Read More »

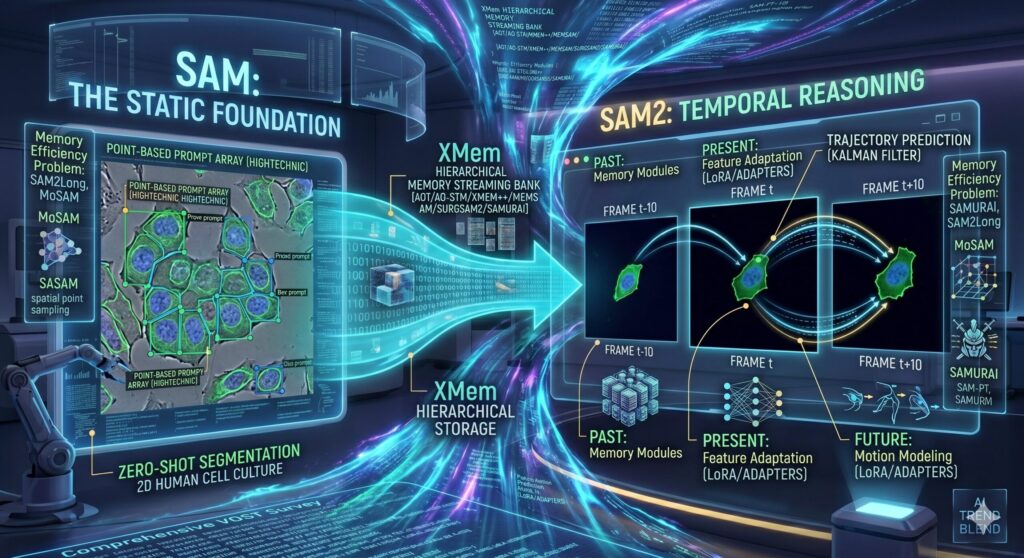
Segment Anything for Video: How SAM2 Is Reshaping Object Tracking and Segmentation.

Segment Anything for Video: How SAM2 Is Reshaping Object Tracking and Segmentation

Segment Anything for Video: How SAM2 Is Reshaping Object Tracking and Segmentation | AI Trend Blend Computer Vision · Comprehensive Survey · UT Southwestern Medical Center & UPenn · 25 min read Segment Anything for Video: Why SAM2 Is the Most Important Architecture Shift in Object Tracking Since Transformers A sweeping new survey from UT

Segment Anything for Video: How SAM2 Is Reshaping Object Tracking and Segmentation Read More »