CIFAR-100

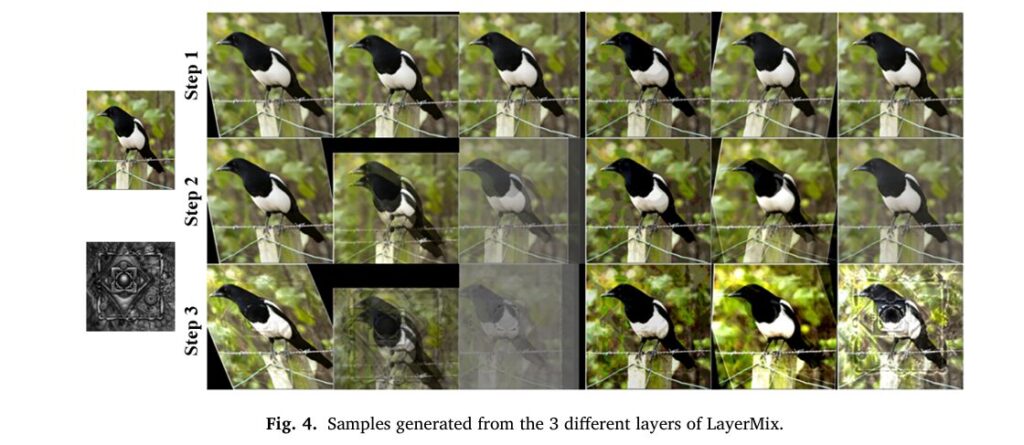
Discover how LayerMix, an innovative data augmentation technique using structured fractal mixing, enhances deep learning model robustness against corruptions, adversarial attacks, and distribution shifts. Learn about its methodology, benchmarks, and results.

LayerMix: A Fractal-Based Data Augmentation Strategy for More Robust Deep Learning Models

Introduction: The Quest for Robust AI Deep Learning (DL) has revolutionized computer vision, enabling machines to identify objects, segment images, and drive cars with astonishing accuracy. Yet, a critical Achilles’ heel remains: these models often fail dramatically when faced with data that deviates even slightly from their training set. A self-driving car trained on sunny-day […]

LayerMix: A Fractal-Based Data Augmentation Strategy for More Robust Deep Learning Models Read More »

Head-Tail Aware KL Divergence for Spiking Neural Networks

Published June 2025 Analysis by the aitrendblend editorial team Pillar: Knowledge Distillation and Model Compression Spiking Neural Networks Knowledge Distillation HTA-KL Divergence Forward KL Reverse KL Neuromorphic Computing CIFAR-100 Energy Efficiency There is a quiet frustration in the spiking neural network community. These networks, modelled on the actual signalling behaviour of biological neurons, consume a

Head-Tail Aware KL Divergence for Spiking Neural Networks Read More »

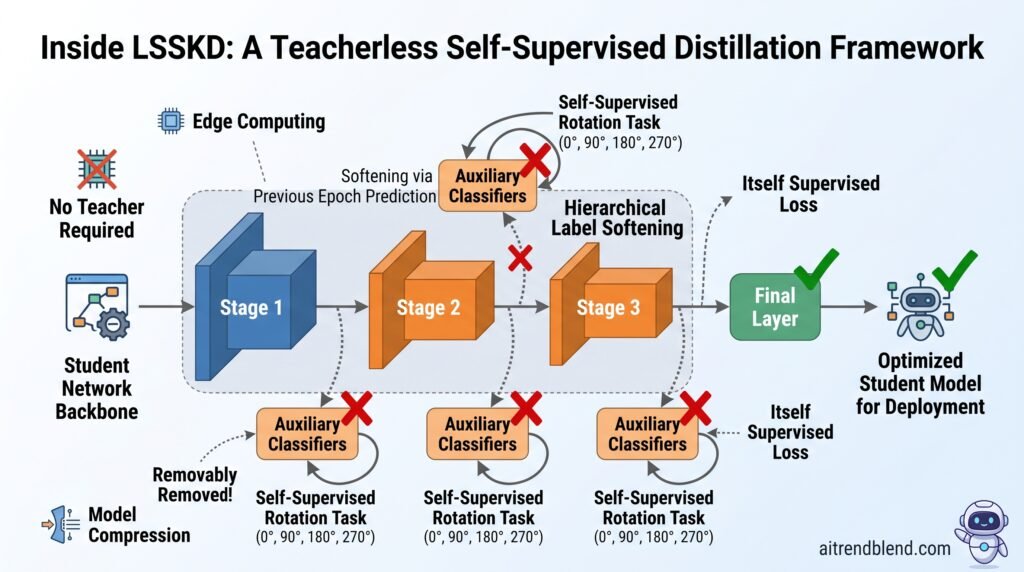
Inside LSSKD, a Self Supervised Distillation Framework That Trains Small Models Without a Teacher

Inside LSSKD, a Self Supervised Distillation Framework That Trains Small Models Without a Teacher

Analysis by the aitrendblend editorial team · Knowledge distillation and model compression · Source, Dahri et al., arXiv 2506.07055, 2025 Knowledge distillation Self supervised learning Edge computing CIFAR 100 LSSKD attaches temporary auxiliary classifiers to a student network during training, then removes every one of them before deployment. Every knowledge distillation paper eventually asks the

Inside LSSKD, a Self Supervised Distillation Framework That Trains Small Models Without a Teacher Read More »

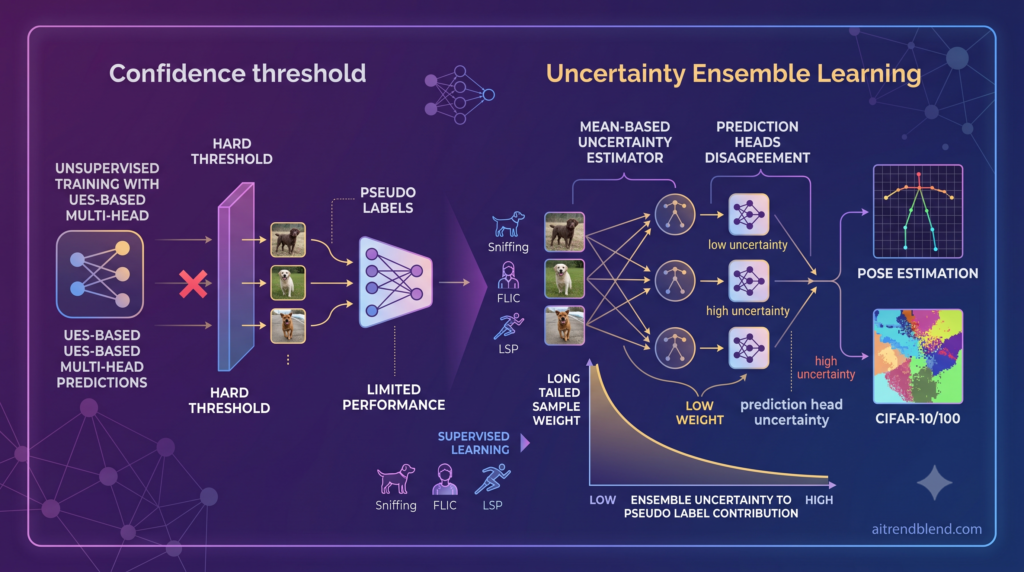
Long Tailed Weights Beat Thresholds For Pseudo Labels

Analysis by the aitrendblend editorial team · Probabilistic methods · Source paper posted March 2025 Semi Supervised Learning Uncertainty Estimation Ensemble Learning Pose Estimation Pseudo Labels Instead of relying on a hard confidence cutoff, UES introduces long tailed weights derived from ensemble uncertainty, ensuring even the least trustworthy pseudo labels still contribute valuable signal to

Long Tailed Weights Beat Thresholds For Pseudo Labels Read More »