
forward KL

Head-Tail Aware KL Divergence for Spiking Neural Networks

Published June 2025 Analysis by the aitrendblend editorial team Pillar: Knowledge Distillation and Model Compression Spiking Neural Networks Knowledge Distillation HTA-KL Divergence Forward KL Reverse KL Neuromorphic Computing CIFAR-100 Energy Efficiency There is a quiet frustration in the spiking neural network community. These networks, modelled on the actual signalling behaviour of biological neurons, consume a […]

Head-Tail Aware KL Divergence for Spiking Neural Networks Read More »
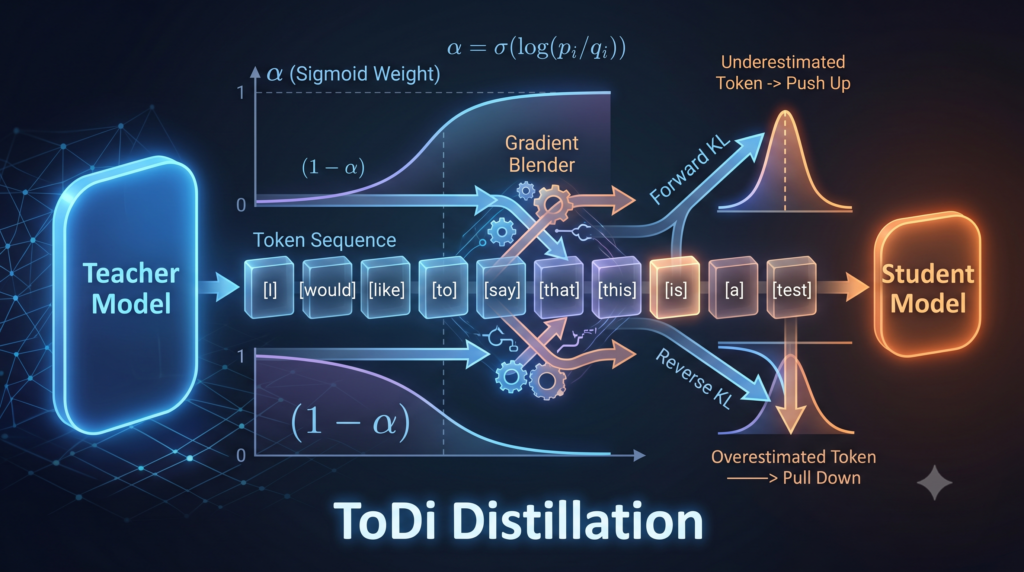
ToDi, Per Token KL Divergence Control for LLM Distillation.

ToDi: Per Token KL Divergence Control for LLM Distillation

Machine Learning › Knowledge Distillation › Paper Analysis Knowledge Distillation Forward KL Reverse KL LLM Compression Instruction Following Paper Analysis Analysis by the aitrendblend editorial team · October 2025 · 13 min read · arXiv:2505.16297 aitrendblend.com · Knowledge Distillation ToDi, Per Token Control of KL Divergence in LLM Distillation A seven billion parameter model writes

ToDi: Per Token KL Divergence Control for LLM Distillation Read More »