Knowledge Distillation Meets Integrated Gradients: A Smarter Way to Compress Neural Networks
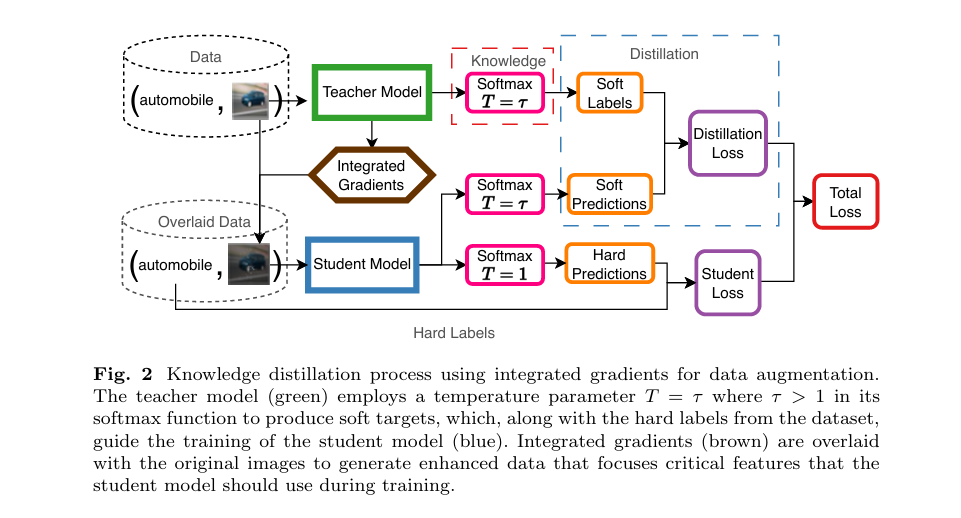
Imagine watching someone take an expert’s detailed reasoning, strip out everything except the most important cues, and hand those cues to a student who has never seen the full picture. That is roughly what a team from National Cheng Kung…