
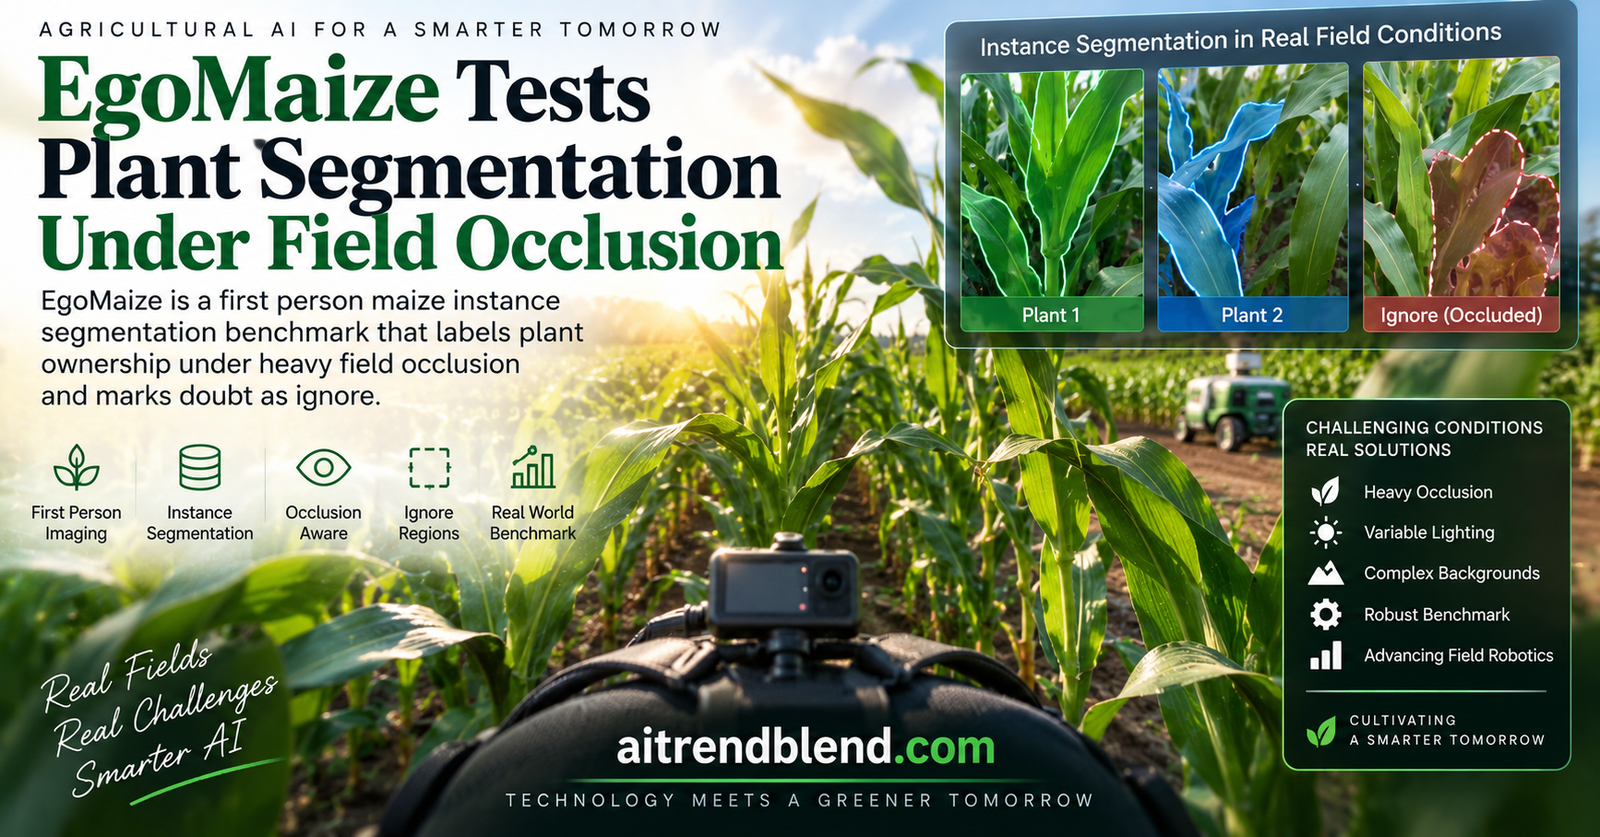
Walk a camera down a row of maize a few weeks after the seedlings come up and the view becomes a green thicket. Leaves cross over leaves, stems from one plant slip behind another, and a single plant can appear as three or four disconnected scraps of green with other plants filling the gaps between them. A human agronomist can still say which leaf belongs to which plant. Ask a modern segmentation model to do the same and it stumbles, and a team at Beijing University of Technology built a benchmark specifically to show where and why.
Key points
- Close range crop phenotyping needs to trace individual plants from inside the field, but after the seedling stage maize plants overlap so heavily that telling them apart is the hard part.
- EgoMaize is a first person instance segmentation benchmark of 301 field images with 1,276 plant instances, built around the question of which visible pixels belong to which plant.
- Its annotation rule labels only what the evidence supports, marking uncertain or unverifiable regions as ignore rather than guessing a hidden shape or dumping them into background.
- Across eight representative segmentation models, no single architecture handled the coupled challenge of fine structure, plant ownership, and occlusion, and the best mask accuracy stayed modest.
- An occlusion breakdown shows accuracy falling sharply as plants hide each other, confirming visibility as the core difficulty rather than a side effect.
Why counting green pixels is not enough
Most agricultural vision you have seen works from above. A drone or a satellite looks down at a field and measures how much of the ground is covered by crop, or separates crop from weed, or estimates a vegetation index. That overhead view is useful for large area monitoring, and it sidesteps the messiest problem in field imaging, because from high up the plants blur into a canopy and nobody needs to know where one plant ends and the next begins.
But many of the traits that agronomists actually care about live inside the canopy, not on top of it. Stalk diameter and bending strength predict whether a plant will lodge, which is to say fall over, and stalk lodging alone is estimated to cost somewhere between 5 and 20 percent of annual yield. Ear height, leaf area, organ arrangement, the whole architecture of an individual plant, these are the numbers that feed breeding and precision agriculture, and you cannot read them from a canopy. You have to look at the plant from within the row, at close range, and you have to know which leaf and which stem belong to which plant. That is an instance segmentation problem, and it is where the field has been thin.
The gap is specific. Existing agricultural datasets cover crop versus weed separation, overhead plant monitoring, seedling stage instances, organ level labels, and three dimensional plant geometry. What they do not cover is the close range first person setting where stems, leaves, tassels, and fragmented visible regions from neighboring plants all have to be assigned to the correct individual plant under severe same class overlap. EgoMaize is built to fill exactly that hole, and if you want the wider context on how models learn to separate one thing from another in a crowded image, our look at how diffusion models segment images covers neighboring ground.
The annotation problem nobody wants
Here is where it gets interesting, and where the paper does its most careful thinking. Suppose you want to label a maize plant in one of these images. You have three bad options, and the whole contribution is a fourth.
The first option is modal annotation, where you label only the pixels you can actually see. This is honest and reproducible, but it shatters a single plant into disconnected fragments, because the visible parts of one plant are scattered across the image with other plants in between. The second option is amodal annotation, where you label the full extent of the plant including the parts hidden behind other plants. This keeps each plant whole, but it forces annotators to invent boundaries for shapes they cannot see, which makes the labels subjective and, in a dense field, close to guesswork. The third option is to shove everything uncertain into the background, which quietly teaches the model that ambiguous maize is not maize.
EgoMaize takes a fourth path it calls the evidence closed annotation protocol. Visible maize pixels are labeled by which plant owns them. Visible regions where ownership or the boundary cannot be reliably determined are marked ignore, a third category that is neither foreground nor background and is excluded from both training and evaluation. Hidden regions are completed only when the gap is small and locally supported by visible structure, what the authors call an evidence closed gap, such as a short self occlusion where the plant’s own architecture makes the continuation obvious. Long hidden stretches, external occlusion by another plant, and anything unverifiable are left out. The rule, in a sentence, is to label what the evidence supports and to refuse to invent what it does not.
What is inside the dataset
The current release holds 301 first person RGB images at a native resolution of 3072 by 4096 pixels, captured from within maize rows in breeding and seed production fields at close range and oblique angles. Across those images are 1,276 labeled plant instances, an average of 4.24 plants per image, plus 9,043 organ field annotations that tag plant owned stems and tassels. Crucially, those stem and tassel cues are not treated as independent objects. They are auxiliary fields linked to their parent plant, because the point is to associate an organ with the plant it belongs to, not to detect organs in isolation.
The ignore category is not a footnote. There are 2,731 ignore region annotations spread across 282 of the 301 images, and on average about 23 percent of an image’s area, by union, falls into ignore. That is a striking number. Nearly a quarter of the typical image is judged too uncertain to label as either plant or background, which tells you how genuinely ambiguous this setting is. The plant instances themselves are small relative to the frame, averaging under one percent of the image area each, so the task is finding and separating many small, thin, tangled objects rather than a few big ones.
The train, validation, and test split was not drawn at random. Because the benchmark is about occlusion and ownership, a random split could stack all the easy low occlusion images into the test set and flatter every model. Instead the authors compute a difficulty score for each image and stratify by it, so that instance density, occlusion, and ignore coverage are represented across all three subsets.
Here \(n\) is the normalized number of plant instances in the image, \(\bar{o}\) and \(o_{\max}\) are the mean and maximum height wise occlusion ratios of the plants, and \(u\) is the ignore region union area ratio. Images are grouped by this score and split in a stratified way, which keeps hard images out of only the training set and makes the benchmark honest. The final split is 211 training images, 45 validation, and 45 test, and each image takes an annotator about 25 minutes, which is why the dataset is deliberately compact and densely labeled rather than large and loosely labeled.
How today’s models actually do
The authors ran eight representative instance segmentation models on EgoMaize, chosen to span different families, one stage, two stage, boundary refinement, occlusion aware, query based, and crop refinement. The goal was not to crown a winner but to expose where each kind of model breaks. Performance is reported with five measures, mean intersection over union for coarse region overlap, average precision at loose and strict thresholds, a count error for how well the model tallies plants, and a bounding box center distance for rough localization.
| Model | Type | mIoU | AP25 | AP50 | Count MAE |
|---|---|---|---|---|---|
| YOLOv8-seg | one stage | 0.0633 | 0.1146 | 0.0000 | 15.60 |
| YOLO11m-seg | one stage | 0.0649 | 0.1124 | 0.0000 | 14.84 |
| Mask R-CNN | two stage | 0.2575 | 0.3688 | 0.0053 | 4.27 |
| PointRend | boundary | 0.3544 | 0.6307 | 0.1291 | 8.93 |
| BCNet | occlusion | 0.2635 | 0.4818 | 0.0185 | 2.24 |
| Mask2Former R50 | query | 0.2493 | 0.6707 | 0.2556 | 1.93 |
| Mask2Former Swin-B | query | 0.5014 | 0.8024 | 0.5586 | 2.18 |
| CropFormer | crop refine | 0.4061 | 0.6586 | 0.6585 | 1.40 |
| DI-MaskDINO-R50 | query | 0.0920 | 0.0430 | 0.0000 | 23.17 |
The scores tell a scattered story, which is the point. Mask2Former Swin-B, a strong pretrained query based model, took the top spot on region overlap at 0.5014 mIoU and on loose instance matching at 0.8024 AP25. CropFormer, which refines crops at high resolution, led on strict mask accuracy at 0.6585 AP50 and on plant counting with the lowest count error at 1.40. The YOLO variants got the closest bounding box centers but posted near zero mask accuracy, meaning they can roughly point at plants but cannot trace them. Different models are good at different pieces, and no model is good at all of them at once.
The revealing gap is between loose and strict matching. For Mask2Former Swin-B, loose AP25 reaches 0.8024 but strict AP50 falls to 0.5586. The model can often recover a coarse instance but struggles to produce a mask that agrees closely with the true, ownership consistent boundary. That is exactly what you would expect given the visual facts of the dataset, where plants are thin, fragmented, repetitive, and interleaved with their neighbors.
Approximate localization and loose instance matching are much easier than high quality ownership consistent masks, and the gap widens as plants hide each other. That gap is the benchmark. Reading of the EgoMaize baseline results
Watching accuracy fall as plants hide
Overall averages can hide where a model fails, so the authors sliced the results by how occluded each plant is, using height wise occlusion bins from no occlusion up to half occluded. The trend is stark. Mask2Former Swin-B scores 0.7171 AP25 on unoccluded plants and holds that through light occlusion, then collapses to 0.0915 once plants reach the 30 to 50 percent occlusion band. CropFormer and the lighter Mask2Former R50 degrade more gracefully but still lose ground. Occlusion is not a nuisance variable here. It is the axis along which the task gets hard, and the breakdown proves that even a strong pretrained model degrades sharply as visibility drops.
This matters because it separates two possible explanations for weak scores. If a model simply was not good enough, its errors would spread evenly. Instead the errors concentrate exactly where plants overlap, which points at the structure of the problem rather than at a fixable training detail. The benchmark is doing its job, isolating occlusion as a genuine failure mode.
Does the ignore label just hide the hard parts
A skeptic would ask a sharp question. If you let annotators mark a quarter of the image as ignore and then exclude those pixels from scoring, are you not just deleting the hard cases and inflating the numbers? The authors take the question seriously and test it directly. They re evaluated the best model two ways, once removing ignore pixels as intended, and once treating those ignore pixels as background.
| Ignore policy | mIoU | AP25 | AP50 |
|---|---|---|---|
| Remove ignore pixels | 0.5014 | 0.8024 | 0.5586 |
| Treat ignore as background | 0.4087 | 0.7885 | 0.5344 |
The scores barely move. Loose and strict AP shift by only a point or two when ignore is treated as background instead of removed. Digging further, the authors found that although about 23 percent of the model’s predicted foreground area lands inside ignore regions, those predictions are not secretly correct. Of the 76 predictions with more than half their area inside ignore, 75 have a best valid region overlap below 0.25 and none reach 0.50. In other words, the ignore label is catching genuinely unverifiable maize, not shielding good masks from scrutiny. It avoids supervising ownership that cannot be confirmed rather than rewarding coarse guesses.
Proving the annotation rule is the right one
The most convincing part of the paper is a small controlled experiment that asks whether evidence closed annotation is actually better than full amodal annotation, or just easier. At a breeding base the team photographed 10 maize plants three ways each, an exposed reference view with occluders removed and leaves moved aside, a natural self occlusion view, and an artificially occluded view. Because the exposed reference shows the true plant, they could measure which annotation style, applied to the occluded views, better matches reality.
Evidence closed annotation won. It reached 0.8038 mean intersection over union against the exposed reference, while full amodal annotation reached only 0.6945, and its bounding box centers were slightly closer too. Being conservative and refusing to complete unverifiable regions matched the real plant better than confidently drawing hidden shapes. A second study backs this up from the annotators’ side. On a difficult subset labeled independently by four people, evidence closed annotation produced a mean agreement of 0.8203 intersection over union, well above the 0.5860 that full amodal labeling managed. Refusing to guess does not just match reality better, it makes different annotators agree with each other more.
Honest limitations
The authors are candid about scope. EgoMaize is compact by design, 301 images from limited field sites, devices, and acquisition conditions, so it is a focused diagnostic benchmark rather than a large pretraining corpus, and results on it should be read as characterizing failure modes rather than ranking production systems. The protocol still leans on human judgment. Annotators must decide plant ownership and whether a gap is evidence closed, which is skilled work at 25 minutes per image and not fully objective, even if the consistency study shows it is reasonably reproducible.
There is also a ceiling that two dimensional images impose. A flat photo cannot fully validate hidden plant geometry, so the evidence closed rule is a practical stand in for ground truth, not a proof of it, and the controlled validation is a small 10 plant study rather than a comprehensive one. The release focuses on plant instances and selected stem and tassel cues rather than complete phenotyping records, so it is a perception layer, not an end to end trait measurement system. And because the dataset is small and the task is hard, the absolute numbers are low across the board, which means the benchmark is most useful for comparing approaches and tracking progress rather than for declaring any model ready for the field.
Why it matters beyond maize
The transferable idea here is not about corn. It is that honest uncertainty belongs in the label schema, not just in the model. Most benchmarks force every pixel into a class and then act surprised when models overconfidently hallucinate boundaries. EgoMaize makes ignore a first class label, refuses to supervise what cannot be verified, and shows through controlled experiments that this conservatism both matches reality better and improves agreement between annotators. Any domain with heavy occlusion and ambiguous boundaries, from cluttered warehouse robotics to crowded street scenes to medical images with indistinct edges, could borrow the same discipline.
The second lesson is about evaluation design. By stratifying the split on a difficulty score and then breaking results down by occlusion level, the authors turned a single confusing average into a diagnostic curve that shows exactly where models fail. That habit, of designing the evaluation to expose failure rather than to produce a flattering headline number, is worth copying anywhere the easy cases threaten to drown out the hard ones. The same instinct shows up in field robotics work such as planning search over difficult terrain, where the interesting behavior lives in the hard regions.
Conclusion
EgoMaize is a benchmark that knows what it is testing. Rather than adding one more segmentation dataset to a crowded shelf, it isolates a specific, underserved problem, tracing individual maize plants from inside the field when those plants overlap so severely that a single plant looks like several and several plants look like one. That close range first person setting is where mobile phenotyping and field robots actually operate, and it is where existing benchmarks had left a gap.
The conceptual contribution is the evidence closed annotation protocol, and it is more principled than it first appears. Faced with the choice between labeling only visible fragments, inventing hidden shapes, or dumping doubt into background, the authors chose a fourth option that labels what the evidence supports and marks the rest as ignore. The controlled experiments show this is not a convenient shortcut. Evidence closed labels match an exposed reference plant better than amodal labels do, and different annotators agree far more when they are allowed to refuse to guess.
The benchmark results support a sober reading of where the field stands. Current instance segmentation models can localize maize plants approximately and sometimes recover coarse instances, but ownership consistent mask prediction under elongated structures, repeated organs, same class overlap, and ignore regions remains out of reach. No architecture handled all the pieces, the best strict mask accuracy stayed near 0.66, and the occlusion breakdown shows even a strong pretrained model collapsing as plants hide each other.
The honest limitations keep the claims in proportion. The dataset is small and single domain, the protocol still needs human judgment, two dimensional images cannot certify hidden geometry, and the controlled validation is modest in size. None of these undercut the contribution, which is a carefully constructed diagnostic that makes a hard, practical agricultural perception problem measurable and reproducible.
For anyone building perception for agriculture, or for any setting where objects of the same kind pile up and hide each other, EgoMaize offers two things worth taking. A dataset that will punish overconfident guessing and reward genuine ownership reasoning, and a design philosophy that treats uncertainty as something to label rather than something to paper over. The plants in these images are stubbornly hard to tell apart, which is precisely why a benchmark that measures the difficulty honestly is more useful than one that hides it.
Reference implementation in Python
Because EgoMaize is a benchmark rather than a new model, the code that matters most is the evaluation, and specifically how the ignore label is handled. The reference below computes an ignore aware intersection over union that excludes ignore pixels from both the intersection and the union, computes the image difficulty score from the paper, and applies an ignore mask to a segmentation training loss, with a smoke test on dummy data. It is a faithful sketch of the dataset’s scoring conventions for study.
# egomaize_eval.py
# Study reference for the EgoMaize evaluation conventions, ignore aware IoU,
# the image difficulty score, and an ignore masked loss. Not the authors'
# full toolkit. Runs a smoke test on dummy data at the end.

import numpy as np
import torch
import torch.nn.functional as F


def ignore_aware_iou(pred, gt, ignore, eps=1e-6):
    """IoU between two binary masks with ignore pixels removed from both.
    pred, gt, ignore are boolean arrays of the same shape."""
    valid = ~ignore
    p = pred & valid
    g = gt & valid
    inter = np.logical_and(p, g).sum()
    union = np.logical_or(p, g).sum()
    return (inter + eps) / (union + eps)


def match_instances(preds, gts, ignore, thr=0.5):
    """Greedy one to one matching of predicted to ground truth instances
    by ignore aware IoU. Returns matched IoU values and counts."""
    used = set()
    tp, ious = 0, []
    for p in preds:
        best, best_iou = -1, 0.0
        for j, g in enumerate(gts):
            if j in used:
                continue
            iou = ignore_aware_iou(p, g, ignore)
            if iou > best_iou:
                best, best_iou = j, iou
        if best_iou >= thr and best >= 0:
            used.add(best); tp += 1; ious.append(best_iou)
    fp = len(preds) - tp
    fn = len(gts) - tp
    return tp, fp, fn, ious


def average_precision(preds, gts, ignore, thr=0.5):
    """A simple precision style score at one IoU threshold, AP25 uses thr 0.25."""
    tp, fp, fn, _ = match_instances(preds, gts, ignore, thr)
    return tp / max(tp + fp + fn, 1)


def difficulty_score(n_instances, occ_ratios, ignore_ratio,
                     n_min=1, n_max=12):
    """EgoMaize image difficulty score.
    s = (1 + 0.5 n) * 2 (mean_occ + max_occ) + ignore_ratio."""
    n = (len(occ_ratios) - n_min) / max(n_max - n_min, 1)  # normalized count
    n = float(np.clip(n, 0.0, 1.0))
    o_mean = float(np.mean(occ_ratios)) if len(occ_ratios) else 0.0
    o_max = float(np.max(occ_ratios)) if len(occ_ratios) else 0.0
    return (1 + 0.5 * n) * 2 * (o_mean + o_max) + ignore_ratio


def ignore_masked_loss(logits, target, ignore):
    """Cross entropy that skips ignore pixels, matching the evaluation policy.
    logits B,C,H,W ; target and ignore B,H,W."""
    loss = F.cross_entropy(logits, target, reduction="none")  # B,H,W
    valid = (~ignore).float()
    return (loss * valid).sum() / valid.sum().clamp_min(1.0)


def smoke_test():
    rng = np.random.default_rng(0)
    H = W = 64
    ignore = rng.random((H, W)) < 0.2          # about 20 percent ignore, like the data
    gt1 = np.zeros((H, W), bool); gt1[10:30, 10:25] = True
    gt2 = np.zeros((H, W), bool); gt2[35:55, 30:50] = True
    pred1 = np.zeros((H, W), bool); pred1[12:31, 11:26] = True
    pred2 = np.zeros((H, W), bool); pred2[40:58, 33:52] = True
    print(f"IoU plant 1 {ignore_aware_iou(pred1, gt1, ignore):.3f}")
    ap = average_precision([pred1, pred2], [gt1, gt2], ignore, thr=0.5)
    print(f"AP50 style score {ap:.3f}")
    s = difficulty_score(2, [0.1, 0.4], ignore.mean())
    print(f"difficulty score {s:.3f}")
    logits = torch.randn(1, 2, H, W)
    target = torch.tensor(gt1 | gt2, dtype=torch.long)[None]
    ig = torch.tensor(ignore)[None]
    print(f"ignore masked loss {ignore_masked_loss(logits, target, ig).item():.3f}")


if __name__ == "__main__":
    smoke_test()
Running the smoke test computes an ignore aware overlap for one plant, a precision style instance score across two plants, the image difficulty score used to stratify the split, and an ignore masked training loss. The ignore handling is the part to watch, since excluding those pixels from the intersection, the union, and the loss is what keeps the benchmark from rewarding or punishing predictions in regions the annotators judged unverifiable.
Frequently asked questions
What is EgoMaize?
It is a first person maize instance segmentation benchmark of 301 close range field images with 1,276 plant instances, built to test whether models can assign overlapping stems, leaves, and tassels to the correct individual plant under severe field occlusion.
Why is segmenting maize plants so hard after the seedling stage?
Post seedling maize plants are elongated, repetitive, and heavily interleaved, so a single plant can appear as several disconnected visible fragments while nearby visible regions belong to different plants. Assigning each region to the right plant under that overlap is the central difficulty.
What is the evidence closed annotation protocol?
It labels visible maize pixels by plant ownership, marks visible regions with unreliable ownership or boundaries as ignore, and completes hidden regions only when a short gap is locally supported by visible structure. It refuses to invent unverifiable hidden shapes.
Do the ignore regions just hide the hard cases?
No. When the best model was re evaluated with ignore pixels treated as background instead of removed, the scores changed only slightly, and predictions falling inside ignore regions were mostly wrong anyway, so the label removes unverifiable noise rather than shielding good masks.
How well do current models perform on it?
No single model handled fine structure, plant ownership, and occlusion together. The strongest overlap score was about 0.50 mean intersection over union and the best strict mask accuracy about 0.66, and accuracy fell sharply as plants became more occluded.
What are the main limitations of the benchmark?
It is compact at 301 images from limited sites and devices, the annotation protocol still requires human judgment at about 25 minutes per image, two dimensional images cannot fully verify hidden geometry, and the release covers plant instances and selected organ cues rather than complete phenotyping records.
Read the full paper and access the dataset and annotation tool.
Read the paper on arXiv Dataset and code on GitHub