
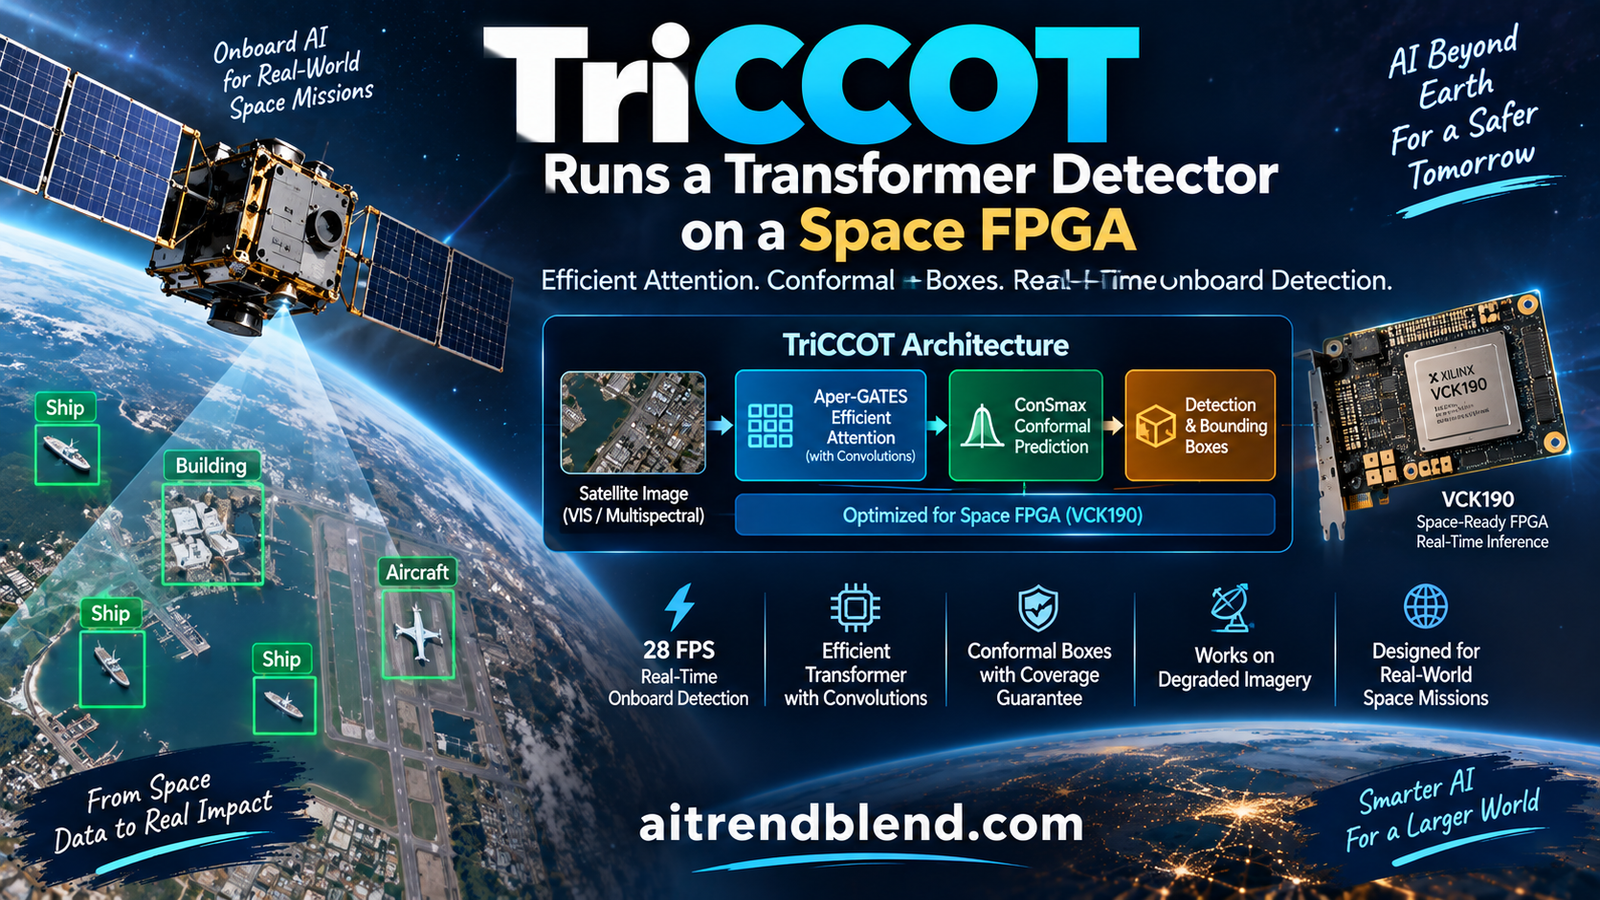
A satellite takes a picture, and then it waits. The raw image travels down to a ground station, gets cleaned up, and only then does anyone run a detector over it to find the ships or planes or windmills inside. That round trip burns time and bandwidth, and a growing number of missions would rather skip it and do the detection in orbit. The trouble is that the best detectors now lean on transformers, and a transformer is close to the worst possible thing to run on the kind of hardware a satellite carries. A team at the French space agency CNES set out to change that.
Key points
- Doing object detection onboard a satellite avoids sending raw imagery to the ground first, but the space grade accelerators available cannot run standard transformer attention.
- TriCCOT chains three stages, a convolutional region proposal network, a conformal predictor that enlarges the boxes with a coverage guarantee, and a hardware friendly attention classifier called Aper-GATES.
- Aper-GATES rewrites attention as convolutions plus a single global channel descriptor, dropping the quadratic cost and the softmax that make transformers unfriendly to these chips.
- The whole model runs on a Xilinx Versal FPGA at 28.2 frames per second without changing the accelerator, and it holds up better than convolutional rivals on raw noisy imagery.
- The biggest surprise in the ablation is that removing the conformal box enlargement hurt accuracy far more than removing the fancy attention did.
Why onboard detection is a hardware problem
Earth observation has always worked in two acts. The satellite senses, and the ground processes. Radiometric and geometric corrections, the steps that turn a raw noisy acquisition into a clean usable image, happen after the data comes down. That pipeline is effective but slow, and as onboard computing has grown, missions have started pushing decisions up to the satellite itself, for tasks like cloud masking, anomaly detection, and object detection, to cut the amount of data that has to be transmitted at all.
Here is where it gets interesting. Moving the intelligence up to the satellite also means moving it onto the satellite’s hardware, and that hardware is nothing like a data center. Space grade accelerators are chosen for radiation tolerance and power efficiency, not for flexibility, and the ones gaining traction, such as the FPGA at the center of this work, run a fixed processing unit built for convolutional networks. Convolutional detectors fit that mold and are efficient, but studies keep finding they lose accuracy on raw uncorrected imagery, because their limited receptive fields struggle to capture the broad patterns that survive when an image is noisy and blurred.
Transformers are better at that global reasoning, which is exactly why they would help on degraded onboard data. But their core operation, self attention, does three things the fixed accelerator hates. It computes an affinity between every pair of tokens, which grows quadratically with the number of tokens. It relies on the softmax function, which is expensive to implement in hardware. And it reshapes data in ways the convolutional processing unit was never designed to handle. So the very models that would help most are the ones the hardware rejects. TriCCOT is an attempt to keep the transformer’s strengths while satisfying the hardware’s constraints.
Three stages, each solving one problem
TriCCOT stands for Tri part Convolutional Conformal Transformer, and the name is the architecture. It runs three stages in sequence, each aimed at a distinct difficulty.
A convolutional region proposal network
The first stage is familiar. A convolutional region proposal network, built on a CSPDarknet backbone with a feature pyramid to handle objects of different sizes, scans the full image and proposes candidate bounding boxes. This part is deliberately conventional. The authors note that image degradation has little effect on box localization, so the proposal stage needs few changes to work on raw data, and it stays convolutional so it maps cleanly onto the accelerator.
A conformal predictor that grows the boxes
The second stage is the clever one, and it turns out to matter most. Proposal boxes are imperfect. They can be shifted or too tight, cropping off part of an object or leaving out the context around it, and a classifier that only sees a tight, slightly wrong crop has little to work with. Rather than expanding every box by a fixed fudge factor, TriCCOT uses conformal prediction, a principled method that provides a distribution free coverage guarantee. It learns a separate correction for each side of the box from a calibration set and enlarges the boxes so that, under the conformal assumptions, a chosen fraction of ground truth objects are entirely contained.
Each coordinate gets its own calibrated correction, which can differ in size and sign, so the method compensates not just for boxes that are too small but for systematic directional biases in where the proposal network places them. With the coverage level set so that 85 percent of objects are fully contained, the enlarged crops carry the surrounding context the classifier needs, without the guesswork of a hand tuned scaling rule.
Aper-GATES, attention the hardware will accept
The third stage classifies each enlarged crop, and it is where the transformer lives. Called Aper-GATES, for Aperture Gated Attention Transformer for Embedded Systems, it keeps the spirit of attention, aggregating global context across the whole crop, while replacing every operation the accelerator cannot handle. The name borrows a camera metaphor. An aperture controls how much light flows through, and here a learned gate controls how much global context flows into each feature.
The models that reason best about noisy imagery are the ones the satellite hardware rejects. The fix is not a better chip but a rewrite of attention that the existing chip already understands. Reading of the paper’s core motivation
How Aper-GATES rewrites attention
Standard attention flattens an image into a list of tokens and builds a matrix comparing each token to every other one. Aper-GATES refuses to flatten. It keeps the two dimensional structure and computes its query, key, and value projections with grouped one by one convolutions, so the spatial grid stays intact and the operation stays native to the accelerator.
Then comes the move that kills the quadratic cost. Instead of a full token by token affinity matrix, Aper-GATES squeezes the interaction between keys and values into a single global channel descriptor, by taking their elementwise product and pooling it across the whole spatial extent. This borrows from Squeeze and Excitation and Global Context networks, which pool a feature map into a compact descriptor, but here it pools the key value product rather than the feature itself.
Finally the queries are gated by that global descriptor, the aperture opening or closing on the global context according to what each query needs, using a hardware friendly activation in place of anything exotic.
The result is that Aper-GATES captures a global summary of feature correlations rather than localizing specific token pairs, and its cost grows linearly with the size of the feature map rather than quadratically with the token count. The trade is deliberate. Aper-GATES gives up the fine grained pairwise expressivity of full attention in exchange for architectural simplicity, numerical stability, and a shape the accelerator can execute.
Killing the softmax
One obstacle remains. Attention normally normalizes with softmax, which is hardware intensive. Aper-GATES swaps it for a learnable gating function inspired by a method called ConSmax, and then simplifies even that into a form the processing unit runs natively, a depthwise affine transform followed by a piecewise linear activation.
The weights are learned channel wise through a depthwise convolution, so the normalization adapts during training while staying cheap at inference. There is also a neat trick for handling different crop sizes. Because objects come in many sizes, Aper-GATES keeps a bank of patch embedders, each tuned to one admissible input resolution among sixteen, thirty two, sixty four, and one hundred twenty eight pixels, and every branch projects its crop onto the same fixed eight by eight feature grid. A small selector on the processor picks the right branch, and a metadata vector tells the network the original object scale so nothing is lost. Keeping the feature grid fixed is what lets a single model serve all sizes without confusing the accelerator, an efficiency mindset shared with other work on making networks smaller without losing accuracy.
What the numbers show
The team tested TriCCOT on DIOR, a standard optical remote sensing benchmark with twenty classes, on a degraded version of DIOR with simulated blur and signal dependent noise, and on VDVRaw, real raw satellite imagery from the VENuS mission with genuine sensor artifacts like striping, band misalignment, and stray light. They compared against a two stage detector, two lightweight one stage detectors, and two transformer detectors, splitting the field into models that can run on the FPGA and models that cannot.
| Model | Params | GFLOPs | DIOR clean mAP@50 | DIOR raw mAP@50 | VDVRaw mAP@50 |
|---|---|---|---|---|---|
| RT-DETR (not FPGA) | 20.0M | 60.0 | 82.1 | 80.3 | 29.7 |
| DETR (not FPGA) | 41.5M | 38.4 | 49.9 | 49.1 | 8.6 |
| Faster R-CNN | 40.0M | 89.0 | 74.8 | 69.2 | 18.2 |
| YOLOX-S | 8.9M | 26.8 | 78.7 | 72.6 | 20.0 |
| NanoDet-Plus | 2.4M | 1.8 | 75.3 | 70.0 | 21.2 |
| TriCCOT | 3.5M | 8.2 | 76.5 | 74.8 | 25.3 |
The pattern is honest and worth reading carefully. On clean DIOR, TriCCOT does not win outright. Among FPGA compatible models, YOLOX-S leads on mAP@50 at 78.7 percent, and TriCCOT trails at 76.5, within about two points while using far fewer parameters at 3.5 million and only 8.2 GFLOPs. But move to degraded data and the ranking flips. On raw DIOR, TriCCOT takes the top spot among FPGA compatible models at 74.8, and on real raw VDVRaw imagery it leads clearly at 25.3. The transformer based models, TriCCOT included, show the smallest drop when moving from clean to degraded imagery, which supports the whole premise that global attention buys robustness to noise.
The ablation delivers the study’s most instructive result. Removing Aper-GATES and reverting to a plain vision transformer cost only 0.82 points of mAP@50, a modest amount, because Aper-GATES was never meant to raise accuracy, only to make attention deployable. Removing the conformal predictor, on the other hand, cost 7.39 points. The context that the enlarged boxes hand to the classifier turned out to matter far more than the exact form of the attention.
Running it on real space hardware
The proof is in the deployment. TriCCOT runs on a Xilinx Versal VCK190 FPGA, a chip with radiation tolerant credentials that appeal to the space community, using its Deep Learning Processor Unit exactly as shipped. This is the part the authors are proudest of. Rather than redesigning the accelerator to fit the attention operations, as other FPGA transformer efforts do, they mapped all of TriCCOT’s convolutional and attention operations onto the standard unit, with nothing offloaded to the processor except a couple of tiny bookkeeping steps.
| Model | Size | Latency | FPS | Power |
|---|---|---|---|---|
| TriCCOT | 10.0 MB | 35.5 ms | 28.2 | 25 W |
| YOLOX-S | 9.2 MB | 74.1 ms | 13.5 | 25 W |
| DETR | 162.7 MB | 13160 ms | 0.08 | 22.5 W |
At 28.2 frames per second on 640 by 640 patches, TriCCOT is the fastest model tested on the board, fast enough for real time onboard processing, and it does so with a transformer inside. The breakdown shows where the time goes. The region proposal network is the bottleneck at 29.1 milliseconds, while the Aper-GATES classifier runs in just 3.9 milliseconds on the accelerator and the conformal and selector steps add only 2.5 milliseconds on the processor. DETR, by contrast, cannot run on the accelerator at all and crawls at 0.08 frames per second on the processor, which is the whole reason a purpose built efficient attention was necessary.
There is a training bonus too. Because the transformer only ever sees object crops rather than full images, most of its input is task relevant, so it needs far less data and time to converge. All three stages together trained in four to five hours on a single RTX 4090, against roughly thirty hours for the transformer baselines.
Honest limitations
The authors are clear about what they gave up. The three stages are trained sequentially, one after another, so errors introduced by the region proposal network propagate into the conformal stage and then into the classifier, and the pipeline is never optimized end to end. The conformal enlargement softens the damage from imperfect proposals, but it does not remove the underlying coupling. Joint or cooperative training, and hard example mining that lets the proposal and classification stages adapt to each other, are named as future work rather than solved problems.
On raw clean imagery TriCCOT also does not lead. RT-DETR posts the best overall numbers by a wide margin on clean DIOR, and TriCCOT only wins once the comparison is restricted to models the FPGA can actually run and the imagery is degraded. That is a fair and useful niche, but it is a niche, and the paper does not oversell it. The model size is bounded by its CSPDarknet backbone, which the authors want to replace with something lighter like MobileNet to shrink the footprint and speed things up further. And the current design uses axis aligned boxes, which struggle with objects whose rotation varies, such as tennis courts, where the same object can present very different box shapes.
One more caveat on the conformal guarantee. Its coverage promise holds under the conformal assumptions and on the calibration distribution. Real onboard imagery from a new sensor or a new scene may drift from that calibration, so the 85 percent containment is a property of the test conditions, not an ironclad promise in orbit. The paper treats conformal prediction as a structural tool for enlarging crops, which is the safe way to use it, rather than as a certified reliability claim about deployment.
Why the approach travels
The most portable idea here is that you can often reshape an expensive operation to fit hardware you already have, instead of waiting for hardware that fits the operation. Aper-GATES does not invent a new accelerator. It rewrites attention as convolutions plus a pooled global descriptor and a piecewise linear gate, all things a convolutional processing unit already runs, and in doing so it lets a satellite chip designed years ago run a transformer today. Any edge deployment stuck with fixed function hardware could apply the same instinct.
The second idea is quieter but just as useful. Conformal prediction is usually pitched as a way to attach uncertainty estimates to predictions. Here it is repurposed as a structural component, a principled way to enlarge crops with a coverage guarantee instead of a hand picked scaling factor, and the ablation shows that structural use delivered most of the accuracy. Borrowing a statistical tool for a mechanical job, and letting it replace a magic number with a calibrated one, is a pattern worth remembering. The habit of pairing detection with a coverage or uncertainty signal shows up across remote sensing, including work on evidential reasoning for road network extraction.
Conclusion
TriCCOT is a systems paper in the best sense. It starts from a hard constraint, that a satellite’s fixed accelerator cannot run standard attention, and it works backward to a design that respects the constraint without abandoning what makes transformers useful. The three stages divide the labor cleanly. Convolution finds the objects, conformal prediction frames them with enough context, and a reshaped attention names them, and each stage was chosen for how well it fits both the task and the hardware.
The conceptual shift is to treat deployability as a first class design goal rather than an afterthought. Most efficient attention research optimizes for parameter count or theoretical complexity. This work optimizes for what a specific space grade processing unit can execute without modification, which is a stricter and more practical target. The payoff is a transformer detector that runs in orbit at real time speed on hardware that already exists, which is not something the field could claim easily before.
The evidence supports a careful claim. TriCCOT does not beat the best detectors on clean imagery, and it says so. What it does is lead among FPGA compatible models on degraded and real raw imagery, at 3.5 million parameters and 8.2 GFLOPs, while running at 28.2 frames per second on the target board. For onboard Earth observation, where the imagery is raw and the hardware is fixed, that combination is the one that counts.
The ablation is the part practitioners should carry away. The expensive, clever attention reformulation bought deployability but almost no accuracy, while the humble conformal box enlargement bought seven points. It is a reminder that in a multi stage system the biggest wins often hide in the plumbing between components rather than in the marquee module, and that giving a classifier the right context can matter more than giving it a better classifier.
The honest limitations point the way forward. Sequential training leaves accuracy on the table that end to end optimization could recover. A lighter backbone would shrink the model and speed it up. Rotated boxes would help with objects whose orientation varies. None of these undercut the central achievement, which is that a transformer now fits on a satellite. For anyone building perception for edge devices with fixed accelerators, from spacecraft to drones to embedded sensors, the lesson is to design for the hardware you have, and to check whether the context around a detection matters as much as the detector itself.
Reference implementation in PyTorch
The code below is a compact, runnable sketch of the Aper-GATES ideas, the convolutional query key and value projections, the pooled global second order context, the aperture gating, the hardware friendly normalization, a multi resolution patch embedder that maps any admissible size to a fixed grid, and a conformal box adjustment function, with a smoke test on dummy data. It captures the mechanics faithfully for study and is not the authors’ FPGA deployment code.
# aper_gates.py
# Study reference for the Aper-GATES ideas from TriCCOT. Not the authors' FPGA
# pipeline. Runs a smoke test on dummy tensors at the end.

import torch
import torch.nn as nn
import torch.nn.functional as F


class ConSmaxDPU(nn.Module):
    """Softmax replacement, a depthwise affine plus a piecewise linear gate."""
    def __init__(self, channels):
        super().__init__()
        self.affine = nn.Conv2d(channels, channels, 1, groups=channels)

    def forward(self, x):
        return F.hardsigmoid(self.affine(x))


class AperGATES(nn.Module):
    """Gated convolutional attention with a global second order descriptor.
    Linear in the feature map size, no token by token affinity matrix."""
    def __init__(self, channels, heads=4):
        super().__init__()
        assert channels % heads == 0
        self.heads = heads
        # grouped 1x1 convolutions keep the 2D grid, one group per head
        self.q = nn.Conv2d(channels, channels, 1, groups=heads)
        self.k = nn.Conv2d(channels, channels, 1, groups=heads)
        self.v = nn.Conv2d(channels, channels, 1, groups=heads)
        self.gate = ConSmaxDPU(channels)
        self.proj = nn.Conv2d(channels, channels, 1)
        self.out = nn.Conv2d(channels, channels, 1)

    def forward(self, x):
        q, k, v = self.q(x), self.k(x), self.v(x)
        # global second order context, pool the key value product over space
        kv = k * v                                # Hadamard product
        g = kv.mean(dim=(2, 3), keepdim=True)   # B, C, 1, 1 channel descriptor
        # aperture modulation, gate the queries by the global descriptor
        u = q * self.gate(self.proj(g))
        return x + self.out(u)                     # residual


class MultiResPatchEmbed(nn.Module):
    """A bank of embedders, one per admissible size, all mapping to G x G."""
    def __init__(self, in_ch=3, dim=128, grid=8, sizes=(16, 32, 64, 128)):
        super().__init__()
        self.grid = grid
        self.sizes = sizes
        self.branches = nn.ModuleDict()
        for s in sizes:
            stride = s // grid                    # land on a fixed grid x grid map
            self.branches[str(s)] = nn.Conv2d(in_ch, dim, kernel_size=stride, stride=stride)
        # metadata fusion, tell the model the original object scale
        self.meta = nn.Sequential(nn.Linear(4, dim), nn.ReLU(True), nn.Linear(dim, dim))

    def _nearest_size(self, hw):
        return min(self.sizes, key=lambda s: abs(s - hw))

    def forward(self, x):
        h, w = x.shape[-2:]
        s = self._nearest_size(max(h, w))       # CPU side boolean selection
        x = F.interpolate(x, size=(s, s), mode="bilinear", align_corners=False)
        z = self.branches[str(s)](x)             # B, dim, grid, grid
        m = torch.tensor([[h / 128, w / 128, s / 128, s / 128]], device=x.device)
        z = z + self.meta(m).view(1, -1, 1, 1)  # additive residual fusion
        return z


def conformal_adjust(boxes, corrections):
    """Enlarge boxes by per side calibrated corrections.
    boxes and corrections are B x 4 as xmin, ymin, xmax, ymax."""
    signs = torch.tensor([-1.0, -1.0, 1.0, 1.0], device=boxes.device)
    return boxes + signs * corrections   # grow outward on every side


class Classifier(nn.Module):
    """Aper-GATES classifier head on a fixed grid embedding."""
    def __init__(self, n_classes=20, dim=128):
        super().__init__()
        self.embed = MultiResPatchEmbed(dim=dim)
        self.attn1 = AperGATES(dim)
        self.attn2 = AperGATES(dim)
        self.head = nn.Conv2d(dim, n_classes, 1)

    def forward(self, crop):
        z = self.embed(crop)
        z = self.attn2(self.attn1(z))
        z = z.mean(dim=(2, 3), keepdim=True)
        return self.head(z).flatten(1)


def smoke_test():
    torch.manual_seed(0)
    clf = Classifier(n_classes=20)
    for hw in [24, 50, 120]:                # different crop sizes, one fixed grid
        crop = torch.randn(2, 3, hw, hw)
        logits = clf(crop)
        print(f"crop {hw} -> logits {tuple(logits.shape)}")
    boxes = torch.tensor([[10., 10., 50., 50.]])
    corr = torch.tensor([[3., 2., 4., 2.]])
    print(f"conformal box {conformal_adjust(boxes, corr).tolist()}")
    n = sum(p.numel() for p in clf.parameters())
    print(f"classifier parameter count {n/1e6:.3f} M")


if __name__ == "__main__":
    smoke_test()
Running the smoke test feeds crops of three different sizes through the classifier and shows they all produce the same shaped output, because the multi resolution embedder maps each one onto the same fixed grid. It then applies a conformal adjustment that grows a box outward on every side and prints the classifier parameter count. The fixed grid behavior is the one to watch, since it is what lets a single model on the accelerator handle objects of any size.
Frequently asked questions
What is onboard object detection and why does it matter?
It means running the detector on the satellite itself rather than sending raw imagery to the ground for processing first. Doing so cuts downlink bandwidth and latency, so the satellite can act on what it sees without waiting for a round trip to a ground station.
Why can standard transformers not run on satellite hardware?
Standard attention computes an affinity between every pair of tokens, which grows quadratically with the token count, and it relies on the softmax function. Both are costly on the fixed convolutional accelerators that space grade FPGAs use, so a plain transformer does not map onto that hardware.
How does Aper-GATES make attention hardware friendly?
It computes its query, key, and value projections with convolutions to keep the two dimensional structure, replaces the pairwise affinity matrix with a single pooled global channel descriptor, gates the queries with that descriptor, and swaps softmax for a piecewise linear activation the accelerator runs natively.
What did conformal prediction contribute?
It enlarges the proposal boxes with a distribution free coverage guarantee so the classifier sees enough context, replacing a hand tuned scaling rule. In the ablation, removing it cost 7.39 points of accuracy, more than any other component.
How fast is TriCCOT on the target FPGA?
It runs at 28.2 frames per second on 640 by 640 patches on a Xilinx Versal VCK190, using the standard processing unit without modification, which makes it the fastest model the authors tested on that board.
What are the main limitations?
The three stages are trained sequentially rather than end to end, so errors propagate between them. The model does not lead on clean imagery, only on degraded and raw data among FPGA compatible models, and it uses axis aligned boxes that struggle with rotated objects.
Read the full paper for the complete formulation and every benchmark.
Read the paper on arXiv Code repository if released