
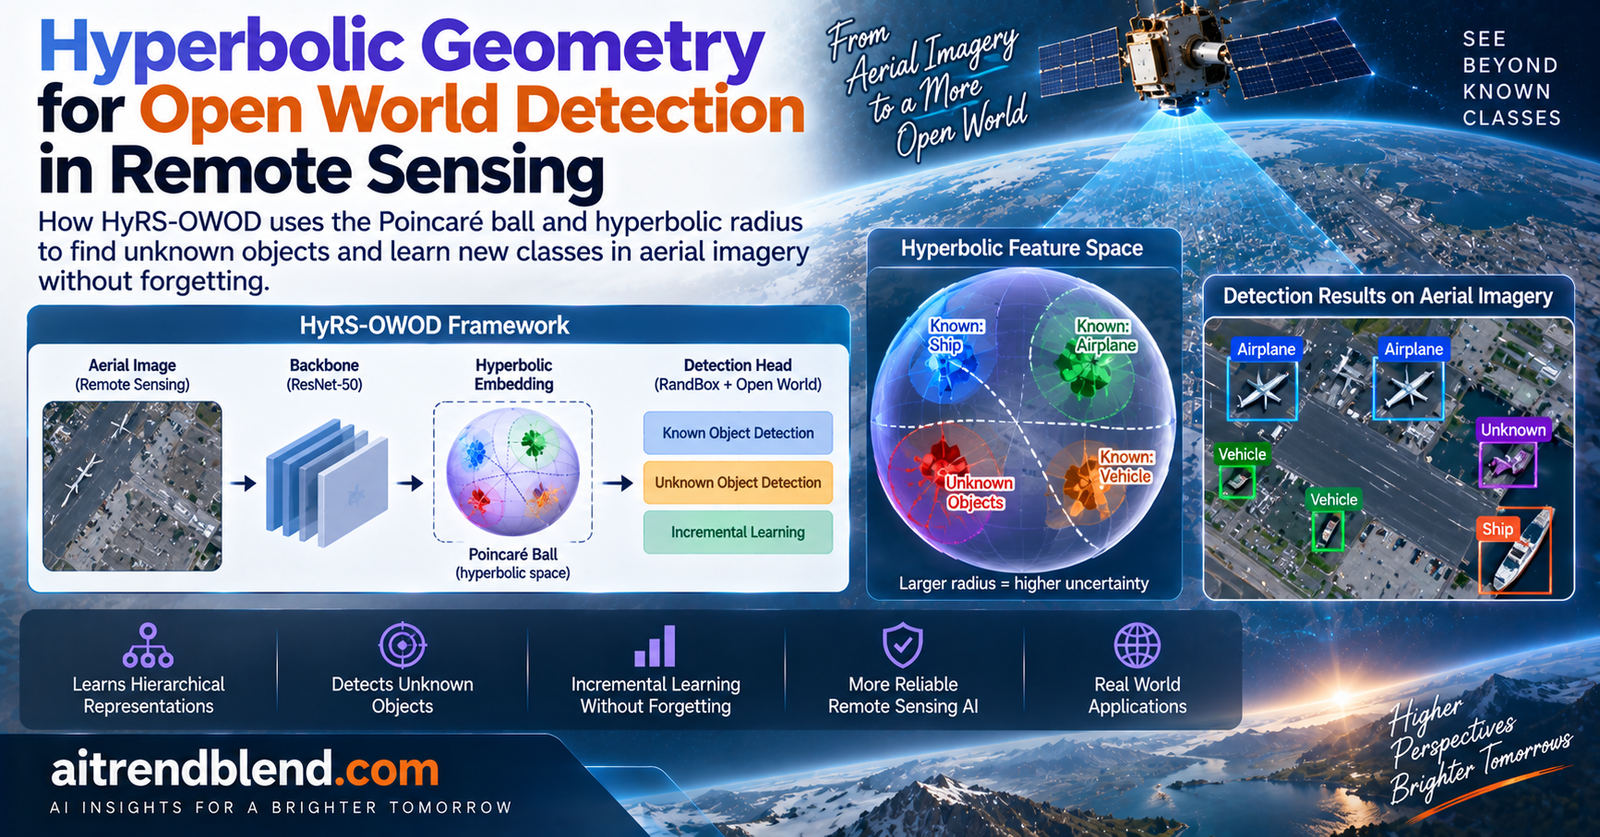
Train an object detector on ships, planes, and storage tanks, then fly it over a harbor it has never seen. A crane swings into view. The detector has two bad options and one good one. It can force the crane into a category it already knows and be wrong. It can dismiss it as background and miss it. Or it can do the thing that turns out to be surprisingly hard, admit that it is looking at something new. A team spanning Wuhan and Ohio State argues that the reason this is hard has less to do with the detector and more to do with the shape of the space its features live in.
Key points
- Open world detection asks a model to recognize known objects, flag unknown ones, and later learn the unknowns as new classes without erasing the old, which is exactly where remote sensing detectors tend to fail.
- Aerial categories form a hierarchy, a destroyer is a kind of warship and a warship is a kind of ship, and flat Euclidean feature space distorts that tree, so the authors move the embeddings into curved hyperbolic space instead.
- The distance from a proposal to the center of the hyperbolic ball becomes a free uncertainty signal, and objects with strong objectness but small radius are flagged as unknown.
- Across three aerial benchmarks the method lifts unknown recall by roughly 19 to 24 points over the best prior methods on one dataset, while keeping false alarms near zero.
- A hyperbolic metric learning stage lifts accuracy on newly added classes from 76.9 to 91.2 percent while barely touching the old classes, easing the usual forgetting problem.
What open world detection actually demands
Most detectors are trained under a quiet assumption that the world contains only the categories in the training set. The field calls this the closed set assumption, and it is convenient and wrong. A detector deployed for urban planning, environmental monitoring, or disaster assessment will meet objects nobody labeled, and those objects often carry the information that matters most. Open world object detection, shortened to OWOD, drops the closed set assumption and asks for three things at once. Recognize the known classes. Identify anything unfamiliar as unknown rather than mislabeling it. Then, once someone annotates a batch of those unknowns, fold them in as new classes without retraining from scratch and without forgetting what came before.
That last clause is where careers go to die. Neural networks are notorious for catastrophic forgetting, the tendency to overwrite old knowledge when learning something new. In remote sensing the problem is worse than in ordinary photos, and the paper is precise about why. Aerial object categories are visually similar and finely divided. A new class is often a subcategory or a close cousin of an existing one, so its feature distribution overlaps heavily with classes the model already learned, which makes the interference during adaptation especially destructive.
There is a matching problem on the unknown side. Because unknown objects are unlabeled during training, they get confused with background, and in aerial imagery they also get confused with similar known objects. Both failures suppress unknown recall, the measure of how many genuinely new objects the detector manages to flag. So the two headline difficulties, low unknown recall and catastrophic forgetting, both trace back to the same root, remote sensing categories relate to each other in ways a flat feature space cannot represent well.
Why flat space is the wrong container
Here is the idea the whole paper rests on. Euclidean space, the ordinary flat geometry that nearly every vision model uses for its embeddings, is bad at holding trees. If you try to place a hierarchy of categories into flat space so that related things sit near each other and the levels stay ordered, you run out of room. The number of items at each level of a tree grows exponentially with depth, but the volume of a flat ball grows only polynomially with its radius, so the tree gets crushed and distorted.
Hyperbolic space does not have this problem. It is a curved geometry with constant negative curvature, and its volume grows exponentially as you move outward, which is exactly the growth rate a tree needs. Embed a hierarchy into hyperbolic space and the parent categories sit near the center while children fan out toward the boundary with room to spare, all at low distortion. The authors work in a specific model of this space called the Poincare ball, an open ball where the geometry stretches without limit as you approach the edge. This same geometry has powered gains in language modeling and knowledge graphs, and it maps naturally onto the way aerial categories nest, an idea we have seen echoed in work on manifold aware fusion for remote sensing classification.
The paper does not just assert that aerial data is hierarchical. It measures it. Using a quantity called delta hyperbolicity, which scores how tree like a metric space is, the authors extract embeddings from three remote sensing datasets and compute their relative hyperbolicity, where lower values mean stronger hierarchy. With a ResNet-50 backbone the values land around 0.25 to 0.29, low enough to justify treating the data as hierarchical, and from those numbers they even estimate a suitable curvature for the ball rather than guessing one.
The three moving parts of HyRS-OWOD
The framework, named HyRS-OWOD, is built on RandBox, a detector that generates random candidate boxes rather than learned region proposals, with a ResNet-50 and a feature pyramid network for its backbone. On top of that base the authors add three components, each aimed at one of the failure modes above.
Decoupled objectness, so foreground is not tied to a name
Objectness is the score that says a box contains some object, any object, regardless of what it is. In principle it should be class agnostic. In practice, when you train the objectness branch using only labeled known classes, it quietly learns to fire for things that look like known classes and to stay quiet otherwise. That is poison for unknown recall, because a genuinely novel object gets a low objectness score and is thrown away as background. The Decoupled Objectness Learning module, or DOL, fights this with a decoupling loss that penalizes the statistical correlation between the objectness score and the class predictions, measured through a squared correlation coefficient. The effect is to pull objectness away from category identity so it captures the plain fact of foreground.
The hyperbolic radius as a built in uncertainty meter
This is the elegant part. Once a proposal is embedded in the Poincare ball, its distance from the center carries meaning on its own. Confident, well understood objects drift toward the boundary, where the space is rich. Abstract, ambiguous, or novel things stay near the origin. So the radius of a proposal, its hyperbolic distance to the center, is a ready made uncertainty cue that needs no extra supervision. Hyperbolic Uncertainty Learning, or HUL, uses it directly. A proposal that scores high on objectness but sits close to the origin is behaving like a real object that the model cannot confidently name, which is precisely the profile of an unknown. HUL adds a smooth loss that encourages candidate unknowns into that high uncertainty region near the center, sharpening the line between known and unknown.
Hyperbolic metric learning against forgetting
For the incremental stage, Hyperbolic Metric Learning, or HML, keeps a class balanced buffer of proposal embeddings from earlier classes and does metric learning in the curved space. It pulls proposals of the same class together and pushes apart hard negatives, the confusing lookalikes from different classes, weighting the hardest pairs most through their hyperbolic distance. Because remote sensing classes overlap so much, focusing the learning on those confusing pairs is what buys back the separability that ordinary fine tuning destroys, a concern shared by other work on continual learning and catastrophic forgetting.
The geometry, in a few equations
The Poincare ball of curvature parameter c is the set of points whose scaled norm stays under one, and its metric is the flat metric multiplied by a conformal factor that blows up at the boundary.
To place a Euclidean feature vector into the ball, the model uses the exponential map from the origin, and to read out an uncertainty it uses the hyperbolic radius, the distance from the embedded point back to the center.
That radius is normalized within each image and turned into an uncertainty score, larger when the point is nearer the origin. The HUL loss then uses a soft margin around a radius threshold to push candidate unknowns into the uncertain zone.
The metric learning objective pulls same class pairs together and pushes weighted hard negatives apart, all with distances measured in the curved metric rather than the flat one.
Does the geometry pay off
The experiments span three aerial benchmarks, NWPU VHR-10 with ten classes, DIOR with twenty across more than 23,000 images, and the large scale DOTA-v1.5. The method is measured on mean average precision for known classes and on unknown recall for the novel objects, plus two error measures, wilderness impact and absolute open set error, that both count how badly unknowns pollute the known predictions.
| Setting | Method | U-Recall | Known mAP |
|---|---|---|---|
| DIOR 16+4 | Best prior | 42.93 | 57.69 |
| DIOR 16+4 | HyRS-OWOD | 52.93 | 71.26 |
| DIOR 10+10 | Best prior | 46.33 | 62.51 |
| DIOR 10+10 | HyRS-OWOD | 53.72 | 73.49 |
| DIOR 4+16 | Best prior | 41.61 | 68.79 |
| DIOR 4+16 | HyRS-OWOD | 40.11 | 79.48 |
| NWPU VHR-10 8+2 | Best prior | 55.90 | 86.03 |
| NWPU VHR-10 8+2 | HyRS-OWOD | 58.94 | 89.06 |
The pattern is strong on the metric that matters most for open world work. On NWPU VHR-10 across the three sequential stages, the method beats the best competing approach on unknown recall by roughly 19, 20, and 24 points, and it does so while keeping wilderness impact near zero and misclassifying only a couple of unknowns as known, dropping to zero such errors by the third stage. Higher unknown recall usually comes at the price of more false alarms. Here it does not, which is the sign that the uncertainty signal is genuinely discriminative rather than just trigger happy.
The ablation makes the contribution of each piece legible. On the NWPU VHR-10 eight plus two split, the base model reaches 45.2 percent unknown recall. Adding decoupled objectness alone lifts it to 48.1. Adding hyperbolic uncertainty learning alone lifts it further to 51.2 while driving both error measures to zero. Together the two reach 58.9, a gain of 13.7 points over the baseline, at the cost of a modest dip in known accuracy from 91.9 to 89.1 percent. That tradeoff is real and the authors report it plainly rather than hiding it.
Proposals with high objectness but small hyperbolic radius are more likely to be unknown. The center of a curved space, it turns out, is where a model puts the things it cannot yet name. Reading of the hyperbolic uncertainty idea
The forgetting problem, eased
The incremental results are where the metric learning earns its place. When new classes are introduced, the danger is that accuracy on them stays low while accuracy on old classes collapses. Adding hyperbolic metric learning raises accuracy on the newly introduced classes from 76.9 to 91.2 percent, a jump of 14.3 points, while accuracy on previously known classes barely moves, edging from 91.5 to 91.6. The overall figure climbs from 88.5 to 91.5. A t-SNE visualization backs the numbers, showing that without the metric learning the class clusters overlap and smear, while with it they tighten and separate.
Honest limitations
The gains in unknown recall come with a known accuracy tax. The ablation shows known mean average precision slipping from 91.9 to 89.1 percent once decoupled objectness and hyperbolic uncertainty are switched on, so a deployment that cares more about never missing a known object than about catching novel ones would feel that tradeoff. It is small, but it is not free, and the balance point will depend on the application.
The method also inherits the moving parts that make hyperbolic learning finicky. It needs a curvature value for the ball, which the authors estimate from the data rather than tune, and it relies on numerically delicate operations near the boundary of the Poincare ball where the conformal factor grows without limit. The incremental stage keeps a replay buffer, fifty exemplars per class in the reported setup, so memory grows with the number of classes seen, a common but real cost of exemplar based continual learning. The evaluation, while spanning three datasets and several splits, is confined to those aerial benchmarks and to the RandBox detection framework, so how the geometry behaves under other detectors or in non aerial open world settings is not established here.
One more honest note on framing. The paper is a preprint in the usual arXiv sense and reports strong numbers against prior methods, but the largest margins appear on the smaller NWPU VHR-10 benchmark, and on the DIOR four plus sixteen split the unknown recall actually trails the best prior method even as known accuracy leads by a wide margin. The story is not uniformly a clean sweep, and reading the full table rather than the headline is worth the effort.
Why the idea travels
Strip away the remote sensing specifics and the transferable lesson is about representation geometry. Whenever the categories in a problem relate to each other hierarchically, and most real taxonomies do, a flat embedding space is quietly working against the model. Moving to a curved space where hierarchy fits naturally can help on two fronts at once, discovering what is novel and integrating it without forgetting, because both depend on how cleanly related concepts can be arranged. That is a general claim, and it is why hyperbolic embeddings keep resurfacing across language, graphs, and now aerial vision.
The uncertainty trick is the part most worth borrowing. Getting a calibrated sense of what a model does not know usually means bolting on an extra head, an ensemble, or a separate estimator. Here the uncertainty falls out of the geometry for free, because the radius already encodes it. Any system that embeds its inputs in a Poincare ball gets an uncertainty measure as a byproduct, which is a rare thing in machine learning, a useful signal that costs nothing extra to compute.
Conclusion
This paper reframes a stubborn problem by questioning an assumption almost nobody states out loud, that feature embeddings belong in flat space. For open world detection in aerial imagery, where categories nest into fine hierarchies and new classes arrive as close relatives of old ones, flatness is a handicap. The authors measure the hierarchy directly, confirm it is there, and then move the representation into a curved geometry built to hold exactly that kind of structure.
The three components fit the diagnosis. Decoupled objectness stops the foreground signal from secretly encoding known category identity, so novel objects are not discarded as background. Hyperbolic uncertainty learning reads the distance to the center of the ball as a confidence measure and flags high objectness, low radius proposals as unknown. Hyperbolic metric learning keeps classes separable in the curved space during incremental updates, which is what holds catastrophic forgetting at bay when visually similar new classes arrive.
The evidence supports a careful claim. Unknown recall improves substantially on the three benchmarks, by double digit margins over prior methods on NWPU VHR-10, while wilderness impact and open set error stay near zero, which means the extra recall is discriminative rather than reckless. The incremental results show new class accuracy climbing sharply while old class accuracy holds steady. These are the two things open world detection is supposed to deliver, and the method delivers both together rather than trading one for the other.
The honest caveats keep the picture balanced. Known accuracy dips slightly when the unknown discovery machinery is active. The curvature must be chosen and the boundary operations handled with care. The replay buffer grows with the class count. And the results are strongest on the smaller dataset, with at least one split where unknown recall does not lead. None of these undercut the central contribution, but each marks a place where the approach could be pushed further.
For anyone building perception systems that must operate in an open world, whether over farmland from a satellite or a warehouse floor from a robot, the takeaway is worth carrying. Before adding another detection head or another loss term, it may be worth asking whether the space your features live in matches the structure of the problem. When the categories form a tree, a curved room may serve them better than a flat one, and the geometry itself may hand you the uncertainty estimate you were about to engineer.
Reference implementation in PyTorch
The code below captures the core mechanics, Poincare ball operations, an exponential map projection head, the hyperbolic radius used as an uncertainty score, the decoupling loss, the hyperbolic uncertainty loss, and a hyperbolic metric learning loss, with a runnable smoke test on dummy data. It is a faithful structural sketch for study, not the authors’ full detection pipeline, and it uses a numerically guarded curvature to stay stable near the ball boundary.
# hyrs_owod.py
# Study reference for the HyRS-OWOD ideas, Poincare ball ops plus the three
# losses. Not the authors' RandBox detector. Runs a smoke test at the end.

import torch
import torch.nn as nn
import torch.nn.functional as F

EPS = 1e-5


def project(x, c):
    """Clip points to stay strictly inside the Poincare ball of curvature c."""
    max_norm = (1.0 - 1e-3) / (c ** 0.5)
    norm = x.norm(dim=-1, keepdim=True).clamp_min(EPS)
    factor = torch.clamp(max_norm / norm, max=1.0)
    return x * factor


def expmap0(v, c):
    """Exponential map at the origin, lifts a Euclidean vector into the ball."""
    sqrt_c = c ** 0.5
    norm = v.norm(dim=-1, keepdim=True).clamp_min(EPS)
    coef = torch.tanh(sqrt_c * norm) / (sqrt_c * norm)
    return project(coef * v, c)


def hyp_radius(x, c):
    """Hyperbolic distance from x to the origin, the uncertainty cue."""
    sqrt_c = c ** 0.5
    norm = x.norm(dim=-1).clamp(EPS, (1.0 - 1e-3) / sqrt_c)
    return (2.0 / sqrt_c) * torch.atanh(sqrt_c * norm)


def hyp_dist(x, y, c):
    """Poincare distance between two batches of points."""
    sqrt_c = c ** 0.5
    diff = (x - y).pow(2).sum(-1)
    xn = x.pow(2).sum(-1); yn = y.pow(2).sum(-1)
    denom = (1 - c * xn).clamp_min(EPS) * (1 - c * yn).clamp_min(EPS)
    arg = (1 + 2 * c * diff / denom).clamp_min(1 + EPS)
    return (1.0 / sqrt_c) * torch.acosh(arg)


class HyperbolicHead(nn.Module):
    """Project Euclidean proposal features into the Poincare ball."""
    def __init__(self, in_dim, dim=64, c=1.0):
        super().__init__()
        self.c = c
        self.proj = nn.Linear(in_dim, dim)

    def forward(self, f):
        return expmap0(self.proj(f), self.c)


def decoupling_loss(class_probs, objectness):
    """Squared correlation between class scores and objectness, per class."""
    o = objectness - objectness.mean()
    total = 0.0
    for c in range(class_probs.shape[1]):
        p = class_probs[:, c] - class_probs[:, c].mean()
        cov = (p * o).mean()
        denom = (p.var() * o.var()).clamp_min(EPS)
        total = total + cov.pow(2) / denom
    return total / class_probs.shape[1]


def hul_loss(z, cand_mask, c, tau=0.5, beta=10.0):
    """Push candidate unknowns toward the origin, the high uncertainty zone."""
    rho = hyp_radius(z, c)
    rho_norm = rho / rho.max().clamp_min(EPS)  # normalize within the image
    cand = rho_norm[cand_mask]
    if cand.numel() == 0:
        return z.new_tensor(0.0)
    return (1.0 / beta) * torch.log1p(torch.exp(beta * (cand - tau))).mean()


def hml_loss(z, labels, c, tau_m=0.2, tau_h=0.2):
    """Hyperbolic metric loss with distance weighted hard negatives."""
    n = z.shape[0]
    zi = z.unsqueeze(1).expand(n, n, -1)
    zj = z.unsqueeze(0).expand(n, n, -1)
    d = hyp_dist(zi.reshape(-1, z.shape[-1]), zj.reshape(-1, z.shape[-1]), c).view(n, n)
    same = labels.unsqueeze(0) == labels.unsqueeze(1)
    eye = torch.eye(n, dtype=torch.bool, device=z.device)
    pos = same & ~eye
    neg = ~same
    total, count = z.new_tensor(0.0), 0
    for i in range(n):
        if pos[i].sum() == 0 or neg[i].sum() == 0:
            continue
        a_pos = torch.exp(-d[i][pos[i]] / tau_m).sum()
        w = F.softmax(-d[i][neg[i]] / tau_h, dim=0)  # emphasize hard negatives
        a_neg = (w * torch.exp(-d[i][neg[i]] / tau_m)).sum()
        total = total - torch.log(a_pos / (a_pos + a_neg + EPS) + EPS)
        count += 1
    return total / max(count, 1)


def smoke_test():
    torch.manual_seed(0)
    c = 1.0
    head = HyperbolicHead(in_dim=128, dim=32, c=c)
    feats = torch.randn(16, 128)
    z = head(feats)
    print(f"all inside ball: {bool((z.norm(dim=-1) < 1.0/(c**0.5)).all())}")
    rho = hyp_radius(z, c)
    print(f"radius range {rho.min():.3f} to {rho.max():.3f}")
    obj = torch.rand(16)
    probs = torch.softmax(torch.randn(16, 5), dim=1)
    print(f"decoupling loss {decoupling_loss(probs, obj).item():.4f}")
    cand = obj > 0.5  # high objectness proposals treated as unknown candidates
    print(f"HUL loss {hul_loss(z, cand, c).item():.4f}")
    labels = torch.randint(0, 4, (16,))
    print(f"HML loss {hml_loss(z, labels, c).item():.4f}")


if __name__ == "__main__":
    smoke_test()
Running the smoke test confirms that every projected point lands strictly inside the ball, prints the range of hyperbolic radii that serve as the uncertainty scores, and evaluates the three losses on dummy proposals. The radius check is the one to watch, since it shows the uncertainty signal is well defined before any of the losses are applied.
Frequently asked questions
What is open world object detection?
It is a setting where a detector must recognize its known classes, flag objects it has never seen as unknown rather than mislabeling them, and later learn those unknowns as new classes without retraining from scratch or forgetting the old classes.
Why use hyperbolic geometry instead of ordinary flat space?
Aerial object categories form a hierarchy, and hierarchies do not fit into flat Euclidean space without heavy distortion because their size grows exponentially with depth. Hyperbolic space grows exponentially outward, so it holds tree like category structure with low distortion.
How does the model decide something is unknown?
It reads the distance from a proposal to the center of the Poincare ball. Confident known objects sit near the boundary, while ambiguous or novel ones sit near the center, so a proposal with high objectness but a small radius is flagged as an unknown object.
How much does the method improve unknown recall?
On the NWPU VHR-10 benchmark it raises unknown recall over the best prior methods by roughly 19 to 24 points across the three sequential stages, while keeping wilderness impact and open set error near zero.
Does it still forget old classes when learning new ones?
Much less. The hyperbolic metric learning stage raised accuracy on newly added classes from 76.9 to 91.2 percent while accuracy on previously known classes stayed near 91.5, so new learning came with almost no loss of old knowledge.
What are the main limitations?
Known class accuracy dips slightly when the unknown discovery components are active, the curvature must be chosen and boundary operations handled carefully, the replay buffer grows with the class count, and the largest margins appear on the smaller dataset.
Read the full paper for the complete formulation and every benchmark table.
Read the paper on arXiv