- Encrypted traffic
- Distribution shift
- Multimodal fusion
- Network monitoring
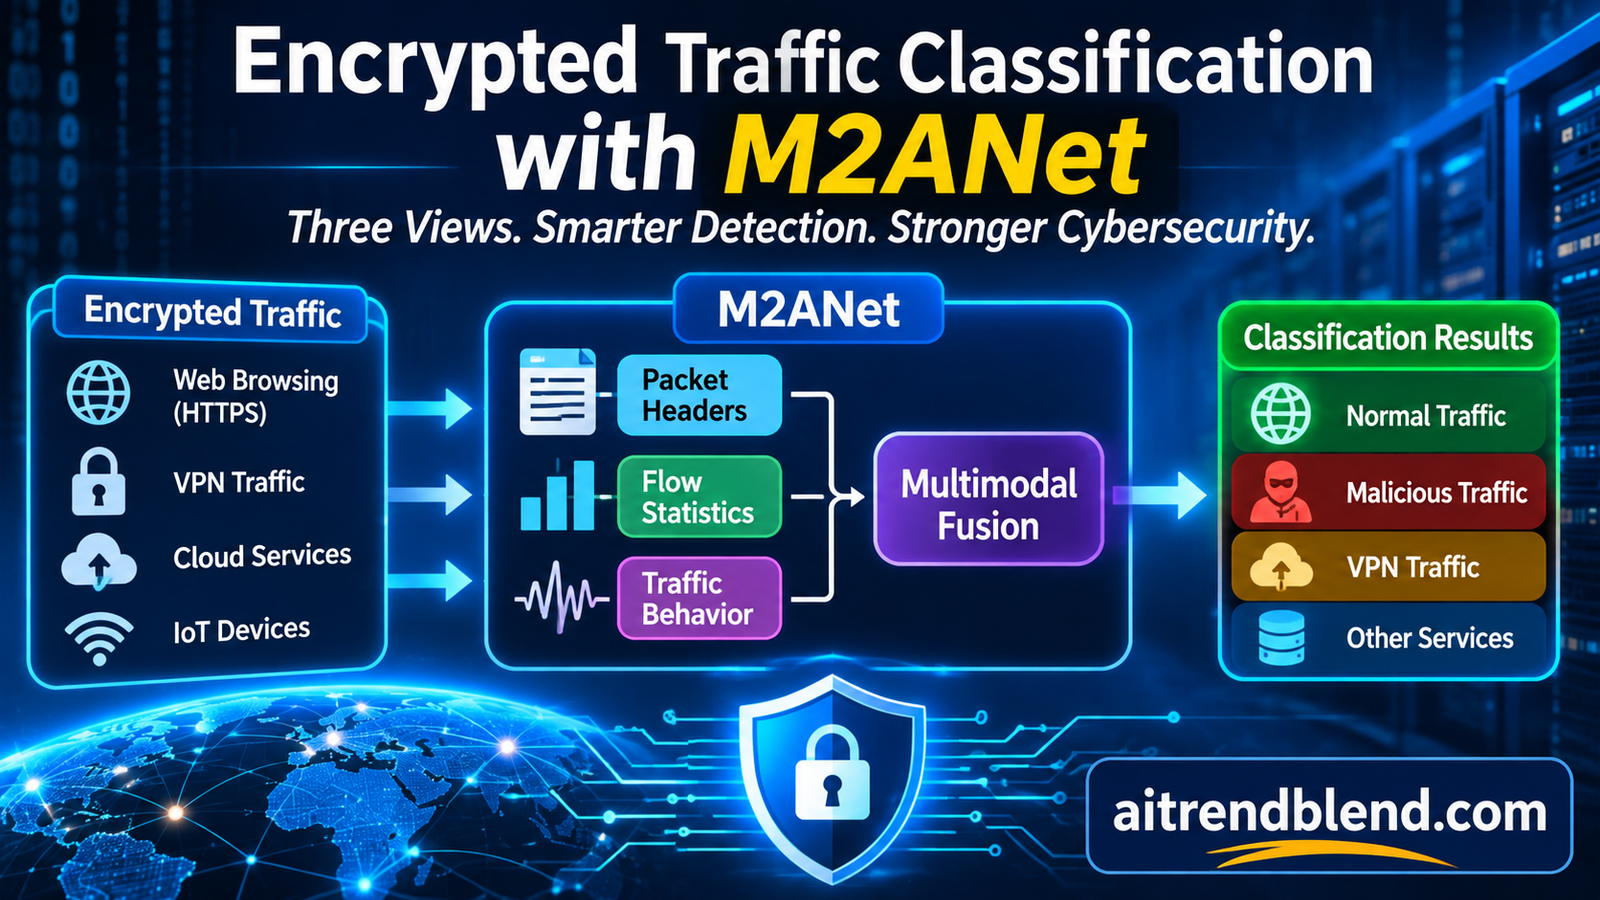
Picture a network operations team looking at the first morning of traffic after a widely used app rolls out an update. Connections still arrive and most still look ordinary on the dashboard. Then a classifier starts confidently sorting familiar traffic into unfamiliar categories. The monitoring system can be working exactly as designed while the examples it learned from are growing stale. A team led by Mei Huang asks how much of that deterioration can be avoided when a model learns to compare several views of the same encrypted connection before it learns the names of the traffic classes.
Encryption leaves behavior visible
Encrypted application data hides message contents. A monitor can still observe properties of a connection, including how many packets pass, which direction they travel and how they cluster in time. A flow classifier uses observations like these to estimate which of its known categories produced the connection. The categories depend on the dataset. They might describe an application, a device traffic family or a category of VPN traffic. The same F1 score can therefore mean something quite different across two benchmarks.
The distinction between ciphertext and traffic behavior is important because a byte model can look more informative than it really is. If it consumes a fixed window that includes the end of a short payload or the beginning of an exposed handshake, the window can carry length or environment cues. The study by Wickramasinghe and colleagues cited by Huang’s team used controlled feature occlusion to examine this question. In those experiments, retaining the original ciphertext byte values yielded little additional discrimination over representations that preserved length. The authors also found situations in which exposed hostname information could act as a shortcut. The lesson for a model builder is to account for what remains in an input after preprocessing. Read the controlled study.
That concern guided the design of M2ANet by researchers at Beijing University of Posts and Telecommunications and Zhongguancun Laboratory. Their byte view uses header information and masks examples of direct identifiers, including IP addresses, ports and time to live values. Packet lengths and burst statistics are represented separately. The resulting design gives reviewers a clearer way to ask which type of evidence supports a prediction. It also leaves open the question of which retained fields are stable across deployments. Read Huang and colleagues’ paper in Information Fusion.
Earlier work offers a useful reference point. Deep Packet learned directly from raw packet bytes, while the study behind the public VPN dataset examined timing properties for encrypted and VPN traffic characterization. M2ANet treats information at different levels as evidence to be coordinated. It asks whether a representation built around packet structure and one built around behavior can identify corresponding flows in a batch of examples. Deep Packet and the VPN traffic study.
Three views at different scales
A packet header and a burst statistic describe the same connection at different resolutions. One records details close to an individual packet. The other summarizes several packets and may smooth over changes that look large at the byte level. The paper uses separate encoders so each representation can preserve useful information at its own scale.
| View | Study input | Patterns represented |
|---|---|---|
| Header bytes | 64 positions per packet for the first 10 packets, with selected fields masked | Byte context within packets and relationships between packets |
| Packet sequence | Up to 100 signed transport payload lengths | Size, order and direction changes |
| Burst statistics | Up to 50 bursts with features such as packet count and duration | Grouped behavior and spacing between bursts |
In the byte branch, a Transformer first learns to predict hidden byte tokens within single packets. The packet summary then becomes an input token for another Transformer, which can learn relationships across packets. Position embeddings tell the model where a packet occurred. Segment embeddings indicate which packets belong to the same burst. The sequence branch uses a similar approach for signed lengths. The statistic branch projects the input features into vectors, adds a position within the flow and models relationships across bursts.
One example illustrates why the scales matter. Two connections can have similar total sizes even when one sends most of its data in a single burst and the other alternates between requests and responses. A burst view can summarize the distinction, while signed lengths can preserve details of the alternation. Conversely, two similar sequences can begin with different header patterns. Learning at each scale gives fusion a chance to exploit patterns that a single summary would hide.
There is a practical consequence of the fixed input windows. A short connection has fewer observations available, and truncation removes the ends of long connections. An evaluation broken down by flow length would show whether the aggregate score masks a weak point at either extreme. For systems that classify traffic early, measuring the first point at which predictions become stable would also help distinguish the value of the model from the value of waiting for more observations.
Why alignment comes before fusion
Combining embeddings assumes a downstream model can learn which parts of each vector refer to the same underlying event. That becomes harder when one encoder describes header structure and another describes timing or length. The goal of alignment in M2ANet is to make the relationships between examples more compatible. Two representations can still keep different information as long as they agree sufficiently on the relative similarity of candidate flows.
A student learns from a teacher whose parameters follow a moving average of the student’s parameters. The teacher scores how well a header representation matches candidates from the combined sequence and statistic view. The same comparison runs in reverse. Recent teacher features in queues enlarge the candidate pool beyond the current batch. The slowly updated teacher supplies a similarity distribution across candidates and the student learns to match it.
Teacher update and bidirectional soft target loss
$$\theta_m \leftarrow m\theta_m+(1-m)\theta$$ $$\mathcal L_{\mathrm{MC}}=-\frac{1}{2N}\sum_{i=1}^{N}\sum_{j=1}^{N+K} \left[y_{b\to s}^{ij}\log p_{b\to s}^{ij}+y_{s\to b}^{ij}\log p_{s\to b}^{ij}\right]$$Here \(N\) is the batch size, \(K\) is the number of queued candidates, \(y\) is a teacher probability and \(p\) is a student probability. The letter \(s\) denotes the combined sequence and statistic view. The paper reports a teacher momentum of 0.995 and a contrastive temperature of 0.3. Temperature controls how concentrated the similarity probabilities are. A distribution can give some credit to nearby candidates when the data contain flows with related behavior.
A separate objective gives cross attention a more pointed question. Each training flow provides a matched pair. The teacher identifies a highly similar but nonmatching candidate in each direction within the batch. A binary head sees the fused representation and judges whether the two views came from the same flow. This creates one positive and two hard negatives per flow. During the second stage of pretraining, the pair discrimination and similarity alignment objectives receive equal weight.
Masked byte prediction, pair discrimination and task supervision
$$\mathcal L_{\mathrm{MLM}}=-\frac{1}{|\mathcal M|}\sum_{t\in\mathcal M}\log p(x_t\mid\widetilde{T}_{\mathrm{byte}})$$ $$\mathcal L_{\mathrm{stage\ 2}}=\mathcal L_{\mathrm{MC}}-\frac{1}{3B}\sum_{n=1}^{3B}\sum_{c\in\{0,1\}}y_{nc}\log p_{nc}$$ $$\mathcal L_{\mathrm{task}}=-\frac{1}{B}\sum_{i=1}^{B}\sum_{c=1}^{C}y_{ic}\log p_{ic}$$The first stage hides 15% of eligible byte tokens. That encoder is frozen when the later components learn across flows and remains frozen during fine tuning. A downstream linear head uses the fused representation to predict the labels in a chosen benchmark. The teacher, queues and binary matching head belong to pretraining. In deployment, the downstream model still pays for three input encoders and the fusion module.
What the benchmarks actually show
The pretraining corpus comprised 3,106,501 samples across four public sources. The paper separates these sources from the datasets used to fine tune and evaluate the model. For the public downstream experiments, the authors sampled up to 500 flows per class and split the retained examples into training, validation and test sets at an 8 to 1 to 1 ratio. The dataset counts in the paper describe available flows before this sampling step. The scores in the table therefore reflect a controlled benchmark protocol whose class mix may differ from a live network.
| Dataset | M2ANet | Highest listed baseline | Baseline F1 | Gain in points |
|---|---|---|---|---|
| USTC-TFC | 98.11% | TrafficFormer | 97.98% | 0.13 |
| ISCX-VPN-Server | 91.55% | TrafficFormer | 91.14% | 0.41 |
| ISCX-VPN-App | 84.36% | MIMETIC | 75.14% | 9.22 |
| CIC-IOT | 91.43% | YaTC | 91.37% | 0.06 |
| Cross Platform Android | 82.74% | MM4flow | 79.81% | 2.93 |
| Cross Platform iOS | 80.74% | TrafficScope | 76.34% | 4.40 |
The 9.22 point improvement on the VPN application task is a different result from the 0.06 point edge on the IoT dataset. That combination is more informative than a count of benchmark wins. It shows where the added architecture changes the comparison substantially and where a simpler benchmark winner may depend on small changes to the experimental conditions. Study readers can also account for the fact that the metric ranking differs by task. A network team would choose its metrics to reflect which classifications trigger human review and which merely organize monitoring data.
Table 7 offers a cleaner way to examine what the model uses. Across four datasets, the full model scored 90.58% F1. The byte only variant scored 84.21%, and removing the byte branch left 52.01%. Removing alignment yielded 84.43%. Substituting concatenation for cross attention yielded 86.96%. Those differences describe each ablation against the full system and should be read individually, since changes to one component can alter how the others are trained. The strong byte branch is a reason to test the stability of retained header information alongside aggregate accuracy.
“Data will be made available on request.”
Huang and colleagues, data availability statement
What changes across a week or a location
The temporal experiment trains on traffic collected earlier and tests on traffic from the same environment captured one week later. The geographic and temporal experiment changes both conditions and evaluates shared categories. The source only methods, including M2ANet, do not adapt on target samples. This design asks how a trained system travels before a team has collected or used local examples for adaptation.
| Shift | Method | Source F1 | Target F1 | Drop in points |
|---|---|---|---|---|
| Time | M2ANet | 91.43% | 75.31% | 16.12 |
| Time | PEAN | 90.19% | 73.89% | 16.30 |
| Location and time | M2ANet | 90.12% | 59.89% | 30.23 |
| Location and time | MM4flow | 89.93% | 58.17% | 31.76 |
The gap between M2ANet and the best target baseline is 1.42 points in the temporal test and 1.72 in the combined test. In both cases, the loss from moving to the new distribution is much larger than the gain from changing the architecture. That puts the model ranking and the operational risk in proportion. A team can buy itself a modest margin with a stronger classifier and still face a substantial change in the quality of predictions the day it moves to a new site.
The results also have a useful connection to what AI Trend Blend’s review of federated learning for edge cyberattack detection describes about variation between devices and sites. Each site can produce a different mix of examples. In this study the appropriate next measurement would be a breakdown by site, time and class, with both the number of examples and the errors shown. Reporting the average alone makes a productive deployment question difficult to answer. Which traffic group would actually account for a jump in manual reviews?
Limits and deployment tradeoffs
The robustness tests use private data, which the paper says can be requested. A public benchmark reimplementation can test the mechanics of training, but verification of the private drift results depends on access to the data and split definitions. A week is a clear test interval with an interpretable result. Longer histories and multiple independent locations would show whether the same model ranking persists when the application mix changes repeatedly.
Known traffic classes also define the scope of the comparison. An unfamiliar service can arrive with a confident prediction under an existing category. F1 on a shared class set leaves the question of recognition of unknown traffic open. A deployment study could add an explicit rejection option and measure how many familiar flows it sends to review and how many new categories it flags. AI Trend Blend’s research review on intrusion detection evaluation offers another perspective on matching the test setting to the claim being made. The experiments in M2ANet study naturally occurring distribution shift under passive observation.
Header masking reduces dependence on the explicitly masked fields. The paper leaves the contribution and stability of individual retained fields open. There is also a privacy distinction between collecting fewer fields and proving a privacy guarantee. A network operator using this approach would still need to understand which observations are collected, what can be inferred from them, and how long the underlying telemetry is retained. Those practical questions remain even when the model consumes derived features.
The paper measured 14.232 ms mean latency per sample for M2ANet at inference batch size one under its comparison protocol. That estimate measures the model benchmark. An operational evaluation would separately measure the time required to accumulate a flow window, transform its inputs and return a classification. The measured latency is one piece of the decision, especially in a monitoring system where many flows compete for the same resources.
What to carry forward from M2ANet
M2ANet provides evidence that explicit alignment can make a multimodal traffic classifier more effective. The public results show the gain depends on the dataset. In the ablation, the largest contribution among the tested fusion and training changes came from explicit alignment. That result is a stronger argument for treating the relationship between views as a design choice than for adding layers to the fusion head.
The conceptual shift is to train for agreement in the structure of the evidence before training for a traffic label. The teacher expresses which candidate flows look related across representations. Attention can then combine what the views have learned. This division gives a practitioner two experiments to run when performance slips. One checks whether the views are still aligned, and the other checks whether the fused prediction is still correct.
The idea transfers to other settings where several instruments observe the same event. An industrial system might pair a series of actuator reports with summaries of vibration bursts. A quality control system could relate images to measurements from another process step. The useful condition is reliable pairing between observations, since mismatched timestamps or records would teach the model the wrong cross view relationships.
The strongest evidence needed next is a sequence of independent deployment tests. Field level ablations could identify input features that hold up across sites. Longer observation windows could reveal how quickly the alignment advantage decays, and unknown category experiments could show what happens when the shared label set no longer describes the traffic being observed.
The decisive number for a security team is the one the classifier earns on the traffic it will actually see. A result on next month’s flows from a new site can determine whether the model belongs in a monitoring pipeline, even when the familiar benchmark already looks excellent.
PyTorch reference implementation
This compact research implementation uses prepared tensors and a synthetic smoke test. It shows masked byte prediction, frozen packet encoding, queued teacher alignment, hard negative pair matching, cross attention and supervised fine tuning. The shared alignment projection, attention token layout and padding conventions are implementation choices. The example uses small dimensions so readers can run all stages on a CPU. Reproducing the published benchmark requires the study data, splits and experimental configuration.
"""Offline M2ANet reference for prepared, authorized tensors.

Inputs are header tokens [B,P,L], signed lengths [B,S], burst features
[B,R,4], and optional packet and sequence burst IDs of shapes [B,P]
and [B,S]. Use 256 for byte padding, NaN for scalar or burst padding,
and zero for unused burst IDs. Keep at least one valid item per view.
"""
from copy import deepcopy

import torch
from torch import nn
from torch.nn import functional as F

PAD, MASK, CLS = 256, 257, 258


def mean_pool(tokens, padding):
    valid = (~padding).unsqueeze(-1)
    return (tokens * valid).sum(1) / valid.sum(1).clamp_min(1)


class Context(nn.Module):
    def __init__(self, width, heads, depth, length, segments=0):
        super().__init__()
        self.position = nn.Embedding(length, width)
        self.segment = nn.Embedding(segments, width) if segments else None
        layer = nn.TransformerEncoderLayer(
            width, heads, 4 * width, activation="gelu", batch_first=True
        )
        self.encoder = nn.TransformerEncoder(layer, depth, enable_nested_tensor=False)

    def forward(self, x, padding, segment_ids=None):
        x = x + self.position(torch.arange(x.size(1), device=x.device))
        if self.segment is not None:
            if segment_ids is None:
                segment_ids = torch.zeros_like(padding, dtype=torch.long)
            x = x + self.segment(segment_ids)
        return self.encoder(x, src_key_padding_mask=padding)


class PacketEncoder(nn.Module):
    def __init__(self, width, heads, depth):
        super().__init__()
        self.tokens = nn.Embedding(259, width, padding_idx=PAD)
        self.context = Context(width, heads, depth, 65)
        self.predict = nn.Linear(width, 256)

    def forward(self, headers):
        cls = headers.new_full((headers.size(0), 1), CLS)
        tokens = torch.cat((cls, headers), dim=1)
        return self.context(self.tokens(tokens), tokens.eq(PAD))

    def masked_loss(self, headers, rate=0.15):
        eligible = headers.lt(256)
        selected = (torch.rand(headers.shape, device=headers.device) < rate) & eligible
        if not selected.any():
            first = eligible.nonzero()[0]
            selected[first[0], first[1]] = True
        corrupted = headers.masked_fill(selected, MASK)
        logits = self.predict(self(corrupted)[:, 1:][selected])
        return F.cross_entropy(logits, headers[selected])


class FlowEncoders(nn.Module):
    def __init__(self, width, heads, depth):
        super().__init__()
        self.packet = PacketEncoder(width, heads, depth)
        self.byte_context = Context(width, heads, depth, 10, segments=51)
        self.length_embedding = nn.Embedding(4097, width)
        self.sequence_context = Context(width, heads, depth, 100, segments=51)
        self.burst_features = nn.Linear(4, width)
        self.burst_context = Context(width, heads, depth, 50)
        self.byte_projection = nn.Linear(width, width)
        self.behavior_projection = nn.Linear(2 * width, width)
        self.view_embedding = nn.Embedding(2, width)

    def forward(self, headers, lengths, bursts, packet_segments=None, sequence_segments=None):
        batch, packets, header_length = headers.shape
        packet_padding = headers.eq(PAD).all(-1)
        packet_vectors = self.packet(headers.reshape(-1, header_length))[:, 0]
        byte = self.byte_context(
            packet_vectors.reshape(batch, packets, -1), packet_padding, packet_segments
        )

        length_padding = ~lengths.isfinite()
        # This reference uses a clipped signed lookup and reserves NaN for padding.
        length_ids = lengths.masked_fill(length_padding, 0).clamp(-2048, 2048).round().long() + 2048
        sequence = self.sequence_context(
            self.length_embedding(length_ids), length_padding, sequence_segments
        )
        burst_padding = ~bursts.isfinite().all(-1)
        statistics = self.burst_context(
            self.burst_features(bursts.masked_fill(burst_padding.unsqueeze(-1), 0)),
            burst_padding,
        )

        byte_vector = mean_pool(byte, packet_padding)
        behavior_vector = torch.cat(
            (mean_pool(sequence, length_padding), mean_pool(statistics, burst_padding)), dim=-1
        )
        byte_key = F.normalize(self.byte_projection(byte_vector), dim=-1)
        behavior_key = F.normalize(self.behavior_projection(behavior_vector), dim=-1)
        behavior = torch.cat(
            (sequence + self.view_embedding.weight[0], statistics + self.view_embedding.weight[1]),
            dim=1,
        )
        behavior_padding = torch.cat((length_padding, burst_padding), dim=1)
        return byte, behavior, packet_padding, behavior_padding, byte_key, behavior_key


class CrossAttention(nn.Module):
    def __init__(self, width, heads):
        super().__init__()
        self.attention = nn.MultiheadAttention(width, heads, batch_first=True)
        self.norm1 = nn.LayerNorm(width)
        self.norm2 = nn.LayerNorm(width)
        self.ffn = nn.Sequential(nn.Linear(width, 4 * width), nn.GELU(), nn.Linear(4 * width, width))

    def forward(self, query, other, other_padding):
        update, _ = self.attention(
            query, other, other, key_padding_mask=other_padding, need_weights=False
        )
        query = self.norm1(query + update)
        return self.norm2(query + self.ffn(query))


class M2ANet(nn.Module):
    def __init__(self, num_classes, width=768, heads=12, depth=6):
        super().__init__()
        self.encoders = FlowEncoders(width, heads, depth)
        self.byte_fusion = nn.ModuleList(CrossAttention(width, heads) for _ in range(depth))
        self.behavior_fusion = nn.ModuleList(CrossAttention(width, heads) for _ in range(depth))
        self.match = nn.Linear(2 * width, 2)
        self.classify = nn.Linear(2 * width, num_classes)

    def train(self, mode=True):
        super().train(mode)
        if not self.encoders.packet.tokens.weight.requires_grad:
            self.encoders.packet.eval()
        return self

    def fuse(self, byte, behavior, byte_padding, behavior_padding):
        for byte_layer, behavior_layer in zip(self.byte_fusion, self.behavior_fusion):
            next_byte = byte_layer(byte, behavior, behavior_padding)
            behavior = behavior_layer(behavior, byte, byte_padding)
            byte = next_byte
        return torch.cat((mean_pool(byte, byte_padding), mean_pool(behavior, behavior_padding)), -1)

    def forward(self, *views):
        byte, behavior, byte_pad, behavior_pad, _, _ = self.encoders(*views)
        return self.classify(self.fuse(byte, behavior, byte_pad, behavior_pad))


class AlignmentTrainer:
    def __init__(self, model, queue_size=128, momentum=0.995, temperature=0.3):
        self.teacher = deepcopy(model.encoders).requires_grad_(False).eval()
        self.momentum = momentum
        self.temperature = temperature
        self.queue_size = queue_size
        width = model.encoders.byte_projection.out_features
        weight = model.encoders.byte_projection.weight
        self.byte_queue = weight.new_empty((0, width))
        self.behavior_queue = weight.new_empty((0, width))

    def soft_loss(self, student_query, student_keys, teacher_query, teacher_keys):
        target = (teacher_query @ teacher_keys.T / self.temperature).softmax(-1)
        log_pred = (student_query @ student_keys.T / self.temperature).log_softmax(-1)
        return -(target * log_pred).sum(-1).mean()

    def step(self, model, optimizer, views):
        model.train()
        byte, behavior, byte_pad, behavior_pad, sb, ss = model.encoders(*views)
        n = sb.size(0)
        if n < 2:
            raise ValueError("Alignment requires at least two flows per batch.")
        with torch.no_grad():
            *_, tb, ts = self.teacher(*views)
            similarities = tb @ ts.T
            similarities.fill_diagonal_(-torch.inf)
            neg_behavior = similarities.argmax(dim=1)
            neg_byte = similarities.argmax(dim=0)

        b_to_s = self.soft_loss(
            sb, torch.cat((ss, self.behavior_queue)), tb,
            torch.cat((ts, self.behavior_queue))
        )
        s_to_b = self.soft_loss(
            ss, torch.cat((sb, self.byte_queue)), ts, torch.cat((tb, self.byte_queue))
        )
        alignment = (b_to_s + s_to_b) * 0.5

        rows = torch.arange(n, device=sb.device)
        b_idx = torch.cat((rows, rows, neg_byte))
        s_idx = torch.cat((rows, neg_behavior, rows))
        fused = model.fuse(byte[b_idx], behavior[s_idx], byte_pad[b_idx], behavior_pad[s_idx])
        labels = torch.cat((rows.new_ones(n), rows.new_zeros(2 * n)))
        discrimination = F.cross_entropy(model.match(fused), labels)
        loss = alignment + discrimination
        optimizer.zero_grad(set_to_none=True)
        loss.backward()
        optimizer.step()
        with torch.no_grad():
            for target, source in zip(self.teacher.parameters(), model.encoders.parameters()):
                target.lerp_(source, 1 - self.momentum)
            self.byte_queue = torch.cat((self.byte_queue, tb))[-self.queue_size:]
            self.behavior_queue = torch.cat((self.behavior_queue, ts))[-self.queue_size:]
        return loss.item()


def fit(model, packets, aligned_batches, labeled_batches, epochs=(1, 1, 1)):
    """Each iterable should be reusable, such as a DataLoader or list."""
    model.train()
    device = next(model.parameters()).device
    packet_optimizer = torch.optim.AdamW(model.encoders.packet.parameters(), lr=1e-3)
    for _ in range(epochs[0]):
        for headers in packets:
            headers = headers.to(device).reshape(-1, headers.shape[-1])
            headers = headers[headers.ne(PAD).any(-1)]
            if headers.numel() == 0:
                continue
            packet_optimizer.zero_grad(set_to_none=True)
            model.encoders.packet.masked_loss(headers).backward()
            packet_optimizer.step()

    model.encoders.packet.requires_grad_(False)
    trainable = [p for p in model.parameters() if p.requires_grad]
    alignment_optimizer = torch.optim.AdamW(trainable, lr=1e-3)
    alignment = AlignmentTrainer(model)
    for _ in range(epochs[1]):
        for views in aligned_batches:
            alignment.step(model, alignment_optimizer, tuple(x.to(device) for x in views))

    task_optimizer = torch.optim.AdamW(trainable, lr=1e-4)
    for _ in range(epochs[2]):
        model.train()
        for views, labels in labeled_batches:
            task_optimizer.zero_grad(set_to_none=True)
            logits = model(*(x.to(device) for x in views))
            F.cross_entropy(logits, labels.to(device)).backward()
            task_optimizer.step()


@torch.inference_mode()
def evaluate(model, batches):
    model.eval()
    device = next(model.parameters()).device
    confusion = None
    for views, labels in batches:
        logits = model(*(x.to(device) for x in views))
        k = logits.size(-1)
        counts = torch.bincount(
            labels.to(device) * k + logits.argmax(-1), minlength=k * k
        ).reshape(k, k)
        confusion = counts if confusion is None else confusion + counts
    if confusion is None:
        raise ValueError("Evaluation requires at least one batch.")
    correct = confusion.diag().float()
    denominator = confusion.sum(0) + confusion.sum(1)
    return {
        "accuracy": (correct.sum() / confusion.sum()).item(),
        "macro_f1": (2 * correct / denominator.clamp_min(1)).mean().item(),
    }


def smoke_test():
    torch.manual_seed(7)
    torch.set_num_threads(1)

    def batch():
        headers = torch.randint(0, 256, (4, 3, 12))
        headers[0, -1] = PAD
        lengths = torch.randint(-256, 256, (4, 8)).float()
        lengths[0, -1] = torch.nan
        bursts = torch.rand(4, 5, 4)
        bursts[0, -1] = torch.nan
        segments = (torch.arange(3) // 2).expand(4, -1)
        length_segments = (torch.arange(8) // 2).expand(4, -1)
        return headers, lengths, bursts, segments, length_segments

    train = [batch(), batch()]
    labels = torch.tensor([0, 1, 2, 0])
    model = M2ANet(num_classes=3, width=32, heads=4, depth=1)
    fit(model, [views[0] for views in train], train, [(v, labels) for v in train])
    metrics = evaluate(model, [(batch(), labels)])
    assert all(0 <= score <= 1 for score in metrics.values())
    assert not model.encoders.packet.tokens.weight.requires_grad
    print("Synthetic smoke test passed:", metrics)


if __name__ == "__main__":
    smoke_test()
Frequently asked questions
What is M2ANet?
M2ANet is a classifier that learns from header bytes, packet length sequences and burst statistics. It aligns these views during pretraining before combining them to predict traffic categories.
Does M2ANet decrypt network traffic?
The model classifies flows using header information and observed behavior. Its byte branch excludes ciphertext payloads.
What is the difference between alignment and fusion?
Alignment trains the encoders to agree on how candidate flows relate. Fusion uses cross attention to combine information from the views for pair matching and traffic classification.
How well did M2ANet handle traffic drift?
It reached 75.31% F1 when tested one week later in the same environment and 59.89% when both time and location changed. The corresponding drops were 16.12 and 30.23 percentage points.
Why does the byte ablation matter?
The header byte branch contributed strongly to performance across the four ablation datasets. The result motivates a closer look at which retained fields remain informative across sites and time periods.
Can the published drift tests be reproduced from public data?
The public benchmarks can be studied separately. The paper says data will be made available on request, and the reported drift evaluation used private traffic.
Mei Huang, Jinqiao Shi, Zhenquan Ding, Wei Wang, Wentao Huang, Wei Peng and Zhiyu Hao. M²ANet, alignment aware multimodal fusion with multi granularity modeling for robust encrypted traffic classification. Information Fusion, volume 140, article 104929, 2027. Available online 4 November 2026. DOI 10.1016/j.inffus.2026.104929.
This analysis is based on the published paper and an independent evaluation of its claims.