
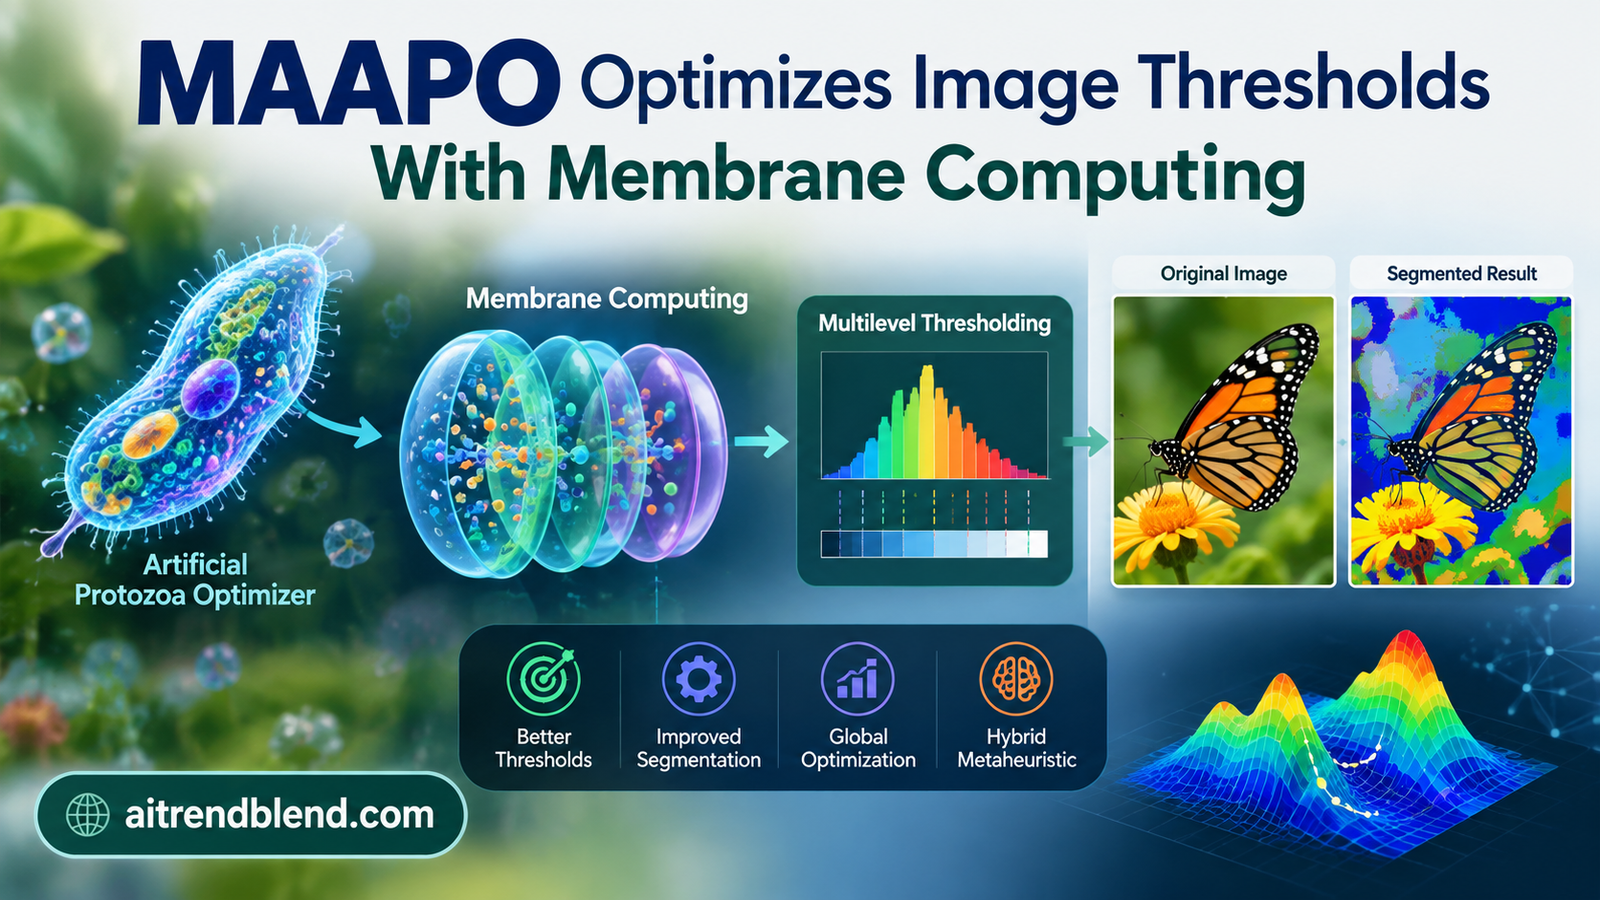
Splitting an image into meaningful regions can come down to a surprisingly old trick, picking a few brightness cutoffs and sorting every pixel into the band it falls in. It works well until you want more than a couple of cutoffs. Ask for six or seven and the number of possible combinations explodes, and finding the best set becomes a genuinely hard search problem. This paper borrows an unlikely pair of ideas, the foraging of single celled organisms and the compartments of a biological cell, to search that space better.
Key points
- Multilevel thresholding segments an image by choosing several gray level cutoffs, and finding the best cutoffs is an optimization problem that grows exponentially harder as you add more thresholds.
- MAAPO improves a recent nature inspired optimizer, the artificial protozoa optimizer, with two additions that add no new tunable model.
- A membrane computing framework splits the population into separate compartments and merges them back, guided by a diversity metric, to keep the search from collapsing into a local optimum.
- A roulette based fitness distance balance replaces the optimizer’s random reference point with one chosen to balance quality and spread across the search space.
- On the CEC2017 optimization benchmark MAAPO ranked first among thirteen algorithms, and on color image segmentation it was strongest under the Kapur entropy method, especially at higher threshold counts.
- The work is a peer reviewed journal article with publicly released MATLAB code, and it is honest that the gains shrink to nothing at low threshold counts where the problem is easy.
Why thresholding gets hard fast
Image segmentation splits a picture into regions that mean something, and thresholding is one of the oldest and most practical ways to do it. You choose one or more gray level cutoffs, and every pixel is assigned to a class by which band its intensity falls into. With a single cutoff you get bilevel thresholding, foreground against background. With two or more you get multilevel thresholding, which carves the image into several regions and generally produces a better segmentation. It is computationally simple, robust, and effective, which is why it stays popular even as fancier methods arrive. The same appetite for better segmentation runs through modern work like segmenting images without labels, but thresholding remains the workhorse when you want speed and simplicity.
Here is where it gets hard. Adding thresholds improves segmentation quality, but the number of ways to place them grows explosively. Finding the set of cutoffs that maximizes a quality criterion, over a full color image with three bands and six or seven thresholds each, is a high dimensional search with an enormous number of candidate solutions and many local optima to get trapped in. Exhaustive search is hopeless. This is exactly the kind of problem where metaheuristic optimizers earn their keep, the family of nature inspired search methods that includes particle swarm optimization, grey wolf optimization, and many others, which we have covered before in work like an improved pelican optimization algorithm.
The base optimizer here is a recent one, the artificial protozoa optimizer, introduced in 2024. It mimics how protozoa forage, go dormant, and reproduce. In the light they forage like plants through a process the paper calls autotrophic, and in the dark they behave like animals and absorb food, called heterotrophic. In harsh conditions they slow down and go dormant, and at the right age they split in two to reproduce. Each of these behaviors becomes a search operator. It is a competitive optimizer, but like all of them it can still get stuck in a local optimum and converge too early on a complex landscape. The authors, from the VŠB-Technical University of Ostrava, Torrens University Australia, and Nanjing University of Information Science and Technology, set out to fix exactly that weakness.
The core problem. More thresholds mean a better segmentation but an exponentially larger search space with more traps. A good optimizer has to keep exploring long enough to avoid settling into a mediocre local optimum, which is precisely where many nature inspired methods fail.
Compartments that keep the search alive
The first of MAAPO’s two additions is membrane computing, a computational paradigm inspired by how a biological cell is divided into compartments by membranes. It provides a parallel distributed structure of nested regions, each holding objects that evolve by their own rules, in what is formally called a P-system. MAAPO treats each candidate solution as an object living in one of these membrane compartments, and uses a separating and merging principle to reshape the population as the search proceeds.
The decision of when to split and when to merge is driven by a diversity metric the authors call multidimensional volumes, or mVOL, which measures how spread out the population currently is across the search space.
The logic is intuitive once you unpack it. When mVOL is above a small threshold, the population is still spread out, so MAAPO activates the separating and merging operation, randomly dividing all solutions into several membranes, evolving each membrane on its own, then merging them back together. When mVOL drops below that threshold, the population has converged, and everything is kept in a single membrane. Splitting the population makes each compartment smaller and more varied than the whole, which promotes diversity and fights premature convergence, and merging lets the compartments exchange information. The number of membranes is not fixed either.
The authors tested this and found a dynamic membrane count beats a static one, with an upper bound of four working best. Early in the search the population is spread out, so it splits into compartments and explores broadly. As it converges, mVOL shrinks and the algorithm naturally transitions to a single membrane, tightening the search. The membrane machinery is, in effect, an automatic schedule that balances exploration against exploitation without a hand tuned knob.
Choosing a better reference point
The second addition targets a specific line inside the protozoa optimizer. In its autotrophic foraging step, a protozoan moves partly toward another randomly chosen protozoan. Choosing that reference at random is wasteful, because it ignores whether the reference is any good or whether it points somewhere useful. MAAPO replaces the random choice with a principled one, drawn from a family of selection methods called fitness distance balance.
The idea of fitness distance balance is to score each candidate by combining how good it is with how far it sits from the current best, so the search is pulled toward solutions that are both high quality and located in unexplored regions.
MAAPO uses the roulette variant, which does not simply grab the single highest scoring candidate but selects probabilistically in proportion to the scores. That randomness matters. The authors compared three selection variants and found the roulette version clearly best, because deterministically picking one reference point every iteration limits how widely the algorithm can explore, whereas roulette selection lets diverse reference points get chosen across iterations. The reference selection then slots into the autotrophic foraging update in place of the original random pick.
Crucially, both additions are parameter light and build on components the optimizer already has. Neither introduces a separate learned model, so the whole thing remains a clean metaheuristic. The ablation confirms both matter. Against the base optimizer, MAAPO with only the membrane system and MAAPO with only the roulette selection each won 5 of 30 benchmark functions and lost none, and the full combination won 8 and lost none, so the two strategies are complementary rather than redundant.
How it does on the optimization benchmark
Before touching images, the authors validated MAAPO on CEC2017, a standard suite of 30 optimization functions spanning unimodal, multimodal, hybrid, and composition types, against twelve other algorithms including the base protozoa optimizer, grey wolf variants, particle swarm variants, differential evolution, and several recent nature inspired methods. Ranked by the Friedman test, MAAPO came out on top.
| Algorithm | Average rank |
|---|---|
| MAAPO | 3.35 |
| MAQUATRE | 3.37 |
| APO (base optimizer) | 3.55 |
| DE | 4.43 |
| ARO | 5.25 |
| PSO | 9.35 |
| GWO | 10.60 |
| SGA | 12.80 |
The head to head comparisons fill in the picture. Under the Wilcoxon signed rank test MAAPO recorded 30 wins and no losses against both grey wolf optimization and the snow geese algorithm, and it held a clear advantage over the animated oat optimizer with 25 wins and no losses. Against its own base, the protozoa optimizer, it won 8, drew 22, and lost none, a consistent improvement with no regression. The one close call was against MAQUATRE, where results were evenly split at 10 wins, 10 draws, and 10 losses, and the Friedman ranks were nearly tied. The honest reading is that MAAPO is at or near the top of a strong field, not that it demolishes everything.
That gain is not free. MAAPO averaged 1.38 seconds per function against 0.81 for the base optimizer, since the membrane operations and the roulette selection add work each iteration. The authors call this acceptable given the better search quality, and it is a fair trade for an offline optimization step, though it is a real cost worth noting.
Segmenting images
The application is color image segmentation by multilevel thresholding, using two classic criteria as the objective the optimizer maximizes. The Otsu method searches for thresholds that maximize the variance between the resulting classes, while the Kapur entropy method searches for thresholds that maximize the entropy of the class distributions.
Segmentation quality is judged by three standard measures, peak signal to noise ratio, the structural similarity index, and the feature similarity index, all comparing the segmented image against the original, with higher meaning better. The team ran MAAPO and seven competitors on three color images, a parrot, an owl, and a horse, at 4, 5, 6, and 7 thresholds, over twenty runs each.
The results carry an honest caveat the authors state plainly. At 4 thresholds almost every algorithm performs the same, because the problem is low dimensional and easy, so there is little to separate the methods. The advantage of MAAPO shows up as the threshold count rises and the search space becomes genuinely hard, which is exactly when a better optimizer should matter. Ranked by the Friedman test across the three images, the picture differs by criterion.
| Method and metric | MAAPO rank | Best competitor |
|---|---|---|
| Otsu, structural similarity | 3.83 (best) | MAAPO |
| Otsu, peak signal to noise | competitive | PSO at 3.17 |
| Otsu, feature similarity | competitive | DE at 3.58 |
| Kapur, peak signal to noise | 3.17 (best) | MAAPO |
| Kapur, structural similarity | 3.75 (best) | MAAPO |
| Kapur, feature similarity | 3.42 (best) | MAAPO |
Under the Kapur entropy criterion MAAPO took the best average rank on all three quality measures, a clean sweep. Under the Otsu criterion it won on structural similarity but placed behind particle swarm optimization on peak signal to noise and behind differential evolution on feature similarity, so it was superior or comparable rather than dominant there. Taken together the segmentation results show MAAPO is competitive and often best, concentrated at the higher threshold counts where the optimization is hard, which is the honest and useful place for the gain to appear.
Key takeaway. The improvement is real but it lives where the problem is hard. At four thresholds every method ties, and MAAPO pulls ahead only as the threshold count and the difficulty climb. That is the right signature for a genuinely better optimizer rather than a benchmark artifact.
Where it falls short
The authors are refreshingly candid about the limits, which strengthens the paper. The clearest one is that the advantage vanishes on easy problems. At low threshold counts MAAPO is indistinguishable from much simpler methods, so the extra machinery only pays off when the search space is large. If your application never needs many thresholds, a plain optimizer will do.
The added computation is a genuine cost too. Roughly 1.4 seconds per benchmark function against 0.8 for the base optimizer is a meaningful overhead, driven by the membrane separating and merging and the roulette selection running every iteration. For offline image segmentation that is fine, but it is not the method to reach for when speed is the priority, and faster competitors like particle swarm optimization exist for exactly that reason.
There are scope limits worth naming as well. The optimization validation is on a single benchmark suite at one dimension setting, and the segmentation study covers three images at four threshold settings, which is a reasonable but not exhaustive evaluation. Under the Otsu criterion MAAPO did not win the peak signal to noise or feature similarity rankings, so the method is not uniformly best across every criterion and metric. And like all metaheuristics, it comes with no guarantee of finding the global optimum, only a better empirical tendency to avoid poor local ones. The paper is a peer reviewed journal article rather than a preprint, and its released MATLAB code makes the claims checkable, both of which raise confidence in the modest, well scoped result it reports.
Why the approach travels
Beyond image thresholding, MAAPO is a template for improving any population based optimizer. The two ideas are portable and independent of the protozoa metaphor. First, splitting a population into compartments and merging them on a diversity signal is a general way to schedule exploration against exploitation without hand tuning, and it could wrap around almost any swarm or evolutionary method. Second, replacing a random reference point with a fitness distance balance selection is a small change that repeatedly helps, because it steers the search toward candidates that are both good and far from the current crowd.
Multilevel thresholding itself is a workhorse across fields, from medical imaging to remote sensing to industrial inspection, so a better threshold optimizer has broad practical reach. The broader current, of taking a base optimizer and grafting on a mechanism that preserves diversity, runs through a lot of recent metaheuristic work, including efforts like chaos driven enhancements for structural optimization and nature inspired optimizers applied to real imaging tasks. MAAPO’s contribution is a particularly clean pairing of a diversity preserving population structure with a smarter reference selection, validated end to end from an abstract benchmark to a concrete segmentation task.
Reference implementation in Python
The code below is a runnable reconstruction of MAAPO’s two core ideas, the membrane separating and merging framework driven by the mVOL diversity metric and the roulette fitness distance balance reference selection, based on the paper’s equations. It optimizes multilevel Otsu thresholds on an image histogram, so it doubles as a working multilevel segmentation solver on a synthetic histogram. A simplified autotrophic foraging step stands in for the full protozoa operator set to keep the file compact. A smoke test runs it end to end. Swap in the full operator set and real image histograms for actual experiments.
# maapo_reference.py
# Membrane framework + roulette fitness distance balance, applied to Otsu thresholds.

import numpy as np


def otsu_fitness(thresholds, hist, p):
    """Between class variance for a set of thresholds. Higher is better."""
    edges = np.concatenate([[0], np.sort(thresholds).astype(int), [len(hist)]])
    total_mean = np.sum(np.arange(len(hist)) * p)
    var = 0.0
    for a, b in zip(edges[:-1], edges[1:]):
        w = p[a:b].sum()
        if w < 1e-9:
            continue
        mu = np.sum(np.arange(a, b) * p[a:b]) / w
        var += w * (mu - total_mean) ** 2
    return var


def mvol(pop, lo, hi):
    """Multidimensional volume diversity metric, Eq 15 to 17."""
    spread = np.abs(pop.max(0) - pop.min(0)) + 1e-9
    limit = np.abs(hi - lo) + 1e-9
    return np.exp(np.mean(np.log(spread / limit)))   # (prod ratios) ** (1/dim)


def rfdb_select(pop, fit, best, rng):
    """Roulette fitness distance balance reference point, Eq 19 to 21."""
    f = (fit - fit.min()) / (fit.ptp() + 1e-9)         # normalized fitness
    d = np.linalg.norm(pop - best, axis=1)
    d = (d - d.min()) / (d.ptp() + 1e-9)               # normalized distance
    score = 0.5 * f + 0.5 * d                          # w = 0.5
    prob = score / score.sum()
    return pop[rng.choice(len(pop), p=prob)]           # roulette pick


def forage(pop, fit, lo, hi, rng):
    """Simplified autotrophic foraging toward an RFDB reference."""
    best = pop[fit.argmax()]
    new = pop.copy()
    for i in range(len(pop)):
        ref = rfdb_select(pop, fit, best, rng)
        f = rng.random()
        new[i] = pop[i] + f * (ref - pop[i]) + 0.1 * rng.standard_normal(pop.shape[1]) * (hi - lo)
    return np.clip(new, lo, hi)


def maapo(hist, n_thresh=5, ps=30, iters=60, eps=1e-4, m_max=4, seed=0):
    rng = np.random.default_rng(seed)
    p = hist / hist.sum()
    lo, hi = np.zeros(n_thresh), np.full(n_thresh, len(hist) - 1, float)
    pop = rng.uniform(lo, hi, size=(ps, n_thresh))
    evolve = lambda sub: forage(sub, np.array([otsu_fitness(x, hist, p) for x in sub]), lo, hi, rng)

    for _ in range(iters):
        if mvol(pop, lo, hi) < eps:
            pop = evolve(pop)                              # one membrane
        else:
            m = 1 + int(np.ceil((m_max - 1) * rng.random()))  # dynamic count, Eq 18
            idx = rng.permutation(ps)
            parts = np.array_split(idx, m)                 # separate
            for part in parts:
                pop[part] = evolve(pop[part])
            # merge is implicit: all parts write back into one pop
    fit = np.array([otsu_fitness(x, hist, p) for x in pop])
    best = np.sort(pop[fit.argmax()].astype(int))
    return best, fit.max()


if __name__ == "__main__":
    # synthetic histogram with a few bright modes, like a real image
    rng = np.random.default_rng(1)
    x = np.arange(256)
    hist = (np.exp(-((x - 40) ** 2) / 200) + np.exp(-((x - 120) ** 2) / 300)
            + np.exp(-((x - 200) ** 2) / 150)) * 1000
    thresholds, score = maapo(hist, n_thresh=4)
    print("best thresholds", thresholds.tolist())
    print("between class variance", round(float(score), 2))
Conclusion
The core achievement of MAAPO is to take a capable but sometimes fragile optimizer and make it steadier on hard search landscapes, using two ideas that cost no new tunable model. A membrane framework splits and merges the population on a diversity signal, keeping exploration alive when the search would otherwise collapse, and a roulette fitness distance balance replaces a wasteful random reference with one that balances quality against spread. On the CEC2017 benchmark that combination ranked first among thirteen algorithms, and on color image thresholding it was strongest under the Kapur criterion, especially where the problem is genuinely hard.
The conceptual contribution that outlasts the specific method is the pairing itself. Diversity preservation and smarter reference selection attack two different failure modes of population based search, premature convergence and uninformative movement, and the ablation shows they are complementary rather than redundant. Neither is tied to protozoa or to thresholding, so both could be grafted onto other swarm and evolutionary optimizers, which is the honest generalization the paper supports.
What makes the paper trustworthy is its restraint. It reports that the advantage disappears on easy, low threshold problems, that the method costs more per iteration than its base, and that it does not win every criterion under Otsu. It shows the gain concentrating exactly where a better optimizer should help, at higher threshold counts, rather than claiming a uniform victory. That is the profile of a real, well scoped improvement, and it is backed by a peer reviewed venue and released code.
For practitioners, the takeaway is practical. If you are optimizing multilevel thresholds for segmentation, or any similarly hard combinatorial search, a diversity aware population structure and a fitness distance balanced reference are cheap, model free additions worth trying, and they matter most exactly when the problem is hard enough that a plain optimizer stalls. MAAPO is published with public MATLAB code, and the reference above is a compact place to start testing the two ideas on a histogram of your own.
Frequently asked questions
What is multilevel threshold image segmentation?
It is a way of segmenting an image by choosing several gray level cutoffs and assigning each pixel to a class by which intensity band it falls into. A single cutoff gives foreground against background, while multiple cutoffs carve the image into several regions. More thresholds improve segmentation quality but make finding the best set of cutoffs a much harder optimization problem.
What does MAAPO add to the artificial protozoa optimizer?
MAAPO adds two parameter light mechanisms. A membrane computing framework splits the population into separate compartments and merges them back, guided by a diversity metric, to preserve exploration. And a roulette fitness distance balance replaces the optimizer’s random reference point with one selected to balance solution quality against distance from the current best.
How does the membrane framework decide when to split the population?
It uses a diversity metric called multidimensional volumes, or mVOL, which measures how spread out the population is. When mVOL is above a small threshold the population is still diverse, so MAAPO splits it into a dynamic number of membranes, evolves each, and merges them. When mVOL falls below the threshold the population has converged and everything stays in one membrane, tightening the search.
How well did MAAPO perform?
On the CEC2017 optimization benchmark it ranked first among thirteen algorithms by the Friedman test, with 30 wins and no losses against grey wolf optimization and the snow geese algorithm, and 8 wins with no losses against its own base optimizer. On color image segmentation it took the best average rank on all three quality metrics under the Kapur entropy method, with gains concentrated at higher threshold counts.
What are the main limitations?
The advantage disappears on easy, low threshold problems where every method ties, and the method costs more computation per iteration than its base, about 1.4 seconds against 0.8 on the benchmark. Under the Otsu criterion it did not win the peak signal to noise or feature similarity rankings, and like all metaheuristics it offers no guarantee of finding the global optimum.
Is the code available?
Yes. The work is a peer reviewed article in Artificial Intelligence Review, and the authors released the MAAPO source code publicly on MATLAB Central, which makes the reported results checkable and the method easy to build on.
Read the source and the code
This analysis draws on the published paper in Artificial Intelligence Review. You can reach it through the inline link earlier in this article, at the journal via its DOI.
Read the paper Get the MATLAB codeAcademic citation. Wang, X., Snášel, V., Mirjalili, S., and Pan, J.S. MAAPO, an innovative membrane algorithm based on artificial protozoa optimizer for multilevel threshold image segmentation. Artificial Intelligence Review 58, 324 (2025). DOI 10.1007/s10462-025-11319-2. Available at https://doi.org/10.1007/s10462-025-11319-2.
This analysis is based on the published paper and an independent evaluation of its claims. The paper is a peer reviewed journal article.