
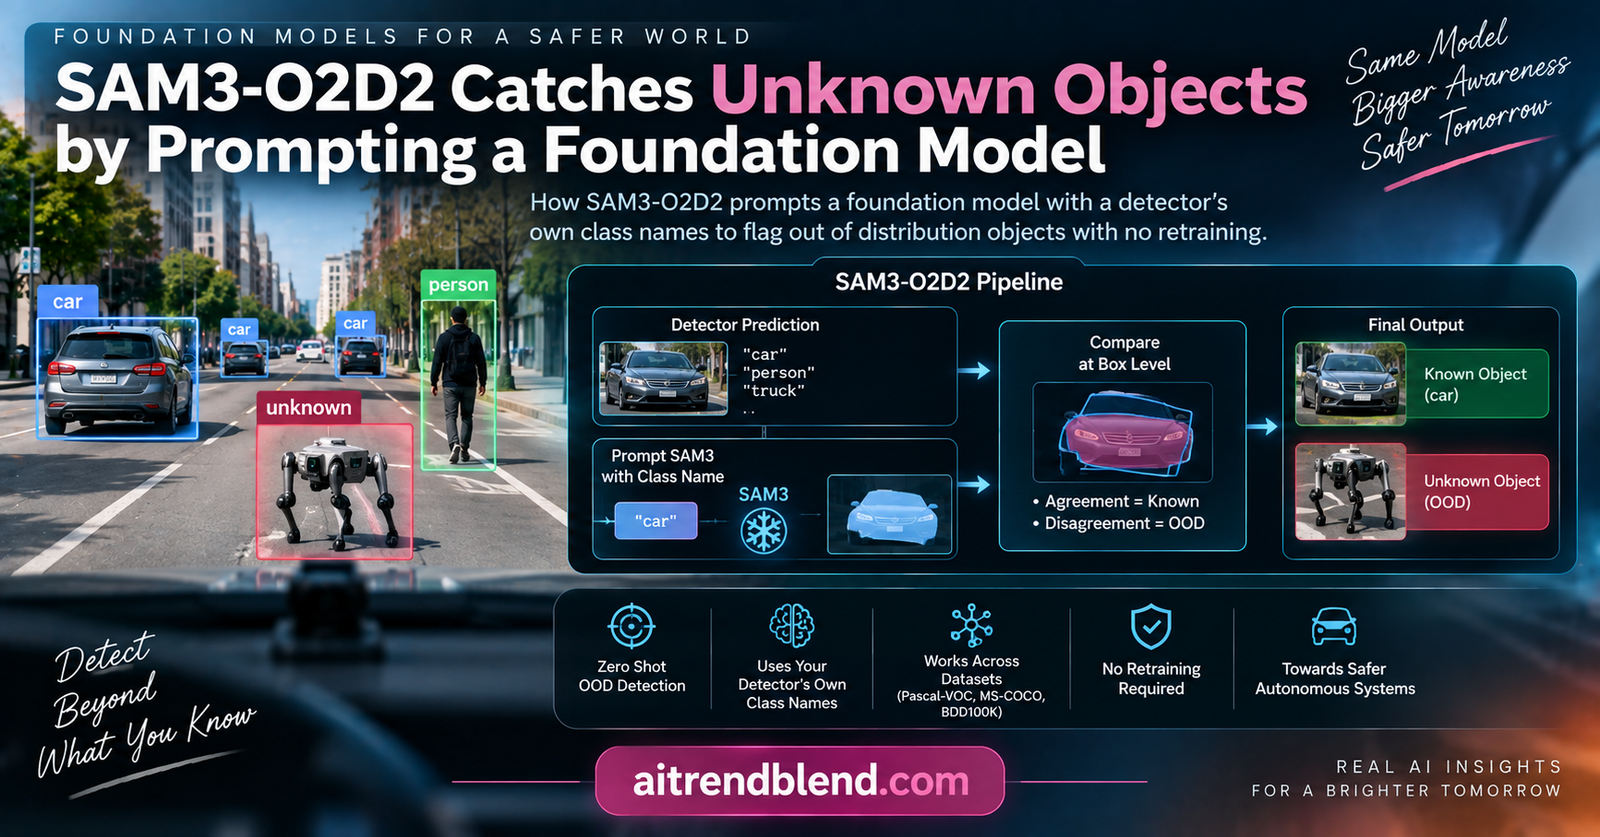
Show an object detector a picture of an elephant standing in a road and it might tell you, with high confidence, that it is looking at a car. This is not a rare glitch. Detectors are trained on a fixed set of categories, and when something outside that set appears, they do not shrug and say they are unsure. They force the new thing into the closest familiar label and report it with the same confidence they would give a real car. In a self driving system or a surveillance feed, that overconfidence is a safety problem, and a team at TU Braunschweig has a clever way to catch it.
Key points
- Object detectors are trained on a closed set of classes and become overconfident on anything unfamiliar, mislabeling unknown objects instead of flagging them.
- SAM3-O2D2 takes the detector’s own guess, such as the word car, and prompts a foundation model to find a car at that spot. If the foundation model finds nothing there, the object is out of distribution.
- The check happens at the level of boxes and labels, not in an abstract feature space, which makes it far more robust to sloppy boxes and lighting than prior methods.
- It needs no retraining, works with any object detector, and beats the previous best zero shot method on every dataset while running about five times faster.
- The biggest gap appears on small and poorly lit objects, where the previous best method fell to near chance while this one held up.
Why a detector cannot flag its own mistakes
The problem runs deeper than it first appears. An object detector learns to recognize a fixed list of categories, the in distribution classes, and its whole training pushes it to assign every object to one of them. When it meets something that belongs to none, an out of distribution object, it has no honest option to output. It simply picks the nearest class and attaches a confidence score, and that score can be just as high for a wrong guess as for a right one. The model is not lying, it is doing exactly what it was trained to do, which is to always answer.
Researchers have studied this at the image level for years, asking whether a whole picture is normal or anomalous. But a real driving scene contains many objects at once, some familiar and some not, so a single label for the whole image is useless. What matters is a per object judgment, and that is the harder task called object out of distribution detection. For each thing the detector reports, a separate system has to decide, is this a genuine member of a known class, which the field marks as in distribution, or is it something unknown, which it marks as out of distribution.
The classical fix is to train an extra module alongside the detector to make that call, but that means retraining for every new detector and needing the full training data. Newer methods lean on vision language foundation models such as CLIP to do it with few examples, yet they still fine tune a custom module for each dataset. The current best zero shot method, called RONIN, avoids retraining but does something computationally heavy, it uses a diffusion model to repaint the detected object according to its predicted class and then checks whether the repainted version matches. It works, but diffusion is slow, and its decision lives in an abstract feature space that can be fooled by things like object size and lighting.
The idea, in one sentence
Here is where it gets interesting. The TU Braunschweig method, named SAM3-O2D2, takes a completely different route. It uses a foundation detection model, SAM3, which can be prompted with a text label and asked to find objects of that class in an image. The trick is to feed SAM3 the object detector’s own guesses. If the detector says there is a car at a certain spot, the system prompts SAM3 with the word car and checks whether SAM3 also finds a car in the same place. If it does, the detector’s guess is corroborated and the object is in distribution. If SAM3, prompted with car, finds nothing at that location, then the visual content does not actually look like a car, the detector’s guess was a forced mislabel, and the object is flagged as out of distribution.
The elegance is that it turns the broad semantic knowledge of a foundation model into a lie detector for a narrow one. The narrow detector has to guess from its closed list. The foundation model has seen far more of the world and can honestly report that no car is present when the object is really an elephant. This is a form of prompting a large pretrained model to do a job it was never explicitly trained for, in the same spirit as work on visual prompting of foundation models without touching their weights. And because the whole method runs after the detector, at the level of its final predictions, it needs no retraining and works with any detector you plug in.
How the check actually works
The pipeline has a few clean steps. First the object detector runs and produces its predictions, a set of bounding boxes each with a predicted class. The system collects the unique class names among those predictions, which it calls R. In the paper’s running example the detector predicts seven objects across three classes, car, person, and bus, so R is three.
Next, the text encoder of SAM3 turns each of those class names into an embedding, and these are precomputed offline for the whole dataset vocabulary so this step is free at run time. Then SAM3 is run once per unique class, three times in the example, each time prompted with one class name, and each run returns SAM3’s own bounding boxes and confidence scores for that class. Running once per unique class rather than once per object is what keeps the cost down.
Now the agreement check. For each detector box, the system finds SAM3 boxes of the same class and measures how much they overlap using intersection over union, the standard overlap measure.
A detector prediction is marked in distribution if at least one SAM3 box of the same class overlaps it above an intersection over union threshold and carries a confidence above a score threshold. Every prediction that fails this test, no matching SAM3 box of the right class in the right place, is marked out of distribution. That is the entire decision. It is interpretable in a way feature space methods are not, because you can look at exactly which prompted class SAM3 failed to confirm and understand why an object was flagged.
The detector incorrectly calls an elephant a cow, but SAM3, prompted with cow, finds no cow there because the pixels are not a cow. The mismatch is the whole signal, and you can read it directly. Reading of the SAM3-O2D2 mechanism
How well it works
The authors tested the method with two in distribution datasets, Pascal-VOC and BDD100K, a driving dataset, and two out of distribution datasets, MS-COCO and OpenImages, using subsets carefully built so their objects do not overlap with the in distribution classes. Performance is measured two ways, the area under the receiver operating curve, where higher is better, and the false positive rate at 95 percent true positive rate, called FPR95, where lower is better. The object detector was a DeformableDETR and the foundation model was the off the shelf SAM3.
| In distribution | Method | MS-COCO AuROC | MS-COCO FPR95 | OpenImages AuROC | OpenImages FPR95 |
|---|---|---|---|---|---|
| Pascal-VOC | RONIN (prev best) | 92.31 | 25.36 | 93.10 | 18.91 |
| Pascal-VOC | SAM3-O2D2 | 97.52 | 6.56 | 94.62 | 16.52 |
| BDD100K | RONIN (prev best) | 92.90 | 26.03 | 91.90 | 23.33 |
| BDD100K | SAM3-O2D2 | 98.46 | 4.55 | 98.40 | 5.00 |
The method wins on every combination and both metrics, earning an average rank of 1.0. The false positive numbers are the striking part. With Pascal-VOC as the in distribution set and MS-COCO as the unknown set, SAM3-O2D2 cuts the false positive rate from RONIN’s 25.36 down to 6.56, and on the BDD100K driving data the OpenImages false positive rate drops from 23.33 to 5.00. A false positive here means an unknown object wrongly accepted as known, which in a safety context is exactly the error you least want, so shrinking it by three quarters or more is the headline.
Speed is the other win. Because the method prompts SAM3 rather than running a diffusion model, it processes a frame in about 0.1 seconds on an A100 GPU, against 0.48 seconds for even the fastest RONIN configuration, roughly five times faster while being more accurate. The cost scales with R, the number of unique predicted classes, but in practice most frames have very few unique classes, so between 37 and 76 percent of frames need no SAM3 detector call at all, and the overhead can be capped by limiting the method to at most three prompted classes with only a small performance loss.
Why checking at the prediction level matters
The most convincing experiments are the robustness tests, because they explain why this approach beats the diffusion based one rather than just showing that it does. Feature space methods compare abstract representations, which quietly bake in things like where the box is and how the object looks. SAM3-O2D2 compares boxes and class labels directly, which turns out to be far sturdier.
The first test adds noise to the detector’s bounding boxes to simulate sloppy localization. RONIN degrades as the boxes get worse, its false positive rate climbing by about 6.8 points as noise grows. SAM3-O2D2 barely moves, holding around 97.5 area under the curve and 6.6 false positive rate across every noise level tested. Because it only needs the prompted class to match somewhere near the object, a slightly wrong box does not derail it. This kind of trustworthy behavior under imperfect inputs is the same concern that drives work on quantifying how much to trust a model’s answer.
The second test varies object appearance. Both methods do worse in low light and on small objects, which is expected, but the gap is enormous. On small objects, RONIN collapses to 51.09 area under the curve, which is essentially a coin flip, while SAM3-O2D2 still reaches 90.76. On medium objects the split is 74.65 against 94.74. The foundation model’s semantic grounding holds up where feature similarity falls apart, which is the whole argument for operating at the prediction level rather than in feature space.
Honest limitations
The method leans entirely on SAM3, and it inherits that model’s blind spots. The authors are candid that both methods degrade in low light and on small objects, and while SAM3-O2D2 degrades far less, it still drops to 90.76 area under the curve on small objects and 94.85 in low light. If SAM3 cannot reliably find a genuinely present object because it is tiny or dim, the agreement check can misfire, and the hardest cases are near out of distribution objects that look a lot like known classes, where the foundation model’s semantic boundary is fuzziest.
There is a real if modest computational cost. The SAM3 image encoder has to run once per image, adding about 63 milliseconds that cannot be avoided, and each unique prompted class adds a detector call, up to about 116 milliseconds in the worst bounded case of three classes. Capping the method at three classes keeps it fast but costs a little accuracy, though even the capped version still beats the previous best. So the speed advantage is real but comes with a floor set by the foundation model’s own inference time.
The authors also make a careful recommendation about the overlap threshold. On their own datasets a low threshold of 0.1 gives the best numbers, but they recommend a slightly higher 0.2 for deployment, because in more general open world settings where known and unknown objects can appear in the same place, too low a threshold would start accepting poorly localized matches and raise false positives. That is an honest acknowledgment that the best number on a benchmark is not always the safest choice in the field. And as with any method built on a single large model, its ceiling is tied to how good and how broad that model is, which is a moving target as foundation models improve rather than a fixed guarantee.
Why the approach travels
The transferable idea is that a foundation model can audit a specialist model by disagreement. The specialist is fast and narrow and cannot admit ignorance. The generalist is broad and can honestly report absence. By asking the generalist to confirm the specialist’s specific claim, you get a reliability signal for free, without retraining either one. That pattern could check many kinds of narrow models, not just object detectors, anywhere a broad model can verify a specific prediction.
The second lesson is about where to put the check. Comparing predictions, the boxes and labels a system actually outputs, is more robust and more interpretable than comparing internal features, because features entangle everything the model happened to encode. When you can phrase the test in terms of the actual decision, do it there. The reliability of catching what a model does not know is a recurring theme, close to the concerns of online anomaly detection under changing conditions, and prediction level checks travel across all of them.
Conclusion
SAM3-O2D2 is a neat inversion of a hard problem. Rather than trying to teach a detector to know when it does not know, which is against everything its training pushes it to do, the method accepts that the detector will always answer and builds a second opinion around it. It takes the detector’s guess, prompts a foundation model with that exact guess, and treats a failure to confirm as the signal that the object is unknown. The whole thing runs after the detector, needs no retraining, and works with any detector you attach.
The conceptual shift is from measuring confidence to checking agreement. Confidence is exactly the quantity a closed set detector cannot report honestly, so methods that lean on it are building on sand. Agreement between a narrow model’s claim and a broad model’s verification sidesteps that entirely, and because the verification happens at the level of boxes and class names rather than abstract features, it stays interpretable and robust to the messiness of real predictions.
The evidence supports a strong but bounded claim. The method sets a new best on all four dataset combinations and both metrics, cutting false positive rates by large margins, and it does so about five times faster than the previous best because prompting a foundation model is cheaper than running a diffusion model. The robustness tests explain why, comparing a class name to what a foundation model finds survives bad boxes and hard lighting where feature similarity does not.
The honest limitations keep the result in proportion. The method is only as good as SAM3, so small and dim objects and near out of distribution cases remain hard, the foundation model’s inference sets a speed floor, and the safest overlap threshold is not the one that maximizes the benchmark. None of these undercut the contribution, which is a fast, retraining free, interpretable way to catch a detector’s overconfident mistakes.
For anyone deploying object detection where a missed unknown could be dangerous, from autonomous driving to surveillance to industrial inspection, the takeaway is practical. You do not have to retrain your detector to make it safer. You can wrap it with a foundation model that verifies its claims, and you can put that verification at the level of what the detector actually says rather than what it internally represents. As foundation models keep improving, a method that rides on their semantic knowledge rather than fighting a narrow model’s overconfidence is likely to keep getting better on its own.
Reference implementation in Python
The code below is a compact, runnable sketch of the SAM3-O2D2 decision logic, grouping detector predictions by class, matching them against foundation model boxes of the same class by intersection over union, applying the overlap and score thresholds, and labeling each prediction in distribution or out of distribution, plus the unique class counting that bounds the cost. It captures the core algorithm faithfully and stands in for the SAM3 calls with a simple interface, with a smoke test on dummy data.
# sam3_o2d2.py
# Study reference for the SAM3-O2D2 out of distribution decision. The real
# method prompts the SAM3 foundation model. Here a stub stands in for SAM3 so
# the logic runs anywhere. Ends with a smoke test on dummy data.

from collections import defaultdict


def iou(a, b):
    """Intersection over union of two boxes as (x1, y1, x2, y2)."""
    x1 = max(a[0], b[0]); y1 = max(a[1], b[1])
    x2 = min(a[2], b[2]); y2 = min(a[3], b[3])
    inter = max(0, x2 - x1) * max(0, y2 - y1)
    area_a = (a[2] - a[0]) * (a[3] - a[1])
    area_b = (b[2] - b[0]) * (b[3] - b[1])
    union = area_a + area_b - inter
    return inter / union if union > 0 else 0.0


def unique_classes(detections, max_r=3):
    """Unique predicted classes, capped at max_r by keeping the classes whose
    predictions have the highest detector confidence, bounding the cost."""
    best = {}
    for d in detections:
        best[d["cls"]] = max(best.get(d["cls"], 0.0), d["score"])
    ranked = sorted(best, key=best.get, reverse=True)
    return ranked[:max_r]


def sam3_o2d2(detections, sam3_query, iou_thr=0.2, score_thr=0.5, max_r=3):
    """Label each detector prediction ID or OOD by foundation model agreement.
    detections: list of dicts with box (x1,y1,x2,y2), cls, score.
    sam3_query(cls) -> list of (box, score) that SAM3 finds for that class."""
    classes = unique_classes(detections, max_r)          # the R prompted classes
    sam3_boxes = defaultdict(list)
    for c in classes:
        sam3_boxes[c] = sam3_query(c)                    # one SAM3 call per unique class

    labels = []
    for d in detections:
        matched = False
        for box, score in sam3_boxes.get(d["cls"], []):
            if score >= score_thr and iou(d["box"], box) >= iou_thr:
                matched = True                       # SAM3 confirms the class here
                break
        labels.append("ID" if matched else "OOD")     # no confirmation means OOD
    return labels


def smoke_test():
    # detector predicts a real car and a "car" that is actually an elephant
    detections = [
        {"box": (10, 10, 60, 50), "cls": "car", "score": 0.95},
        {"box": (100, 20, 180, 90), "cls": "car", "score": 0.88},
    ]

    def fake_sam3(cls):
        # SAM3 finds a car only at the first location, not the elephant
        if cls == "car":
            return [((11, 9, 59, 51), 0.9)]
        return []

    labels = sam3_o2d2(detections, fake_sam3)
    print(f"labels {labels}")                     # expect ID for the real car, OOD for the elephant
    print(f"prompted classes {unique_classes(detections)}")


if __name__ == "__main__":
    smoke_test()
Running the smoke test labels the genuine car in distribution, because the stand in foundation model confirms a car at that box, and labels the second object, which the detector wrongly called a car, out of distribution, because no car is confirmed there. It also prints the unique prompted classes, showing how the method bounds its cost by the number of distinct labels rather than the number of objects.
Frequently asked questions
What is out of distribution detection?
It is the task of deciding whether an object a detector reports belongs to one of its known training classes, called in distribution, or is something unknown, called out of distribution. It matters because detectors mislabel unfamiliar objects with high confidence rather than flagging them.
How does SAM3-O2D2 decide if an object is unknown?
It takes the detector’s predicted class for an object, prompts the SAM3 foundation model to find that class in the image, and checks whether SAM3 finds a matching object at the same location. If SAM3 finds nothing there, the object is flagged as out of distribution.
Why is prompting a foundation model better than measuring confidence?
A detector trained on a closed set of classes cannot honestly report low confidence on unknown objects, because it always assigns the nearest label. A foundation model has broad semantic knowledge and can genuinely report that a prompted class is not present, which turns disagreement into a reliable signal.
Does the method need retraining?
No. It runs after the object detector, uses an off the shelf foundation model, and needs no retraining, so it can be paired with arbitrary detectors. This makes it practical to add to an existing system as a reliability check.
How much better and faster is it than prior work?
It sets a new best across two in distribution and two out of distribution datasets on both metrics, cutting false positive rates by large margins, and it processes a frame in about 0.1 seconds against 0.48 seconds for the previous best, roughly five times faster.
What are the main limitations?
The method depends on the foundation model, so small and poorly lit objects and near out of distribution cases remain hard, though it degrades far less than prior methods. The foundation model’s inference sets a speed floor, and the authors recommend a slightly conservative overlap threshold for real deployments.
Read the full paper for the complete method and every robustness experiment.
Read the paper on arXiv The SAM3 foundation model