Computer Vision

Computer vision is one of our deepest areas, covering how machines learn to see, segment, and reason about images and video. Articles here range from convolutional and transformer based architectures to dense prediction tasks like detection and segmentation, with regular coverage of medical imaging where reliable vision models carry real clinical weight. The emphasis stays on what makes a method work and where it breaks, backed by the original research.

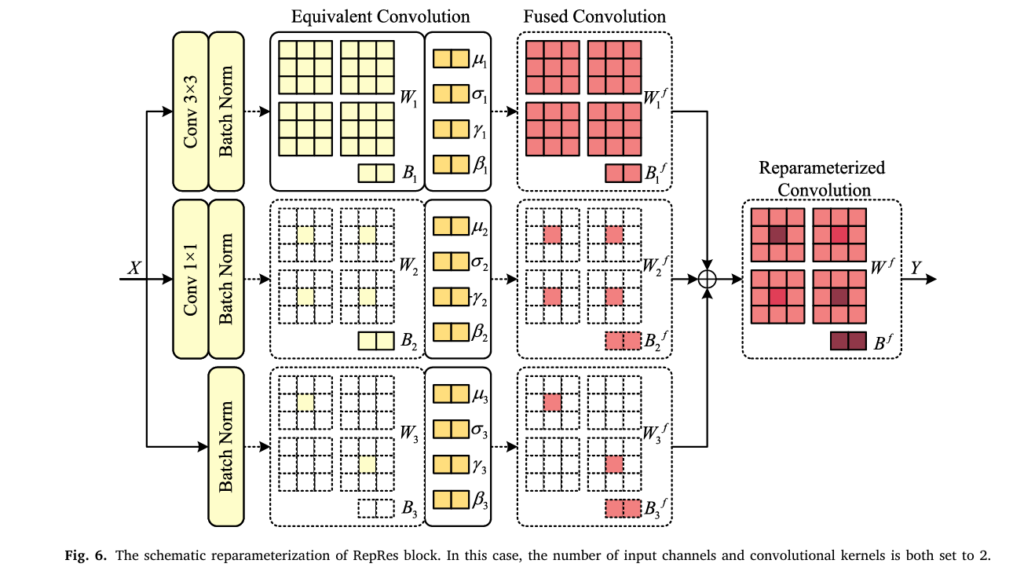
RepVIS-GAN: Nighttime Satellite Visible Image Retrieval from Infrared Data.

RepVIS-GAN: Nighttime Satellite Visible Image Retrieval from Infrared Data

Every night, weather satellites go partially blind — their visible cameras shut off the moment the sun dips below the horizon. Researchers at Ocean University of China built a reparameterized GAN that reads three thermal infrared channels and reconstructs what…

RepVIS-GAN: Nighttime Satellite Visible Image Retrieval from Infrared Data Read More »
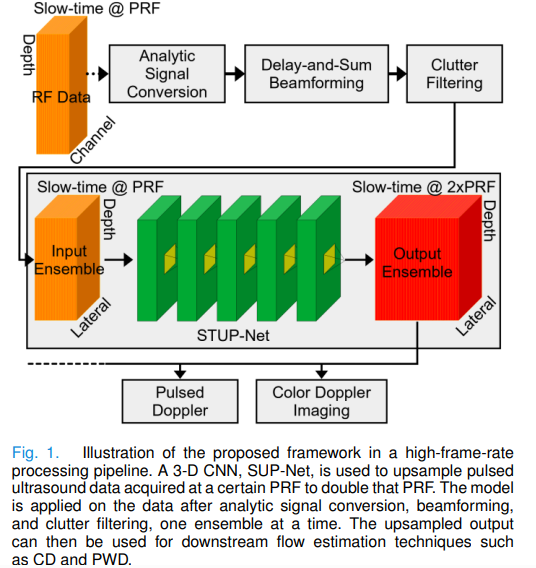
SUP-Net: Deep Learning Fixes Doppler Ultrasound Aliasing by Upsampling the Raw Signal

SUP-Net: Deep Learning Fixes Doppler Ultrasound Aliasing by Upsampling the Raw Signal

University of Waterloo researchers built SUP-Net, a 3D convolutional U-Net that fixes Doppler ultrasound’s fundamental speed limit by upsampling the raw slow-time signal — before any Doppler processing occurs — allowing color Doppler and pulse wave Doppler to work reliably…

SUP-Net: Deep Learning Fixes Doppler Ultrasound Aliasing by Upsampling the Raw Signal Read More »

H2CL: Dual-Geometry Hyperbolic-Euclidean Image-Text Learning for Medical Hierarchical Classification.

H2CL: Dual-Geometry Hyperbolic-Euclidean Image-Text Learning for Medical Hierarchical Classification

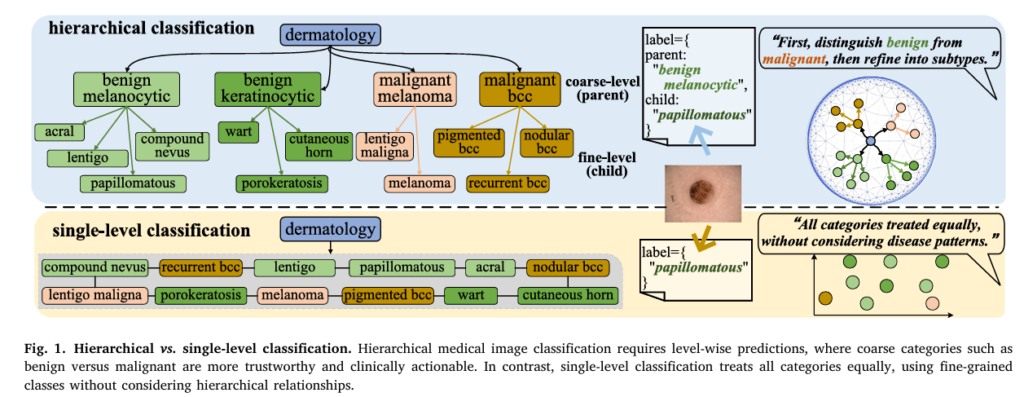
A UNSW Sydney team built H²CL — a dual-geometry image-text framework that simultaneously operates in Euclidean and hyperbolic spaces, combining group contrastive learning with a hyperbolic entailment loss, to classify medical images across clinical taxonomies. The result: 7% accuracy gains…

H2CL: Dual-Geometry Hyperbolic-Euclidean Image-Text Learning for Medical Hierarchical Classification Read More »

GTP: The Graph-Transformer That Reads Whole Slide Pathology Images Like a Pathologist

GTP: The Graph-Transformer That Reads Whole Slide Pathology Images Like a Pathologist

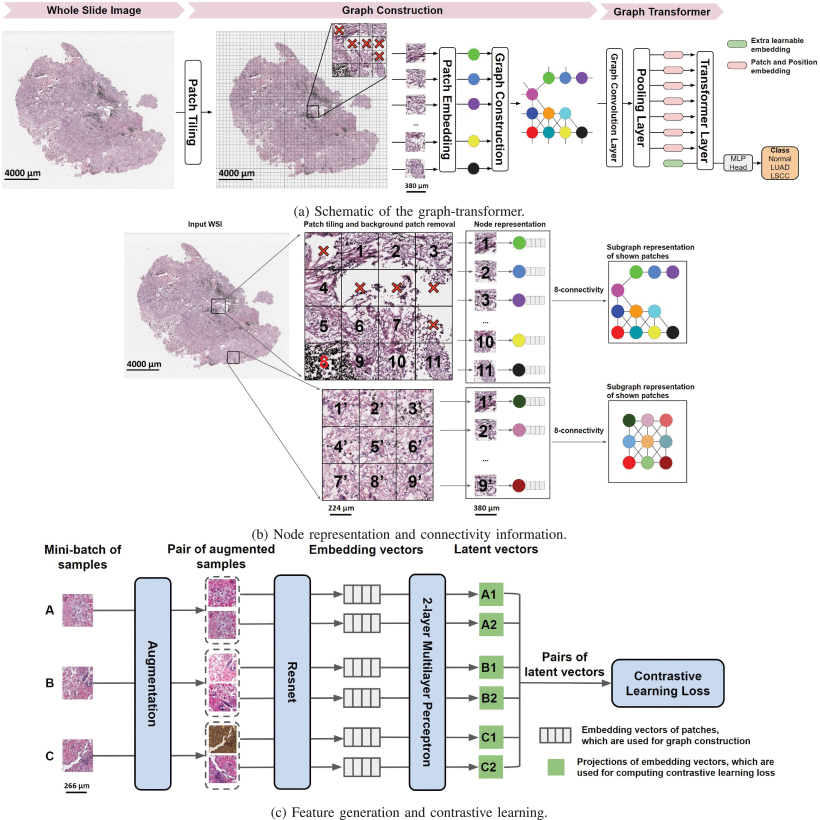
A team at Boston University built GTP — a Graph-Transformer for Pathology that fuses graph convolutional networks with vision transformers to classify gigapixel whole slide images of lung cancer at 91.2% accuracy, plus a novel GraphCAM technique that highlights exactly…

GTP: The Graph-Transformer That Reads Whole Slide Pathology Images Like a Pathologist Read More »

Agentic AI for Personalized Knee Braces: How sEMG, Facial Expressions, and LLMs Combine to Configure Rehab Devices

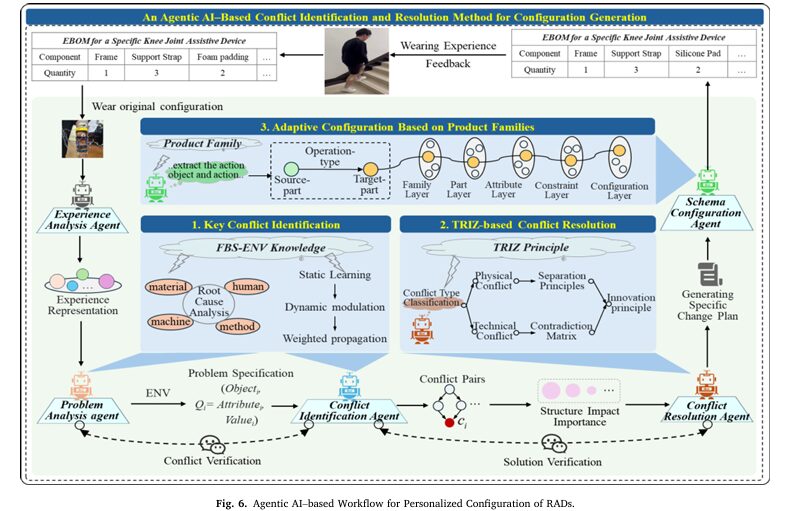
Donghua University’s five-agent AI system cross-checks muscle signals against facial expressions and verbal reports to configure personalized rehabilitation braces — catching cases where patients exaggerate, suppress, or simply can’t articulate their discomfort accurately. It achieves 0.88 parameter accuracy versus 0.13…

Agentic AI for Personalized Knee Braces: How sEMG, Facial Expressions, and LLMs Combine to Configure Rehab Devices Read More »

PARNet: Dual-Encoder Crack Detection with Dynamic Alignment and Residual Fusion.

PARNet: Dual-Encoder Crack Detection with Dynamic Alignment and Residual Fusion

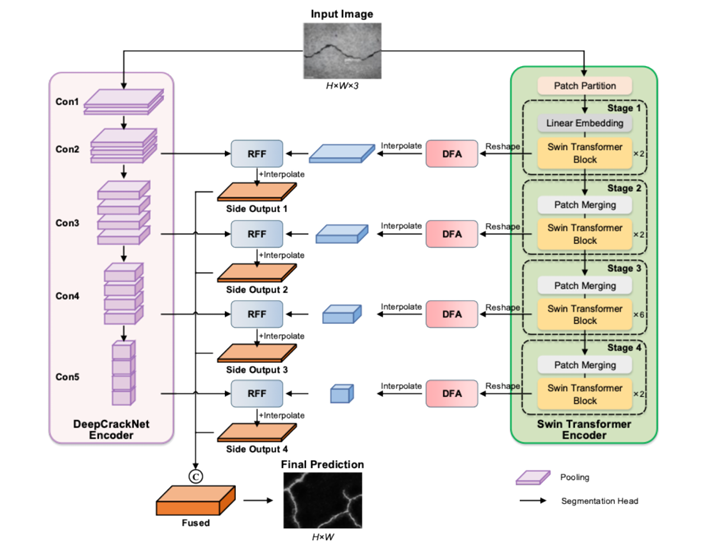
Researchers at Shandong University and Stony Brook University built PARNet, a dual-encoder architecture that runs CNN and Transformer feature extraction in strict parallel, aligns their outputs with dynamic attention, and fuses them through residual connections — achieving the best accuracy,…

PARNet: Dual-Encoder Crack Detection with Dynamic Alignment and Residual Fusion Read More »

MEWS: Semantic Segmentation With Almost No Labels — A Few Pixels Per Class Is All You Need.

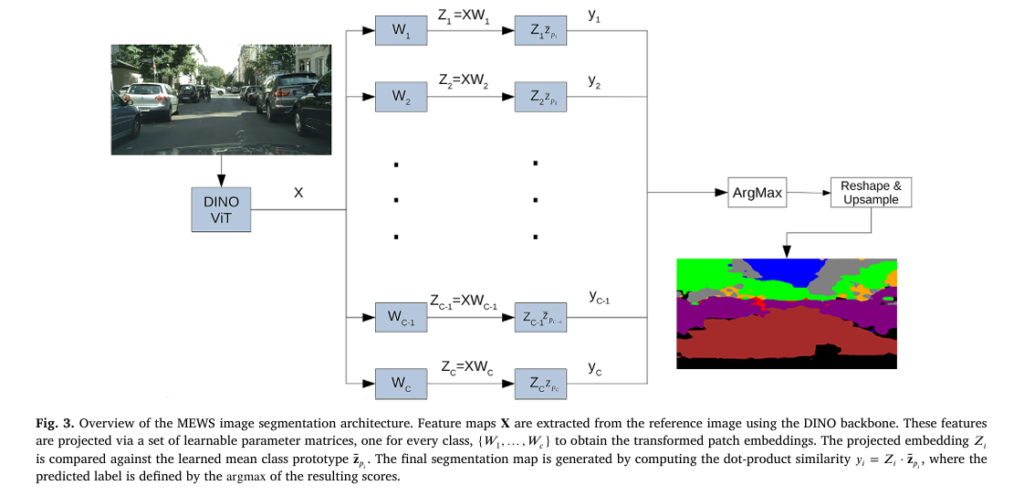
MEWS: Semantic Segmentation With Almost No Labels — A Few Pixels Per Class Is All You Need

Researchers at Aristotle University of Thessaloniki built a segmentation system that achieves 63.27% mIoU on Cityscapes — virtually matching fully supervised methods — using only sparse pixel annotations on a handful of training images. No dense masks. No text prompts.…

MEWS: Semantic Segmentation With Almost No Labels — A Few Pixels Per Class Is All You Need Read More »

Mask-CDKD: Source-Free Knowledge Distillation from SAM for Satellite Onboard Land Cover Mapping.

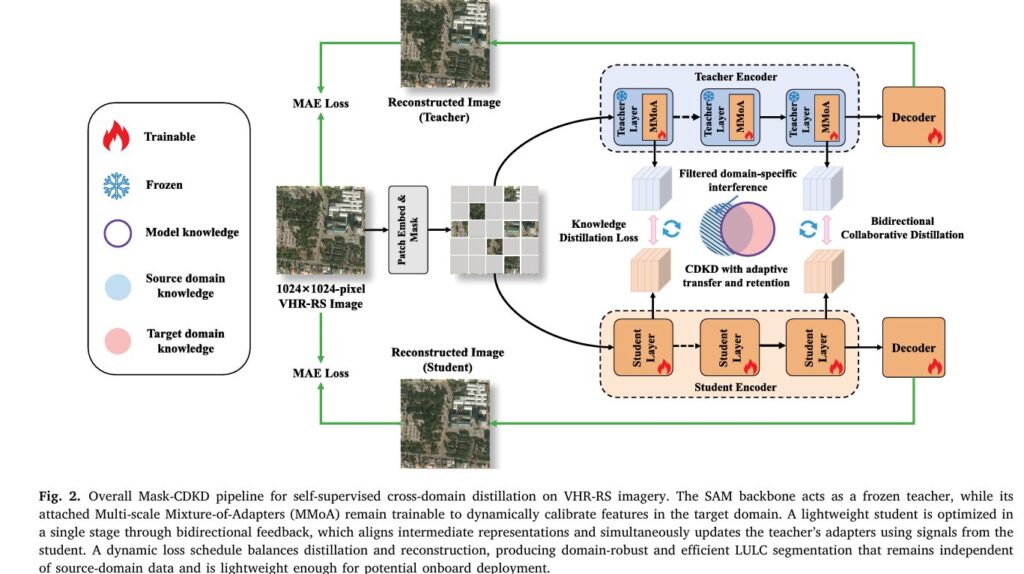
Mask-CDKD: Source-Free Knowledge Distillation from SAM for Satellite Onboard Land Cover Mapping

Researchers at Wuhan University built a distillation framework that transfers SAM’s powerful visual priors to a compact student network using only unlabeled satellite imagery — no source data, no labels — and deployed the result live on an edge AI…

Mask-CDKD: Source-Free Knowledge Distillation from SAM for Satellite Onboard Land Cover Mapping Read More »

Causal Graph Neural Networks for Wildfire Forecasting Across Geographic Shifts.

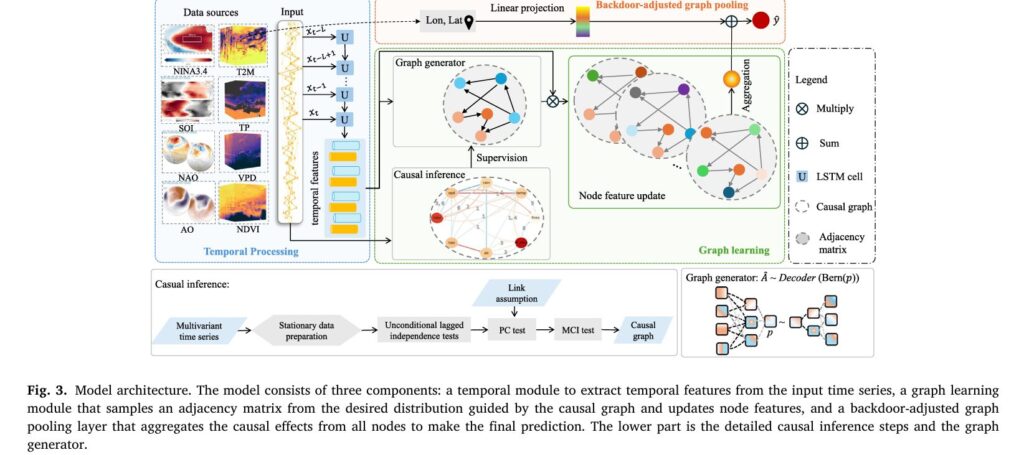
Causal Graph Neural Networks for Wildfire Forecasting Across Geographic Shifts

Shan Zhao, Ioannis Prapas, and their colleagues at TU Munich and the National Observatory of Athens built a causally informed graph neural network that forecasts burned areas with 64% lower prediction variance and outperforms correlation-based baselines by 2–5 AUROC points…

Causal Graph Neural Networks for Wildfire Forecasting Across Geographic Shifts Read More »

Stereo 3D Tracker: Real-Time 3D Point Tracking in Fisheye Stereo Photogrammetry.

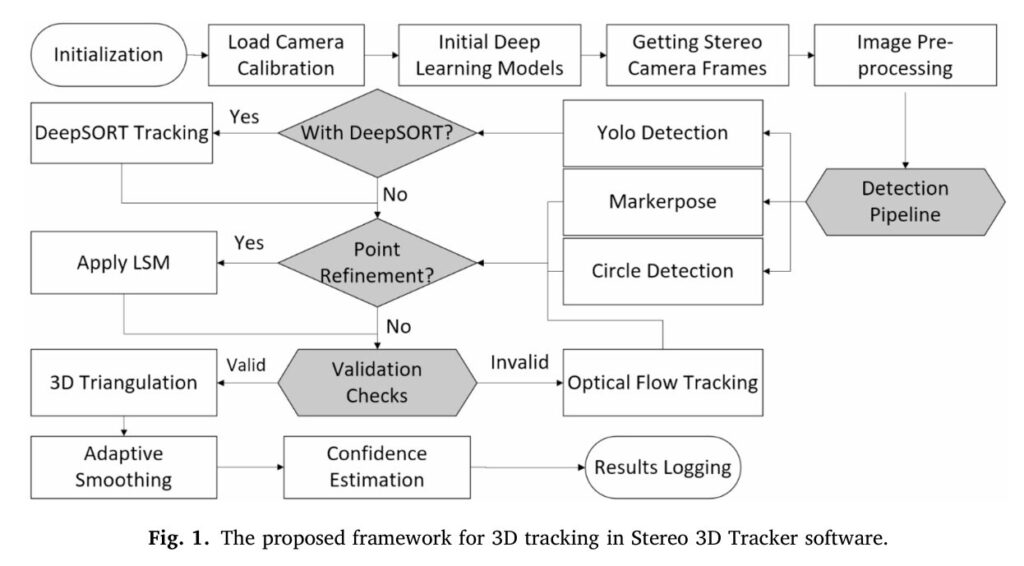
Stereo 3D Tracker: Real-Time 3D Point Tracking in Fisheye Stereo Photogrammetry

A researcher at K.N. Toosi University built a hybrid classical-plus-deep-learning framework that tracks 3D points in fisheye stereo imagery with 0.03mm precision — comparable to VICON and OptiTrack systems costing $10,000–$100,000 — running at 60 FPS capture on a Jetson…

Stereo 3D Tracker: Real-Time 3D Point Tracking in Fisheye Stereo Photogrammetry Read More »