Vision Transformers & Attention

Attention mechanisms, vision transformers, and the architectures replacing convolutions across vision tasks. We unpack how attention is used, misused, and reinvented in current research, from efficient attention branches to Mamba-style state space models.

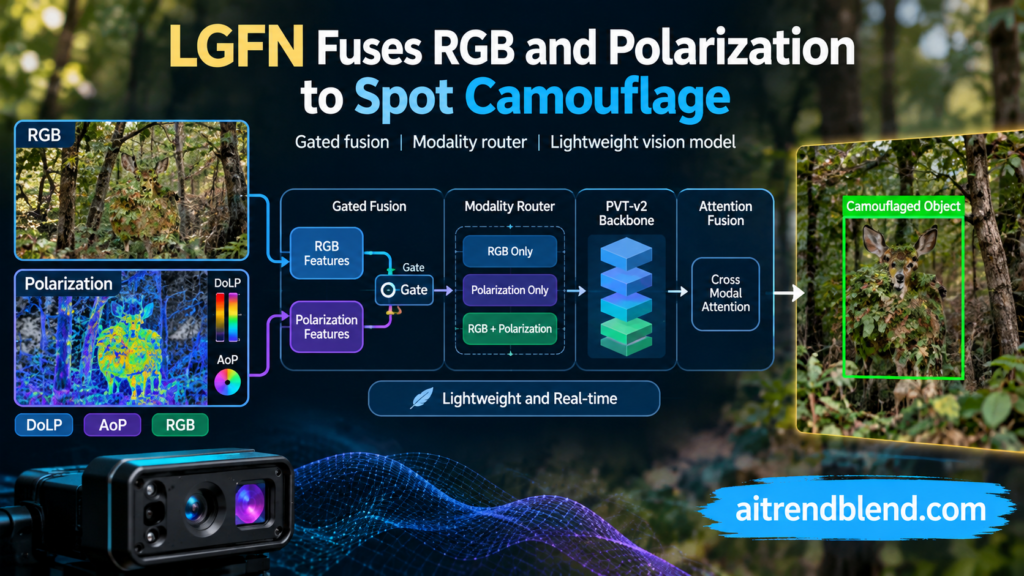
LGFN Fuses RGB and Polarization to Spot Camouflage

LGFN Fuses RGB and Polarization to Spot Camouflage

Analysis by the aitrendblend editorial team  •  Vision transformers and attention  •  Updated September 2026 camouflaged object detection polarization imaging RGB polarization fusion modality availability lightweight vision model PVT-v2 backbone LGFN routes an image through an RGB only path or a multimodal path depending on which polarization sensors are available, then folds coordinated polarization evidence […]

LGFN Fuses RGB and Polarization to Spot Camouflage Read More »
XPert: A Transformer That Predicts How Drugs Change Cells

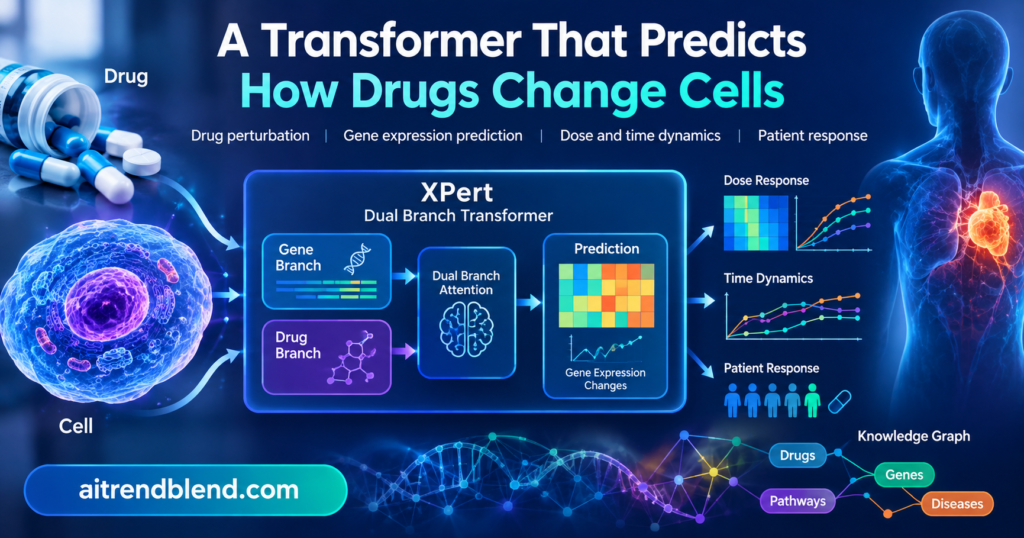
XPert: A Transformer That Predicts How Drugs Change Cells

Analysis by the aitrendblend editorial team  ·  AI for healthcare and drug discovery  ·  Explains published research, not medical advice  ·  Reading time about 18 minutes Drug Perturbation Transformer Gene Expression XPert Drug Discovery Precision Medicine XPert reads a cell’s baseline gene activity and a drug’s chemical and biological identity, then predicts how the drug

XPert: A Transformer That Predicts How Drugs Change Cells Read More »

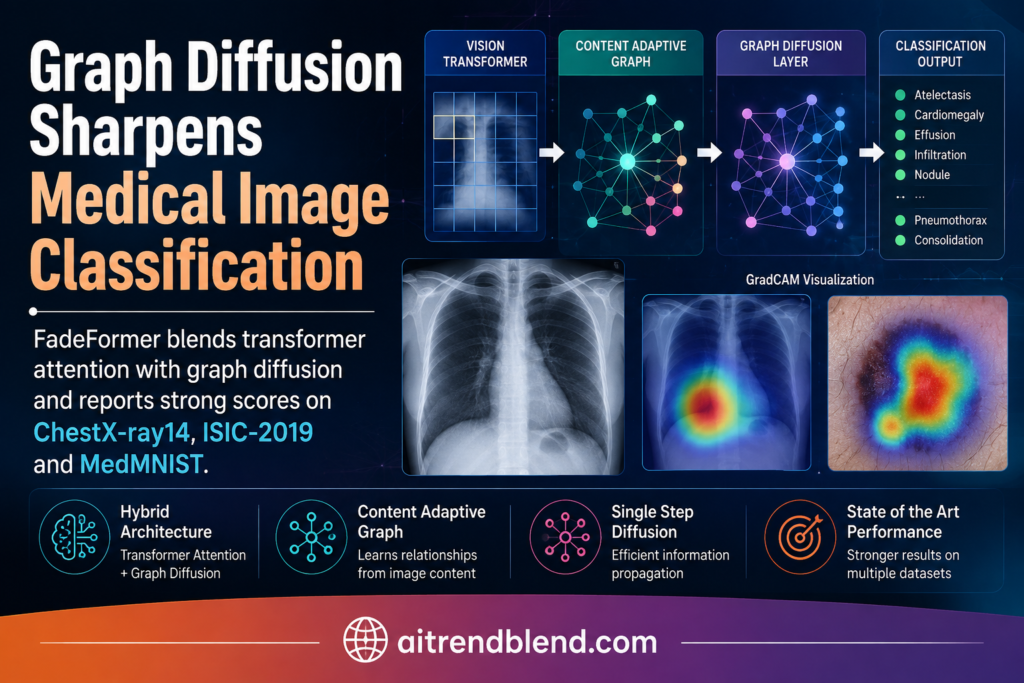
FadeFormer: Graph Diffusion Sharpens Medical Image Classification

FadeFormer: Graph Diffusion Sharpens Medical Image Classification

Analysis by the aitrendblend editorial team / Pillar 1, Medical Imaging and Diagnostic AI Vision Transformers Graph Diffusion Chest X-Ray Classification Skin Lesion Classification MedMNIST A FadeFormer layer fuses standard self attention with a learned graph diffusion process before every feed forward block. A radiologist scanning a chest film is not looking at one pixel

FadeFormer: Graph Diffusion Sharpens Medical Image Classification Read More »

The Four Secrets Behind Video Vision Transformers Explained

The Four Secrets Behind Video Vision Transformers Explained

Analysis by the aitrendblend editorial team · Computer Vision · Reading time about 14 minutes video vision transformer ViViT patch division token selection position encoding attention mechanism Every video transformer answers the same four questions in a different order, and this review tries to catalog every answer given so far. Take any video clip, a

The Four Secrets Behind Video Vision Transformers Explained Read More »

How Mamba State Space Models Are Reshaping Multimodal AI Fusion

How Mamba State Space Models Are Reshaping Multimodal AI Fusion

Analysis by the aitrendblend editorial team · Pillar 4, vision transformers and attention · 13 minute read mamba architecture state space models multimodal fusion cross modal attention remote sensing AI uncertainty aware learning A state space block does not look at every token pair like attention does. It carries a compressed running memory forward, one

How Mamba State Space Models Are Reshaping Multimodal AI Fusion Read More »

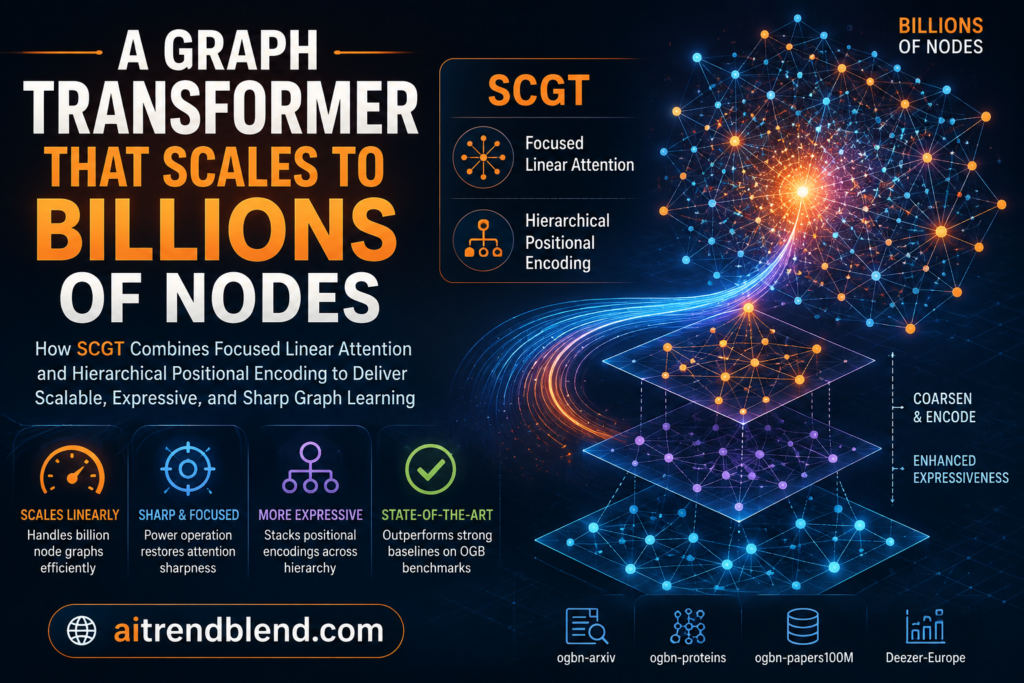
A Graph Transformer That Scales to Billions of Nodes

A Graph Transformer That Scales to Billions of Nodes

Graph Neural Networks  ·  Analysis by the aitrendblend editorial team  ·  15 min read graph transformer linear attention positional encoding node classification scalability SCGT keeps attention sharp with a power operation while a coarsened graph hierarchy feeds it positional encodings at several scales. Transformers rewrote what was possible in language and vision, so pointing them

A Graph Transformer That Scales to Billions of Nodes Read More »

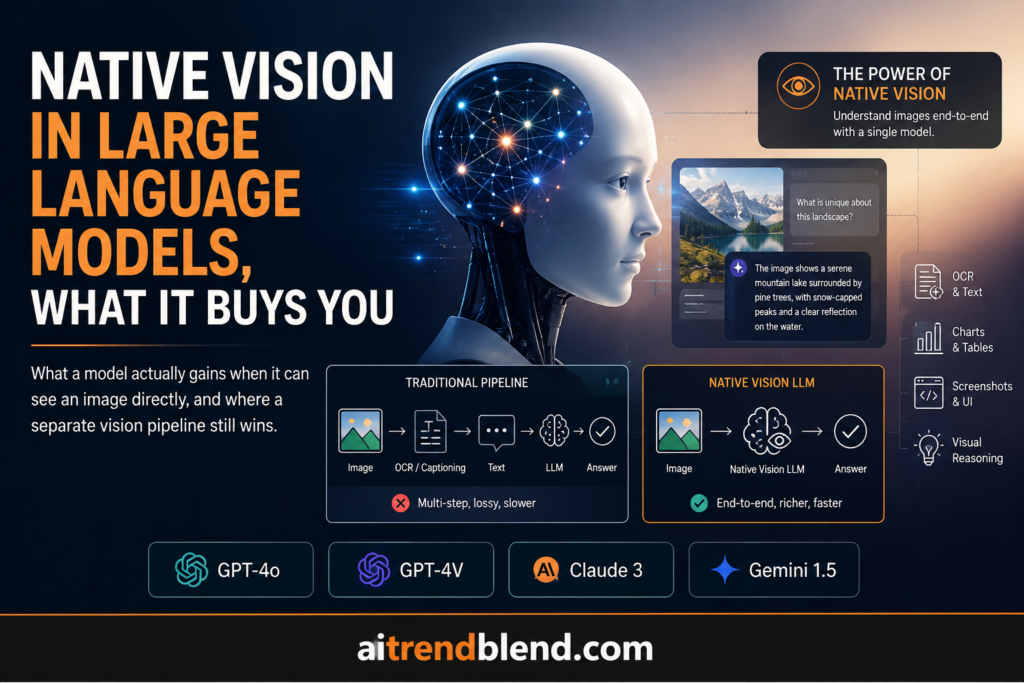
Native Vision In Large Language Models, What It Buys You

Native Vision In Large Language Models, What It Buys You

Analysis by the aitrendblend editorial team · Vision Transformers and Attention Multimodal Models Vision Transformers Image Understanding OCR Practical AI Native vision means the model reads the pixels itself. What that actually earns you depends heavily on the task. For years the only way to get a language model to react to an image was

Native Vision In Large Language Models, What It Buys You Read More »

Why Deepfake Detectors Need Their Own Vision Transformer

Why Deepfake Detectors Need Their Own Vision Transformer

Vision transformers and attention · Analysis by the aitrendblend editorial team · 10 min read Vision Transformers Deepfake Detection Self Supervised Learning IEEE TPAMI PyTorch Owner note, upload the feature image to the path above or change the src attribute before publishing. Somewhere on a trust and safety team, someone is staring at a video

Why Deepfake Detectors Need Their Own Vision Transformer Read More »

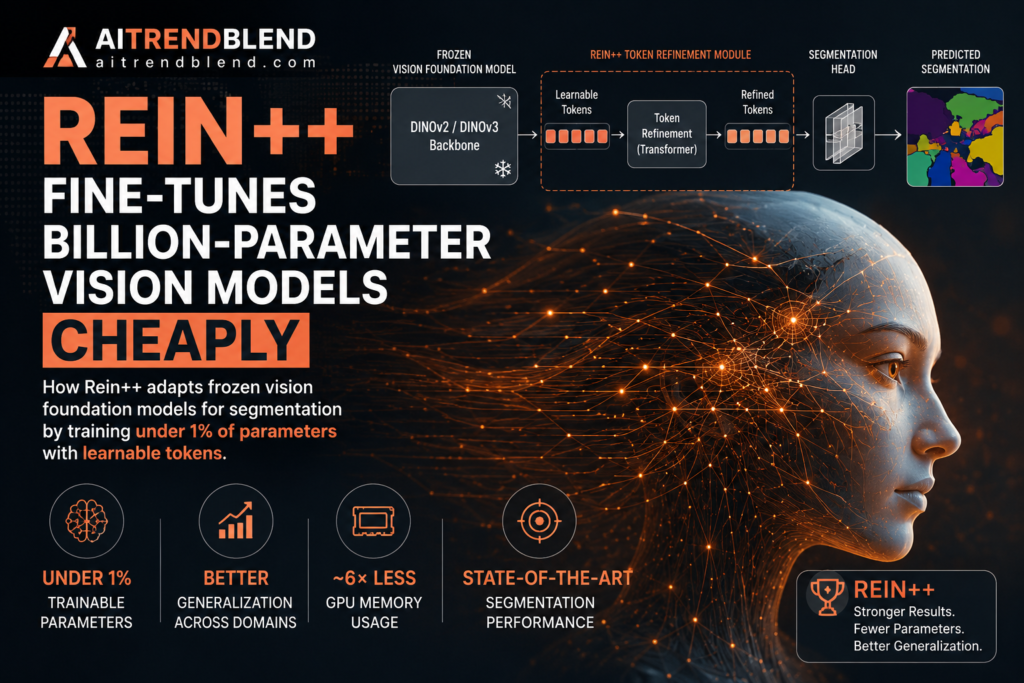
Rein++ Fine-Tunes Billion-Parameter Vision Models Cheaply

Rein++ Fine-Tunes Billion-Parameter Vision Models Cheaply

Analysis by the aitrendblend editorial team  |  Vision transformers and attention  |  15 minute read vision foundation models parameter efficient fine tuning domain generalization domain adaptation semantic segmentation Rein++ leaves a giant vision model frozen and steers it for segmentation with a thin set of learnable tokens. A vision foundation model trained on a hundred

Rein++ Fine-Tunes Billion-Parameter Vision Models Cheaply Read More »

Teaching AI Online Point Tracking Without Looking Ahead

Teaching AI Online Point Tracking Without Looking Ahead

Vision Transformers and Attention · Video Understanding · 13 min read Point Tracking Online Video Models Transformer Memory Occlusion Handling Track-On2 Track-On2 · Online Point Tracking With MemoryNo future frames, no full video buffer, just a compact memory of what each point looked like a moment ago. Tap a single point on a video, the

Teaching AI Online Point Tracking Without Looking Ahead Read More »