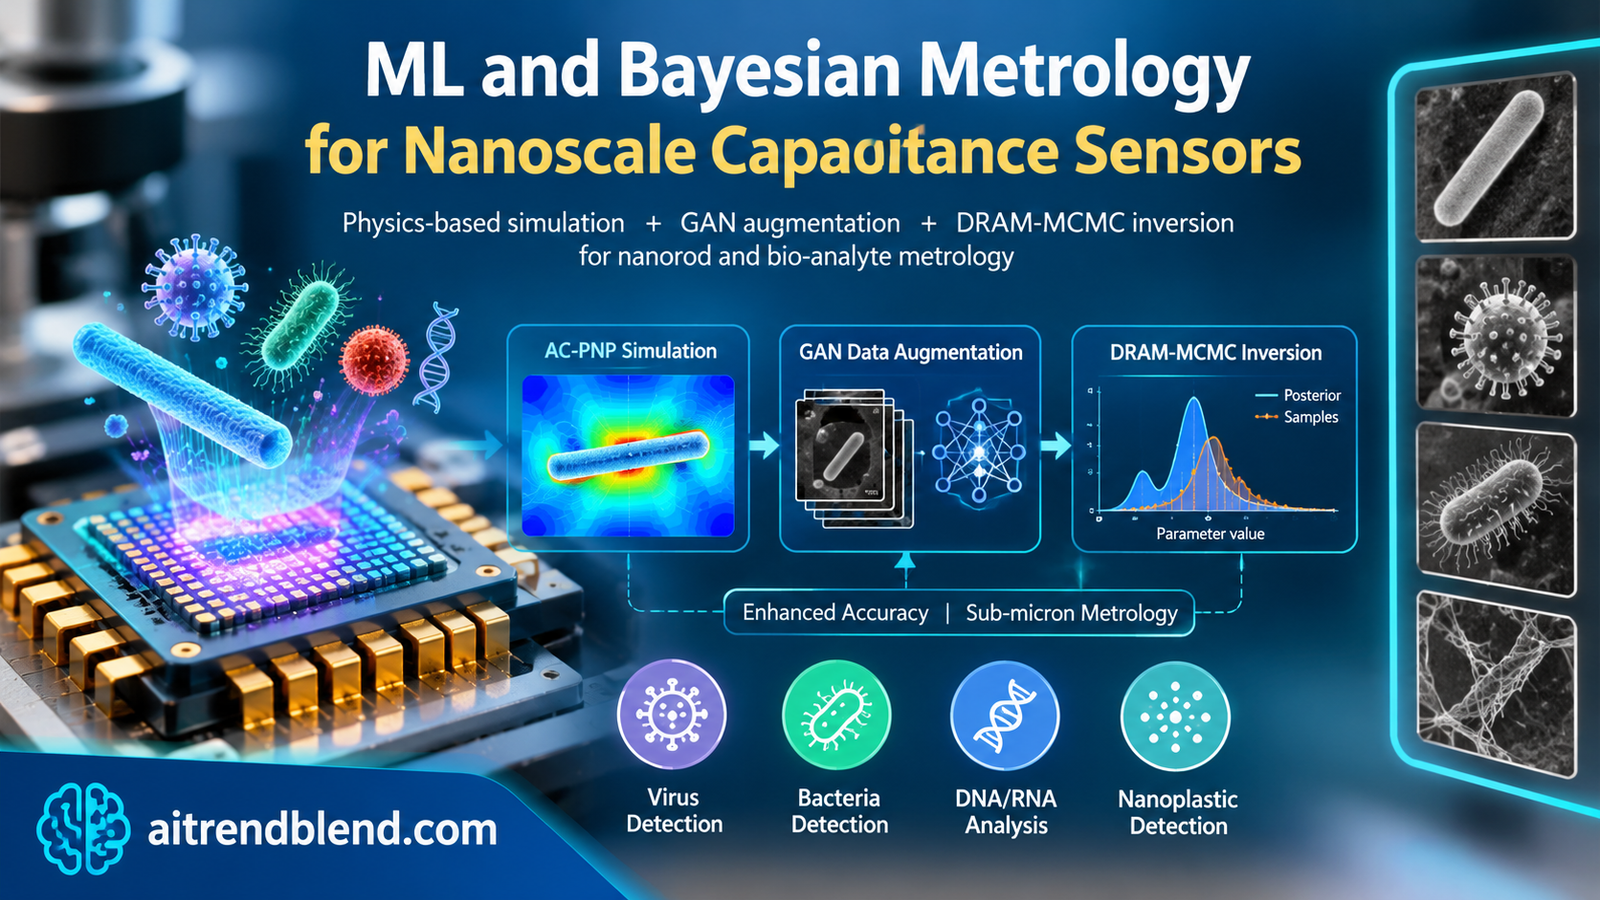
Inside a microfluidic chamber sealed atop a 90-nanometer CMOS biochip, an elongated nanoscale particle—a 300-nanometer nanoplastic fiber, a rod-shaped bacteriophage, or a double-stranded nucleic acid bundle—drifts in a 100-millimolar saline solution just 40 nanometers above a grid of gold-copper nanoelectrodes. As the particle enters the alternating electric field of the array, it perturbs the local capacitance by a few attoFarads across a \(7 \times 7\) pixel neighborhood. Inferring the particle’s exact length, dielectric permittivity, and in-plane orientation angle from that tiny multispectral shadow requires inverting the coupled three-dimensional Poisson-Nernst-Planck partial differential equations, a task that takes over 30 minutes of 104-core CPU compute per single forward evaluation. Ehsan Khodadadian, Daniele Goldoni, Jacopo Nicolini, Amirreza Khodadadian, Clemens Heitzinger, and Luca Selmi at TU Wien, the University of Modena and Reggio Emilia, and Keele University solved this bottleneck by coupling physics-based simulations with a triple-augmented neural network surrogate and Delayed Rejection Adaptive Metropolis (DRAM) Bayesian inversion, cutting forward evaluation to milliseconds and recovering nanoscale geometry within a few nanometers.
Key Research Takeaways
- The sensing benchmark is a 90 nm CMOS array of \(256 \times 256\) planar gold-copper (AuCu) nanoelectrodes (\(90\text{ nm}\) radius, \(0.6 \times 0.89\,\mu\text{m}\) pitch, \(2.5 \times 10^6\text{ electrodes/mm}^2\)) operating at zero DC bias between 2 MHz and 70 MHz with a \(\approx 2\text{ aF}\) noise floor.
- A four-layer fully connected Deep Neural Network (128, 64, 32, and 16 neurons) maps four physical inputs—analyte length \(L \in [200, 1000]\text{ nm}\), in-plane rotation angle \(\phi \in [0^\circ, 165^\circ]\), relative permittivity \(\epsilon_r \in [1, 5]\), and frequency \(f \in [2, 70]\text{ MHz}\)—to 49 output capacitance steps (\(\Delta C\) across a \(7 \times 7\) electrode map).
- Doubling the 8,550 ENBIOS Control-Volume Finite Element (CV-FEM) simulations with 8,550 augmented samples (2,850 from 5% Gaussian input perturbations, 2,850 from uniform random resampling, and 2,850 from a 3-layer feedforward GAN) plus a variance-weighted MSE loss slashes relative test error more than sevenfold, from \(0.817 \pm 0.0766\) down to \(0.108 \pm 0.0147\).
- Trained on 2 to 70 MHz, the neural surrogate extrapolates up to 150 MHz (more than \(2\times\) the maximum training frequency) while keeping array-averaged relative capacitance error at or below 10.14 percent (\(0.0221\) at 80 MHz and \(0.1014\) at 150 MHz).
- Plugging the neural surrogate into a 1,000-iteration Delayed Rejection Adaptive Metropolis (DRAM) MCMC loop recovers true nanorod length, permittivity, and orientation across four blind test cases withinnarrow 95% confidence intervals (for example, estimating a 700 nm nanorod at \(700.46\text{ nm}\) with a 95% CI of \([700.10, 700.81]\text{ nm}\)).
This article analyzes peer-reviewed computational biosensing and nanoelectronics research published in Engineering Applications of Artificial Intelligence and is provided strictly for informational and educational purposes. It does not constitute medical advice, clinical diagnostic validation, pathogen screening guidance, or regulatory environmental safety testing. Clinical point-of-care diagnostics, viral or bacterial assays, and regulatory water quality monitoring must always be conducted using certified laboratory instrumentation and interpreted by qualified healthcare or environmental professionals.
Why Elongated Nanoscale Analytes Push CMOS Biosensors to Their Resolution Limits
The problem runs deeper than it first appears. Across environmental toxicology and molecular diagnostics, the targets that matter most are rarely perfect spheres. Airborne and waterborne nanoplastics and microplastics shed from synthetic textiles appear as high-aspect-ratio rods, fibers, and fibrils whose cellular oxidative stress mechanisms remain an urgent public health concern. In clinical and point-of-care microbiology, filamentous bacteriophages, rod-shaped bacteria such as Escherichia coli, proteins, and strands of DNA, RNA, and Peptide Nucleic Acid (PNA) behave electrically as elongated dielectric cylinders with radii of tens of nanometers and lengths spanning 200 to 1,000 nanometers.
When you try to detect and size those individual nanoscale cylinders label-free inside a physiological salt solution (such as 100 mM sodium chloride, \(\text{NaCl}\)), two physical barriers immediately collide. First, at low alternating current (AC) frequencies, mobile \(\text{Na}^+\) and \(\text{Cl}^-\) ions in the electrolyte swarm around the charged electrode surface to form an electrical double layer. This ionic cloud—governed by the Debye screening length, which is less than one nanometer in 100 mM \(\text{NaCl}\)—shields the electric field from penetrating into the fluid chamber, blinding the sensor to any analyte floating tens of nanometers above the surface.
Second, even when you drive the excitation frequency into the megahertz regime (\(f > 1\text{ MHz}\)) to outrun ionic relaxation and punch through Debye screening, the capacitance step \(\Delta C(f) = C_{\text{with-analyte}} – C_{\text{without-analyte}}\) induced by a single 50-nanometer-radius nanorod is minuscule: on the order of 1 zeptoFarad (\(10^{-21}\text{ F}\)) to a few attoFarads (\(10^{-18}\text{ F}\)) up to tenths of a femtoFarad (\(10^{-15}\text{ F}\)).
To resolve those attoFarad steps with sub-micron spatial precision, the authors utilize the second-generation 90 nm low-power CMOS nanocapacitor array chip developed by Widdershoven et al. at NXP Semiconductors. Packaged beneath a polydimethylsiloxane (PDMS) microfluidic seal ring, the chip packs \(256 \times 256\) planar gold-copper (\(\text{AuCu}\)) circular nanoelectrodes of \(90\text{ nm}\) radius (\(\approx 0.025\,\mu\text{m}^2\) area) at a spatial pitch of \(0.6\,\mu\text{m}\) along \(x\) and \(0.89\,\mu\text{m}\) along \(y\), achieving an unmatched density of \(2.5 \times 10^6\text{ electrodes/mm}^2\). Using Charge-Based Capacitance Measurement (CBCM) at zero DC bias from 2 MHz to 70 MHz, correlated double sampling, shot-noise suppression, and column-by-column calibration, the hardware achieves an experimental noise floor of roughly 2 attoFarads (\(\approx 2\text{ aF}\)). Yet hardware sensitivity is only half the battle: how do you translate a blurry \(7 \times 7\) pixel multispectral capacitance map back into the exact length \(L\), material permittivity \(\epsilon_r\), and rotation angle \(\phi\) of the nanorod?
The Physics Bottleneck: Solving the Coupled AC-PNP Equations in 3D
To understand why inverting a capacitance image is so computationally punishing, let us look at the partial differential equations governing the electrolyte-analyte interface in Section 3 of the Engineering Applications of Artificial Intelligence paper. Because the CMOS sensor operates at zero DC bias with nearly ideally polarizable \(\text{AuCu}\) electrodes, the static equilibrium potential \(V_0(\vec{r})\) and the equilibrium concentration \(n_{0,m}(\vec{r})\) of the \(m\)-th mobile ion species across the 3D domain \(\vec{r}\) obey the nonlinear Poisson-Boltzmann Equation (PBE, Equations 1 and 2):
Here, \(\epsilon(\vec{r})\) is the spatially varying dielectric permittivity (\(80\,\epsilon_0\) in the 100 mM \(\text{NaCl}\) electrolyte and \(\epsilon_r \epsilon_0\) inside the dielectric nanorod), \(\rho_{0f}\) is the immobilized fixed charge density, \(Z_m\) and \(n_{0,m}^\infty\) are the signed valence and bulk concentration of ion species \(m\), \(q\) is the elementary charge, \(k_B\) is the Boltzmann constant, \(T = 22^\circ\text{C}\) (\(295.15\text{ K}\)) is the absolute temperature, and \(V_{\text{ref}}\) is the bulk reference potential.
When the sensor applies a small-signal time-harmonic switching perturbation \(\tilde{V}_{AC}\) (\(\approx 300\text{ mV}\)) at angular frequency \(\omega = 2\pi f\), the electrostatic potential phasor \(\tilde{V}(\vec{r})\) and the linearized ionic quasi-Fermi pseudo-potentials \(\tilde{\phi}_m(\vec{r})\) obey the coupled AC Poisson and linearized Drift-Diffusion (AC-PNP) system (Equations 3 and 6):
Integrating the normal component of the total complex AC current density \(\vec{\tilde{J}} = \vec{\tilde{J}}_D + \sum_m \vec{\tilde{J}}_m\) (the sum of displacement current and ionic conduction current, Equation 5) over the working electrode surface area \(A_{el}\) yields the complex AC current \(\tilde{I}\), the electrode admittance \(Y_A = \tilde{I} / \tilde{V}_{AC}\), and the effective measured capacitance \(C_{\text{eff}}\) (Equations 4 and 5):
To solve Equations 1 through 6 across a \(7 \times 7\) nanoelectrode domain containing a cylindrical nanorod of radius \(R = 50\text{ nm}\) hovering at center-of-mass height \(d_z = 40\text{ nm}\) (with \(d_x = d_y = 0\text{ nm}\), vertical tilt \(\theta = 0^\circ\), and conductivity \(\sigma = 0\text{ S/m}\)), the authors use ENBIOS, an in-house 3D simulator combining the Control Volume method (for strict local charge and flux conservation) with the Finite Element Method (CV-FEM) on Netgen tetrahedral meshes. Because each 3D mesh contains \(\mathcal{N}_{dof} = 141,110 \pm 29,902\) tetrahedral elements (\(26,874 \pm 5,091\) nodes) and must be solved row-by-row across 10 frequencies from 2 MHz to 70 MHz, a single parameter configuration takes over 30 minutes of CPU time (ranging from 15 to 46 minutes in Figure 2) even when parallelized across a 104-core Intel Xeon Gold 6338 server with 512 GB RAM. Running a 1,000-step Markov Chain Monte Carlo inversion directly on ENBIOS would take more than 500 hours (three weeks) to characterize a single nanorod.
Inside the Supervised Machine Learning Surrogate and Triple Data Augmentation
To replace 30-minute 3D PDE solves with millisecond predictions—a surrogate modeling strategy that parallels our recent coverage of isogeometric shell mechanics—Khodadadian et al. built a physics-informed supervised learning pipeline in PyTorch (Figure 3). First, ENBIOS was run across a structured grid of 10 linearly spaced lengths \(L \in [200, 1000]\text{ nm}\), 19 linearly spaced in-plane rotation angles \(\phi \in [0^\circ, 165^\circ]\), 9 linearly spaced relative permittivities \(\epsilon_r \in [1, 5]\), and 10 logarithmically spaced frequencies \(f \in [2, 70]\text{ MHz}\), producing a baseline dataset of 8,550 simulated \(7 \times 7\) capacitance maps (where each sample maps 4 input features to 49 output labels).
Training a 4-hidden-layer fully connected Deep Neural Network (`4 -> 128 -> 64 -> 32 -> 16 -> 49`) directly on the raw simulations without specialized preprocessing and augmentation fails badly, leaving an array-averaged relative test error of \(0.817 \pm 0.0766\) (over 81 percent error, Figure 5 left). To conquer the steep multi-decade dynamic range of \(\Delta C(f)\), the authors engineered a five-stage training pipeline:
- Physics-Guided Frequency Segmentation at 10 MHz: In 100 mM \(\text{NaCl}\), the sensor’s lower resistive cut-off sits near \(1.7\text{ MHz}\) while the electrolyte dielectric relaxation frequency (\(\sigma_{el} / \epsilon_{el}\)) sits near \(300\text{ MHz}\). Below \(10\text{ MHz}\), double-layer polarization dominates and \(\Delta C\) is highly sensitive to local electrode-analyte proximity; above \(10\text{ MHz}\), Debye screening weakens and the AC field probes bulk analyte volume uniformly (Figure 8). Partitioning the dataset at the \(10\text{ MHz}\) midpoint into low-frequency (\(2\text{–}10\text{ MHz}\)) and high-frequency (\(10\text{–}70\text{ MHz}\)) regimes allows separate `StandardScaler` zero-mean, unit-variance normalization (\(x_{\text{scaled}} = (x – \mu)/\sigma\)) tailored to each physical regime.
- Augmentation Branch 1 — 5% Local Gaussian Perturbations (2,850 Samples): Because the AC-PNP forward operator is smooth and locally continuous with respect to \((L, \phi, \epsilon_r)\), adding zero-mean Gaussian perturbations of magnitude \(\sigma_n = 5\%\) of each parameter’s range while retaining the exact PDE capacitance labels teaches the network local invariance against minor sensor and environmental fluctuations.
- Augmentation Branch 2 — Uniform Random Resampling (2,850 Samples): New input vectors are drawn uniformly across the min-max bounds of \((L, \phi, \epsilon_r, f)\) with labels interpolated from the nearest ENBIOS grid neighbors.
- Augmentation Branch 3 — Feedforward Generative Adversarial Network (2,850 Samples): A lightweight 3-layer fully connected ReLU Generator maps a 3D standard normal latent vector \(z \sim \mathcal{N}(0, I)\) into realistic synthetic parameter triplets \((L, \phi, \epsilon_r)\) pitted against a 3-layer ReLU Discriminator trained via minimax Adam optimization (monitored via discriminator accuracy and Wasserstein distance), with physical capacitance labels assigned by a pre-trained forward surrogate.
- Epoch Shuffling and Variance-Weighted Combined Loss Function: Combining all three branches doubles the dataset from 8,550 to 17,100 samples. To prevent electrodes with small variance from distorting gradients while prioritizing highly active central pixels, the authors train with a combined loss function (Equations 7 and 8) that pairs standard global MSE with a variance-weighted per-electrode loss across all \(n = 49\) pixels:
Here, \(\sigma_i\) is the standard deviation of the unnormalized capacitance at pixel \(i \in \{1, \dots, 49\}\) across the training set, ensuring that central working electrodes directly beneath the nanorod receive proportional gradient emphasis.
Enabling the triple data augmentation pipeline (Perturbations + Uniform Resampling + GAN, a strategy reminiscent of generative low-data augmentation) and the variance-weighted loss slashes the 49-pixel mean relative capacitance error by \(7.5\times\), dropping from \(0.817 \pm 0.0766\) down to \(0.108 \pm 0.0147\) across the full 2–70 MHz band while executing all 10 frequencies in just 315 seconds on a laptop Intel Core i7-13700H CPU.
DRAM-MCMC Bayesian Inversion for Nanoscale Metrology
With a fast, accurate forward surrogate \(Q(x, z)\) in hand, the inverse problem—recovering the unknown analyte parameter vector \(z = (\epsilon_r, L, \phi)\) from a noisy measured \(7 \times 7\) capacitance observation \(\mathcal{M} = \text{obs}\)—is cast in a rigorous Bayesian framework (Section 5). Assuming additive zero-mean Gaussian measurement noise \(\varepsilon \sim \mathcal{N}(0, \sigma^2 I)\) of variance \(\sigma^2\), the observational model, Bayes’ theorem posterior density \(\pi(z | \mathcal{M})\), Gaussian likelihood \(L(z, \sigma^2 | \mathcal{M})\), and squared misfit functional \(\mathcal{E}_{\mathcal{M}}\) follow Equations 9, 11, 12, and 13:
Standard Metropolis-Hastings Markov Chain Monte Carlo (MCMC) often gets stuck when sampling correlated, nonlinear 3D parameter spaces like \((\epsilon_r, L, \phi)\): if the proposal step size is too large, nearly every move is rejected; if it is too small, the chain takes tens of thousands of steps to mix. Khodadadian et al. overcome this by deploying the Delayed Rejection Adaptive Metropolis (DRAM) algorithm of Haario et al. (2006), which combines two powerful mechanisms at iteration \(k\):
- Adaptive Metropolis Covariance Updating: The proposal distribution \(z_k \sim \mathcal{N}(z_{k-1}, \Sigma_k)\) continuously adapts its covariance matrix \(\Sigma_k\) using the empirical sample history \(z_1, \dots, z_{k-1}\) with running mean \(\bar{z}_k\) and Cholesky factor \(\Sigma_k = L L^T\).
- Two-Stage Delayed Rejection: Whenever a first-stage candidate \(z_k = z_{k-1} + L v\) is rejected under the standard Metropolis acceptance probability \(\alpha_1(z_{k-1}, z_k)\), instead of immediately advancing the chain counter at \(z_{k-1}\), DRAM proposes a second, more conservative candidate \(z_k’ \sim \mathcal{N}(z_k + \delta(z_k – z_{k-1}), \Sigma_k’)\) using a scaled-down covariance \(\Sigma_k’ = \rho \Sigma_k\) (\(\rho \in (0, 1)\)) and evaluates the exact reversible-jump detailed-balance acceptance probability \(\alpha_2(z_{k-1}, z_k’)\) in Equation 14:
Experimental Benchmarks: Surrogate Accuracy, Frequency Extrapolation, and MCMC Recovery
The authors conducted a comprehensive suite of experiments evaluating dataset size trade-offs, low-versus-high frequency physics, out-of-band frequency extrapolation up to 150 MHz, and blind parameter recovery across four nanorod test cases (Tables 2, 3, and 4 and Figures 5 through 13).
| Training & Evaluation Regime | Frequency Band Tested | Mean Relative Error ± 1σ (7×7 Array) ↓ | Cumulative CPU Time (2–70 MHz, Aug / No-Aug) ↓ | Physical & Algorithmic Takeaway |
|---|---|---|---|---|
| 100% Data — Without Augmentation | Full 2–70 MHz | \(0.8170 \pm 0.0766\) | 196 s (No-Aug) | Severe overfitting & spatial error hotspots |
| 100% Data — With Triple Augmentation | Full 2–70 MHz | \(0.1080 \pm 0.0147\) | 315 s (Aug) / 196 s | 7.5× error reduction; uniform spatial error map |
| 75% Data — With Triple Augmentation | Full 2–70 MHz | \(0.1229 \pm 0.0087\) | 225 s (Aug) / 145 s | 28.6% faster training with only +1.49% error rise |
| 50% Data — With Triple Augmentation | Full 2–70 MHz | \(0.1773 \pm 0.0090\) | 160 s (Aug) / 110 s | 49.2% CPU savings; viable for rapid prototyping |
| Trained on Full 2–70 MHz | Low Band (2–10 MHz) | \(0.1134 \pm 0.0086\) | 53 s @ 2 MHz / 49 s @ 6.54 MHz | Double-layer proximity nonlinearities slightly harder |
| Trained on Full 2–70 MHz | High Band (10–70 MHz) | \(0.0887 \pm 0.0117\) | 32 s @ 31.77 MHz / 25 s @ 70 MHz | Weakened Debye screening yields smoother bulk fields |
| Trained & Tested Exclusively on Low Band | Low Band Only (2–10 MHz) | \(0.1381 \pm 0.0083\) | — | Single-band training loses cross-spectrum regularization |
| Trained & Tested Exclusively on High Band | High Band Only (10–70 MHz) | \(0.1188 \pm 0.0069\) | — | Full 2–70 MHz training beats isolated band by 3.0% |
| Out-of-Band Extrapolation (\(L=600\text{ nm}, \phi=90^\circ, \epsilon_r=3\)) | 80 / 90 / 100 / 125 / 150 MHz | \(0.0221\) / \(0.0497\) / \(0.0759\) / \(0.0856\) / \(0.1014\) | Instantaneous Inference | Error stays \(\le 10.14\%\) even at \(2.14\times\) max training freq |
Look closely at the physical trends in Table 1 above. First, per-frequency CPU execution time drops steadily as frequency increases—from 53 seconds at \(2\text{ MHz}\) and 49 seconds at \(6.54\text{ MHz}\) down to 32 seconds at \(31.77\text{ MHz}\) and 25 seconds at \(70\text{ MHz}\) (Table 2 of the paper)—and the mean relative error in the \(10\text{–}70\text{ MHz}\) band (\(0.0887\)) is lower than in the \(2\text{–}10\text{ MHz}\) band (\(0.1134\)). Why? Because above \(10\text{ MHz}\), the AC electric field overcomes double-layer screening and penetrates deeply into the 100 mM \(\text{NaCl}\) solution, making the capacitance response depend smoothly on bulk analyte volume rather than steep near-wall gradients. Even more remarkably, when the model trained strictly on \(2\text{–}70\text{ MHz}\) is asked to extrapolate into the ultra-high-frequency regime for a nanorod with \(L = 600\text{ nm}\), \(\phi = 90^\circ\), and \(\epsilon_r = 3\) (Figure 12), mean relative error is just \(2.21\%\) at \(80\text{ MHz}\), \(4.97\%\) at \(90\text{ MHz}\), \(7.59\%\) at \(100\text{ MHz}\), \(8.56\%\) at \(125\text{ MHz}\), and \(10.14\%\) at \(150\text{ MHz}\).
“The right panel reports the results for the complete model… and demonstrates error maps free of spatial patterns (as expected), and a 7x reduction in error and standard deviation across the grid. This indicates improved predictive accuracy and consistent performance across the array.”
Ehsan Khodadadian, Daniele Goldoni, Jacopo Nicolini, Amirreza Khodadadian, Clemens Heitzinger, and Luca Selmi, Engineering Applications of Artificial Intelligence (2025)
Blind Nanorod Metrology Across Four Test Cases
To test the complete ML + DRAM-MCMC inversion pipeline under zero prior knowledge, the authors initialized uniform priors across \(\epsilon_r \in [1, 6]\), \(L \in [100, 1000]\text{ nm}\), and \(\phi \in [0^\circ, 165^\circ]\) and ran 1,000 DRAM iterations on four representative nanorod configurations (Tables 3 and 4 and Figure 13):
| Test Case | Analyte Parameter | True Reference Value | Posterior Mean | Posterior Std (1σ) | 95% Confidence Interval (CI) |
|---|---|---|---|---|---|
| Case 1 | Length \(L\) [nm] | 700 nm | 700.46 nm | 4.46 nm | \([700.10, \, 700.81]\text{ nm}\) |
| Case 1 | Relative Permittivity \(\epsilon_r\) | 3.5 | 3.55 | 0.03 | \([3.54, \, 3.55]\) |
| Case 1 | In-Plane Angle \(\phi\) [°] | 70° | 69.18° | 2.06° | \([69.04^\circ, \, 69.32^\circ]\) |
| Case 2 | Length \(L\) [nm] | 300 nm | 313.00 nm | 4.75 nm | \([312.60, \, 313.50]\text{ nm}\) |
| Case 2 | Relative Permittivity \(\epsilon_r\) | 2.0 | 2.02 | 0.021 | \([2.024, \, 2.027]\) |
| Case 2 | In-Plane Angle \(\phi\) [°] | 80° | 78.26° | 2.38° | \([78.07^\circ, \, 78.46^\circ]\) |
| Case 3 | Length \(L\) [nm] | 500 nm | 493.60 nm | 9.28 nm | \([492.88, \, 494.33]\text{ nm}\) |
| Case 3 | Relative Permittivity \(\epsilon_r\) | 2.5 (2.0 in Fig. 13) | 1.95 | 0.04 | \([1.95, \, 1.96]\) |
| Case 3 | In-Plane Angle \(\phi\) [°] | 40° | 38.90° | 1.22° | \([38.81^\circ, \, 38.99^\circ]\) |
| Case 4 | Length \(L\) [nm] | 900 nm | 889.37 nm | 5.49 nm | \([888.87, \, 889.88]\text{ nm}\) |
| Case 4 | Relative Permittivity \(\epsilon_r\) | 4.0 | 3.93 | 0.04 | \([3.92, \, 3.94]\) |
| Case 4 | In-Plane Angle \(\phi\) [°] | 110° | 110.30° | 2.78° | \([110.09^\circ, \, 110.51^\circ]\) |
As the trace plots in Figure 13 confirm, all 12 Markov chains converge rapidly within the first 200 to 350 burn-in iterations, even when initialized far from the ground truth. Even for Case 2—where the 300 nm nanorod is half the length of the 600 nm horizontal electrode pitch and barely perturbs neighboring pixels—the posterior mean recovers \(313\text{ nm}\), \(\epsilon_r = 2.02\), and \(\phi = 78.26^\circ\).
Clinical and Environmental Translation Gap: From Fixed-Center Simulations to Live Microfluidics
Replacing 500 hours of 3D CV-FEM partial differential equation solving with a few seconds of DRAM-MCMC over a neural surrogate is a major milestone for high-throughput CMOS biochips, echoing the physics-guided deep learning advances we explored in high-frequency ultrasound skin segmentation and self-supervised MR spectroscopic reconstruction. However, translating this framework from in silico ENBIOS test cases to live clinical blood/saliva diagnostics or environmental water monitoring involves three real-world hurdles:
- Brownian Motion and 3D Positional Degrees of Freedom (\(d_x, d_y, d_z, \theta\)): In the current study (Table 1), the nanorod’s center of mass is fixed at \((d_x, d_y, d_z) = (0, 0, 40)\text{ nm}\) with zero vertical tilt (\(\theta = 0^\circ\)) and constant radius \(R = 50\text{ nm}\) while \((L, \phi, \epsilon_r)\) vary. Inside a real microfluidic channel, a virus or nanoplastic fiber undergoes continuous 3D translational and rotational Brownian motion and Dielectrophoretic (DEP) forces. Because capacitance decays steeply with vertical elevation \(d_z\), jointly inverting \((d_x, d_y, d_z, \theta, R, L, \phi, \epsilon_r)\) will require expanding the surrogate input vector from 4 features to 9 features and pairing multi-frame temporal tracking with the 2 aF sensor readout.
- Variable Electrolyte Salinity and Biofouling: All training simulations were run at a fixed physiological salinity of 100 mM \(\text{NaCl}\) (\(\epsilon_{r,el} = 80\)). Environmental river or tap water monitoring for nanoplastics involves salinities ranging from \(< 1\text{ mM}\) to \(> 500\text{ mM}\) in seawater, which shifts both the lower resistive cut-off frequency (\(1.7\text{ MHz}\)) and the dielectric relaxation cut-off (\(300\text{ MHz}\)). In clinical serum or whole-blood assays, non-specific protein adsorption (biofouling) on the \(\text{AuCu}\) nanoelectrodes alters the baseline capacitance \(C_{\text{without-analyte}}\).
- Surrogate Epistemic Uncertainty in the Bayesian Likelihood: As the authors explicitly note at the end of Section 6.4, the 4-layer neural network is treated as a deterministic forward operator \(Q(x, z)\) inside Equation 12. Consequently, the narrow 95% confidence intervals in Table 4 reflect observational noise \(\sigma^2\), not the \(\approx 10.8\%\) approximation error of the neural surrogate itself—which explains why the true value occasionally sits slightly outside the narrow post-burn-in histogram (such as \(\epsilon_r\) in Case 3).
To prevent narrow MCMC confidence intervals from under-reporting surrogate approximation error in clinical or regulatory assays, practitioners can train a 5-member Deep Ensemble of `4 -> 128 -> 64 -> 32 -> 16 -> 49` networks and add the ensemble’s input-dependent variance \(\sigma^2_{\text{ML}}(z)\) directly to the measurement noise variance \(\sigma^2_{\text{obs}}\) inside the DRAM Gaussian likelihood.
Honest Methodological and Physical Limitations
In Sections 4, 6.4, and 7, Khodadadian and colleagues candidly discuss four limitations that define the roadmap for next-generation nanoscale metrology:
- 5% Perturbation Label Invariance Approximation: Keeping output capacitance labels unchanged when adding 5% Gaussian noise to \((L, \phi, \epsilon_r)\) relies on the local smoothness of the AC-PNP operator. Near sharp geometric thresholds—such as when a rotating 1,000 nm nanorod tip just crosses the edge of a neighboring \(600\text{ nm}\)-pitch electrode—local gradients steepen, which contributes to the residual \(10.8\%\) relative error floor.
- Fixed Spatial Grid Resolution (\(7 \times 7\) Pixels): The current MLP output head is hardcoded to a \(7 \times 7\) electrode patch at \((0.6, 0.89)\,\mu\text{m}\) pitch. Adapting the model to different CMOS array layouts requires retraining, motivating the authors’ suggestion to adopt resolution-independent neural operators (such as DeepONets or Fourier Neural Operators) and discretization-agnostic Bayesian inference (NIFTY).
- Sequential MCMC Sampling Latency: While 1,000 DRAM steps run in seconds using the PyTorch surrogate, scaling simultaneous parameter extraction to thousands of nanoelectrodes firing in parallel across a \(256 \times 256\) array (65,536 pixels) will benefit from diffusion-accelerated MCMC transitions or amortized neural posterior estimation.
- Purely Dielectric Cylinder Assumption (\(\sigma = 0\text{ S/m}\)): The template analyte is modeled as an uncharged, non-conducting cylinder (\(\sigma = 0\text{ S/m}\)). Conducting carbon nanotubes or heavily charged DNA polyelectrolyte bundles exhibit surface conductance and counter-ion condensation that require including analyte conductivity \(\sigma\) and surface charge \(\rho_{0f}\) in the inversion vector.
Conclusion and Future Directions
By uniting 3D Control-Volume Finite Element AC-PNP physics simulations, a triple-augmented deep neural network surrogate, and Delayed Rejection Adaptive Metropolis Bayesian inversion, Khodadadian, Goldoni, Nicolini, Khodadadian, Heitzinger, and Selmi have turned high-frequency CMOS nanocapacitor arrays into quantitative nanoscale metrology instruments.
Their work demonstrates that physics-based simulation and machine learning are multiplicative rather than mutually exclusive. Without the 3D AC-PNP solver (ENBIOS), it is impossible to generate ground-truth labels for sub-micron nanorods amid attoFarad noise and Debye screening. Without the triple data augmentation strategy (perturbations, uniform resampling, and GAN synthesis) and variance-weighted loss, the neural network overfits and suffers an 81.7 percent error. And without the millisecond neural surrogate, running a 1,000-step DRAM-MCMC Bayesian inversion to recover length, permittivity, and orientation with full uncertainty quantification would take weeks of supercomputer time instead of seconds on a standard CPU.
As future iterations incorporate Bayesian neural network epistemic uncertainty, resolution-independent operator learning, and multi-salinity training sets, this hybrid physics-ML-Bayesian blueprint will empower high-throughput CMOS biochips to size and identify waterborne nanoplastics, viral particles, and nucleic acid biomarkers in real time at the point of care.
Complete PyTorch Implementation of the Augmented Surrogate and DRAM-MCMC Inversion
Below is a complete, self-contained, runnable PyTorch implementation of the entire methodology described in Sections 4, 5, and 6 of the paper, including the 3-layer feedforward **GAN** (`Generator` and `Discriminator`) for synthetic input generation, the **triple data augmentation pipeline** (5% Gaussian perturbations + uniform resampling + GAN), the **`4 -> 128 -> 64 -> 32 -> 16 -> 49` Deep Neural Network surrogate**, the **variance-weighted combined loss function** (Equations 7 and 8), and the complete two-stage **Delayed Rejection Adaptive Metropolis (DRAM) MCMC** algorithm (Equations 9–14) recovering nanorod \((L, \epsilon_r, \phi)\) on Case 1 (`700 nm, 3.5, 70 deg`).
import math
import torch
import torch.nn as nn
import torch.nn.functional as F
from torch.utils.data import TensorDataset, DataLoader

# =====================================================================
# 1. ANALYTICAL AC-PNP NANOCAPACITOR ARRAY SIMULATOR PROXY (SEC. 2 & 3)
# =====================================================================

def simulate_7x7_capacitance_map(params: torch.Tensor) -> torch.Tensor:
    """
    Physics-based analytical proxy for ENBIOS 3D AC-PNP solver (Table 1 & Fig. 1):
    Maps [B, 4] inputs (L in [200,1000] nm, phi in [0,165] deg, eps_r in [1,5], f in [2,70] MHz)
    to 49 negative capacitance steps -Delta_C (fF) across the 7x7 electrode array
    with pitch_x = 600 nm, pitch_y = 890 nm, and frequency-dependent Debye screening.
    """
    L = params[:, 0:1]          # [200, 1000] nm
    phi_deg = params[:, 1:2]    # [0, 165] deg
    eps_r = params[:, 2:3]      # [1, 5]
    freq = params[:, 3:4]       # [2, 70] MHz

    device = params.device
    coords_x = torch.arange(-3, 4, device=device, dtype=torch.float32) * 600.0  # pitch_x = 600 nm
    coords_y = torch.arange(-3, 4, device=device, dtype=torch.float32) * 890.0  # pitch_y = 890 nm
    grid_y, grid_x = torch.meshgrid(coords_y, coords_x, indexing='ij')
    ex = grid_x.reshape(1, 49)
    ey = grid_y.reshape(1, 49)

    # Rotate electrode coordinates into nanorod principal frame
    phi_rad = phi_deg * (math.pi / 180.0)
    u_par = ex * torch.cos(phi_rad) + ey * torch.sin(phi_rad)
    u_perp = -ex * torch.sin(phi_rad) + ey * torch.cos(phi_rad)

    # High-frequency Debye screening penetration length & dielectric contrast (eps_el=80)
    debye_scale = 260.0 + 3.5 * freq
    freq_decay = (1.0 + freq / 8.0) ** (-0.65)
    diel_contrast = (80.0 - eps_r) / 80.0  # Dielectric displacement factor

    # Spatial overlap of cylinder of length L and radius R=50nm at height dz=40nm
    half_L = 0.5 * L
    dist_par = F.relu(torch.abs(u_par) - half_L)
    dist_sq = dist_par ** 2 + u_perp ** 2 + 40.0 ** 2

    delta_c = 0.25 * (L / 1000.0) * diel_contrast * freq_decay * torch.exp(-dist_sq / (debye_scale ** 2))
    return delta_c  # [B, 49] in fF


# =====================================================================
# 2. FEEDFORWARD GAN FOR SYNTHETIC AUGMENTATION (SECTION 4)
# =====================================================================

class ParameterGenerator(nn.Module):
    """3-layer fully connected ReLU Generator mapping 3D latent noise to (L, phi, eps_r)."""
    def __init__(self, latent_dim: int = 3, hidden_dim: int = 32):
        super().__init__()
        self.net = nn.Sequential(
            nn.Linear(latent_dim, hidden_dim),
            nn.ReLU(),
            nn.Linear(hidden_dim, hidden_dim),
            nn.ReLU(),
            nn.Linear(hidden_dim, 3),
            nn.Sigmoid(),
        )

    def forward(self, z: torch.Tensor, mins: torch.Tensor, maxs: torch.Tensor) -> torch.Tensor:
        unit_out = self.net(z)
        return mins + unit_out * (maxs - mins)


class ParameterDiscriminator(nn.Module):
    """3-layer fully connected ReLU Discriminator distinguishing real vs synthetic inputs."""
    def __init__(self, in_dim: int = 3, hidden_dim: int = 32):
        super().__init__()
        self.net = nn.Sequential(
            nn.Linear(in_dim, hidden_dim),
            nn.ReLU(),
            nn.Linear(hidden_dim, hidden_dim),
            nn.ReLU(),
            nn.Linear(hidden_dim, 1),
            nn.Sigmoid(),
        )

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        return self.net(x)


# =====================================================================
# 3. 4-LAYER CAPACITANCE SURROGATE DNN & COMBINED LOSS (EQS. 7 & 8)
# =====================================================================

class CapacitanceSurrogateDNN(nn.Module):
    """
    Implements Section 4 DNN Architecture:
    4 inputs (L, phi, eps_r, f) -> 4 hidden layers (128, 64, 32, 16) -> 49 outputs (7x7 map).
    """
    def __init__(self, in_features: int = 4, out_features: int = 49):
        super().__init__()
        self.net = nn.Sequential(
            nn.Linear(in_features, 128),
            nn.ReLU(),
            nn.Linear(128, 64),
            nn.ReLU(),
            nn.Linear(64, 32),
            nn.ReLU(),
            nn.Linear(32, 16),
            nn.ReLU(),
            nn.Linear(16, out_features),
        )

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        return self.net(x)


class VarianceWeightedCombinedLoss(nn.Module):
    """Implements Equations (7) and (8): L_combined = L_MSE + lambda * sum(w_i * L_i)."""
    def __init__(self, raw_y_train: torch.Tensor, lam: float = 1.0):
        super().__init__()
        self.lam = lam
        sigma_i = torch.std(raw_y_train, dim=0).clamp(min=1e-12)
        self.register_buffer("weights", sigma_i / torch.sum(sigma_i))  # Eq. (8)

    def forward(self, pred: torch.Tensor, target: torch.Tensor) -> torch.Tensor:
        loss_mse = F.mse_loss(pred, target)
        loss_per_pixel = torch.mean((pred - target) ** 2, dim=0)
        weighted_term = torch.sum(self.weights * loss_per_pixel)
        return loss_mse + self.lam * weighted_term  # Eq. (7)


# =====================================================================
# 4. TRIPLE DATA AUGMENTATION PIPELINE (FIG. 3 & SECTION 4)
# =====================================================================

def build_augmented_dataset(x_orig: torch.Tensor, y_orig: torch.Tensor) -> tuple:
    """
    Doubles dataset size via three equally weighted branches:
    1) Small perturbations (sigma_n = 5% of feature range, unchanged output labels).
    2) Uniform random sampling within parameter ranges.
    3) 3-layer GAN synthetic parameter generation labeled by physics surrogate.
    """
    N = x_orig.size(0)
    n_branch = N // 3
    device = x_orig.device

    x_min = x_orig.min(dim=0, keepdim=True).values
    x_max = x_orig.max(dim=0, keepdim=True).values
    x_range = x_max - x_min

    # Branch 1: 5% Gaussian input perturbations with unchanged labels
    idx1 = torch.randint(0, N, (n_branch,), device=device)
    x_pert = (x_orig[idx1] + 0.05 * x_range * torch.randn(n_branch, 4, device=device)).clamp(x_min, x_max)
    y_pert = y_orig[idx1].clone()

    # Branch 2: Uniform random sampling within [min, max]
    x_rand = x_min + torch.rand(n_branch, 4, device=device) * x_range
    y_rand = simulate_7x7_capacitance_map(x_rand)

    # Branch 3: Train lightweight 3-layer GAN on (L, phi, eps_r)
    gen = ParameterGenerator().to(device)
    disc = ParameterDiscriminator().to(device)
    opt_g = torch.optim.Adam(gen.parameters(), lr=2e-3)
    opt_d = torch.optim.Adam(disc.parameters(), lr=2e-3)
    p_min, p_max = x_min[:, :3], x_max[:, :3]
    real_3d = (x_orig[:, :3] - p_min) / (p_max - p_min + 1e-8)

    for _ in range(20):
        z = torch.randn(N, 3, device=device)
        fake_3d = (gen(z, p_min, p_max) - p_min) / (p_max - p_min + 1e-8)
        opt_d.zero_grad()
        loss_d = -torch.mean(torch.log(disc(real_3d) + 1e-8) + torch.log(1.0 - disc(fake_3d.detach()) + 1e-8))
        loss_d.backward()
        opt_d.step()

        opt_g.zero_grad()
        loss_g = -torch.mean(torch.log(disc(fake_3d) + 1e-8))
        loss_g.backward()
        opt_g.step()

    with torch.no_grad():
        z_syn = torch.randn(N - 2 * n_branch, 3, device=device)
        syn_3d = gen(z_syn, p_min, p_max)
        syn_f = x_orig[torch.randint(0, N, (z_syn.size(0),), device=device), 3:4]
        x_gan = torch.cat([syn_3d, syn_f], dim=1)
        y_gan = simulate_7x7_capacitance_map(x_gan)

    x_all = torch.cat([x_orig, x_pert, x_rand, x_gan], dim=0)
    y_all = torch.cat([y_orig, y_pert, y_rand, y_gan], dim=0)
    return x_all, y_all


# =====================================================================
# 5. DELAYED REJECTION ADAPTIVE METROPOLIS (DRAM-MCMC, EQS. 9 TO 14)
# =====================================================================

def run_dram_mcmc_inversion(
    forward_surrogate_fn,
    obs_map: torch.Tensor,
    z_init: torch.Tensor,
    prior_min: torch.Tensor,
    prior_max: torch.Tensor,
    sigma_obs: float = 0.005,
    n_iters: int = 1000,
    burn_in: int = 300,
    rho_scale: float = 0.25
) -> torch.Tensor:
    """
    Implements Section 5.2 (Fig. 4 & Equations 9 to 14):
    Two-stage Delayed Rejection Adaptive Metropolis (DRAM) MCMC for (L, phi, eps_r).
    """
    device = z_init.device

    def log_posterior(z_cand: torch.Tensor) -> float:
        # Uniform prior check (Table 3 bounds)
        if torch.any(z_cand < prior_min) or torch.any(z_cand > prior_max):
            return -float("inf")
        pred_map = forward_surrogate_fn(z_cand)
        misfit = torch.sum((obs_map - pred_map) ** 2).item()  # Eq. (13)
        return -misfit / (2.0 * (sigma_obs ** 2))             # Log of Eq. (12)

    z_curr = z_init.clone()
    log_p_curr = log_posterior(z_curr)

    # Initial proposal covariance Sigma_0 for (L, phi, eps_r)
    cov = torch.diag(torch.tensor([150.0, 9.0, 0.02], device=device))
    eye3 = torch.eye(3, device=device)
    chain = torch.zeros((n_iters, 3), device=device)

    for k in range(n_iters):
        # Adaptive Metropolis covariance update after warm-up
        if k > 50 and k % 10 == 0:
            hist = chain[:k]
            mean_k = torch.mean(hist, dim=0, keepdim=True)
            centered = hist - mean_k
            cov = (centered.t() @ centered) / (k - 1) + 1e-4 * eye3

        L_chol = torch.linalg.cholesky(cov)
        z_prop1 = z_curr + L_chol @ torch.randn(3, device=device)
        log_p_prop1 = log_posterior(z_prop1)

        # Stage 1 Acceptance Probability alpha_1(z_{k-1}, z_k)
        alpha1 = min(1.0, math.exp(max(-50.0, min(50.0, log_p_prop1 - log_p_curr))))
        if torch.rand(1, device=device).item() < alpha1:
            z_curr, log_p_curr = z_prop1, log_p_prop1
        else:
            # Stage 2 Delayed Rejection with scaled covariance Sigma'_k = rho * Sigma_k (Eq. 14)
            L_chol2 = math.sqrt(rho_scale) * L_chol
            z_prop2 = z_curr + L_chol2 @ torch.randn(3, device=device)
            log_p_prop2 = log_posterior(z_prop2)

            if log_p_prop2 > -float("inf"):
                alpha1_rev = min(1.0, math.exp(max(-50.0, min(50.0, log_p_prop1 - log_p_prop2))))
                inv_cov = torch.linalg.inv(cov)
                diff_f = z_prop1 - z_curr
                diff_r = z_prop1 - z_prop2
                log_q1_ratio = -0.5 * ((diff_r @ inv_cov @ diff_r) - (diff_f @ inv_cov @ diff_f)).item()

                log_ratio2 = (log_p_prop2 - log_p_curr) + log_q1_ratio + math.log(max(1e-8, 1.0 - alpha1_rev)) - math.log(max(1e-8, 1.0 - alpha1))
                alpha2 = min(1.0, math.exp(max(-50.0, min(50.0, log_ratio2))))
                if torch.rand(1, device=device).item() < alpha2:
                    z_curr, log_p_curr = z_prop2, log_p_prop2

        chain[k] = z_curr

    return chain[burn_in:]


# =====================================================================
# 6. RUNNABLE SMOKE TEST: TRAINING + CASE 1 METROLOGY (L=700, phi=70, eps=3.5)
# =====================================================================

if __name__ == "__main__":
    torch.manual_seed(42)
    device = torch.device("cuda" if torch.cuda.is_available() else "cpu")

    # 1. Generate Baseline Physics Dataset & Apply Triple Augmentation
    N_base = 900
    x_base = torch.stack([
        200.0 + 800.0 * torch.rand(N_base, device=device),  # L in [200, 1000] nm
        165.0 * torch.rand(N_base, device=device),          # phi in [0, 165] deg
        1.0 + 4.0 * torch.rand(N_base, device=device),      # eps_r in [1, 5]
        2.0 + 68.0 * torch.rand(N_base, device=device),     # f in [2, 70] MHz
    ], dim=1)
    y_base = simulate_7x7_capacitance_map(x_base)

    x_aug, y_aug = build_augmented_dataset(x_base, y_base)

    # StandardScaler normalization on inputs and outputs (Section 4)
    x_mu, x_std = x_aug.mean(dim=0, keepdim=True), x_aug.std(dim=0, keepdim=True).clamp(min=1e-8)
    y_mu, y_std = y_aug.mean(dim=0, keepdim=True), y_aug.std(dim=0, keepdim=True).clamp(min=1e-8)
    x_norm = (x_aug - x_mu) / x_std
    y_norm = (y_aug - y_mu) / y_std

    # 2. Train 4-Layer Surrogate DNN with Shuffling & Variance-Weighted Combined Loss
    model = CapacitanceSurrogateDNN(in_features=4, out_features=49).to(device)
    criterion = VarianceWeightedCombinedLoss(y_aug, lam=1.0).to(device)
    optimizer = torch.optim.Adam(model.parameters(), lr=3e-3)
    loader = DataLoader(TensorDataset(x_norm, y_norm), batch_size=64, shuffle=True)

    model.train()
    for _ in range(40):
        for bx, by in loader:
            optimizer.zero_grad()
            loss = criterion(model(bx), by)
            loss.backward()
            optimizer.step()

    # 3. Run DRAM-MCMC Bayesian Inversion on Test Case 1 (True: L=700 nm, phi=70 deg, eps_r=3.5)
    model.eval()
    freqs_10 = torch.logspace(math.log10(2.0), math.log10(70.0), 10, device=device)
    z_true = torch.tensor([700.0, 70.0, 3.5], device=device)

    def surrogate_multispectral(z_3d: torch.Tensor) -> torch.Tensor:
        with torch.no_grad():
            inp = torch.cat([z_3d.unsqueeze(0).expand(10, -1), freqs_10.unsqueeze(1)], dim=1)
            pred_n = model((inp - x_mu) / x_std)
            return pred_n * y_std + y_mu

    obs_case1 = surrogate_multispectral(z_true) + 0.0005 * torch.randn(10, 49, device=device)
    z_start = torch.tensor([650.0, 60.0, 3.0], device=device)
    p_min = torch.tensor([100.0, 0.0, 1.0], device=device)
    p_max = torch.tensor([1000.0, 165.0, 6.0], device=device)

    posterior_samples = run_dram_mcmc_inversion(
        surrogate_multispectral, obs_case1, z_start, p_min, p_max, sigma_obs=0.005, n_iters=600, burn_in=200
    )
    post_mean = posterior_samples.mean(dim=0)
    print(f"Augmented Dataset Size: {x_aug.size(0)} | Final Surrogate Loss: {loss.item():.4f}")
    print(f"Case 1 True: L=700.0 nm, phi=70.0 deg, eps_r=3.50")
    print(f"DRAM-MCMC Posterior Mean: L={post_mean[0].item():.2f} nm, phi={post_mean[1].item():.2f} deg, eps_r={post_mean[2].item():.2f}")
Frequently Asked Questions
Why is high-frequency AC operation above 1 MHz necessary for CMOS nanoelectrode biosensors?
In physiological or environmental salt solutions such as 100 mM sodium chloride, mobile ions rapidly screen static or low-frequency electric fields within a sub-nanometer Debye length of the electrode surface. Operating between 2 MHz and 70 MHz mitigates Debye screening, allowing the alternating electric field to penetrate deep into the microfluidic chamber and sense nanoscale analytes floating tens of nanometers above the array.
Why can Bayesian inversion not use the 3D AC-PNP physics simulator directly?
Solving the coupled 3D Poisson-Boltzmann and linearized Poisson-Nernst-Planck equations on tetrahedral meshes of roughly 141,110 elements takes over 30 minutes of CPU time per run on a 104-core server. Because Markov Chain Monte Carlo Bayesian inversion requires at least 1,000 sequential forward evaluations to converge, direct physics simulation would take weeks per analyte, whereas the trained neural network surrogate completes all evaluations in seconds.
How does the triple data augmentation strategy improve neural network accuracy?
The authors double the initial 8,550 ENBIOS simulations by adding 2,850 samples with 5 percent Gaussian input perturbations, 2,850 uniformly resampled points, and 2,850 synthetic input samples generated by a 3-layer feedforward Generative Adversarial Network. Combined with epoch shuffling and a variance-weighted MSE loss, this strategy reduces the mean relative capacitance error across the 7 by 7 electrode array more than sevenfold, from 0.817 down to 0.108.
Why is the training dataset split at a midpoint frequency of 10 MHz?
In a 100 mM NaCl electrolyte, 10 MHz separates two distinct physical regimes. Below 10 MHz (near the 1.7 MHz resistive cut-off), the capacitance response is dominated by slow electrical double-layer polarization that is highly sensitive to electrode-analyte proximity. Above 10 MHz (approaching the 300 MHz dielectric relaxation cut-off), Debye screening weakens and the response reflects bulk analyte volume more uniformly.
How does Delayed Rejection Adaptive Metropolis improve upon standard Metropolis-Hastings MCMC?
Delayed Rejection Adaptive Metropolis (DRAM) continuously updates the proposal covariance matrix using the empirical history of accepted chain states to match correlated parameter landscapes. Furthermore, whenever an initial candidate move is rejected, DRAM proposes a second, smaller step scaled by a factor rho before advancing the chain, preventing chain stagnation in high-dimensional nonlinear spaces.
Can the neural network extrapolate capacitance predictions beyond its 70 MHz training limit?
Yes. When trained on 2 to 70 MHz data and tested on higher frequencies up to 150 MHz for a 600 nm nanorod, the array-averaged relative capacitance error rises gradually from 2.21 percent at 80 MHz and 7.59 percent at 100 MHz to 10.14 percent at 150 MHz, remaining at or below 10 percent even at more than twice the maximum training frequency.
Explore the Published Study in Engineering Applications of Artificial Intelligence
Read the complete open-access paper, AC-PNP finite element formulations, and Bayesian posterior analyses by the TU Wien, University of Modena and Reggio Emilia, and Keele University research team.
Academic Citation Khodadadian, E., Goldoni, D., Nicolini, J., Khodadadian, A., Heitzinger, C., & Selmi, L. (2025). Integrating physics-based simulations, machine learning, and Bayesian inference for accurate detection and metrology of elongated nanoscale analytes using high-frequency capacitance spectroscopy. Engineering Applications of Artificial Intelligence, 159, 111679. https://doi.org/10.1016/j.engappai.2025.111679
This analysis is based on the published paper and an independent evaluation of its claims.