
Key points
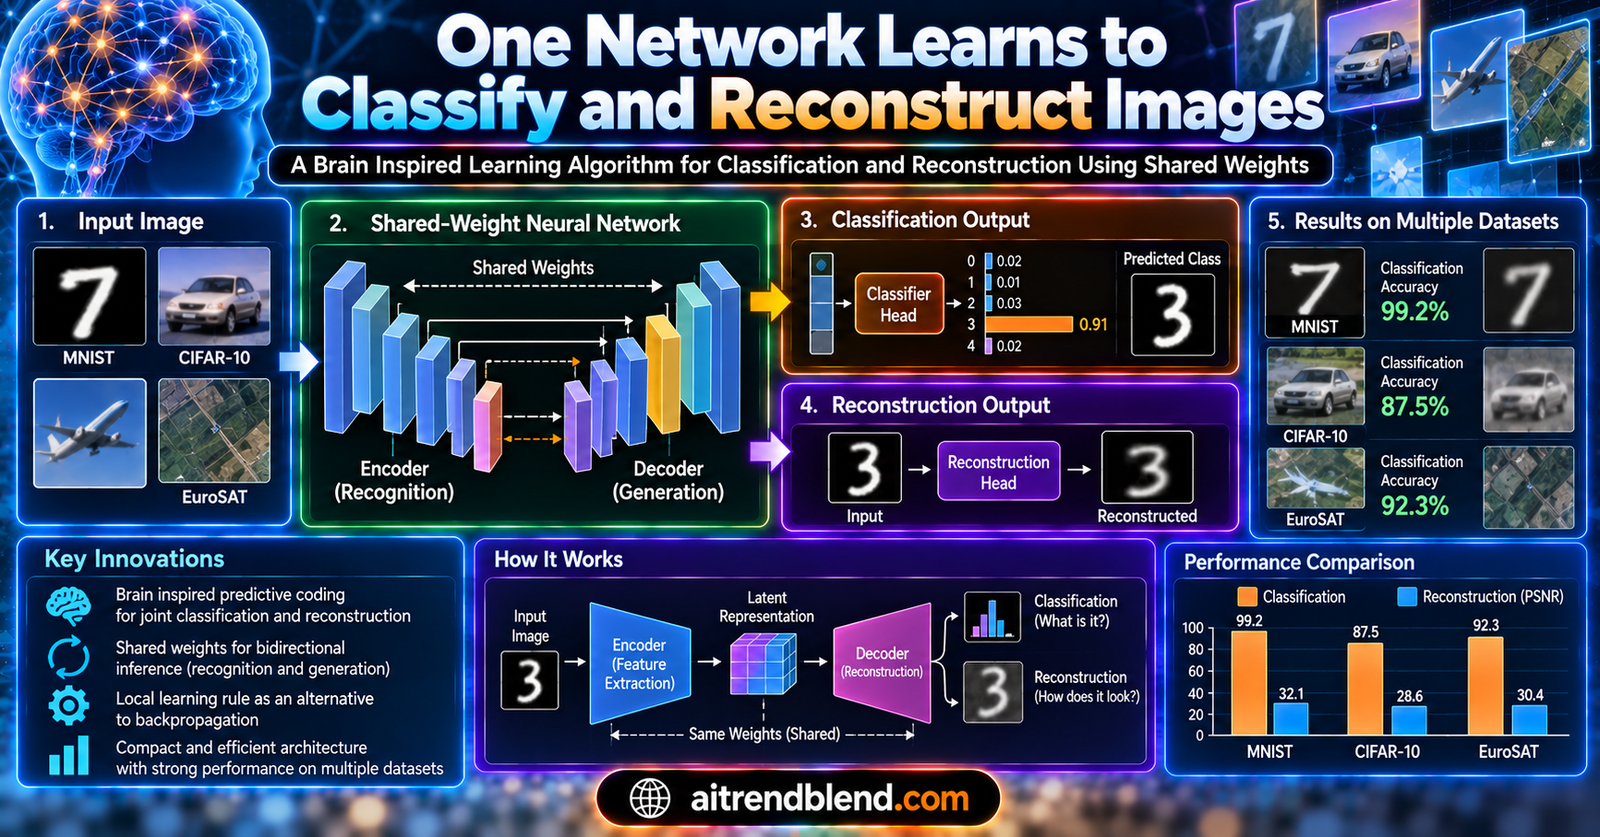
- The method, called Deep Bidirectional Predictive Coding, lets one network perform classification and reconstruction using a single shared set of weights instead of two separate pathways.
- Every layer predicts the neuron activity of the layer before it and the layer after it, and only ever needs information from its immediate neighbors to learn, which means every layer can update in parallel rather than waiting for a signal to travel end to end.
- On MNIST the convolutional version reached 99.58 percent accuracy with only 0.425 million parameters, close to networks like VGG that need eight times as many parameters to hit 99.72 percent.
- On Fashion-MNIST it reached 92.42 percent and on the harder CIFAR-10 dataset 74.29 percent, both ahead of every other predictive coding based method tested, and it also worked on real satellite imagery from the EuroSAT dataset at 92.56 percent.
- Two hyperparameters, one weighting classification and one weighting reconstruction, let the same network trade off between the two goals, and an ablation study shows training them jointly beats training for either goal alone.
The problem with how most networks actually learn
Almost every deep network in production today learns through error backpropagation, the algorithm that compares a prediction against the correct answer at the output and pushes that error signal backward through every layer to figure out how each weight should change. It works remarkably well, but it has a structural quirk that becomes a real headache once you try to run it anywhere other than a beefy GPU cluster. Each layer needs to know about the weights in every layer that comes after it before it can update itself, a requirement researchers call the weight transport problem. That dependency forces training to happen in a strict sequence, back to front, which is exactly the kind of bottleneck that limited hardware on a phone, a drone, or an embedded sensor cannot absorb gracefully.
The brain does not appear to work this way. Biological synapses adjust themselves using only information available locally, at that connection, not a global error signal broadcast from some distant output layer. That mismatch between how artificial networks train and how brains apparently train has kept researchers chasing local learning rules for decades, and predictive coding is one of the more promising candidates that has come out of that search.
Predictive coding starts from a simple premise, one layer in the network tries to guess what the layer next to it is doing, and the mismatch between the guess and the actual activity becomes the learning signal. Researchers have known for years that representations learned this way turn out to be useful for more than one task. The same internal representation that lets a network reconstruct an input can often also support classifying it, which raises an obvious question. Why train two separate networks, or two separate sets of weights, when one might do both jobs.
What earlier predictive coding networks left on the table
The paper’s related work section makes clear that most prior predictive coding research picked one job and stuck with it. A large body of neuroscience inspired work built purely generative, unsupervised models, clamping the input and letting the rest of the network settle into a representation that could reconstruct it, useful for understanding perception but not built for classification. A separate line of supervised predictive coding work went the other direction, clamping both the input and the correct label during training and using only the resulting representations to classify new inputs at test time. Those networks were never designed to reconstruct anything.
A few studies tried to bridge the gap. One earlier approach used predictive coding within a network that could do both classification and reconstruction, but it kept an entirely separate set of parameters for each task, which defeats a lot of the point if compact, parameter efficient networks are the goal. Another approach used predictive coding only to estimate the internal representations while falling back on ordinary backpropagation to update the weights themselves, which brings the weight transport problem right back in through the side door. None of the prior work managed shared weights, local learning, and both tasks at once, and that is the specific gap this paper set out to close.
Making one set of weights run both directions
The core trick in Deep Bidirectional Predictive Coding, DBPC for short, is almost embarrassingly simple to state even though getting it to train stably clearly took real engineering. Every layer in the network predicts two things at once, the activity of the layer behind it, using feedback propagation, and the activity of the layer ahead of it, using feedforward propagation. Both predictions use the exact same weight matrix, just applied in different directions, feedforward as a normal matrix multiplication and feedback using the transposed matrix.
Here \(f\) is a ReLU activation, \(y_l\) is the activity vector for layer \(l\), and \(W_l\) is the weight matrix connecting layer \(l\) to layer \(l+1\). Notice that the second equation reuses the transpose of the very same matrix used in the first, rather than training a separate feedback pathway the way an autoencoder trains a separate encoder and decoder. That single design choice is what keeps the total parameter count so small across every experiment in the paper.
Two kinds of error, computed locally
Once a layer has made both predictions, it compares them against its own actual activity and produces two error signals, a feedforward prediction error and a feedback prediction error.
Everything a layer needs to compute both of these errors already lives right next to it, the activity of the layer before, the activity of the layer after, and the two weight matrices connecting them. No error signal has to travel from the output layer all the way back through every earlier layer the way it does under backpropagation. That locality is what unlocks parallel learning. Every layer in the network can compute its errors and start updating at the same moment, rather than layer ten waiting on a gradient computed at layer fifty first.
Two knobs that trade off classification against reconstruction
The representations themselves, the \(y_l\) values, get updated by gradient descent on a weighted combination of both error types, and separately the weights get updated by gradient descent on a similarly weighted combination.
The team found through empirical testing that setting \(\lambda_b\) to zero, meaning feedback errors do not directly reshape the representations during training, produced far more stable results, apparently because letting both classification driven and reconstruction driven signals fight over the same representation at the same time caused oscillation and slower convergence. Instead they let feedforward errors alone shape the representations while both \(\beta_c\) and \(\beta_r\) shape the weights, meaning the weights still learn to support reconstruction even though the moment to moment representation updates are steered mainly by the classification objective. It is a subtle asymmetry, and one of the more interesting engineering decisions buried in the paper, since it means the two tasks share weights without directly interfering with each other’s short term learning dynamics.
Extending the idea to convolutional layers
Fully connected layers are one thing, convolutional layers are trickier because a convolution kernel does not naturally reverse itself the way a matrix transpose does. The authors solve this with a padding rule that keeps the input and output of every convolution the same spatial size, letting the same kernel run forward as an ordinary convolution and backward, after reshaping which axis represents input and output channels, as another ordinary convolution rather than requiring a separate transpose convolution operation.
where \(K\) is the kernel size and \(P\) the padding. This one line of arithmetic is what makes it possible for a convolutional version of DBPC to exist at all using shared kernels, and it turns out to matter a great deal for the results, since the convolutional variant beats the fully connected one across every dataset tested.
How well does sharing weights actually work
Here is where the paper earns its keep. Sharing one set of weights across two very different objectives sounds like it should cost something, and the natural worry is that a network forced to also handle reconstruction would classify worse than a network built purely for classification. The results argue against that worry, at least at the scale tested here.
| Dataset | DBPC accuracy | Parameters | Best comparison method | Its accuracy and parameters |
|---|---|---|---|---|
| MNIST, fully connected | 98.90 percent | 1.225M | FIPC3 (predictive coding) | 98.84 percent, 2.450M |
| MNIST, convolutional | 99.58 percent | 0.425M | VGG5 Spinal FC | 99.72 percent, 3.630M |
| Fashion-MNIST, convolutional | 92.42 percent | 1.004M | PC-1 (predictive coding) | 89.00 percent, 0.532M |
| CIFAR-10, convolutional | 74.29 percent | 1.109M | iPC (predictive coding) | 72.54 percent, 8.539M |
| EuroSAT, convolutional | 92.56 percent | not stated | GoogleNet | 95.70 percent |
Two things stand out reading across that table. Against other predictive coding methods, which is the fairest comparison since those methods share the same basic local learning philosophy, DBPC wins on every dataset, often by a wide margin, and it does so using substantially fewer parameters in most cases. Against conventional backpropagation trained networks like VGG or ResNet, DBPC lands close behind rather than ahead, which is a genuinely honest way for the authors to frame it. A method built around local learning and dual task capability is not trying to dethrone backpropagation on raw accuracy, it is trying to show that the local learning approach does not have to pay nearly as steep a price as earlier predictive coding attempts suggested.
The reconstruction side of the ledger
Because DBPC’s whole premise rests on getting classification and reconstruction from the same weights, it matters that the reconstructions are not an afterthought. The team compared DBPC’s reconstruction quality against dedicated autoencoders and variational autoencoders using PSNR and SSIM, two standard image quality metrics. The picture that emerges is layer dependent and honestly reported. Reconstructions from the layer closest to the input consistently look sharp, on MNIST the second layer of the convolutional version reached a PSNR of 31.67, close to the 32.82 an autoencoder achieves with a network built purely for reconstruction. Push deeper into the network toward the layers doing more of the classification work, and reconstruction quality degrades steadily, dropping to a PSNR in the low teens by the final hidden layers. That pattern makes intuitive sense, the deepest representations are compressed hardest toward whatever distinguishes one class from another, throwing away detail that reconstruction would want to keep.
What the ablation study actually shows
It would be easy for a paper like this to simply assert that training classification and reconstruction jointly helps both, so it is worth calling out that the authors actually tested the claim. They trained three versions of the fully connected network on MNIST, one with both objectives active, one with only the classification factor turned on, and one with only the reconstruction factor turned on.
| Configuration | Classification factor | Reconstruction factor | Accuracy | Reconstruction PSNR and SSIM |
|---|---|---|---|---|
| Classification only | 0.08 | 0.000 | 98.60 percent | 6.559 / 0.098 |
| Reconstruction only | 0.00 | 0.001 | 13.55 percent | 13.210 / 0.610 |
| Joint learning | 0.08 | 0.001 | 98.87 percent | 9.395 / 0.187 |
Joint training beats classification only training on accuracy, 98.87 percent against 98.60 percent, which supports the idea that the reconstruction objective acts as a kind of regularizer, nudging the network toward representations that generalize a little better rather than overfitting purely to the classification boundary. The reconstruction only network unsurprisingly falls apart on classification, landing near chance at 13.55 percent, since nothing in its training ever pushed it to separate the ten digit classes. What is worth noting honestly is that the joint network’s reconstruction quality sits well below the reconstruction only network’s, a real tradeoff rather than a free lunch, which the authors attribute to the higher weight placed on the classification factor relative to the reconstruction factor in their chosen hyperparameters.
Testing it on something less tidy than digits
MNIST and Fashion-MNIST are useful benchmarks precisely because they are small and clean, but that cleanliness can also flatter a method in ways that do not survive contact with messier real world data. The team pushed DBPC onto the EuroSAT dataset, twenty seven thousand labeled satellite images spanning ten land use categories like crop fields, rivers, highways, and forest, a genuinely different kind of visual problem from handwritten digits.
DBPC reached 92.56 percent accuracy on EuroSAT, trailing ResNet-50 and GoogleNet by a few points but clearing a standard two layer CNN baseline and a bag of visual words approach by a comfortable margin. The result that matters more than the accuracy number itself is that the same network also reconstructed the satellite tiles from each of its internal layers using the identical weights it used for classification, a capability none of the comparison methods in that experiment offer at all. For a satellite monitoring pipeline running on constrained hardware at the edge, getting both a land use label and a visual reconstruction from one compact model is a meaningfully different proposition than needing two separate networks to do the same two jobs.
Reading the honest limitations
The authors are refreshingly direct about where this stands. The entire premise of local learning is that every layer can update in parallel, but nothing in this paper was actually run on hardware built to exploit that parallelism. Every experiment ran as a standard sequential PyTorch training loop on a single GPU, which means the efficiency argument for DBPC is currently theoretical rather than measured in wall clock training time. Until someone runs this on neuromorphic hardware or a genuinely parallel compute architecture, the parallel learning benefit remains a promise the algorithm’s structure supports rather than a number anyone has clocked.
There is also an architectural quirk worth flagging. The output layer in a classification network is necessarily small, ten neurons for a ten class problem, which is plenty of room to represent a class label but not much room to represent enough visual detail to reconstruct a complex image well. That squeeze is part of why reconstruction quality drops so sharply in the deepest layers, and the authors point toward population coding techniques, representing information across a larger group of neurons rather than a compact one, as a possible fix they have not yet tried.
Finally, the accuracy gap on CIFAR-10 is real and worth sitting with. Every predictive coding method tested, DBPC included, lands well behind the best backpropagation trained networks on this harder dataset, roughly 74 percent against the low nineties for a strong ResNet. The authors are candid that predictive coding style approaches generally still trail purpose built classifiers on visually complex, natural image tasks, and they frame closing that specific gap, along with adding standard regularization techniques like dropout and batch normalization, as their next research target.
Reproducing the local learning rule in PyTorch
The paper implements DBPC in PyTorch already, but it uses the automatic differentiation engine to compute the local errors, which can obscure just how local the actual information flow is. The code below builds a small fully connected DBPC network from first principles, making the feedforward prediction, feedback prediction, and the two local error signals fully explicit, then runs a short training loop on synthetic data so you can see the whole learning rule execute end to end without needing MNIST on hand.
This version deliberately keeps each layer’s update self contained, right down to computing a fresh gradient for a single weight matrix at a time, rather than letting PyTorch’s autograd engine trace a path across the entire network the way a typical training script would. That is the whole point of local learning made visible in code. Scale the layer sizes up, swap in real MNIST batches, and add the convolutional padding rule from the paper’s Equation 9 for image data, and this same structure becomes a working reproduction of DBPC-FCN.
Why this matters beyond the benchmark numbers
Step back from the specific accuracy figures and the more durable contribution here is a demonstration that local learning does not have to mean choosing between doing one task well or doing two tasks poorly. Prior predictive coding work had shown local learning could support classification, and separately that it could support reconstruction, but usually at the cost of doubling the parameters or falling back on ordinary backpropagation somewhere in the pipeline. Showing that one shared weight matrix, updated entirely from local information, can do both jobs at a level competitive with dedicated classifiers is a meaningfully different result than incremental accuracy gains on yet another MNIST leaderboard entry.
The practical argument for caring about this sits squarely with edge computing. A drone, a wearable sensor, or a small robot that needs to both recognize what it is looking at and hold onto enough of a representation to reconstruct or compress that input for later transmission would otherwise need two separate networks, doubling memory and compute demands on hardware that already has very little of either to spare. A single compact network handling both jobs, trained through a process that could in principle run its updates in parallel across layers rather than waiting on a full forward and backward pass, is a genuinely useful target for that kind of constrained deployment, even if the parallel hardware to fully cash in on that benefit is not something most people have sitting on their desk yet.
Limitations worth keeping in view
None of this should be read as predictive coding having caught up to backpropagation across the board. The CIFAR-10 gap is real, the parallel hardware benefit is unmeasured, and the reconstruction quality in deeper layers is genuinely weak compared to the earlier layers. There is also a narrower question the paper does not fully settle, whether the specific choice to zero out the feedback factor during representation learning, which stabilized training here, might be quietly limiting how much the reconstruction objective can actually shape what the network learns to represent. The authors flag exploring nonzero feedback factors as future work rather than a solved problem, which is an honest way to leave it.
Conclusion
What Deep Bidirectional Predictive Coding demonstrates is that the old assumption behind most local learning research, that abandoning global error backpropagation means accepting a real performance penalty, is not as fixed a tradeoff as it once looked. By letting the same weight matrix run forward as a classifier and backward as a decoder, and by keeping every layer’s learning signal confined to its immediate neighbors, the authors built networks that beat every other predictive coding method tested while frequently using a fraction of the parameters.
The conceptual move worth remembering here is the reuse of one matrix in two directions rather than training a mirrored encoder and decoder pair. That single choice is what keeps the parameter counts so low across MNIST, Fashion-MNIST, and CIFAR-10, and it is also what makes the biological analogy more than just marketing language, since a real synapse does not maintain two entirely separate weight values for two entirely separate purposes either.
Whether this approach can close the remaining gap with backpropagation on genuinely complex, high resolution natural images is still an open question, and the CIFAR-10 numbers make clear there is real distance left to cover. The EuroSAT results are an encouraging signal that the method holds up reasonably well outside of small toy datasets, which matters more than another fraction of a percent on MNIST ever could.
The honest limitations, no parallel hardware measurements, a reconstruction quality that degrades in deeper layers, and a persistent accuracy gap on harder natural image datasets, all point toward a method still early in its development rather than one ready to replace backpropagation in production systems. The authors’ own stated next steps, adding dropout and batch normalization, exploring nonzero feedback factors, and extending the approach to temporal data, read like a reasonable and fairly modest roadmap rather than an overreaching one.
If nothing else, this paper is a useful data point for anyone tracking whether biologically inspired learning rules can eventually offer a genuine alternative to backpropagation rather than just an academically interesting curiosity. The gap has not closed, but on this evidence it is narrowing from a direction, shared weights doing double duty, that most prior work had not fully explored.
Frequently asked questions
What problem does Deep Bidirectional Predictive Coding actually solve
It lets a single neural network perform both image classification and image reconstruction using one shared set of weights, trained entirely through local learning rules rather than standard error backpropagation, which normally requires a global error signal to travel through the whole network.
How does one set of weights handle two different directions
Each layer uses its weight matrix as is to predict the next layer’s activity, feedforward, and uses the transpose of that same matrix to predict the previous layer’s activity, feedback. No separate encoder and decoder pathway is trained.
What accuracy did the method achieve
The convolutional version reached 99.58 percent on MNIST, 92.42 percent on Fashion-MNIST, 74.29 percent on CIFAR-10, and 92.56 percent on the EuroSAT satellite image dataset, each using a notably small network compared to standard classifiers.
Does training for both tasks hurt classification accuracy
The paper’s ablation study found the opposite for classification, jointly training on both objectives produced slightly higher accuracy than training for classification alone, 98.87 percent against 98.60 percent on MNIST, though reconstruction quality in the joint model was noticeably lower than in a model trained only for reconstruction.
Is this ready to replace backpropagation in real systems
Not yet. The parallel learning benefit has not been measured on hardware built to exploit it, reconstruction quality drops sharply in deeper layers, and the method still trails leading backpropagation trained networks on harder datasets like CIFAR-10. The authors present it as a promising step rather than a finished replacement.
Why would anyone want a network that does both classification and reconstruction
Devices with limited memory and compute, like drones, wearables, or small robots, benefit from one compact model doing two jobs instead of two separate networks. The same shared representation used to recognize an object can also be used to reconstruct or compress the input it saw.
Read the full open access paper, including every equation, the complete hyperparameter tables, and the class activation map visualizations, at Neural Networks.
Read the paper View on ScienceDirectThe full source paper, including the complete architecture tables, the heatmaps showing how the classification and reconstruction factors interact, and the Grad-CAM++ interpretability visualizations, is available through its DOI at doi.org/10.1016/j.neunet.2025.107785. It is published open access under a Creative Commons license.
Qiu, S., Bhattacharyya, S., Coyle, D. and Dora, S. Deep predictive coding with bi-directional propagation for classification and reconstruction. Neural Networks 191, 107785 (2025). This analysis is based on the published paper and an independent evaluation of its claims.