
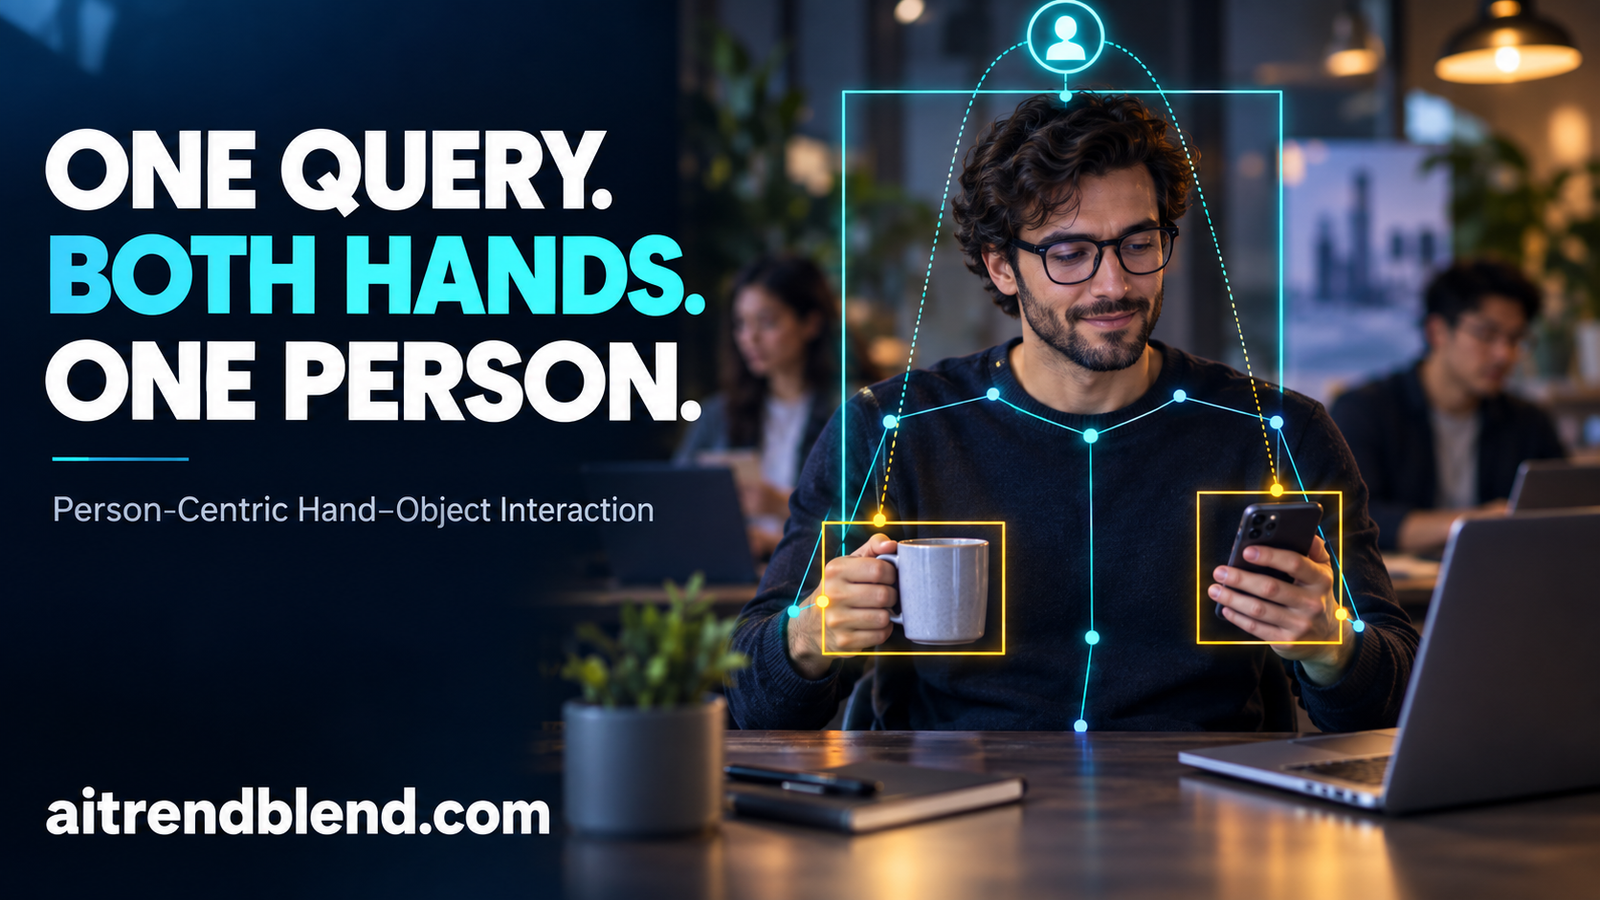
Watch two people shake hands at a reception while a third pours a drink nearby, and your eye never loses track of whose hand is whose. A detector does. Most hand detectors find hands one at a time as separate objects, so in a busy frame they can spot every hand correctly and still have no idea which two belong to the same person, or that the left hand holding a bouquet and the right hand gripping a glass are the same individual. That confusion is the problem this paper sets out to fix.
Key points
- The method reframes hand object interaction as a person centric task, where one query predicts an entire person at once, the body box, the pose, both hand boxes and states, and what each hand interacts with.
- A part aware deformable attention scheme lets a single query attend to body level, hand level, and joint level regions, so it can localize a large body and two small hands together.
- Instead of regressing an object box for each hand, each hand selects its target from the set of detected queries plus a learnable off token, directly recovering the target’s box and class.
- That relation based selection roughly doubled the strictest tuple accuracy, lifting the medium metric from 44.9 to 60.8 and the hard metric from 12.6 to 28.9 against direct box regression.
- Adding body pose supervision and part aware references was decisive, pulling the hard metric from about 10 up to 31 once the model attends to the right local regions.
- The team built a COCO based dataset with person centric bimanual annotations and a structured metric that penalizes assigning a hand to the wrong person, which hand centric scores ignore.
Why detecting hands is not the same as understanding them
Hands are the main interface between people and the physical world, so a vision system that can parse which person uses which hand to manipulate which object is useful for action understanding, learning from demonstration, assistive perception, and robots that learn by watching. The field has made real progress at the level of a single hand. A representative line of work predicts, for each hand, its bounding box, which side it is, its contact state, and the box of the object it touches. Later work expanded that to object segments, second objects touched through tools, and grasp categories.
Here is the limitation that runs underneath all of it. These formulations are hand centric. They treat each hand as an independent instance and never explicitly couple the left and right hands under a shared person. In a single person photo that is fine. In a multi person scene it breaks, because the model can detect every hand and every interaction and still fail to say which two hands belong to the same person. The authors put the mismatch precisely. The prediction unit is an independent hand, but the interpretation unit a human actually cares about is a person with two hands interacting with things. Those are not the same object, and optimizing the first does not give you the second.
This is a familiar shape of problem in detection. The broader human object interaction literature, and transformer detectors that reason over object queries, have shown that you get cleaner structure when the model predicts relationships directly rather than stitching them together afterward. This work carries that instinct down to the level of one person and two hands, and it sits squarely in the lineage of transformer models that predict structure directly rather than post processing it.
The core problem. A hand centric detector can be right about every hand and still wrong about every person. Ownership, which hand goes with which body, is exactly the information that gets lost when hands are predicted as independent objects.
One query owns the whole person
The fix, from the AI Lab in LG Electronics’ CTO Division, is a person centric structured prediction framework built on a DETR style set prediction detector. The human instance becomes the primary prediction unit, and the left and right hands are attached to it as two explicit slots. A single query predicts all the outputs for one instance at once, the human box, the body pose, the left and right hand boxes and states, and each hand’s interaction target.
In the underlying detector there are many object queries, and each one can turn out to represent either a human or a plain object. When a query is classified as a person, it fires a set of extra heads that a normal detector does not have. It predicts body keypoints for the pose, left and right hand boxes, and a pair of hand embeddings that will be used for interaction reasoning. Because everything for one person flows from one query, the left hand and the right hand can never drift onto different bodies. They are, by construction, the same person’s hands. That single design choice is what makes the ownership problem disappear.
Teaching one query to see a body and two hands at once
The immediate technical challenge is that a person is large and a hand is tiny, and one query has to localize both. A standard attention scheme tuned for the body will smear over the hands, and one tuned for hands will lose the body. The answer is part aware deformable attention, which gives a single query several reference regions to look at rather than one.
For each person query, the model builds reference points from the main box and both hand boxes.
where the function maps a box to a reference point such as its center. On top of that it adds a reference region for each body joint, centered on the predicted joint and sized by scaling the main box.
The decoder’s attention heads are then spread across these references, so one query attends jointly to the body, the hands, and the joints while it refines its prediction. The ablation shows this is not a nicety but the load bearing part. Strip the part aware allocation out and let all heads share the main box reference, and pose accuracy collapses from the low sixties to about forty two, while the strictest hand metric falls off a cliff. The lesson is blunt. A single query can carry a whole person only if you tell it where on the person to look.
Selecting the target instead of drawing it
The second idea is the more elegant one. Once you know a hand is in contact with something, how do you say what it is touching? The obvious route is to regress a bounding box for the interacting object from the hand. But a regressed box does not tell you the object’s class, and in a crowded scene it is hard to line that box up with the actual entity, which might be an object or even another person’s hand.
So the model does not draw the target. It picks it. Every final query embedding is projected to a relation embedding, and a single learnable off token is added to represent no contact. For each hand, the model scores that hand’s embedding against every candidate target with a dot product, then takes a softmax over all of them.
The choice the hand makes carries the whole interpretation. Selecting the off token means no contact. Selecting the query’s own person means self contact, a hand touching its own body. Selecting any other query means contact with another entity, which can be an object or another person. And because every query already predicts a box and a class, choosing target query means you instantly inherit that target’s bounding box and semantic label, with no separate object regression at all. The interaction, the target location, and the target class all fall out of one selection.
This is the same move that makes relation based detectors clean. Rather than inventing a new output, the model reuses the entities it already detected and just points at the right one. It mirrors the structured, per instance reasoning seen in work like handing a model a scene as a set of identifiable entities to point at, applied here to hands choosing their targets.
Building the data nobody had
A person centric formulation needs person centric labels, and no existing dataset had hand boxes, hand contact, object boxes and classes, human boxes, and body keypoints all together. So the team built one on top of COCO, which was the right base for two reasons. It has diverse multi person scenes, and it already provides object detection annotations and human keypoints, so person level interaction structure could be assembled without re annotating everything from scratch.
Hand annotations came from Hands23, and the clever part is aligning those hands to the right COCO person. The pipeline uses wrist guided geometric matching. For a person and a hand side, it measures the distance between the person’s wrist keypoint and the hand box center, and accepts a match only when that distance is small relative to the hand size and the hand box sits inside a slightly expanded person box.
Rule based matching goes wrong under occlusion and overlap, so a verification stage follows, using a vision language model with the full image, a local crop, and a relative depth map from a monocular depth model for front to back ordering. It runs a conservative no guessing policy, labeling each case contact, no contact, or uncertain, and simply throwing out the uncertain ones. A manual audit on 770 samples put the uncertain rate at 1.3 percent and cut the annotation error rate from 2.5 percent to 2.1 percent after verification, with two annotators agreeing 98.4 percent of the time. The remaining errors are the genuinely hard cases, blurry or very small hands and depth ambiguous configurations.
Just as important as the data is a metric that measures the right thing. The authors define three progressively stricter scores. The soft metric checks hand state accuracy over matched persons. The medium metric additionally requires the interacted object to be localized correctly when a hand is holding something. The hard metric further requires the hand box itself to be localized correctly. Crucially, these scores penalize cross person hand assignment and left or right slot confusion, the exact failures that a hand centric metric never notices.
What the numbers say
The experiments use an RT-DETR based detector with the added person centric heads. The most revealing comparison is between drawing the object box and selecting it, both without pose supervision.
| Method | Det mAP | Soft | Medium | Hard |
|---|---|---|---|---|
| Direct box regression | 49.1 | 81.5 | 44.9 | 12.6 |
| Relation based selection | 48.8 | 80.0 | 60.8 | 28.9 |
Look at the medium and hard columns. Selecting the target instead of regressing a box lifts the medium metric from 44.9 to 60.8 and the hard metric from 12.6 to 28.9, roughly a doubling on the strictest tuple correctness. Detection mAP barely moves, and soft accuracy dips a shade on COCO, which tells you the relation formulation is not buying raw detection, it is buying correct association and localization of the whole human hand object tuple. That is precisely the thing the person centric task is about.
Adding body pose supervision and part aware references stacks on top of that, and the full configuration is the strongest.
| Method | Det mAP | Pose AP | Soft | Medium | Hard |
|---|---|---|---|---|---|
| Direct box | 49.1 | N/A | 81.5 | 44.9 | 12.6 |
| Direct box + pose | 47.7 | 61.8 | 83.0 | 57.6 | 30.1 |
| Relation | 48.8 | N/A | 80.0 | 60.8 | 28.9 |
| Relation + pose | 47.1 | 62.3 | 83.8 | 64.6 | 31.3 |
Pose supervision helps both formulations, which supports the paper’s hypothesis that understanding body structure strengthens hand reasoning. It does cost a little detection mAP, the familiar tension in multi task learning where two objectives pull on shared features, but the consistent gains in the medium and hard metrics say the trade is worth it for the person centric goal.
The part aware attention ablation is the one that shows how fragile the whole thing is without it.
| Configuration | Det mAP | Pose AP | Medium | Hard |
|---|---|---|---|---|
| Without part aware references | 48.6 | 42.8 | 63.6 | 10.3 |
| With part aware references | 47.1 | 62.3 | 64.6 | 31.3 |
Without part aware references the hard metric is 10.3. With them it is 31.3, a threefold jump, and pose accuracy climbs from 42.8 to 62.3 at the same time. The medium metric barely moves, which makes sense, because medium does not require precise hand localization while hard does. The message is that once the evaluation insists on precise hand boxes, attending to the correct local regions is not optional. A small drop in detection mAP is a cheap price for that.
Key takeaway. Two ideas do the heavy lifting. Selecting the target instead of regressing it fixes association, and part aware attention fixes localization. Together they move the strict tuple metric from the low teens to the low thirties.
Where it still struggles
The honest weak spot is crowding, and the paper measures it directly by splitting the validation set on how many people are in each image.
| People in image | Soft | Medium | Hard |
|---|---|---|---|
| 1 person | 90.28 | 79.42 | 54.00 |
| 2 to 4 people | 86.58 | 67.31 | 33.09 |
| 5 or more people | 75.84 | 56.17 | 22.02 |
The model is strong on single and moderately crowded scenes and clearly weaker once five or more people share a frame, where the hard metric more than halves from the single person case. Severe occlusion, overlapping hands, and small visible hand regions remain the real challenge, which is a little ironic since resolving ownership in a crowd was the original motivation. It is better at it than a hand centric model would be, but crowding is still where the gains thin out.
Two more caveats matter for reading the results. The training labels are built by rule based alignment between two datasets and then filtered, so despite the careful verification the supervision carries some residual noise, and the validation set is a manually annotated slice of about 2,000 images rather than a large independent benchmark. And this is a preprint with a public project page but not yet peer review, so the numbers are strong early evidence rather than a settled result. The authors also note that adding pose costs a little detection accuracy, an honest acknowledgment that the unified query is a set of compromises, not a free lunch.
Why the approach travels
Strip away the hands and this is a general recipe for structured, per instance prediction. When the thing you care about is a composite, a person with parts, a vehicle with components, a scene with related entities, making one query own the whole composite prevents the parts from drifting apart, and letting that query select its relations from the detected set rather than regress them keeps association clean and classes intact. The part aware attention idea, giving one query several reference regions so it can see a whole and its parts at once, would carry to any task where a single instance spans very different scales.
It also fits the broader momentum in detection toward reasoning over queries rather than boxes alone, the same current running through recent work on structure guided object detection and relation based transformer detectors generally. The specific contribution here is to make the person, not the hand, the first class unit, and to supply both the dataset and the tuple level metric that make that shift measurable.
Reference implementation in PyTorch
The code below is a runnable reconstruction of the two central ideas, the part aware reference points and the relation based hand to target selection, based on the paper’s equations. A small query set with per query heads stands in for the full RT-DETR decoder so the file runs without weights. It builds body, hand, and joint reference points for each query, projects queries to relation embeddings, adds a learnable off token, scores each hand against every candidate, and decodes the selection into no contact, self contact, or contact with a specific target query. A smoke test runs it on dummy tensors. Swap in the real detector and dataset for actual experiments.
# single_query_bhoi_reference.py
# Reconstruction of part aware references and relation based hand target selection.
# Replace QuerySetStub with an RT-DETR decoder for real experiments.

import torch
import torch.nn as nn
import torch.nn.functional as F

N_JOINTS = 17   # COCO style keypoints
D = 256        # query embedding dim


class PersonHeads(nn.Module):
    """Per query heads. Any query may be person or object."""
    def __init__(self, d=D, n_classes=80):
        super().__init__()
        self.cls = nn.Linear(d, n_classes + 1)      # + person class
        self.box = nn.Linear(d, 4)                  # cx, cy, w, h
        self.hand_box = nn.Linear(d, 8)             # left and right, 4 each
        self.pose = nn.Linear(d, N_JOINTS * 2)        # joint centers
        self.hand_embed = nn.Linear(d, 2 * d)        # left and right hand embeddings

    def forward(self, z):                            # z: (B, N, d)
        B, Nq, _ = z.shape
        hb = self.hand_box(z).view(B, Nq, 2, 4)
        he = self.hand_embed(z).view(B, Nq, 2, -1)
        return {
            "cls": self.cls(z), "box": self.box(z).sigmoid(),
            "hand_box": hb.sigmoid(), "pose": self.pose(z).view(B, Nq, N_JOINTS, 2).sigmoid(),
            "hand_embed": he}


def part_aware_references(box, hand_box, pose, gamma_w, gamma_h):
    """Build body, hand, and joint reference points for each query."""
    p_body = box[..., :2]                          # center of the main box, Eq 1
    p_hand = hand_box[..., :2]                     # (B, N, 2, 2) left and right centers
    w, h = box[..., 2:3], box[..., 3:4]
    # joint reference regions sized by scaling the main box, Eq 2
    s_w = gamma_w.view(1, 1, -1) * w
    s_h = gamma_h.view(1, 1, -1) * h
    p_joint = pose                                    # joint centers, (B, N, J, 2)
    joint_size = torch.stack([s_w, s_h], dim=-1)     # (B, N, J, 2)
    return p_body, p_hand, p_joint, joint_size


class RelationHead(nn.Module):
    """Each hand selects a target from the query set plus an off token."""
    def __init__(self, d=D):
        super().__init__()
        self.to_relation = nn.Linear(d, d)               # r_i = project(z_i)
        self.off = nn.Parameter(torch.randn(d))          # learnable off embedding r_0

    def forward(self, z, hand_embed):
        B, Nq, d = z.shape
        r = self.to_relation(z)                          # (B, N, d)
        off = self.off.view(1, 1, d).expand(B, 1, d)
        cand = torch.cat([off, r], dim=1)             # (B, N+1, d), index 0 is off
        # dot product score of each hand against every candidate target
        scores = torch.einsum("bnsd,bcd->bnsc", hand_embed, cand)  # (B, N, 2, N+1)
        return scores.softmax(-1)


def decode_interaction(prob, query_index):
    """Turn a selection into no contact, self contact, or a target query."""
    sel = prob.argmax(-1)                            # (B, N, 2), 0 means off
    out = []
    B, Nq, _ = sel.shape
    for b in range(B):
        for i in range(Nq):
            for s, name in enumerate(["L", "R"]):
                j = sel[b, i, s].item()
                if j == 0:
                    state = "no_contact"
                elif j - 1 == i:
                    state = "self_contact"
                else:
                    state = f"contact_with_query_{j - 1}"   # inherit that query box and class
                out.append((b, i, name, state))
    return out


class QuerySetStub(nn.Module):
    """Stand in for the RT-DETR decoder. Produces N query embeddings."""
    def __init__(self, n_query=30, d=D):
        super().__init__()
        self.q = nn.Parameter(torch.randn(n_query, d))

    def forward(self, B):
        return self.q.unsqueeze(0).expand(B, -1, -1)


if __name__ == "__main__":
    B = 2
    qset, heads, rel = QuerySetStub(), PersonHeads(), RelationHead()
    gamma_w = torch.rand(N_JOINTS) * 0.3
    gamma_h = torch.rand(N_JOINTS) * 0.3
    z = qset(B)
    pred = heads(z)
    refs = part_aware_references(pred["box"], pred["hand_box"], pred["pose"], gamma_w, gamma_h)
    prob = rel(z, pred["hand_embed"])
    interactions = decode_interaction(prob, query_index=None)
    print("queries", z.shape[1], "selection prob", tuple(prob.shape))
    print("example interactions", interactions[:4])
    n = sum(p.numel() for m in [qset, heads, rel] for p in m.parameters())
    print("parameters", round(n / 1e6, 2), "M")
Conclusion
The core achievement here is a shift of unit. By making the person, not the hand, the thing a single query predicts, the method dissolves the ownership problem that hand centric detectors carry into every crowded scene. One query holds the body box, the pose, both hands, and each hand’s target, so left and right can never be assigned to different people. On the strict tuple metrics that actually test this, relation based target selection roughly doubled accuracy over box regression, lifting the medium score from 44.9 to 60.8 and the hard score from 12.6 to 28.9.
The conceptual move worth keeping is that association is cleaner as selection than as regression. Instead of drawing a box for the object a hand touches and then trying to reconcile it with the scene, the hand points at an already detected entity and inherits its box and class for free. A learnable off token folds no contact into the same mechanism, and self contact and other person contact fall out of which query gets chosen. It is a tidy reformulation that removes a whole regression head and its ambiguity along with it.
The part aware attention result is the quiet lesson underneath. A single query can only carry a whole person if it is told where to look, and the threefold jump in the hard metric when part aware references are switched on shows how much of the performance lives in that detail. This idea, one query with several reference regions spanning very different scales, is the piece most likely to transfer to other composite prediction tasks.
The honest limitations keep it in proportion. This is a preprint, its training labels come from rule based cross dataset alignment with some residual noise, its validation set is a small manually annotated slice, and its performance clearly thins out in scenes of five or more people, which is exactly the crowded regime the work set out to conquer. It handles ownership better than a hand centric model, but crowding is still the frontier.
For anyone building structured detectors, the practical message is compact. When your unit of interpretation is a composite, predict it as one query rather than assembling parts after the fact. Let relations be selected from the entities you already detected instead of regressed from scratch. And when one instance spans a large body and small parts, give the query a map of reference regions so it can attend to all of them at once. The project page is public, and the reference above is a place to start testing the idea on a structure of your own.
Frequently asked questions
What is person centric hand object interaction detection?
It is a way of parsing hand interactions where the unit of prediction is a whole person rather than an individual hand. A single model output covers the human box, body pose, both hand boxes and states, and what each hand is interacting with, so the left and right hands stay tied to the same person even in a multi person scene.
Why do hand centric detectors struggle in crowds?
Hand centric detectors treat each hand as an independent object and do not explicitly link the two hands of one person. In a crowded frame they can detect every hand correctly yet still fail to say which two hands belong to the same body, which is the ownership confusion this work is designed to remove.
How does the relation matrix replace object box regression?
Instead of regressing a bounding box for the object a hand touches, each hand selects its target from the set of already detected queries plus a learnable off token, using a dot product score followed by a softmax. Selecting off means no contact, selecting the hand’s own person means self contact, and selecting any other query recovers that target’s box and class directly, with no separate object regression.
How much did the new formulation improve accuracy?
Against direct box regression without pose, relation based selection lifted the medium metric from 44.9 to 60.8 and the hard metric from 12.6 to 28.9. Adding body pose supervision and part aware references pushed the full model further, to 64.6 medium and 31.3 hard, while part aware references alone raised the hard metric from 10.3 to 31.3.
What data was the model trained on?
The team built a COCO based dataset, aligning hand annotations from Hands23 to COCO people with wrist guided geometric matching, then verifying matches with a vision language model and a monocular depth map. The result provides hand boxes, hand contact labels, object boxes and classes, human boxes, and body keypoints together, with a manually annotated validation split of about 2,000 images.
What are the main limitations?
It is an unreviewed preprint, its training labels come from rule based cross dataset alignment that carries some residual noise, and its validation set is a small manual slice. Accuracy also drops in scenes with five or more people, where severe occlusion, overlapping hands, and small hand regions remain the hardest cases.
Read the source and the project page
This analysis draws on the preprint. You can also reach it through the inline link earlier in this article, at arXiv:2609.12155.
Read the paper on arXiv Visit the project pageAcademic citation. Kim, J., Roh, J., Yoon, Y., Lee, H., Park, J., Hwang, T., Kim, J., and Lee, J. Single-Query Person-Centric Bimanual Hand-Object Interaction Detection. arXiv preprint arXiv:2609.12155, 2026. AI Lab, CTO Division, LG Electronics. Project page at https://lgecto-ail-vil.github.io/SingleQuery-BHOI/. Paper at https://arxiv.org/abs/2609.12155.
This analysis is based on the published paper and an independent evaluation of its claims. The paper is a preprint and has not completed peer review.