Adnan Saeed

Adnan Saeed is a deep learning researcher working on medical image analysis, with a focus on multimodal architectures, graph neural networks, and evidential deep learning for clinical imaging tasks. His peer reviewed research has appeared in journals across machine learning and biomedical signal processing. At AI Trend Blend he turns recent papers into clear, practical explainers, with an emphasis on what a method actually does and where it holds up, written for readers who want depth without the hype.

Comparison graph showing WER reduction in CTC ASR using context-dependent ILM vs. traditional methods.

Unlock 13% Better Speech Recognition: How Label-Context-Dependent ILM Estimation Shatters CTC Limits

Connectionist Temporal Classification (CTC) powers countless speech recognition systems. But here’s the dirty secret: its “context-independent” assumption is a myth. Modern encoders do learn context-dependent patterns, and ignoring this wastes potential. This paper reveals how to harness this hidden power,…

Unlock 13% Better Speech Recognition: How Label-Context-Dependent ILM Estimation Shatters CTC Limits Read More »

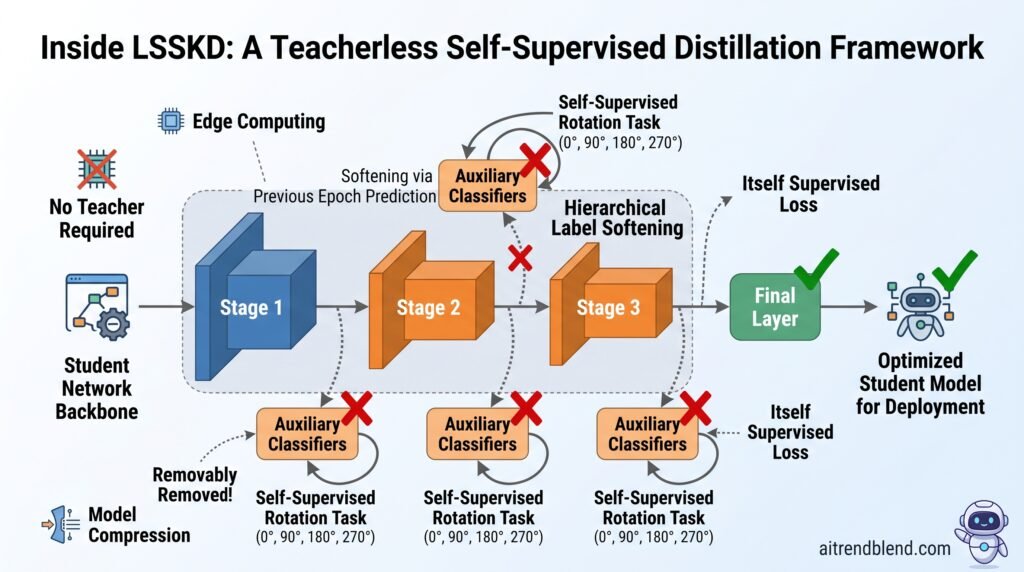
Inside LSSKD, a Self Supervised Distillation Framework That Trains Small Models Without a Teacher

Inside LSSKD, a Self Supervised Distillation Framework That Trains Small Models Without a Teacher

Knowledge distillation has a well known shape. Train a large, accurate teacher model. Train a small student model to mimic the teacher’s softened output probabilities, using the temperature trick Geoffrey Hinton popularized, rather than only the ground truth labels. The…

Inside LSSKD, a Self Supervised Distillation Framework That Trains Small Models Without a Teacher Read More »

Molecular dynamics simulation speed comparison using traditional vs. new knowledge distillation framework.

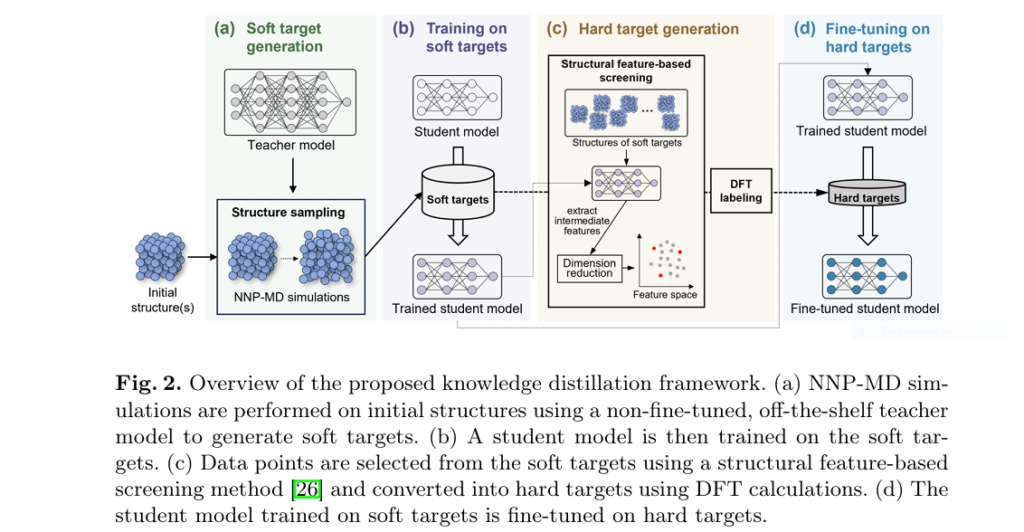
Knowledge Distillation: Why an Untuned Teacher Model Trains Better MD Potentials

Neural network potentials, NNPs for short, have become the go to tool for simulating how atoms move and interact without running full quantum mechanical calculations for every timestep. They learn the potential energy surface, essentially a map of how much…

Knowledge Distillation: Why an Untuned Teacher Model Trains Better MD Potentials Read More »