Computer Vision

Computer vision is one of our deepest areas, covering how machines learn to see, segment, and reason about images and video. Articles here range from convolutional and transformer based architectures to dense prediction tasks like detection and segmentation, with regular coverage of medical imaging where reliable vision models carry real clinical weight. The emphasis stays on what makes a method work and where it breaks, backed by the original research.

The Moon's Many Faces: A Single Unified Transformer for Multimodal Lunar Reconstruction

The Moon’s Many Faces: A Single Unified Transformer for Multimodal Lunar Reconstruction

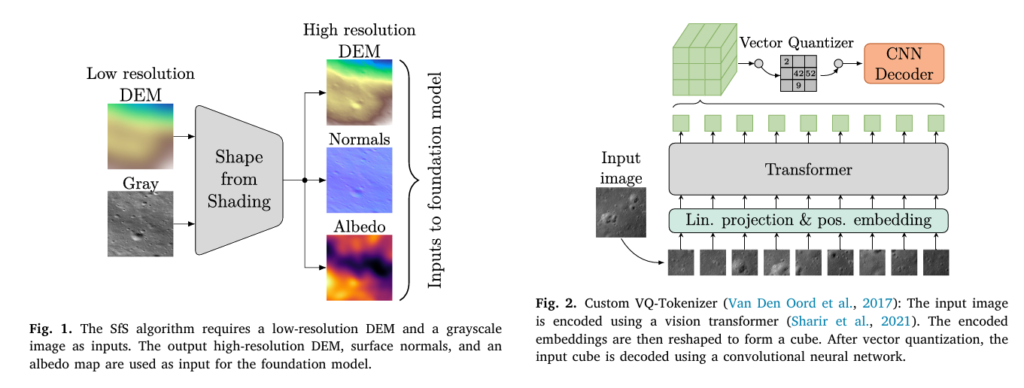
A team at TU Dortmund built a single 29.7-million-parameter foundation model that can translate any combination of lunar data — grayscale images, elevation maps, surface normals, and albedo — to any other, all in a single forward pass. The key…

The Moon’s Many Faces: A Single Unified Transformer for Multimodal Lunar Reconstruction Read More »
CS-EMCF: Compressive Sensing Phase Unwrapping for SAR Interferometry.

CS-EMCF: Compressive Sensing Phase Unwrapping for SAR Interferometry

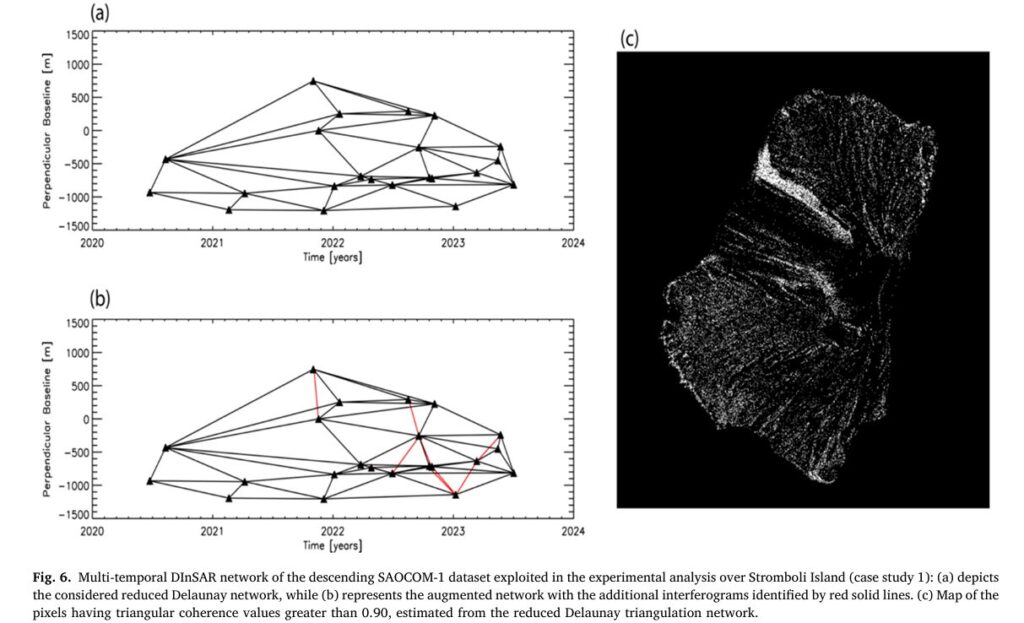
Researchers at Italy’s CNR-IREA fused decades-old minimum cost flow theory with modern compressive sensing to build a phase unwrapping algorithm that detected a 40 cm volcanic displacement at Stromboli that the classic EMCF method simply could not recover — and…

CS-EMCF: Compressive Sensing Phase Unwrapping for SAR Interferometry Read More »

Fusion-Mamba: Hidden State Space Fusion for Cross-Modality Object Detection

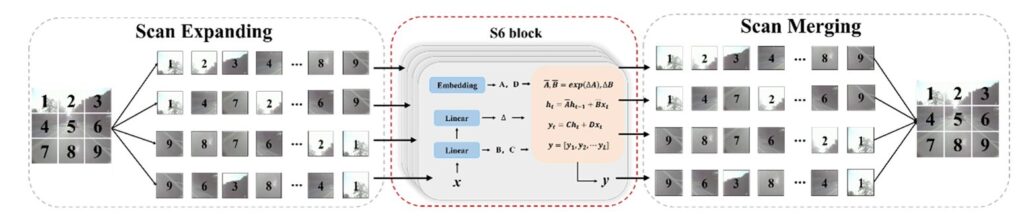
Fusion-Mamba: Hidden State Space Fusion for Cross-Modality Object Detection

Researchers at Beihang University asked what happens when you stop treating cross-modal fusion as a spatial alignment problem and start treating it as a state-space modeling problem. The answer outperforms every transformer-based fusion method while running faster — by mapping…

Fusion-Mamba: Hidden State Space Fusion for Cross-Modality Object Detection Read More »

IRDFusion: Iterative Differential Feedback for Multispectral Object Detection.

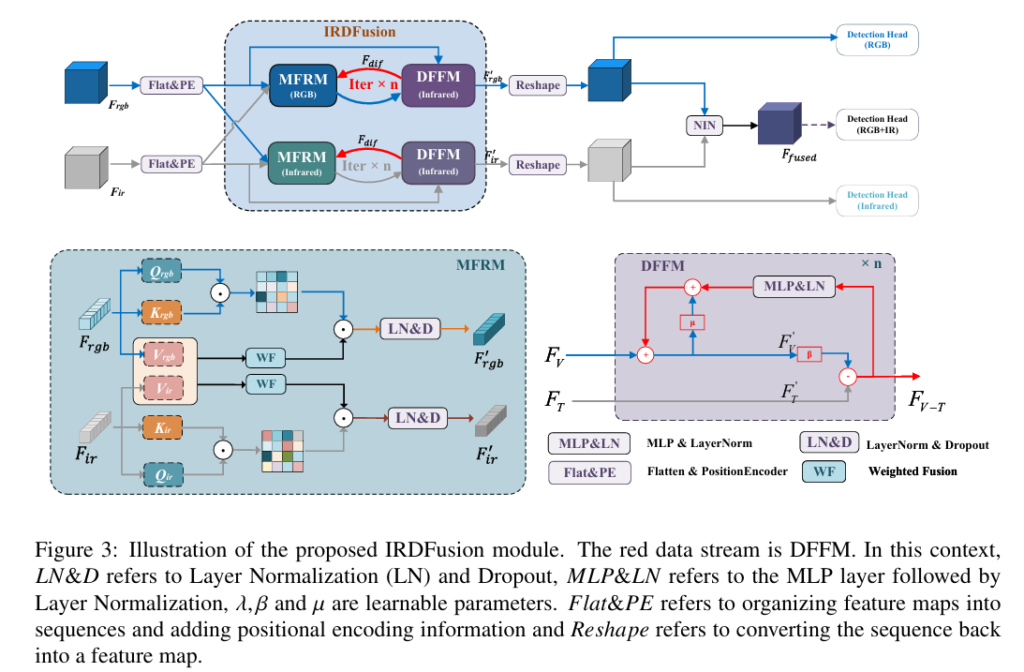
IRDFusion: Iterative Differential Feedback for Multispectral Object Detection

Researchers at Jiangsu University asked a simple question: what if we treated cross-modal feature fusion the same way electrical engineers treat differential amplifiers? The answer — IRDFusion — hits 88.3 mAP50 on FLIR and works as a plug-and-play module inside…

IRDFusion: Iterative Differential Feedback for Multispectral Object Detection Read More »

SLGNet: Structural Priors and Language-Guided Modulation for Multimodal Object Detection.

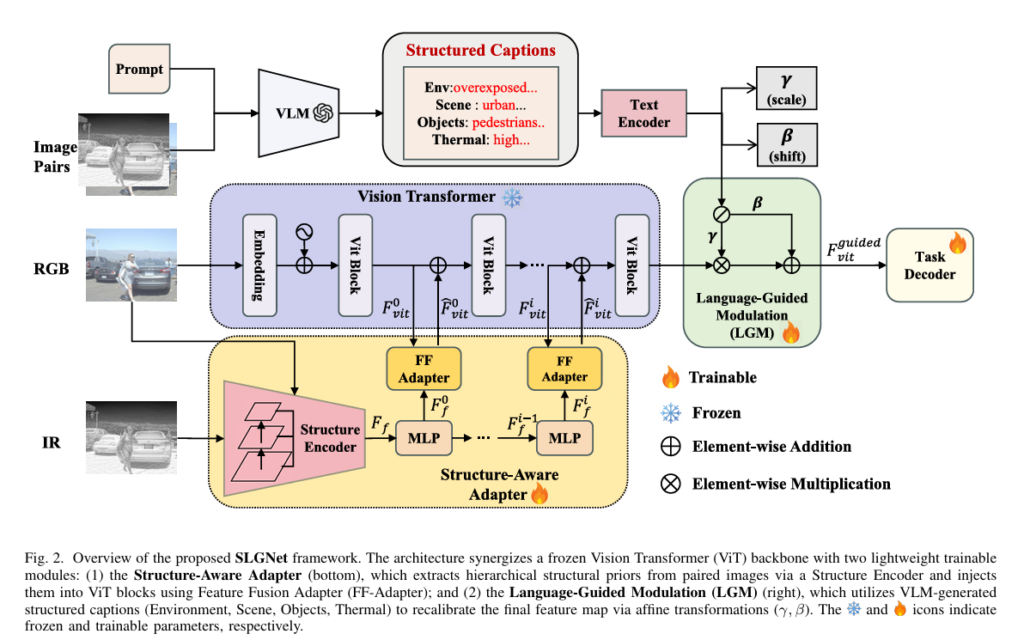
SLGNet: Structural Priors and Language-Guided Modulation for Multimodal Object Detection

Researchers at the Chinese Academy of Sciences built a multimodal object detector that freezes 88% of its parameters, asks a language model to describe the scene, and still beats every fully fine-tuned competitor — including on aerial drone footage at…

SLGNet: Structural Priors and Language-Guided Modulation for Multimodal Object Detection Read More »

HMHI-Net: Hierarchical Memory with Heterogeneous Interaction for Video Object Segmentation.

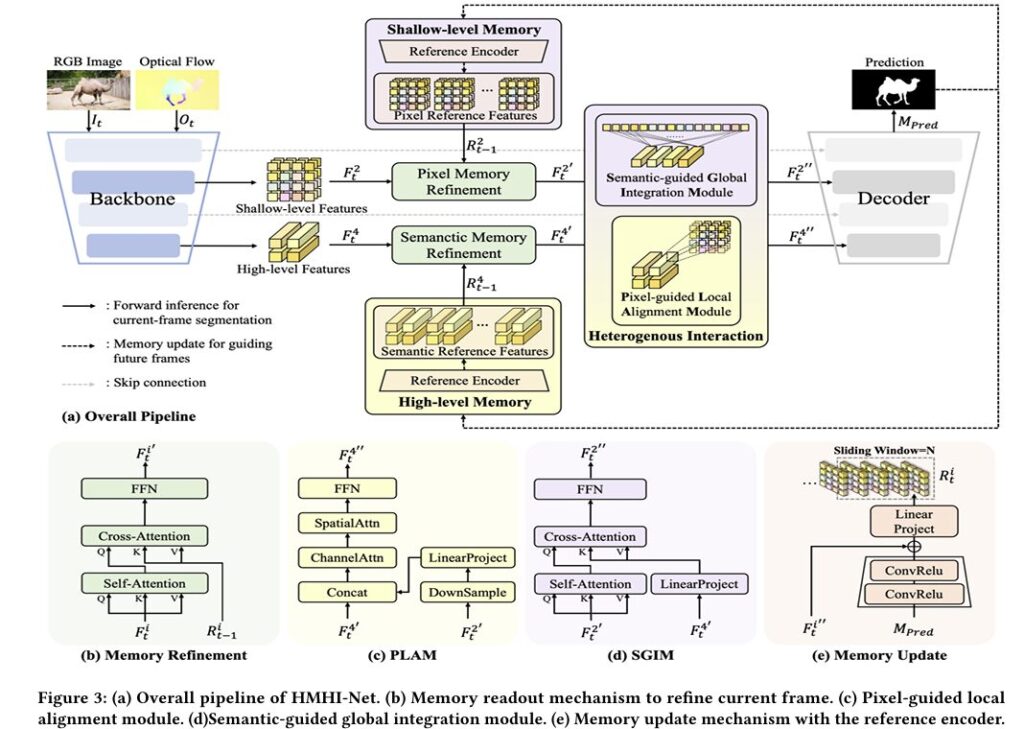
HMHI-Net: Hierarchical Memory with Heterogeneous Interaction for Video Object Segmentation

Fudan University researchers discovered that every existing memory-based video segmentation method makes the same mistake — memorizing only high-level semantic features while discarding the fine-grained pixel details that unsupervised segmentation desperately needs. Their fix, HMHI-Net, reaches 89.8% J&F on DAVIS-16,…

HMHI-Net: Hierarchical Memory with Heterogeneous Interaction for Video Object Segmentation Read More »

FedLSC: Federated Learning with Layer Similarity Comparison for Skin Cancer.

FedLSC: Federated Learning with Layer Similarity Comparison for Skin Cancer

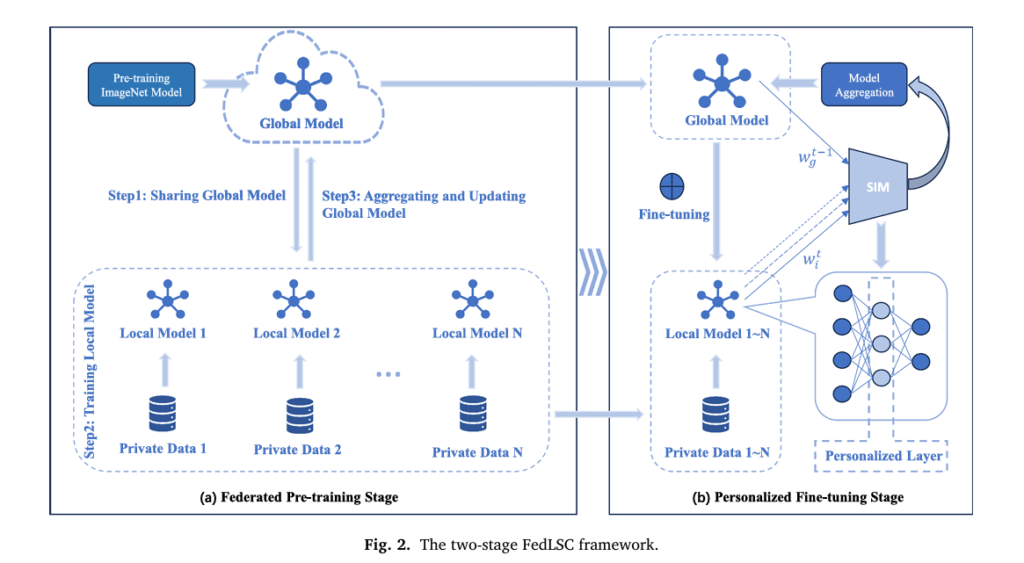
Researchers at Southwest University built a two-stage federated learning framework that measures how similar different hospitals’ model updates are — layer by layer — then uses that similarity to allocate smarter aggregation weights and automatically pick which layers to keep…

FedLSC: Federated Learning with Layer Similarity Comparison for Skin Cancer Read More »

BGPANet: How Bi-Granular Progressive Attention Cracked the Skin Cancer Diagnosis Problem

BGPANet: How Bi-Granular Progressive Attention Cracked the Skin Cancer Diagnosis Problem

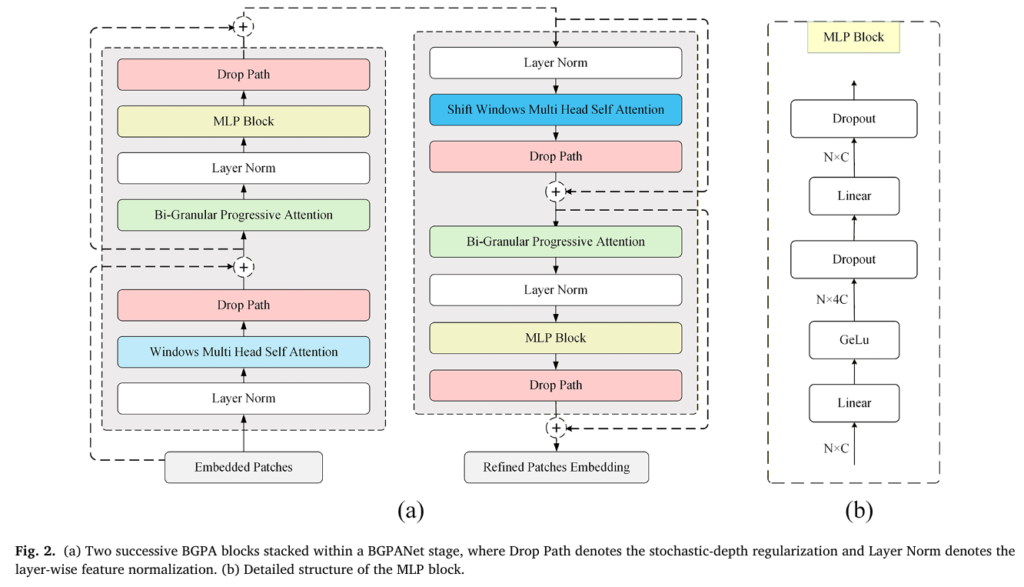
How a research team from Changchun University designed a network that mimics the “local-first, global-second” reasoning of expert clinicians — and in doing so, achieved state-of-the-art accuracy on two major skin cancer benchmarks while solving the imbalanced data problem that…

BGPANet: How Bi-Granular Progressive Attention Cracked the Skin Cancer Diagnosis Problem Read More »