Knowledge Distillation

Knowledge distillation is how a small, fast model learns to behave like a large, accurate one, keeping most of the quality while shedding the cost of running it. This category collects plain language breakdowns of the research that moves the field forward, from the classic KL divergence losses through newer token level and ranking based objectives. Every analysis explains the core idea, the math that makes it work, and the limitations the authors are honest about, and most ship with runnable code you can drop straight into your own training pipeline. It is built for practitioners who want to understand a method well enough to use it, not just cite it.

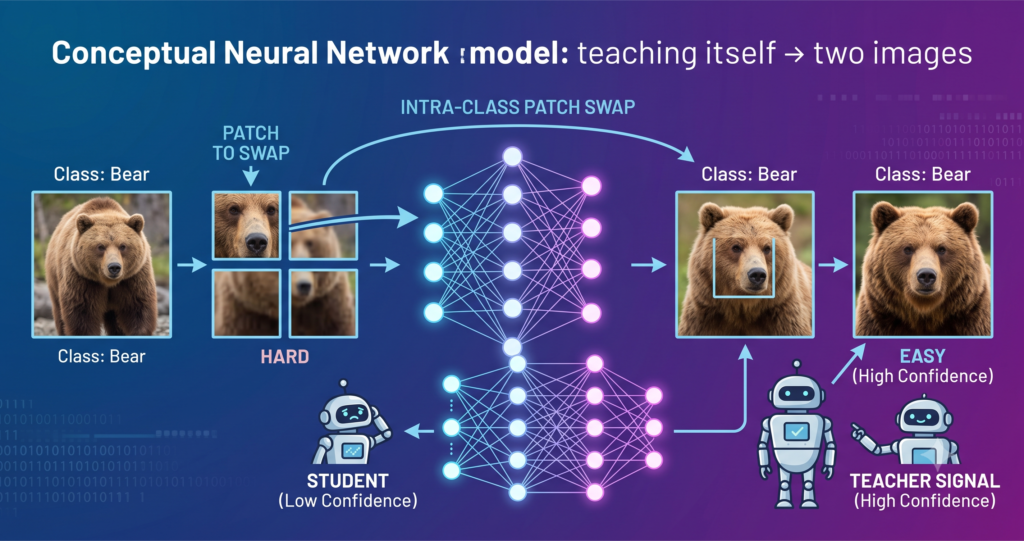
A Single Model Can Now Teach Itself Through Patch Swaps

A Single Model Can Now Teach Itself Through Patch Swaps

Analysis by the aitrendblend editorial team · Pillar 2, Knowledge distillation and model compression · Reading time about 15 minutes knowledge distillation self-distillation data augmentation model compression image classification Swap a patch between two photos of the same animal, and one image quietly becomes the teacher for the other. Training a strong image classifier usually […]

A Single Model Can Now Teach Itself Through Patch Swaps Read More »
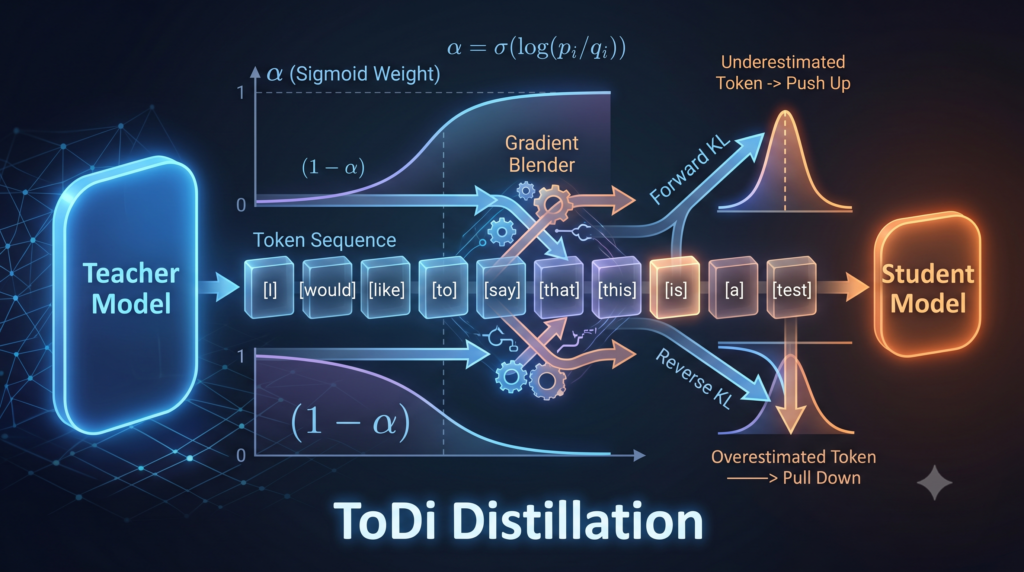
ToDi, Per Token KL Divergence Control for LLM Distillation.

ToDi: Per Token KL Divergence Control for LLM Distillation

Machine Learning › Knowledge Distillation › Paper Analysis Knowledge Distillation Forward KL Reverse KL LLM Compression Instruction Following Paper Analysis Analysis by the aitrendblend editorial team · October 2025 · 13 min read · arXiv:2505.16297 aitrendblend.com · Knowledge Distillation ToDi, Per Token Control of KL Divergence in LLM Distillation A seven billion parameter model writes

ToDi: Per Token KL Divergence Control for LLM Distillation Read More »

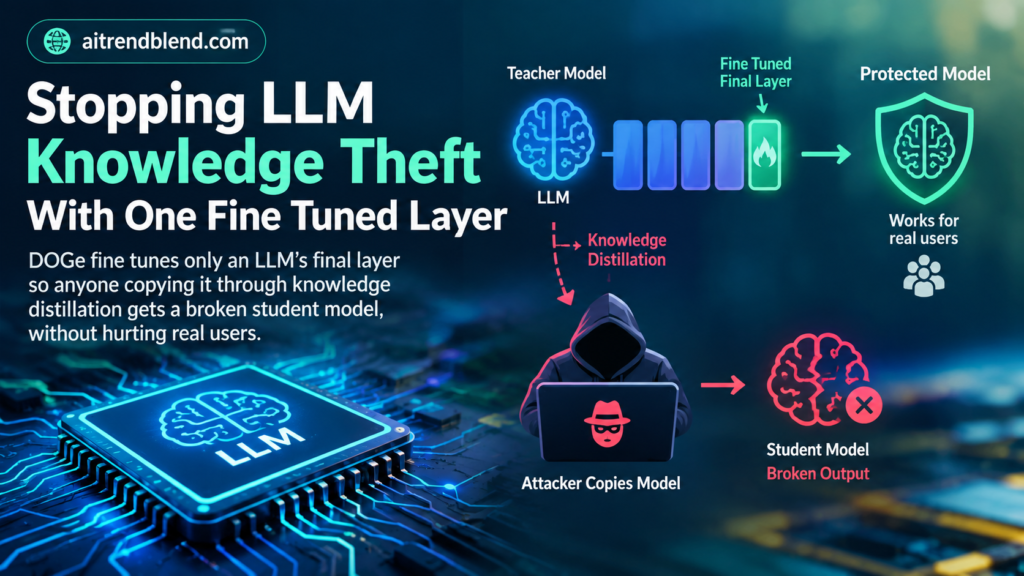
Doge: Stopping LLM Knowledge Theft With One Fine Tuned Layer

Doge: Stopping LLM Knowledge Theft With One Fine Tuned Layer

Analysis by the aitrendblend editorial team · Pillar 2, Knowledge Distillation and Model Compression · 13 minute read Knowledge Distillation Model IP Protection Adversarial Training LLM Security PyTorch DOGe retrains only the final layer of a teacher LLM so that any student model trained on its outputs learns a broken version of its reasoning. A

Doge: Stopping LLM Knowledge Theft With One Fine Tuned Layer Read More »

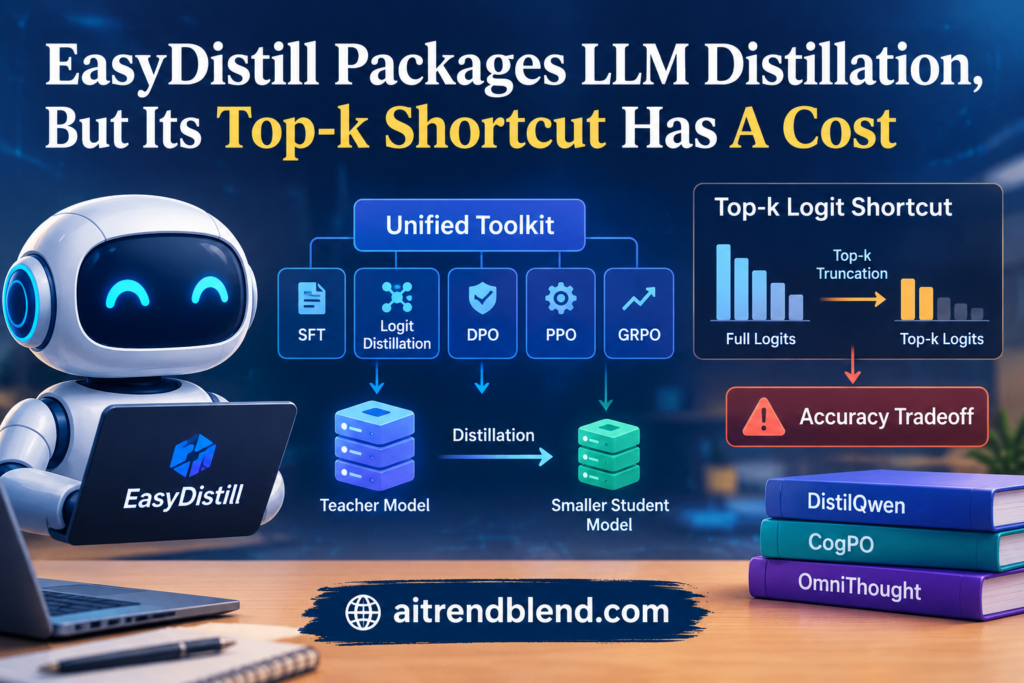
EasyDistill Packages LLM Distillation, But Its Top-k Shortcut Has A Cost

EasyDistill Packages LLM Distillation, But Its Top-k Shortcut Has A Cost

Analysis by the aitrendblend editorial team · Knowledge distillation and model compression · 13 min read LLM distillation Toolkit DistilQwen Alibaba Cloud EasyDistill bundles supervised fine-tuning, logit distillation, preference optimization and reinforcement learning into one command line pipeline for shrinking large language models. Most teams that want a smaller, cheaper version of a large language

EasyDistill Packages LLM Distillation, But Its Top-k Shortcut Has A Cost Read More »

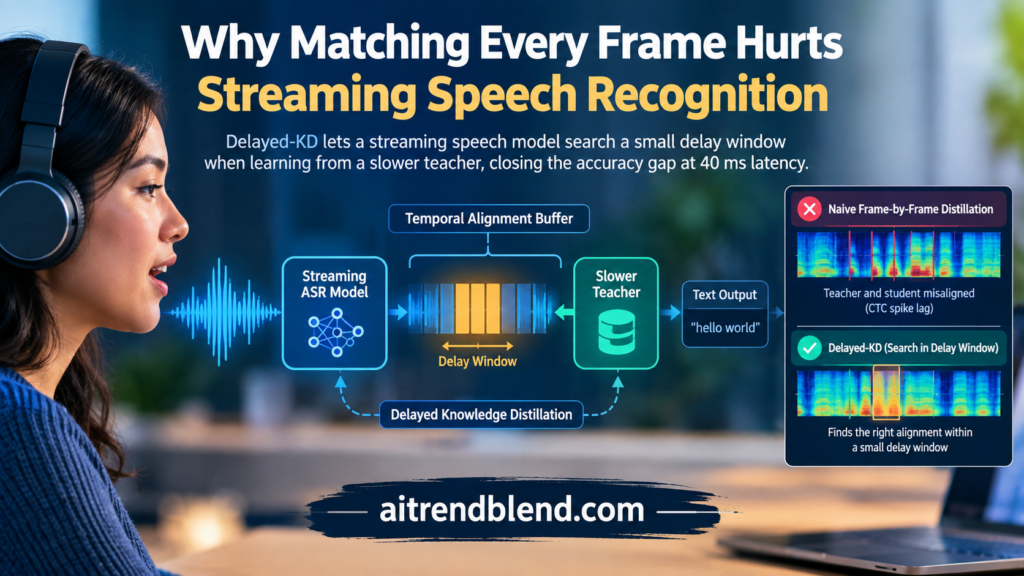
Delayed-KD: Why Matching Every Frame Hurts Streaming Speech Recognition

Delayed-KD: Why Matching Every Frame Hurts Streaming Speech Recognition

Analysis by the aitrendblend editorial team · Knowledge distillation and model compression · 13 min read Streaming ASR Knowledge distillation CTC Low latency A streaming model has to commit to a token before it has heard the rest of the sentence, which is exactly what creates the emission delay this paper targets. A voice assistant

Delayed-KD: Why Matching Every Frame Hurts Streaming Speech Recognition Read More »

Vision-language model distilling knowledge to a compact AI, reducing training costs by 90% with ActiveKD and PCoreSet

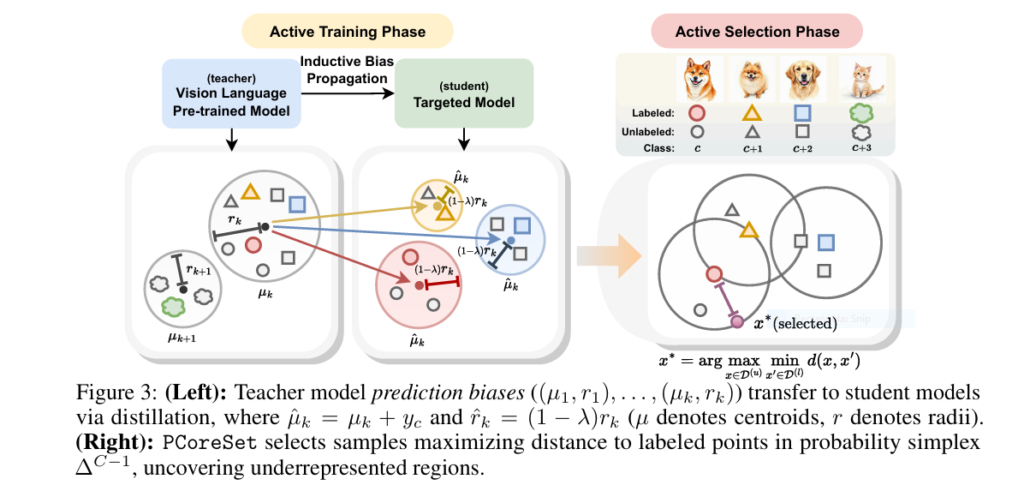
How ActiveKD Uses VLM Bias To Guide Active Learning

Analysis by the aitrendblend editorial team · Pillar, Knowledge distillation and model compression · Source paper, arXiv:2506.00910 Knowledge Distillation Active Learning Vision Language Models CLIP Coreset Selection ActiveKD, one biased teacher, a coreset built in probability space Every active learning paper has the same starting problem. Labeling data is expensive, so you want an algorithm

How ActiveKD Uses VLM Bias To Guide Active Learning Read More »

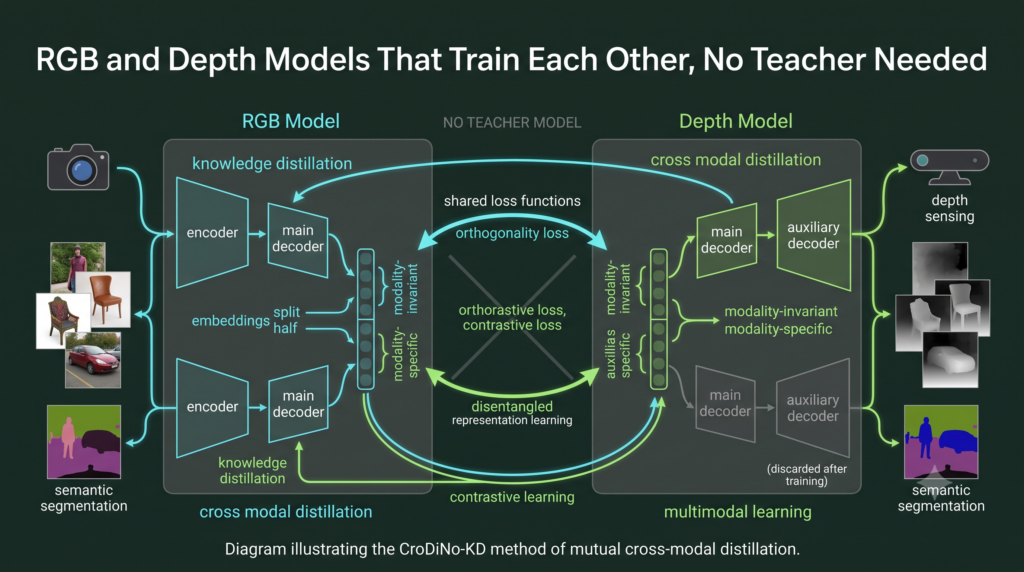
CroDiNo-KD: RGB and Depth Models That Train Each Other, No Teacher Needed

Knowledge Distillation Computer Vision 9 min read Analysis by the aitrendblend editorial team No teacher, no bottleneck. Two students who happen to sit next to each other in class. A robot or a self driving car often sees the world through two eyes that do not match. A camera gives rich color and texture, a

CroDiNo-KD: RGB and Depth Models That Train Each Other, No Teacher Needed Read More »

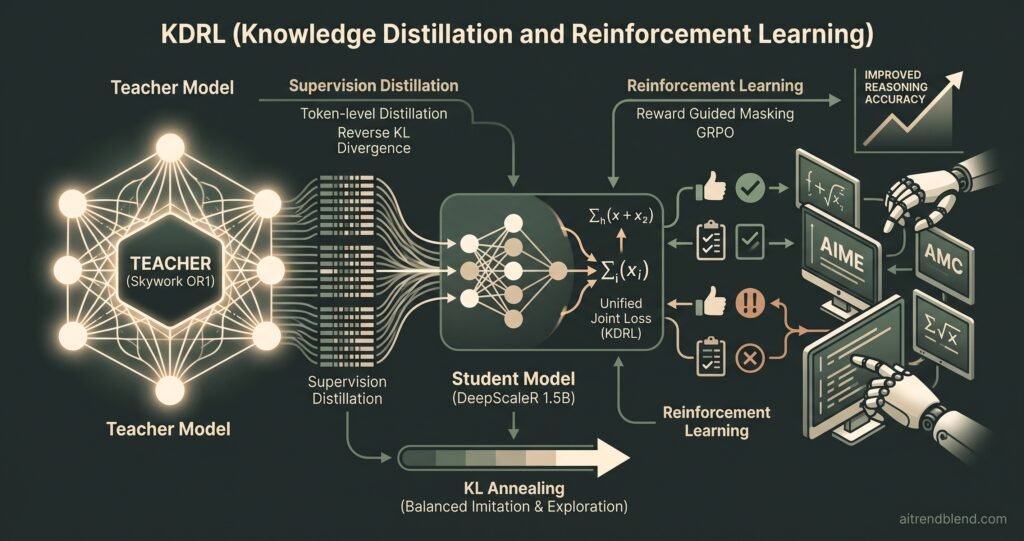
KDRL Unifies Distillation And Reinforcement Learning

KDRL Unifies Distillation And Reinforcement Learning

Analysis by the aitrendblend editorial team · Pillar, Knowledge distillation and model compression · Source paper, arXiv:2506.02208 Knowledge Distillation Reinforcement Learning Reasoning LLMs GRPO Post Training KDRL, one loss, two teachers, teacher supervision and reward explorationKDRL folds teacher supervision and reward driven exploration into a single training objective rather than running them as separate stages.

KDRL Unifies Distillation And Reinforcement Learning Read More »

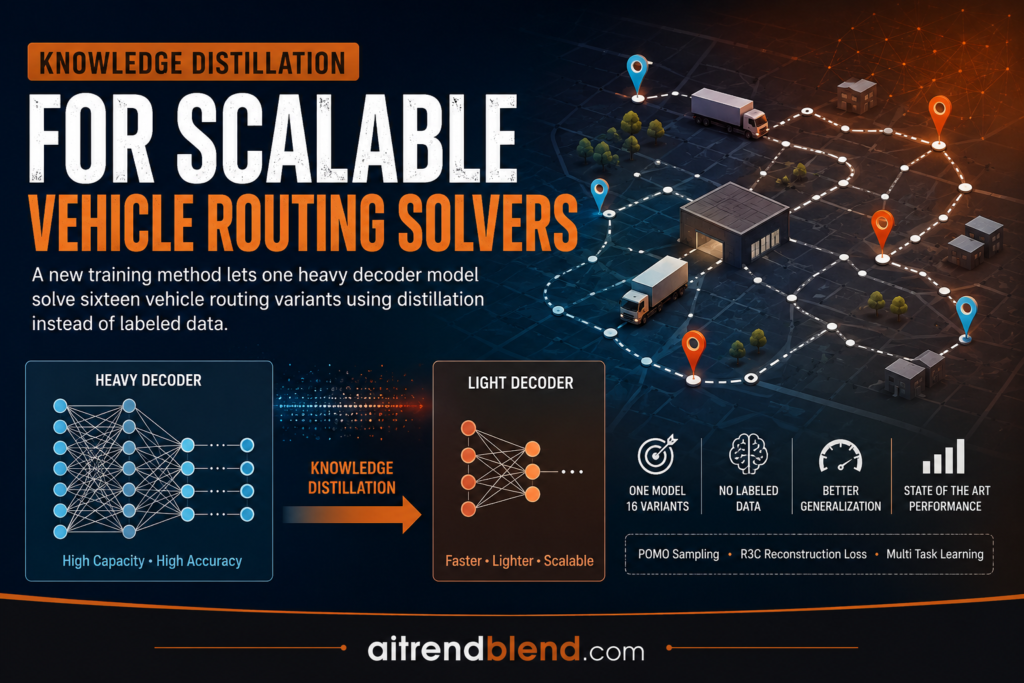
MTL-KD: Knowledge Distillation For Scalable Vehicle Routing Solvers

MTL-KD: Knowledge Distillation For Scalable Vehicle Routing Solvers

Analysis by the aitrendblend editorial team · Pillar, Knowledge distillation and model compression · Source paper, arXiv:2506.02935 Knowledge Distillation Vehicle Routing Multi Task Learning Neural Combinatorial Optimization NeurIPS 2025 MTL-KD, one student model, six teachers, sixteen routing problemsA single heavy decoder model learns to solve sixteen vehicle routing variants by imitating six specialist teacher models

MTL-KD: Knowledge Distillation For Scalable Vehicle Routing Solvers Read More »

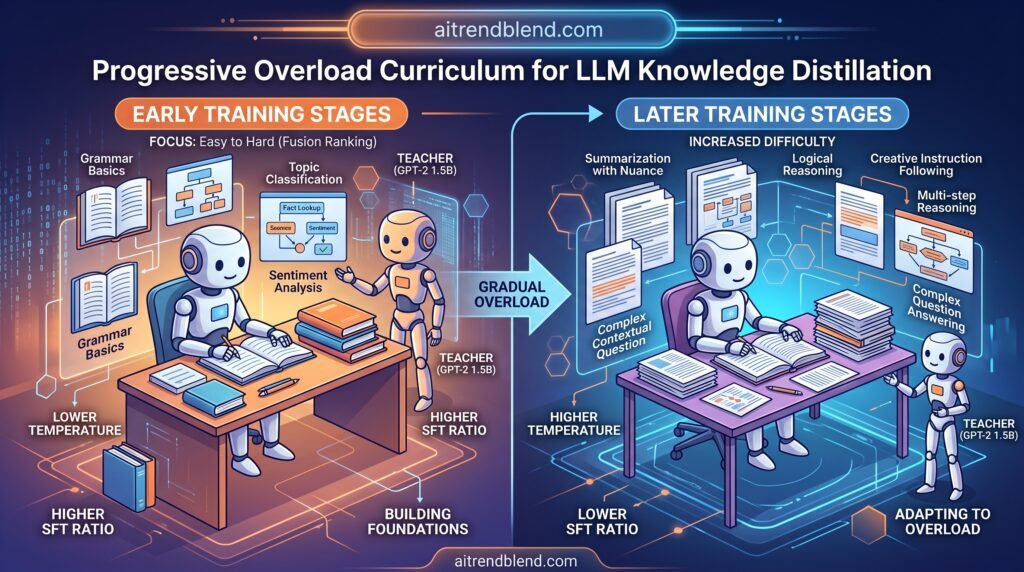
POCL: How A Progressive Overload Curriculum Improves LLM Distillation

POCL: How A Progressive Overload Curriculum Improves LLM Distillation

Knowledge distillation and model compression pillar. Reading time about thirteen minutes. Analysis by the aitrendblend editorial team, no clinical claims are made in this piece. knowledge distillation curriculum learning model compression large language models GPT-2 A new athlete does not start their first day at the gym with the heaviest weight on the bar, and

POCL: How A Progressive Overload Curriculum Improves LLM Distillation Read More »