Knowledge Distillation

Knowledge distillation is how a small, fast model learns to behave like a large, accurate one, keeping most of the quality while shedding the cost of running it. This category collects plain language breakdowns of the research that moves the field forward, from the classic KL divergence losses through newer token level and ranking based objectives. Every analysis explains the core idea, the math that makes it work, and the limitations the authors are honest about, and most ship with runnable code you can drop straight into your own training pipeline. It is built for practitioners who want to understand a method well enough to use it, not just cite it.

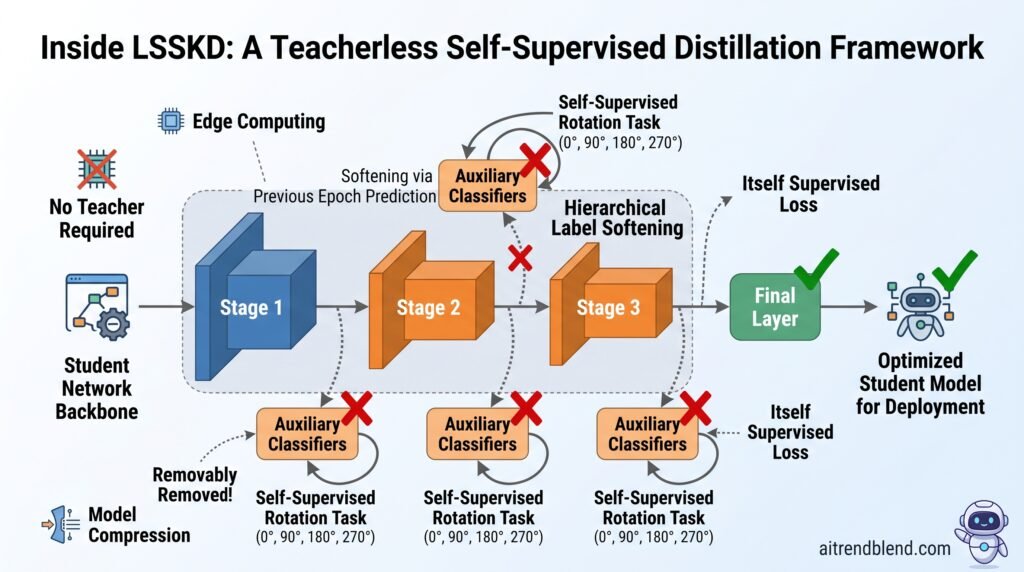
Inside LSSKD, a Self Supervised Distillation Framework That Trains Small Models Without a Teacher

Inside LSSKD, a Self Supervised Distillation Framework That Trains Small Models Without a Teacher

Analysis by the aitrendblend editorial team · Knowledge distillation and model compression · Source, Dahri et al., arXiv 2506.07055, 2025 Knowledge distillation Self supervised learning Edge computing CIFAR 100 LSSKD attaches temporary auxiliary classifiers to a student network during training, then removes every one of them before deployment. Every knowledge distillation paper eventually asks the […]
Inside LSSKD, a Self Supervised Distillation Framework That Trains Small Models Without a Teacher Read More »

PLD: List Wise Knowledge Distillation with Plackett-Luce.

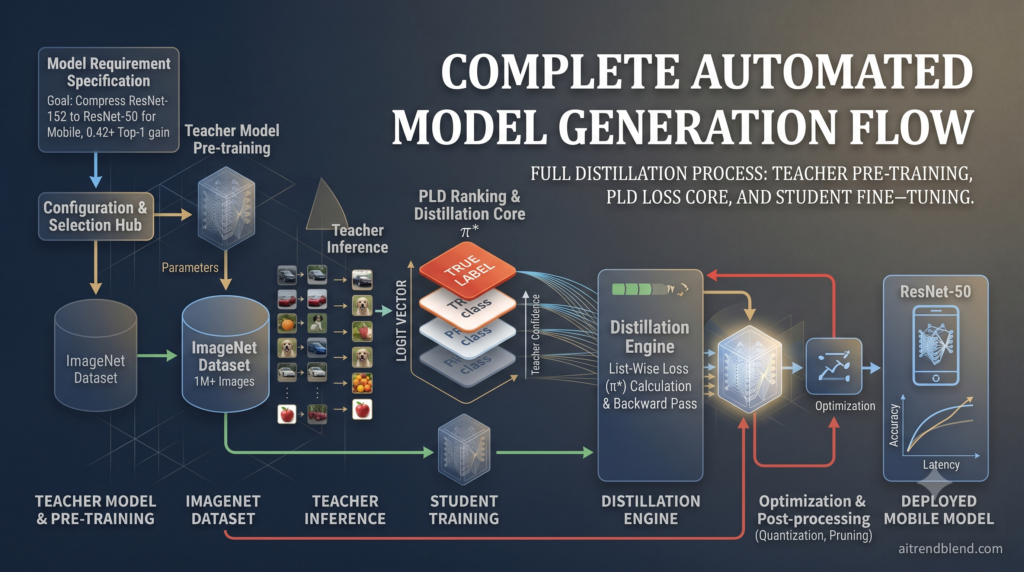
PLD: List Wise Knowledge Distillation with Plackett-Luce

Machine Learning › Knowledge Distillation › Paper Analysis Knowledge Distillation Plackett-Luce List Wise Ranking ListMLE Image Classification Paper Analysis Analysis by the aitrendblend editorial team · October 2025 · 13 min read · arXiv:2506.12542 aitrendblend.com · Knowledge Distillation PLD, List Wise Knowledge Distillation with the Plackett-Luce Model Almost every logit based distillation method shares an

PLD: List Wise Knowledge Distillation with Plackett-Luce Read More »

Molecular dynamics simulation speed comparison using traditional vs. new knowledge distillation framework.

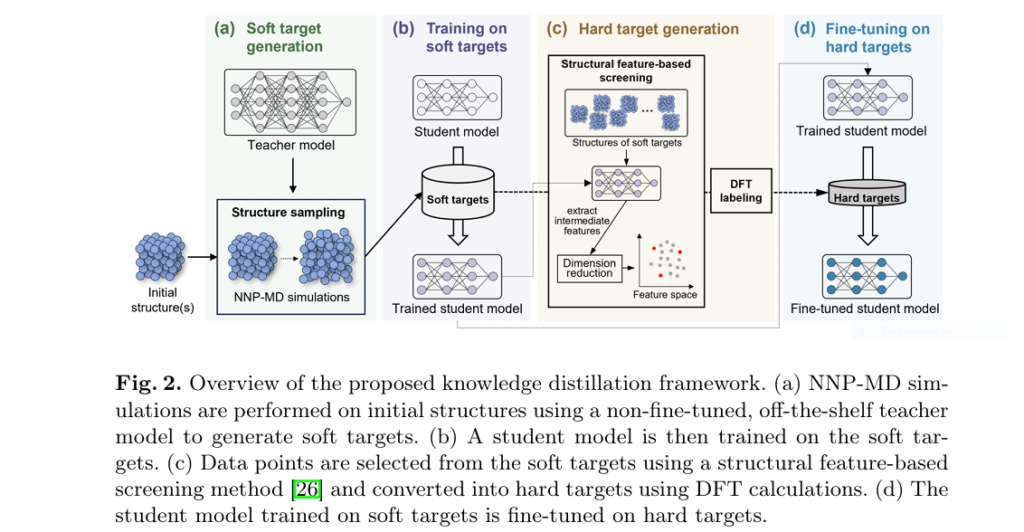
Knowledge Distillation: Why an Untuned Teacher Model Trains Better MD Potentials

Analysis by the aitrendblend editorial team · Pillar, Knowledge distillation methods · Paper arXiv:2506.15337 Knowledge Distillation Neural Network Potentials Molecular Dynamics Materials Simulation Teacher Student Models There is a piece of standard advice in knowledge distillation that everyone takes for granted, get your teacher model as accurate as possible before you let a student learn

Knowledge Distillation: Why an Untuned Teacher Model Trains Better MD Potentials Read More »

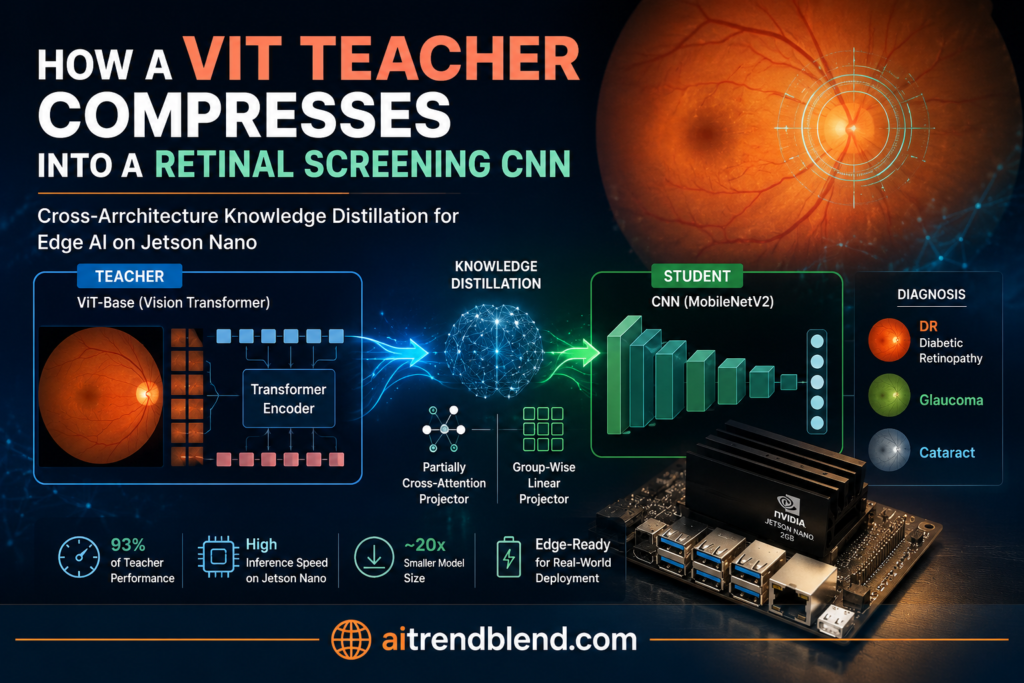
How A ViT Teacher Compresses Into A Retinal Screening CNN

How A ViT Teacher Compresses Into A Retinal Screening CNN (with -80% Fewer Parameters for 3 Diseases)

Knowledge distillation and model compression pillar. Reading time about fourteen minutes. Analysis by the aitrendblend editorial team, no clinical claims are made in this piece. knowledge distillation vision transformers edge AI model compression medical imaging A model small enough to run on a two gigabyte Jetson Nano, trained to mimic one that needed a server-grade

How A ViT Teacher Compresses Into A Retinal Screening CNN (with -80% Fewer Parameters for 3 Diseases) Read More »

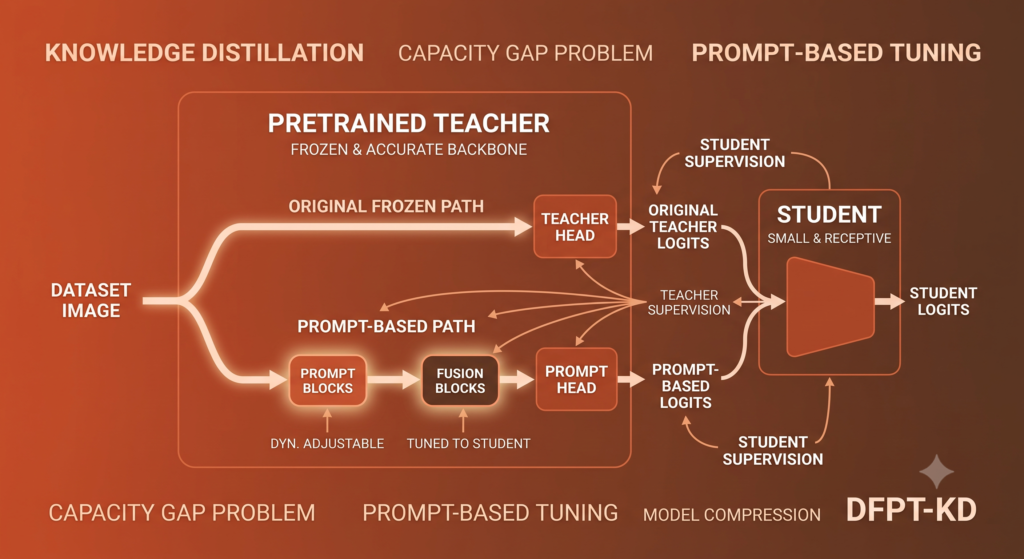
Dual Forward Path Teacher Knowledge Distillation Explained

Analysis by the aitrendblend editorial team · Pillar 2, Knowledge distillation and model compression · Source paper on arXiv, identifier 2506.18244 knowledge distillation capacity gap prompt tuning model compression CIFAR-100 A pretrained teacher with two forward paths, one frozen and accurate, one tuned to match the student. Source, Li et al., 2025. Picture a graduate

Dual Forward Path Teacher Knowledge Distillation Explained Read More »

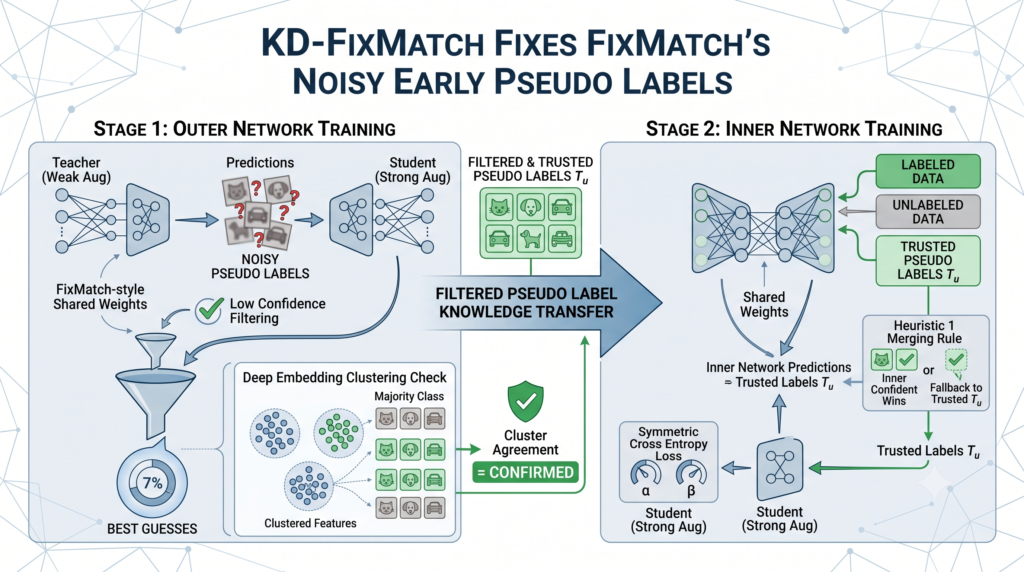
KD-FixMatch Fixes FixMatch's Noisy Early Pseudo Labels.

KD-FixMatch Fixes FixMatch’s Noisy Early Pseudo Labels

Knowledge Distillation Semi Supervised Learning 8 min read Analysis by the aitrendblend editorial team An outer network’s best guesses become the inner network’s head start, once they clear two separate filters. A retailer sorting product photos into defective and acceptable piles runs into a wall almost every computer vision team eventually hits. Good images are

KD-FixMatch Fixes FixMatch’s Noisy Early Pseudo Labels Read More »

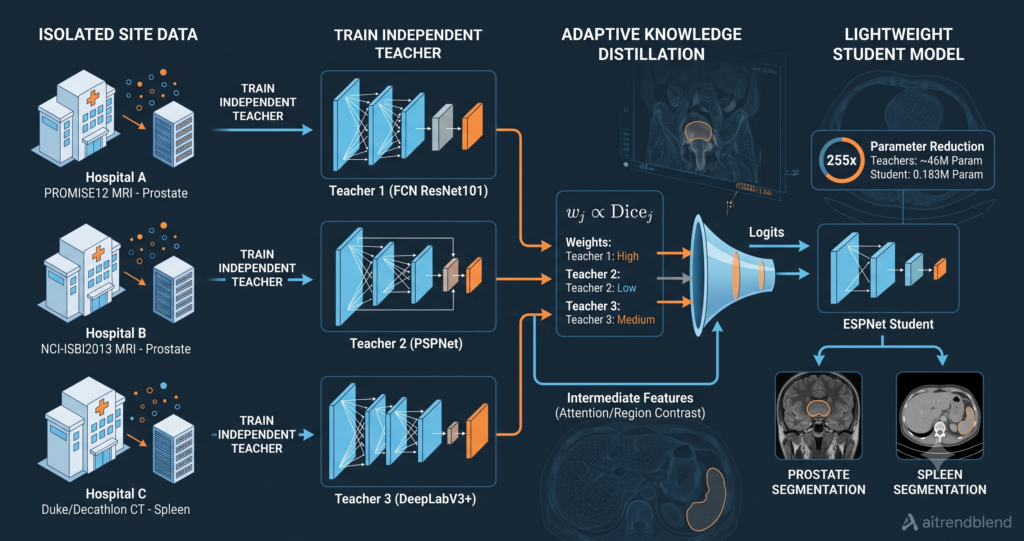
How Adaptive Multi-Teacher Knowledge Distillation Enables Lightweight Medical Segmentation with Limited Site Data.

How Adaptive Multi-Teacher Knowledge Distillation Enables Lightweight Medical Segmentation with Limited Site Data

Analysis by the aitrendblend editorial team. Published originally in Knowledge-Based Systems, volume 315, 2025, article 113196. Open access under a CC BY 4.0 license. Medical Imaging Knowledge Distillation MRI Segmentation CT Segmentation University Rovira i Virgili Adaptive multi-teacher distillation, separate hospital data into a single lightweight segmentation model Three hospitals, three teachers, zero shared patient

How Adaptive Multi-Teacher Knowledge Distillation Enables Lightweight Medical Segmentation with Limited Site Data Read More »