Machine Learning

Machine learning sits at the core of everything we cover at AI Trend Blend. This section gathers our research breakdowns, method explainers, and practical analyses across supervised, self-supervised, and generative learning, with a steady focus on the ideas that actually move results rather than the noise around them. You will find work spanning optimization, model architectures, training dynamics, and the theory that explains why modern systems behave the way they do, written for readers who want depth without filler.

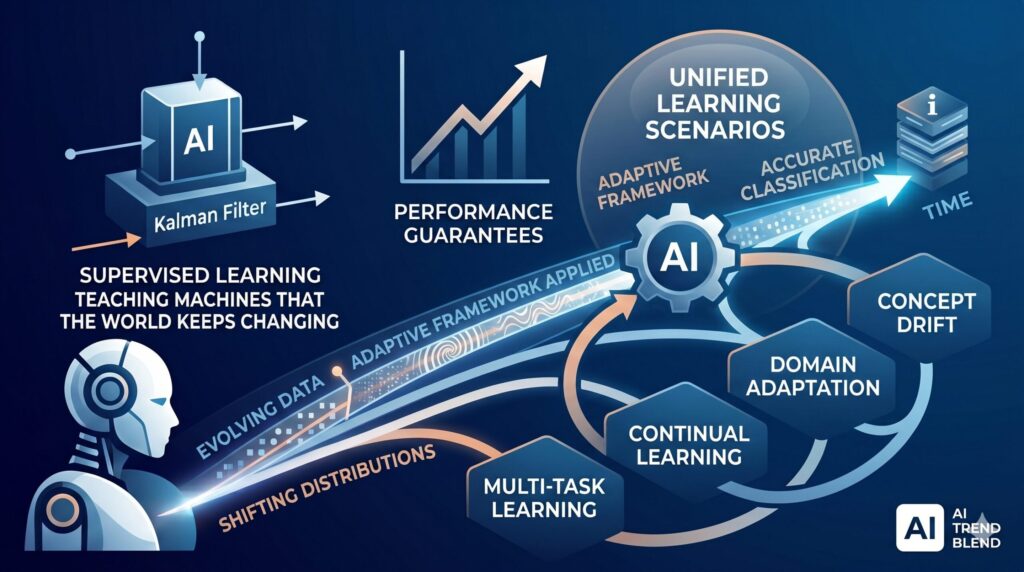
Teaching Machines That the World Keeps Changing: Supervised Learning with Evolving Tasks and Performance Guarantees

Teaching Machines That the World Keeps Changing: Supervised Learning with Evolving Tasks and Performance Guarantees

Verónica Álvarez, Santiago Mazuelas, and Jose A. Lozano show that a single Kalman-filter-based methodology can unify multi-task learning, continual learning, domain adaptation, and concept drift — while being the first to provide computable, tight error-probability guarantees and a closed-form characterization…
Teaching Machines That the World Keeps Changing: Supervised Learning with Evolving Tasks and Performance Guarantees Read More »

An Axiomatic Definition of Hierarchical Clustering: Why Hartigan Was Right All Along.

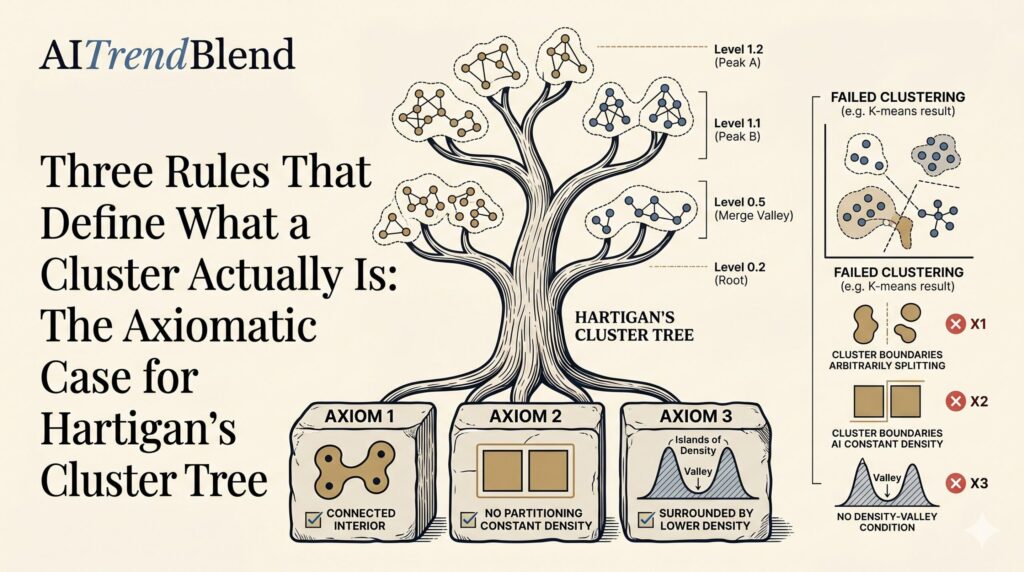
An Axiomatic Definition of Hierarchical Clustering: Why Hartigan Was Right All Along

Ery Arias-Castro and Elizabeth Coda from UC San Diego take an approach inspired by Lebesgue integration — starting from first principles — to show that three intuitive axioms about what a cluster ought to be uniquely recover Hartigan’s cluster tree,…

An Axiomatic Definition of Hierarchical Clustering: Why Hartigan Was Right All Along Read More »

Bayes Meets Bernstein: Why Meta-Learning Finally Gets Fast — A PAC-Bayes Breakthrough.

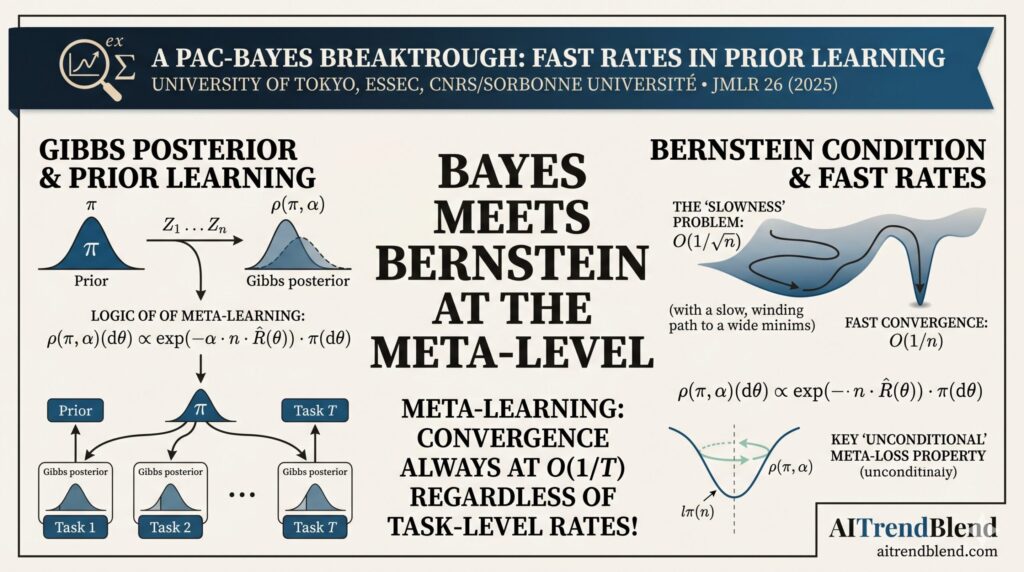
Bayes Meets Bernstein: Why Meta-Learning Finally Gets Fast — A PAC-Bayes Breakthrough

A research team from three leading institutions has proven something nobody expected: when learning a prior across many tasks using the Gibbs algorithm, fast convergence rates are always guaranteed at the meta level — even when individual tasks refuse to…

Bayes Meets Bernstein: Why Meta-Learning Finally Gets Fast — A PAC-Bayes Breakthrough Read More »

Claude Code for Medical Research Pipelines (2026 Guide) — 10 Prompts for Clinical AI Engineering.

Claude Code for Medical Research Pipelines (2026 Guide) — 10 Prompts for Clinical AI Engineering

Clinical data is unlike any other data an engineer works with. It arrives from systems designed for billing and care coordination, not analysis — which means inconsistent coding schemes, free-text fields where structured data should live, observation timestamps that reflect…

Claude Code for Medical Research Pipelines (2026 Guide) — 10 Prompts for Clinical AI Engineering Read More »

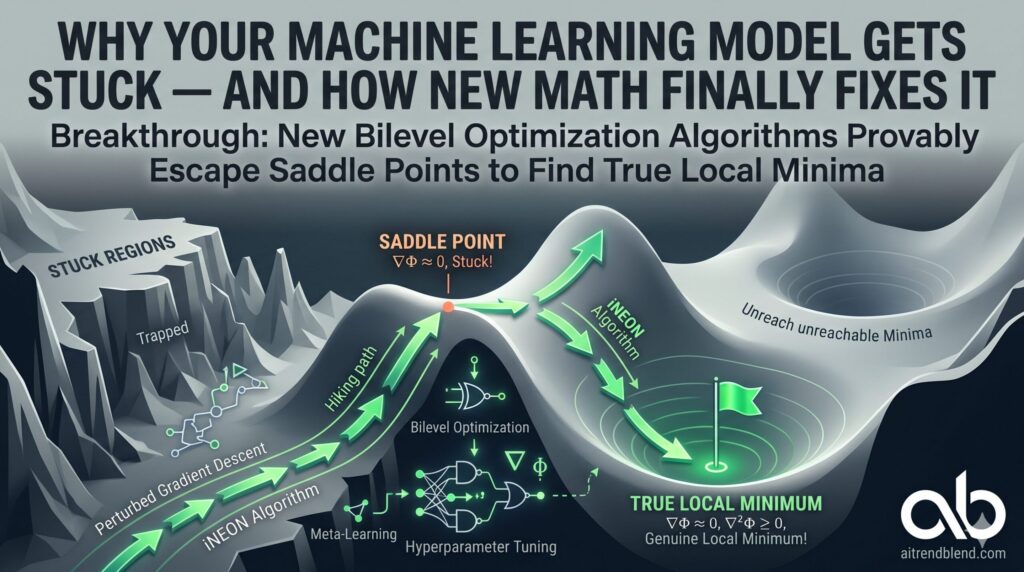
Escaping Saddle Points in Bilevel Optimization — A Breakthrough in Machine Learning Theory.

Escaping Saddle Points in Bilevel Optimization — A Breakthrough in Machine Learning Theory

A research team from three major U.S. universities has proven for the first time that bilevel optimization algorithms can reliably escape saddle points and find true local minima — solving a problem that has quietly undermined meta-learning, hyperparameter tuning, and…

Escaping Saddle Points in Bilevel Optimization — A Breakthrough in Machine Learning Theory Read More »

Liquid Biopsy and AI: Multi-Cancer Early Detection — 10 Claude Code Prompts (2026 Guide).

Liquid Biopsy and AI: Multi-Cancer Early Detection — 10 Claude Code Prompts (2026 Guide)

Liquid biopsy for multi-cancer early detection is one of the most consequential diagnostic innovations of the past decade — and one of the most computationally demanding. The signal you’re looking for is vanishingly small: at Stage I, circulating tumour DNA…

Liquid Biopsy and AI: Multi-Cancer Early Detection — 10 Claude Code Prompts (2026 Guide) Read More »

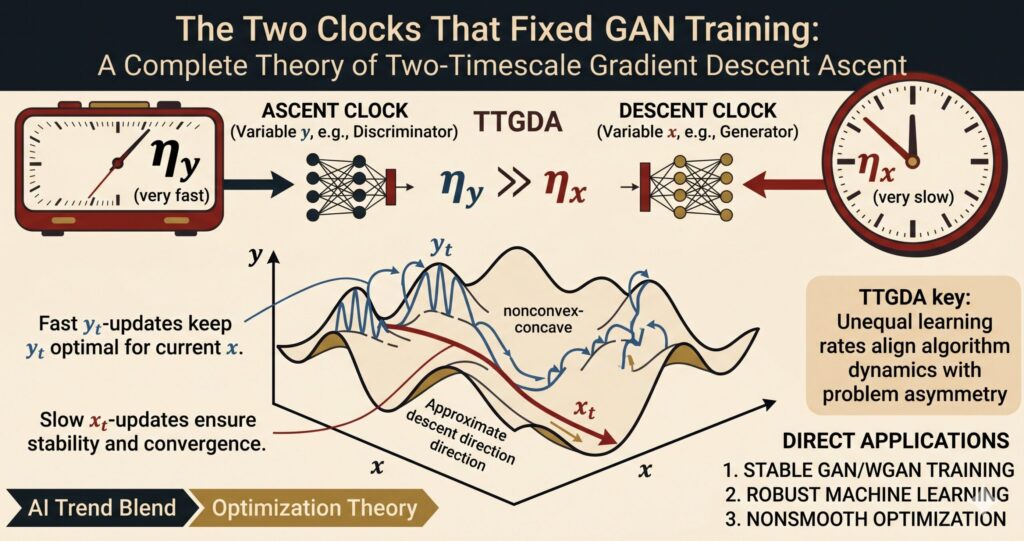
TTGDA: Two-Timescale Gradient Descent Ascent for Nonconvex Minimax Optimization.

TTGDA: Two-Timescale Gradient Descent Ascent for Nonconvex Minimax Optimization

Tianyi Lin, Chi Jin, and Michael I. Jordan from Columbia, Princeton, and UC Berkeley deliver the first rigorous nonasymptotic analysis of two-timescale gradient descent ascent — the algorithm that has powered GAN training in practice for years — establishing tight…

TTGDA: Two-Timescale Gradient Descent Ascent for Nonconvex Minimax Optimization Read More »

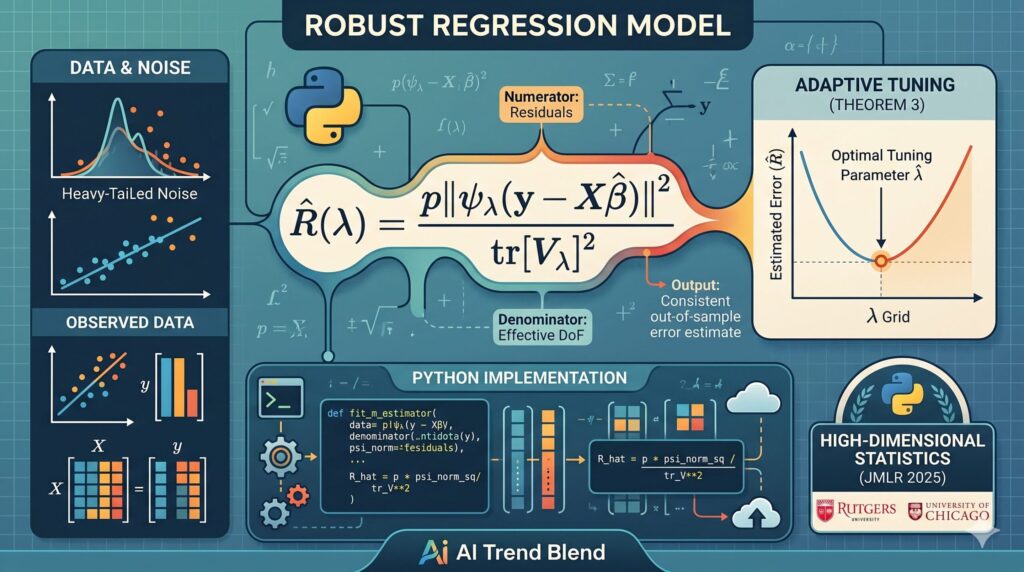
How to Tune a Robust Regression Model Without Knowing the Noise: Adaptive Error Estimation for Unregularized M-Estimators.

How to Tune a Robust Regression Model Without Knowing the Noise: Adaptive Error Estimation for Unregularized M-Estimators

Pierre C. Bellec (Rutgers) and Takuya Koriyama (Chicago Booth) prove that a simple, fully observable formula consistently estimates the prediction error of any Huber-class M-estimator in high dimensions — and that minimizing it over a grid of scale parameters automatically…

How to Tune a Robust Regression Model Without Knowing the Noise: Adaptive Error Estimation for Unregularized M-Estimators Read More »

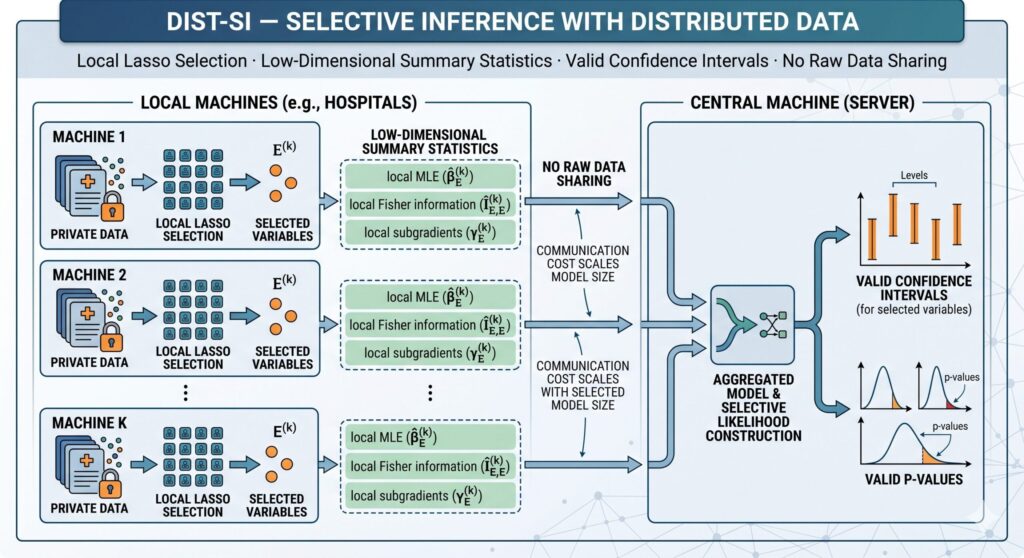
Dist-SI: Selective Inference with Distributed Data via Randomized Lasso.

Dist-SI: Selective Inference with Distributed Data via Randomized Lasso

Sifan Liu (Stanford) and Snigdha Panigrahi (University of Michigan) introduce Dist-SI — a procedure that lets distributed machines run lasso independently, share only tiny summary statistics with a central server, and still produce valid confidence intervals and p-values as if…

Dist-SI: Selective Inference with Distributed Data via Randomized Lasso Read More »