Vision Transformers & Attention

Attention mechanisms, vision transformers, and the architectures replacing convolutions across vision tasks. We unpack how attention is used, misused, and reinvented in current research, from efficient attention branches to Mamba-style state space models.

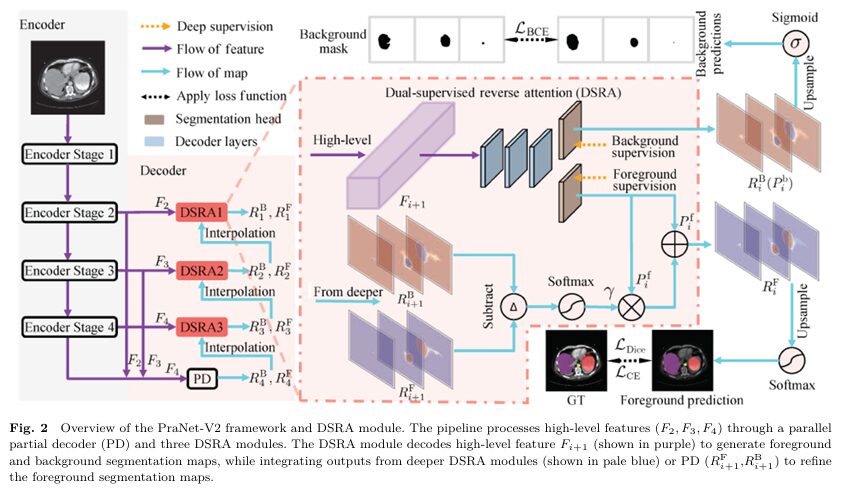
PraNet-V2: Dual-Supervised Reverse Attention for Medical Image Segmentation.

PraNet-V2 Fixes Medical Segmentation By Modeling Background

Analysis by the aitrendblend editorial team · Medical image segmentation · Computational Visual Media, 2026 PraNet-V2 Dual Supervised Reverse Attention Polyp Segmentation Multi Organ CT Cardiac MRI Overview of the PraNet-V2 decoder. Three cascaded DSRA stages refine a coarse prediction using both a foreground head and an independently supervised background head. A flat polyp sitting […]

PraNet-V2 Fixes Medical Segmentation By Modeling Background Read More »
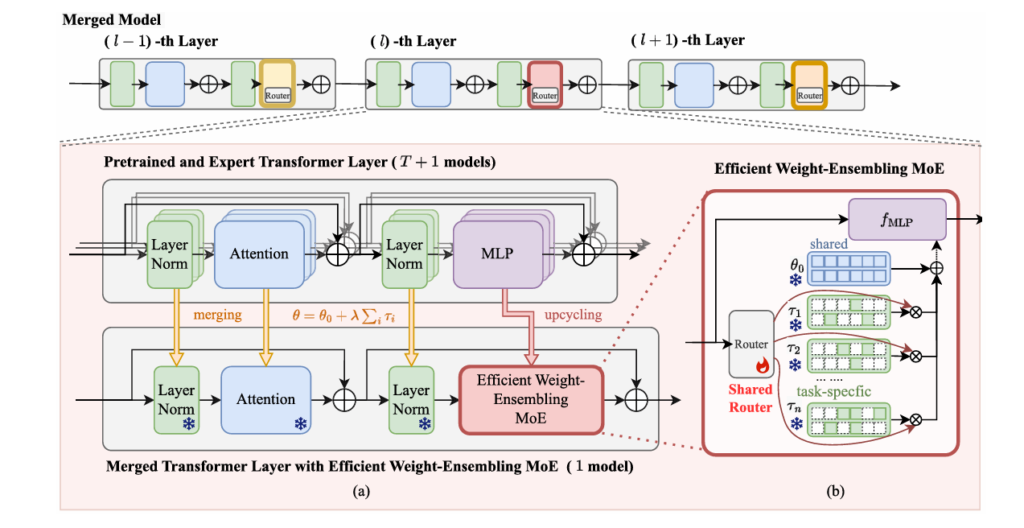
The WEMoE framework transforms critical MLP modules into dynamic mixture-of-experts structures while statically merging non-critical components. Input-dependent routing weights allow the model to adaptively blend task-specific knowledge, achieving superior multi-task performance over static merging methods.

WEMoE: How a Mixture-of-Experts Approach Is Solving the Multi-Task Model Merging Problem

WEMoE: How a Mixture-of-Experts Approach Is Solving the Multi-Task Model Merging Problem | MedAI Research Deep Learning · TPAMI, 2026 · 18 min read The Static Model Merging Problem — and How WEMoE Learned to Adapt WEMoE introduces a dynamic mixture-of-experts approach to multi-task model merging, transforming how we combine fine-tuned neural networks by routing

WEMoE: How a Mixture-of-Experts Approach Is Solving the Multi-Task Model Merging Problem Read More »

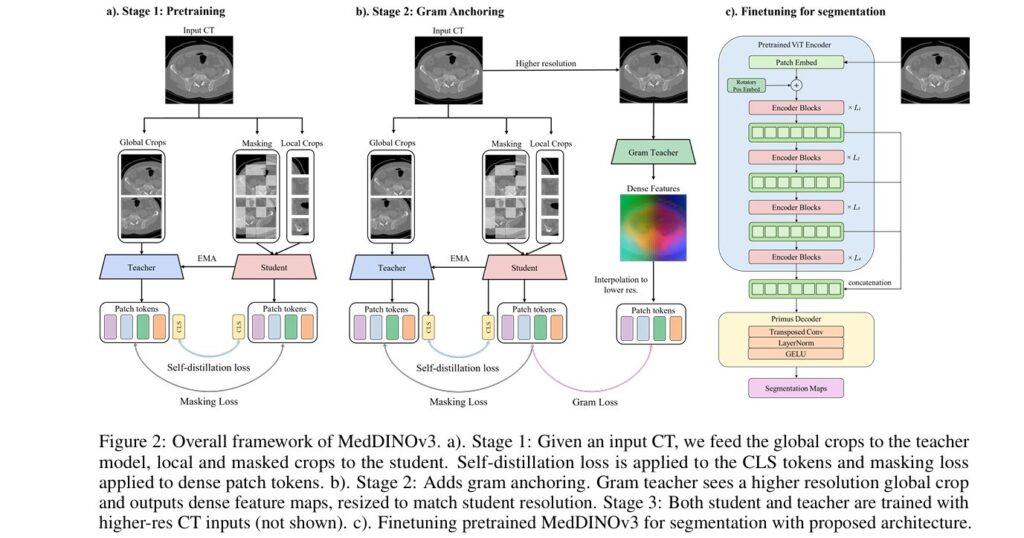
MedDINOv3: Revolutionizing Medical Image Segmentation with Adaptable Vision Foundation Models

MedDINOv3 Adapts A Vision Foundation Model For CT And MRI Segmentation

AI for medical imaging and healthcare Vision foundation models CT and MRI segmentation Self supervised pretraining Analysis by the aitrendblend editorial team A radiation oncologist planning a course of treatment needs the kidneys, liver, spinal cord, and every nearby organ outlined precisely enough that the radiation beam avoids them by design rather than by luck.

MedDINOv3 Adapts A Vision Foundation Model For CT And MRI Segmentation Read More »

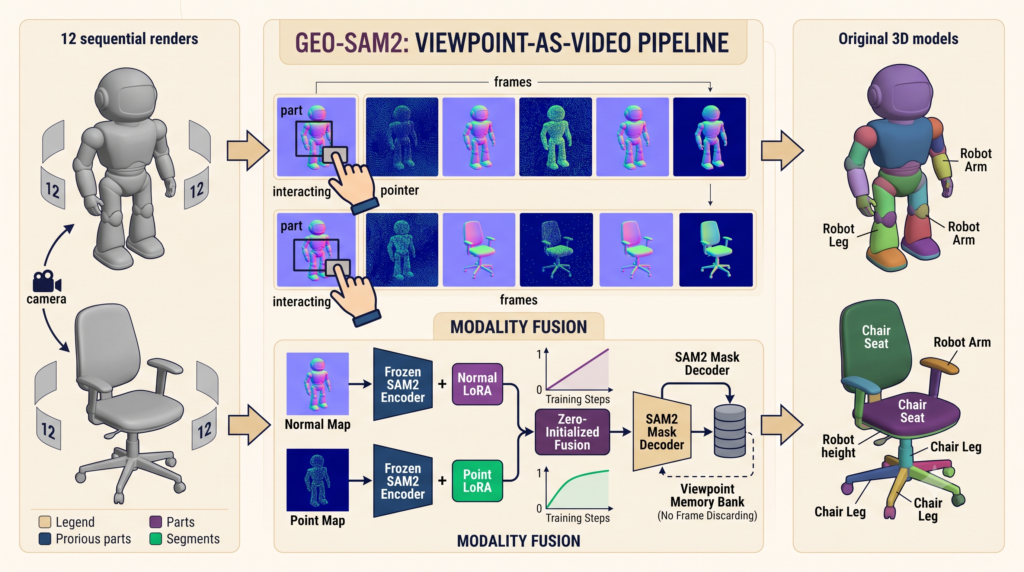
GeoSAM2 Turns SAM2 Into a 3D Part Segmentation Tool

GeoSAM2 Turns SAM2 Into a 3D Part Segmentation Tool

Analysis by the aitrendblend editorial team · Pillar: Vision transformers and attention · Source paper published August 2025 3D part segmentation SAM2 LoRA adaptation multi-view geometry foundation models GeoSAM2 treats twelve renders of a single 3D object as if they were frames of a short video clip. SAM2 was built to watch a video and

GeoSAM2 Turns SAM2 Into a 3D Part Segmentation Tool Read More »

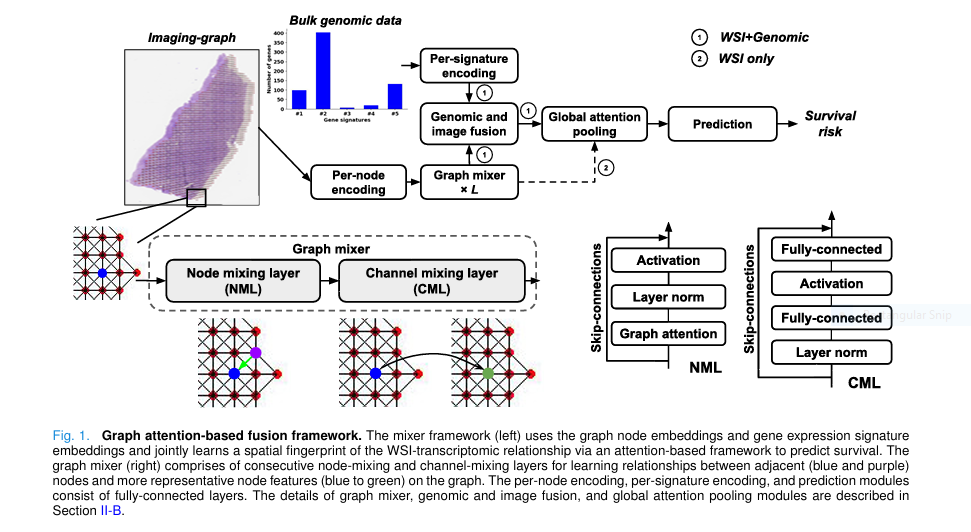
Graph Attention Model for Cancer Survival Prediction

Graph Attention Fusion of Pathology Images and Gene Expression Predicts Cancer Survival

Analysis by the aitrendblend editorial team · Medical imaging AI· Graph Attention Networks Digital Pathology Gene Expression Fusion Lung Cancer Survival Multimodal Learning A pathology slide and a gene expression profile describe the same tumor from two completely different angles. One shows how the tissue is physically organized under a microscope, the other shows which

Graph Attention Fusion of Pathology Images and Gene Expression Predicts Cancer Survival Read More »

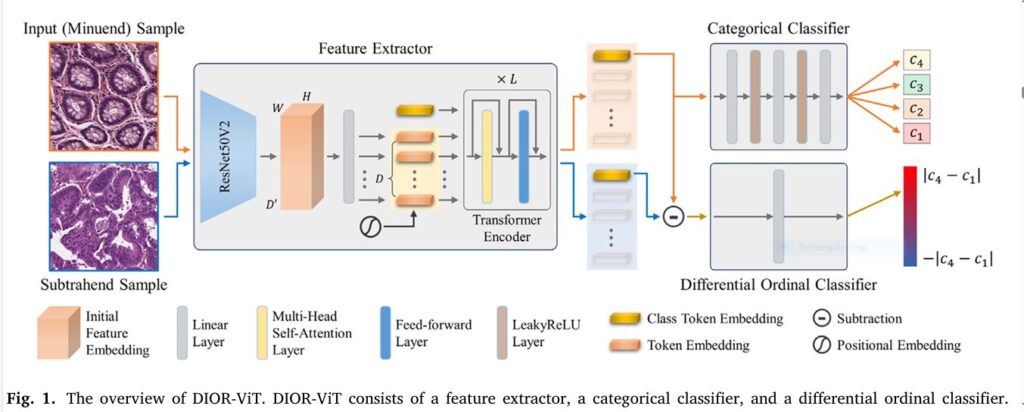
Diagram illustrating the DIOR-ViT architecture for differential ordinal classification in pathology images

DIOR-VIT: Vision Transformers Learn the Order of Cancer Grades

Analysis by the aitrendblend editorial team · 14 minute read Computational Pathology Vision Transformer Cancer Grading Ordinal Learning A pathologist looking at two biopsy slides rarely just labels each one and moves on. They also weigh how much worse one sample looks than the other, because that comparison shapes how urgently a patient needs treatment.

DIOR-VIT: Vision Transformers Learn the Order of Cancer Grades Read More »