
Key points
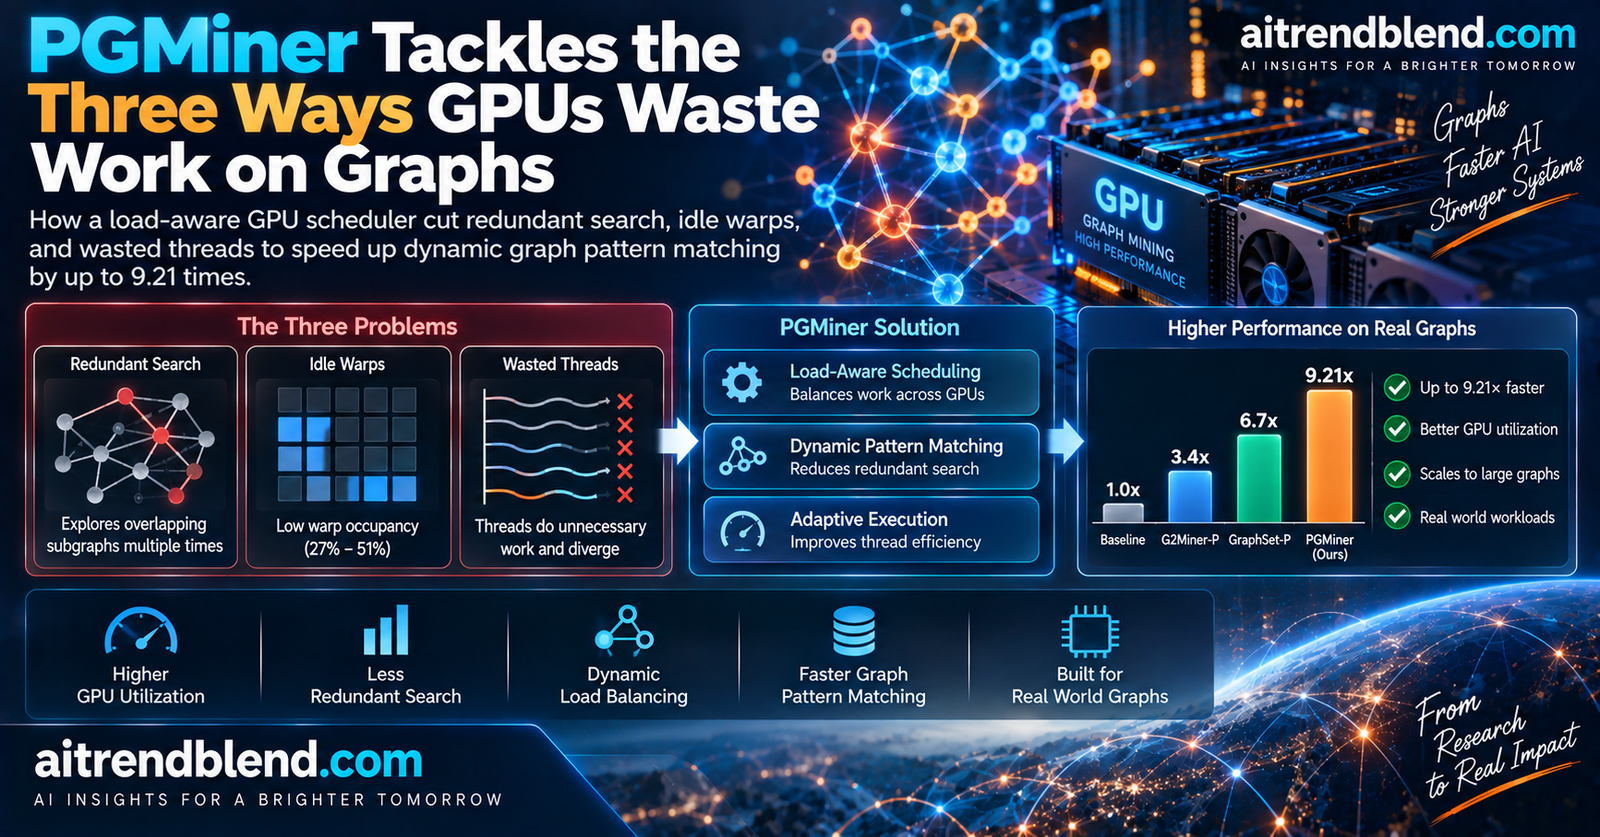
- PGMiner is a GPU system for dynamic graph pattern matching, the task of finding every new or removed subgraph that matches a given pattern each time a graph gains or loses an edge.
- The researchers first measured exactly how much existing GPU systems waste, finding GPU warp occupancy as low as 27.24 percent and a 1.43 times average execution time gap between the busiest and least busy GPU in a four GPU setup.
- PGMiner attacks three separate bottlenecks, redundant computation from isomorphic pattern edges, load imbalance both across GPUs and between warps inside one GPU, and idle threads within individual warps.
- Compared against two state of the art GPU based dynamic graph pattern matching baselines built for this paper, GraphSet-P and G2Miner-P, PGMiner delivers speedups of 2.18 to 7.81 times and 3.85 to 9.21 times respectively.
- Every one of PGMiner’s three mechanisms was tested in isolation through ablation experiments, showing each contributes a real, separately measurable performance gain rather than the total speedup being attributable to just one dominant trick.
Why matching a pattern in a graph gets harder the moment the graph starts moving
Graph pattern matching asks a deceptively simple question. Given a small pattern graph, maybe a triangle, maybe a four node clique, find every place in a much larger data graph where that exact shape of connections appears. It shows up constantly in practice, from spotting suspicious transaction rings in financial networks to finding recurring motifs in protein interaction data. The trouble is that graph pattern matching is an NP-complete problem whose computational cost grows exponentially as the graph gets bigger, and real world graphs are rarely static. Social networks, transaction networks, and communication networks all accumulate and lose edges continuously, and any system that wants to keep its answer current has to somehow keep up.
The naive approach, rerunning a full pattern match across the whole graph every time a single edge changes, is exactly as wasteful as it sounds. So systems researchers moved to incremental computation instead, matching only the new subgraphs that could possibly have been created or destroyed by the specific edges that just changed. CPU based systems built around this idea exist, but CPUs are fundamentally limited by how many threads they can run at once, and dynamic graph workloads with real time demands quickly run into that ceiling. GPUs, with their much larger pool of parallel threads, look like the obvious answer. The paper’s contribution starts from a less obvious observation, that simply porting an incremental CPU algorithm onto a GPU does not automatically deliver the speedup you would hope for, because the GPU’s own execution model introduces new problems that were never present on the CPU side.
A short vocabulary lesson, because the terms matter
A few definitions from the paper are worth having straight before going further, because the whole optimization strategy hinges on them. A pattern graph is just the small shape you are searching for, written as \( P = (V, E) \). Two edges in that pattern graph are called isomorphic edges if some structural symmetry of the pattern, formally an automorphism, maps one edge onto the other. A matching order fixes the sequence in which the pattern’s vertices get matched against candidate vertices in the data graph. A symmetric order is a constraint, something like requiring one matched vertex’s index to always be greater than another’s, that exists purely to stop the same subgraph from being counted multiple times because of the pattern’s internal symmetry. Put a matching order and a symmetric order together and you get what the paper calls an execution plan, the concrete recipe a GPU thread actually follows to search for matches.
Diagnosing the waste before trying to fix it
Before proposing PGMiner, the authors built two baseline systems specifically to measure where the losses were happening. They took two existing state of the art GPU systems for static graph pattern matching, called GraphSet and G2Miner, and grafted the incremental computation model from a leading CPU based dynamic system called PSMiner onto each of them, producing GraphSet-P and G2Miner-P. These hybrids represent a reasonable, honest baseline, the kind of system you would build today if you wanted dynamic graph pattern matching on a GPU without inventing anything new. Then they measured exactly how much performance those hybrids were leaving on the table, and organized the losses into three distinct categories.
Waste one, redundant computation from isomorphic edges
The traditional incremental approach generates a separate execution plan for every edge of the pattern graph, then runs all of those plans starting from whichever edge in the data graph just changed. Because some of the pattern’s edges are isomorphic to each other, several of those separately generated execution plans end up searching largely overlapping territory, and the symmetric order checks needed to avoid double counting pile up on top of that. Measured across three patterns on three datasets, this overhead ranged from 8.21 percent to 20.23 percent of total runtime for redundant computation, and 6.32 percent to 14.33 percent for redundant symmetry checking, with the most symmetry rich pattern in the test set hitting the high end of both ranges.
Waste two, load imbalance at two different scales
The second problem shows up at two separate levels of the hardware. Inside a single GPU, tasks get spread across warps, and because real world graphs follow a power law degree distribution, some vertices have vastly more neighbors than others, which means some warps get handed dramatically more work than their neighbors sitting idle a few cycles away. Measuring warp occupancy directly, the authors found utilization ranging from only 27.24 percent to 51.34 percent, meaning roughly half or more of the available parallel compute capacity was sitting unused at any given moment. Zoom out to a four GPU setup and the same pattern repeats at a larger scale. The baseline’s block based round robin task scheduling, which hands out tasks without any awareness of how expensive each one actually is, produced execution times that varied significantly across the four devices. On two of the five test datasets, the busiest GPU took 1.43 times longer than the least busy GPU on average, with the worst single case reaching a 1.56 times gap.
Waste three, idle threads inside the warp itself
The third problem is the most granular. A GPU warp executes 32 threads in lockstep, and the system’s intersection calculations, the core operation of checking whether two candidate vertex sets overlap, use all 32 threads to run a parallel binary search. That works well when a vertex has dozens of neighbors to search through, but real graphs are full of low degree vertices, and the paper found that between 20.23 percent and 55.14 percent of the sets involved in these intersection calculations had only 1 to 16 elements, well under the warp’s full width of 32. The resulting thread utilization measured between 41.23 percent and 72.21 percent, meaning a meaningful chunk of every warp’s threads were doing nothing useful even while the warp as a whole was actively running.
How PGMiner is put together
PGMiner is organized into three components that map fairly directly onto the three problems just described. A pattern analysis component eliminates the redundant computation problem before any GPU work even starts, by analyzing the pattern graph’s topology once, up front, on the host side. A task allocation component addresses the cross GPU load imbalance by predicting how expensive each unit of work will be and distributing accordingly. A task execution component addresses both the within GPU warp imbalance and the within warp thread idling, using two complementary runtime mechanisms once the matching process is actually underway on the device.
Killing redundant work with a shared execution plan
Instead of generating one execution plan per pattern edge and running them independently, PGMiner first identifies which edges of the pattern graph are isomorphic to each other, grouping them into what the paper calls isomorphic edge classes. Isomorphic edges are then merged so they share a single execution plan rather than each carrying its own redundant search and its own redundant symmetric order check. Concretely, the paper walks through pattern P3 as an example, where the traditional approach needs 18 separate execution plans, while PGMiner’s shared plan strategy collapses that down to just 3, eliminating the symmetry check overhead entirely for the merged plans. Generating this shared plan runs in \( O(k^2 t) \) time, where \( k \) is the number of matching sequences under consideration and \( t \) is the number of symmetric sequences, and because this analysis happens once on the pattern graph rather than repeatedly during matching, its cost is negligible relative to the savings it produces.
Predicting task cost cheaply enough to actually use it
To balance load across multiple GPUs, PGMiner needs to estimate, before running a task, roughly how expensive that task will be. The constraint here is tight, because this prediction has to run on the CPU while the GPUs are busy doing the actual matching, so it needs to be cheap. PGMiner restricts itself to information that is essentially free to obtain, the degree of the two vertices on the update edge, the average degree of the whole dynamic graph, which can be maintained incrementally rather than recomputed, and the structure of the execution plan itself.
When a pattern graph vertex is not adjacent to both endpoints of the update edge, this formula estimates the size of its candidate set, where \( |V| \) is the total number of vertices in the dynamic graph, \( d_0 \) and \( d_1 \) are the degrees of the update edge’s two endpoints, \( d_{avg} \) is the graph’s average degree, \( k \) counts the remaining adjacent vertices in the matching order, and \( b_1, b_2 \in \{0, 1\} \) flag whether the vertex is adjacent to either endpoint.
When a vertex is adjacent to both endpoints of the update edge, meaning \( b_1 = b_2 = 1 \), its candidate set comes from intersecting both neighborhoods directly, so the estimate instead starts from num, the actual measured size of that neighborhood intersection.
A third factor, the probability that the symmetric order will end up filtering a given candidate subgraph out entirely, is folded in as well, since pruning reduces the effective workload of a task even after its candidate set size has been estimated. Put together, the whole task cost prediction model runs in \( O(d^2) \) time, where \( d \) is the maximum degree in the graph, and the authors measured its actual runtime overhead directly, finding that task overhead prediction consumed only 1.92 to 7.09 percent of total execution time and task sorting an additional 0.23 to 1.23 percent, confirming the prediction step stays cheap enough not to become a bottleneck of its own.
Once every task has a predicted cost, distributing them across GPUs becomes a classic scheduling problem, partition a set of numbers into groups so that the largest group sum is minimized, which is itself NP-complete in general. PGMiner sidesteps an exact solution with a practical greedy heuristic, sorting tasks from most to least expensive, then repeatedly assigning the next task to whichever GPU currently holds the smallest total load, tracked efficiently with a min-heap so the least loaded device is always available in constant time.
Balancing load twice inside the GPU
Getting tasks fairly distributed across GPUs still leaves the warp level imbalance problem untouched, so PGMiner layers two more mechanisms on top, working entirely within a single device. The first is adaptive task splitting, which looks at two signals for every task in flight, the number of valid candidate vertices remaining at the current search level, and the number of vertices near the end of the matching order that are not adjacent to each other. A task with a large candidate set and a matching order where those late stage vertices are poorly connected is flagged as high load and gets split into smaller, independently schedulable pieces that get pushed back into a global queue, spreading the work more evenly before it ever causes an imbalance.
The second mechanism, dynamic work stealing, catches whatever imbalance the first one missed. When a warp runs out of work and the global queue is empty, it looks for the currently most loaded warp, first within its own thread block where shared memory makes checking other warps’ status cheap, then across thread blocks if nothing local is available.
The remaining workload of a warp is estimated as the number of unprocessed candidate vertices, left_nodes, scaled by \( \alpha \), a cost factor for that warp’s specific execution plan taken from a performance prediction model used in prior work called GraphPi, and by \( \lambda = (1/d_{avg})^{l-2} \), a recursion depth factor reflecting that warps deeper in the search tree generally have less remaining work left to expand, counted from level 2 onward since the update edge’s two vertices are already matched by that point.
Because stealing requires locking another warp’s shared state with CUDA atomic instructions, it is not free, so PGMiner caps how deep into the search tree a warp is allowed to steal from, using a tunable parameter called DetectLevel, keeping synchronization overhead in check while still catching the imbalance that adaptive splitting alone cannot.
Squeezing the last idle threads out of a warp
The final mechanism addresses the problem that even a perfectly load balanced warp can waste threads if the vertex sets it is intersecting are simply too small to fill all 32 lanes. PGMiner’s dynamic loop unrolling mechanism tracks the running total neighborhood size of vertices it has queued up for intersection, and once that total is large enough to keep the warp’s threads busy, or once a maximum step count is reached, it fuses several separate intersection calculations into one batch and runs them together, rather than running each undersized intersection on its own and leaving most of the warp idle. Underneath all of this, PGMiner also swaps in a dynamic memory allocator called Gallatin, built on a van Emde Boas tree structure, replacing fixed size preallocation with on demand allocation of fixed size memory blocks, set to 4 kilobytes in the experiments, which matters because dynamic graphs are constantly creating and discarding intermediate search state as edges come and go.
Does it actually work, and does each piece pull its weight
The headline numbers come from five real world graphs of quite different scale, ranging from a 100,000 vertex, 1.08 million edge co-purchase graph up to a 3.7 million vertex, 117 million edge Orkut social network with a maximum vertex degree over 33,000, tested against six standard pattern graphs used throughout the graph mining literature. Experiments loaded 90 percent of each graph’s edges up front, then streamed in the remaining 0.1 percent as dynamic updates to simulate a live, changing graph.
| Comparison baseline | Speedup range | Average speedup |
|---|---|---|
| PSMiner-S, the leading CPU based dynamic graph pattern matching system | 1.06 to 58.85 times | 19.8 times |
| GraphSet-P, a GPU hybrid built for this paper | 2.18 to 7.81 times | 4.12 times |
| G2Miner-P, a second GPU hybrid built for this paper | 3.85 to 9.21 times | 6.41 times |
The pattern with the single largest speedup, referred to as P5 in the paper, benefited from a combination of having many sharable execution plans, which let the redundancy elimination mechanism do a lot of work, and having large cost differences between its various execution plans, which gave the load balancing mechanisms plenty of imbalance to correct. Interestingly, PGMiner’s advantage over GraphSet-P specifically was narrower on two other patterns, P4 and P6, and the authors explain this honestly rather than glossing over it, noting that GraphSet-P already uses a set conversion optimization that lets it terminate its depth first search early for exactly those two pattern shapes, so PGMiner’s redundancy and load balancing improvements had less remaining headroom to work with on those particular cases.
The performance improvement of PGMiner on GraphSet-P is narrower. This is mainly because GraphSet-P employs set conversion technology for performance optimization, which can terminate the DFS search process in advance. From the paper’s performance comparison section, explaining a case where PGMiner’s advantage was smaller than average
To confirm the speedup was not just one mechanism doing all the work, the authors ran a full set of ablation experiments. Merging isomorphic edges into shared execution plans, tested in isolation as PGMiner-M against a version without merging called PGMiner-WM, produced a 1.171 to 1.892 times improvement on its own. The two level load balancing strategy, broken into a no balancing baseline called PGMiner-N, an adaptive splitting only version called PGMiner-A, and the full splitting plus stealing version called PGMiner-AS, showed adaptive task splitting alone contributing 1.31 to 1.89 times and dynamic work stealing adding a further 1.37 to 1.98 times on top. Those improvements tracked directly with measured warp occupancy, which rose by an average of 14.55 percent with splitting alone and 27.31 percent with both mechanisms combined, relative to the unbalanced baseline. Finally, the dynamic loop unrolling mechanism improved performance by 1.51 times on average compared with no unrolling at all, and by 1.21 times compared with a simpler fixed step unrolling scheme that does not adapt to how many threads are actually idle.
Tuning a real system, not just a paper result
Two sensitivity experiments stand out for how directly they translate into practical guidance for anyone trying to build on this work. The idle thread threshold, the trigger point that decides when dynamic loop unrolling kicks in, was tested at values of 4, 8, 12, and 16. Runtime improved as the threshold rose from 4 up to 8, then got worse again at 12 and 16. Too low a threshold means most tasks never accumulate enough neighborhood size to trigger the optimization at all, while too high a threshold leaves a large share of threads sitting idle before unrolling finally activates, and the authors landed on 8 as the point of best balance between those two failure directions for their test hardware and workloads.
The other sensitivity result is more of a systems engineering reassurance than a tuning knob. Because the task cost prediction model has to run on the CPU while the GPUs stay busy with actual matching work, an expensive predictor would defeat its own purpose. Measured directly, prediction overhead stayed under 7.09 percent of total runtime and sorting overhead under 1.23 percent even in the most demanding test configuration, evidence that the load aware approach is not quietly trading GPU compute time for CPU scheduling time behind the scenes.
Honest limitations
A few boundaries are worth stating plainly, based only on what the paper itself reports. The load prediction model is explicitly built around an assumption that vertex degrees not directly tied to the update edge are evenly distributed, and while the authors argue this remains reasonable even under the heavily skewed power law degree distributions typical of real graphs, they also state directly that the model does not account for resource constrained scenarios, and that prediction accuracy may suffer in such cases, without further quantifying by how much. The experimental hardware was a fixed four GPU Tesla V100 configuration, so how PGMiner’s cross GPU load balancing behaves on a different device count, a mix of GPU generations, or GPUs connected with different interconnect bandwidth was not tested in this paper. The dynamic update workload was also fixed at a specific shape, loading 90 percent of each graph up front and streaming the remaining 0.1 percent as updates, and while the sensitivity analysis did vary update batch sizes down to 0.00001 times the edge count, it only did so on two of the five datasets and two of the six patterns, so the full parameter space of possible update rates and batch sizes across every dataset and pattern combination was not exhaustively explored.
It is also worth being precise about what the reported speedups represent. The paper states clearly that the measured runtime includes only the dynamic graph pattern matching calculation itself, excluding graph data loading, update operation time, and program preprocessing and compilation time. That is a standard and defensible way to isolate the algorithmic contribution being studied, but it also means the end to end wall clock experience of running PGMiner on a fresh dataset, including data loading and compilation, would include additional time not reflected in the headline multiplier figures.
Where this fits in the bigger picture
The broader lesson from this paper travels well beyond graph pattern matching specifically. Porting an algorithm designed for one hardware model onto another, in this case moving an incremental computation idea from CPU threads to GPU warps, is not a mechanical translation exercise. The GPU’s execution model, with its lockstep warps, its reliance on keeping all 32 lanes busy, and its need to explicitly balance work across physically separate devices, creates entirely new failure modes that simply do not exist in the CPU version of the same algorithm. The value of this paper’s methodology is arguably as much in its diagnostic discipline as in PGMiner itself, measuring warp occupancy directly, measuring cross GPU load gaps directly, measuring thread utilization directly, rather than assuming a GPU port would automatically inherit the CPU algorithm’s efficiency.
Conclusion
PGMiner is not a single clever trick dressed up as a system. It is three separately diagnosed problems, each with its own separately validated fix, and the paper’s own ablation studies make that structure unusually easy to verify rather than take on faith. Shared execution plans cut redundant search and symmetry checking before a single GPU thread launches. A lightweight, cheaply computed load prediction model and a greedy scheduling heuristic keep four physically separate GPUs from sitting unevenly loaded. Adaptive task splitting and dynamic work stealing keep individual warps from idling while their neighbors are overloaded. Dynamic loop unrolling squeezes usable work out of threads that would otherwise sit idle inside an already busy warp.
What makes the result credible is the discipline behind it. The authors did not simply claim load imbalance was a problem, they measured it directly, warp occupancy between 27 and 51 percent, a 1.43 times average gap between the busiest and least busy GPU, and thread utilization as low as 41 percent within active warps. Every fix that followed was aimed at a specific, quantified number, and every fix was then tested in isolation to confirm it actually moved that number, which is a more rigorous standard than many systems papers hold themselves to.
The speedup figures themselves, 2.18 to 7.81 times over GraphSet-P and 3.85 to 9.21 times over G2Miner-P, are substantial, but the more durable contribution is probably the load prediction formula and the two level balancing strategy, both of which are general enough to be relevant to other irregular, power law shaped parallel workloads on GPUs, not just graph pattern matching specifically. Dynamic graphs are everywhere that data changes in real time, financial transaction monitoring, recommendation systems, fraud detection networks, and any system trying to keep pattern based analytics current on a graph that never stops moving faces some version of the exact three problems this paper measured and solved.
The honest caveats the authors include, a load model that assumes away resource constrained scenarios, a fixed four GPU test configuration, and a narrower advantage on pattern shapes where a competing baseline already had its own optimization, keep the claims grounded. That combination, a real measured problem, three targeted and separately verified fixes, and a candid account of where the approach’s advantage narrows, is what makes this a systems paper worth reading past the headline multiplier in its abstract.
Reference implementation of the core scheduling logic in Python
The following is an original, simplified, runnable Python implementation inspired by the load prediction formulas, the greedy multi GPU task allocator, and the adaptive splitting threshold logic described in the paper. It is a compact educational reconstruction of the scheduling ideas, not the authors’ own CUDA implementation, built to illustrate the core algorithms on synthetic data with a working smoke test.
# pgminer_scheduling_core.py
# Educational reimplementation of the load prediction formulas, the
# greedy min-heap task allocator across GPUs, and the adaptive task
# splitting threshold logic described in "PGMiner: A Load-Aware
# Dynamic Graph Pattern Matching Approach on GPUs", IEEE TKDE, 2026.

import heapq
from dataclasses import dataclass
from typing import List


@dataclass
class UpdateEdgeTask:
    """One task, the combination of an update edge and an execution plan,
    following the task granularity definition in Section IV-C."""
    task_id: int
    d0: int              # degree of the update edge's first endpoint
    d1: int              # degree of the update edge's second endpoint
    num_intersect: int    # measured size of the direct neighborhood intersection
    k: int               # remaining vertices adjacent in the matching order
    both_adjacent: bool   # True when the vertex depends on both update edge endpoints
    prune_prob: float    # estimated probability the symmetric order prunes this task


def estimate_candidate_set_size(task: UpdateEdgeTask, num_vertices: int, avg_degree: float) -> float:
    """Implements Eq. 1 and Eq. 2 from the paper, estimating how many
    candidate vertices a task's search will need to examine."""
    if task.both_adjacent:
        # Eq. 2, the vertex's candidates come from an already measured
        # neighborhood intersection of both update edge endpoints.
        return task.num_intersect * (avg_degree / num_vertices) ** task.k
    # Eq. 1, the vertex is adjacent to at most one update edge endpoint.
    b1 = 1 if task.d0 > 0 else 0
    b2 = 1 if task.d1 > 0 else 0
    return (
        num_vertices
        * (task.d0 / num_vertices) ** b1
        * (task.d1 / num_vertices) ** b2
        * (avg_degree / num_vertices) ** task.k
    )


def predict_task_cost(task: UpdateEdgeTask, num_vertices: int, avg_degree: float) -> float:
    """Combines the candidate set size estimate with the symmetric order
    pruning probability to produce a single predicted task cost, used
    to sort and allocate tasks in Section IV-C."""
    candidate_size = estimate_candidate_set_size(task, num_vertices, avg_degree)
    return candidate_size * (1.0 - task.prune_prob)


def allocate_tasks_to_gpus(tasks: List[UpdateEdgeTask], num_gpus: int, num_vertices: int, avg_degree: float):
    """Greedy min-heap task allocator following Section IV-C.2, sorting
    tasks by predicted cost descending, then repeatedly assigning the
    next costliest task to the currently least loaded GPU."""
    costed = [(predict_task_cost(t, num_vertices, avg_degree), t) for t in tasks]
    costed.sort(key=lambda pair: pair[0], reverse=True)

    # Min-heap of (current_load, gpu_id), the top is always the least loaded GPU.
    heap = [(0.0, gpu_id) for gpu_id in range(num_gpus)]
    heapq.heapify(heap)

    assignment = {gpu_id: [] for gpu_id in range(num_gpus)}
    for cost, task in costed:
        current_load, gpu_id = heapq.heappop(heap)
        assignment[gpu_id].append(task.task_id)
        heapq.heappush(heap, (current_load + cost, gpu_id))

    final_loads = {gpu_id: load for load, gpu_id in heap}
    return assignment, final_loads


def should_split_task(len_candidates: int, k_nonadjacent: int, c_th: float, k_th: int, recursion_level: int) -> bool:
    """Implements the adaptive task splitting rule from Section IV-D.1.
    A task is split when its candidate set is large and its matching
    order pushes intersection work into the innermost loops, unless
    it is already too close to the recursion base case to be worth it."""
    if recursion_level <= 3:
        return False
    return k_nonadjacent <= k_th and len_candidates >= c_th


def estimate_remaining_load(left_nodes: int, plan_cost_ratio: float, avg_degree: float, level: int) -> float:
    """Implements left_task = left_nodes * alpha * lambda from
    Section IV-D.2, used by idle warps to pick the best warp to
    steal work from."""
    alpha = plan_cost_ratio
    lam = (1.0 / avg_degree) ** max(level - 2, 0)
    return left_nodes * alpha * lam


def smoke_test():
    """Builds a small synthetic task set and confirms the prediction,
    allocation, splitting, and stealing logic all run without errors
    and produce sane, balanced output."""
    num_vertices = 100_000
    avg_degree = 21.6  # roughly matches the MiCo dataset's edge to vertex ratio

    tasks = [
        UpdateEdgeTask(task_id=i, d0=5 + i % 50, d1=3 + i % 30,
                        num_intersect=4 + i % 12, k=2,
                        both_adjacent=(i % 3 == 0), prune_prob=0.1 + (i % 5) * 0.05)
        for i in range(40)
    ]

    assignment, final_loads = allocate_tasks_to_gpus(tasks, num_gpus=4, num_vertices=num_vertices, avg_degree=avg_degree)

    split_decision = should_split_task(len_candidates=64, k_nonadjacent=1, c_th=avg_degree, k_th=2, recursion_level=5)
    steal_target_load = estimate_remaining_load(left_nodes=40, plan_cost_ratio=1.8, avg_degree=avg_degree, level=4)

    print("Tasks per GPU", {gpu: len(t) for gpu, t in assignment.items()})
    print("Final predicted load per GPU", {gpu: round(load, 2) for gpu, load in final_loads.items()})
    print("Should this high load task be split", split_decision)
    print("Estimated remaining load for a steal target warp", round(steal_target_load, 4))
    print("Smoke test completed without errors")


if __name__ == "__main__":
    smoke_test()
Frequently asked questions
What is dynamic graph pattern matching
Dynamic graph pattern matching is the task of finding every subgraph in a changing graph that matches a given pattern shape, and specifically identifying only the new matches created or the old matches destroyed each time an edge is added or removed, rather than rescanning the entire graph from scratch after every change.
Why does a GPU port of a CPU graph algorithm not automatically run faster
GPUs execute threads in fixed size groups called warps that run in lockstep, and they only reach their full potential when every thread in a warp has useful, roughly equal work to do. The paper found that a straightforward GPU port of an existing CPU incremental algorithm left GPU warp occupancy as low as 27.24 percent and left individual GPU devices in a four GPU setup with execution times up to 1.43 times apart on average, showing that the GPU’s specific execution model introduces new bottlenecks the original CPU algorithm never had to deal with.
What are GraphSet-P and G2Miner-P
They are two baseline systems the researchers built specifically for this paper by combining existing state of the art GPU based static graph pattern matching systems, GraphSet and G2Miner, with the incremental computation model from a leading CPU based dynamic graph pattern matching system called PSMiner. They represent a realistic, competitive baseline for what dynamic graph pattern matching on a GPU looks like without PGMiner’s specific optimizations.
How much faster is PGMiner than the alternatives
Compared with PSMiner-S, the software version of the leading CPU based dynamic graph pattern matching system, PGMiner achieved speedups ranging from 1.06 to 58.85 times, averaging 19.8 times. Compared with the two GPU based baselines built for this paper, PGMiner achieved 2.18 to 7.81 times speedup over GraphSet-P and 3.85 to 9.21 times speedup over G2Miner-P.
Does each of PGMiner’s optimizations actually help on its own
Yes, and the paper backs this with separate ablation experiments for each mechanism. Shared execution plans alone improved performance by 1.171 to 1.892 times. Adaptive task splitting alone contributed 1.31 to 1.89 times, and adding dynamic work stealing on top contributed a further 1.37 to 1.98 times. Dynamic loop unrolling improved performance by 1.51 times on average compared with no unrolling and 1.21 times compared with a simpler fixed step unrolling approach.
What hardware was used to test PGMiner
The experiments ran on a system with four 12-core Intel Xeon E5-2670 v3 CPUs and 128 gigabytes of host memory, paired with four NVIDIA Tesla V100 GPUs, compiled with GCC 7.3 and CUDA 10.1. The paper does not report testing on other GPU generations, device counts, or interconnect configurations.
Read the original research
This analysis is based on the peer reviewed, open access paper published in IEEE Transactions on Knowledge and Data Engineering, volume 38, issue 10, October 2026.