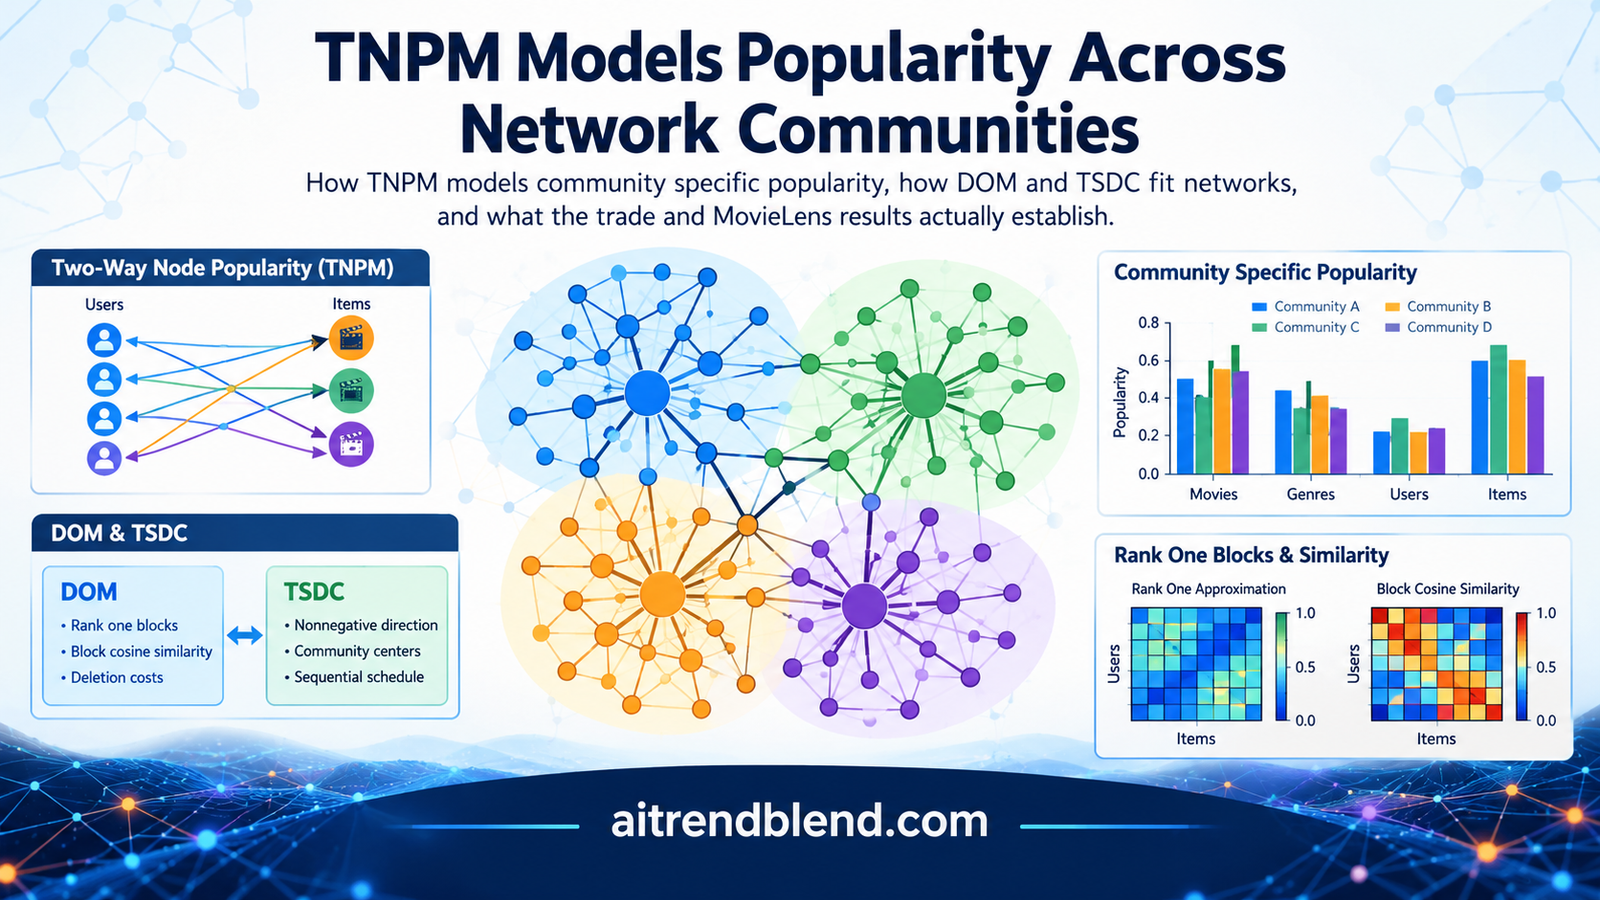
Two movie viewers can rate a similar number of films and still behave very differently. One is active around action films, another around documentaries. Their total activity hides where that activity goes. A network model that assigns each viewer one overall popularity score can miss the distinction. The Two Way Node Popularity Model gives popularity a destination community as well as a node identity.
Key points
- TNPM gives row nodes and column nodes separate community labels and separate popularity profiles across the communities on the other side.
- Its mean matrix has rank one blocks after the correct row and column rearrangement.
- DOM fits those blocks using a deletion based coordinate objective, while TSDC uses cosine similarity separately within opposite communities.
- The mean matrix and community results have assumptions that do not automatically certify the output of a practical iterative solver.
- TSDC is far faster than DOM in the displayed runtime experiments, but other methods can be faster than TSDC.
- The MovieLens application evaluates community alignment rather than held out recommendation quality or causal user preferences.
Research context
This article explains published research and is not medical advice, diagnosis or treatment. Consult a qualified professional about health decisions. The paper mentions biological network research as background but reports no clinical population, patient dataset or diagnostic validation. Its real applications concern trade and movie ratings. No medical review has been supplied.
Popularity is a profile rather than one number
A degree count describes how much a node connects. It does not describe the communities receiving those connections. That difference is especially relevant in a directed network, where sending and receiving are separate roles, or a bipartite network, where the two sides contain different kinds of objects.
Bing-Yi Jing at The Chinese University of Hong Kong, Shenzhen, Ting Li and Ya Wang at Southern University of Science and Technology, and Jiangzhou Wang at Shenzhen University formalize this distinction in Two Way Node Popularity Model for Directed and Bipartite Networks. The published paper appears in the Journal of Machine Learning Research in February 2026.
The framework is a probabilistic community model, not a graph neural network. It does not propagate learned messages through neural layers. It asks which row and column assignments make the expected interaction matrix resemble a collection of rank one blocks. That places it in the site’s broader Machine Learning category.
The authors extend ideas from stochastic block models, degree corrected models and the popularity adjusted block model. Those earlier frameworks and their references are discussed in the supplied paper. TNPM’s additional flexibility allows a node’s popularity to change across communities on the opposite side, while distinguishing outgoing and incoming structure.
This flexibility is useful only if it describes a meaningful pattern rather than absorbing noise. Adding more popularity parameters creates a richer model, but recovering communities still requires separable structure and sufficient information. The paper’s theory, fitting algorithms and empirical applications should therefore be assessed separately.
One rectangular matrix can represent two kinds of network
For a bipartite network, rows index one node set and columns index another. Users and movies are a familiar example. The matrix can be rectangular because there need not be as many users as movies. Row groups describe user communities, while column groups describe movie communities.
A directed network can use the same construction by treating a node once as a sender and once as a receiver. Rows describe outgoing interactions and columns incoming interactions. A country can consequently have one exporting community and a different importing community. Nothing in the model requires those two labels to coincide.
The distinction also permits different community counts. A matrix may have two outgoing groups and three incoming groups. Forcing the same count on both sides can impose a symmetry that the data do not possess. The trade application makes this visible rather than treating asymmetry as an implementation nuisance.
The adjacency or interaction matrix has separate row and column membership vectors. The two community counts are model choices.
The graph neural network mathematics explainer on graph representations and message passing supplies neighboring context, but its neural mechanisms should not be imported into TNPM. Here the representation is a structured statistical mean matrix, and the fitting objective uses matrix blocks directly.
The model’s defining equation
A row node has a popularity parameter for each column community. A column node has a popularity parameter for each row community. Their appropriate pair determines the mean interaction. Popularity is therefore conditional on where the other node belongs.
Equation 1 in the paper. The row parameter selects the destination community, while the column parameter selects the source community.
This is not one global outer product. The two chosen parameter columns depend on the community labels. After grouping rows and columns, however, each particular community pair does have an outer product representation.
The rank one block structure is the bridge between the probabilistic model and its algorithms. Degenerate zero blocks would have lower rank and require separate care.
Within one such block, row mean vectors differ by a multiplicative popularity factor. Their directions coincide when the factors are positive. Yet the same rows can have very different multipliers in another block. A global cosine comparison can obscure that pattern because it mixes all destination communities before normalizing.
There is also a scale ambiguity. Multiplying one block factor by a positive constant and dividing its partner by the same constant leaves the mean block unchanged. The paper therefore concentrates on recovering the block mean rather than pretending its two factor vectors have a unique absolute scale.
For Bernoulli edges, means must stay between zero and one. For general weighted observations, the permitted mean range depends on the observation model. A factorization alone does not make arbitrary products valid probabilities. The reference simulator uses bounded positive factors to ensure its Bernoulli means are valid.
What the distributional flexibility does and does not cover
Conditional on memberships, the model assumes independent entries with sub Gaussian fluctuations around their means. This covers bounded variables such as Bernoulli and fixed size Binomial observations, as well as Gaussian observations. It allows entry distributions to differ without requiring one common likelihood family.
The variance proxy controls the moment generating function. It is a tail assumption, not a statement that all observations are normally distributed.
This breadth has limits. Heavy tailed weights and dependencies between edges are not automatically covered. Transactions can share a common shock, and rating observations can reflect a shared platform process. Those possibilities require investigation rather than an appeal to the model’s general wording.
The paper also reports Poisson generated simulations. Unbounded Poisson observations are not generally sub Gaussian in the stated all real argument sense. Those experiments demonstrate empirical behavior beyond the main distributional assumptions, rather than extending the theorem to every count network. Keeping that distinction prevents simulation variety from becoming an unsupported theoretical claim.
The model addresses the interaction matrix supplied to it. If an unobserved rating is encoded as zero, zero now carries an observation meaning in the matrix objective. That meaning differs from a user assigning a low rating. A practical analysis must state how absent interactions and unmeasured values enter before treating the fitted mean as a rating preference model.
DOM fits the best rank one block for each proposed partition
With memberships fixed, the least squares fit of each block is its best rank one singular value approximation. The difficulty is finding the memberships. Searching all row and column partitions is a combinatorial problem, so the practical algorithm updates individual labels rather than enumerating every possible partition.
The fixed community count fitting criterion in Section 3.1. The projection uses the leading singular value and its corresponding vectors.
The Delete One Method examines how a block fit changes when a node is removed and then assigned to a candidate community. Only the candidate insertion costs need to be compared after the common deletion. Rows and columns are updated in turn, with earlier changes in a pass available to later updates.
The paper accelerates the resulting calculations through its singular value update machinery. That engineering detail matters because a direct implementation can repeatedly compute many small singular value decompositions. The objective is easy to write down, but a fast implementation is not obtained merely by translating its definition into nested loops.
DOM is a local search. An objective decrease does not show that the result is the global minimizer. This is particularly relevant when reading the consistency theorems, which characterize defined optimization estimators under assumptions. A practical alternating procedure can fail to reach the optimizer used in a theorem.
The authors initialize memberships through singular value decomposition and K means. Different initial assignments can lead to different solutions, so comparing several starts and inspecting final residuals is useful editorial guidance. It is not a replacement for the theoretical assumptions or a guarantee that enough starts will find the truth.
Key takeaway
The statistical target is a good partition into rank one mean blocks. DOM provides an iterative route toward that target, and its attained objective should be reported separately from a theorem about an ideal optimization estimator.
Why dividing cosine similarity helps TSDC
Suppose two rows belong to the same outgoing community. Restrict them to one incoming community and compare their population mean directions. Under positive popularity factors, their cosine similarity is one. Their lengths may differ greatly, but normalization removes that scalar difference within the block.
Repeating the comparison across incoming communities creates block cosine similarity. Each block contributes its own directional comparison before the contributions are added. The method therefore respects popularity differences across communities instead of letting the largest block dominate one global normalization.
The row similarity uses the current column partition. A corresponding column similarity uses the current row partition.
TSDC alternates a row stage and a column stage. Its cluster center within a block is an average of normalized row or column vectors. It then assigns nodes according to block similarities with those centers. The roles of the two partitions are coupled, even though the final outputs remain separate.
Equation 21 gives the normalized directional center. Zero norm blocks require an explicit implementation convention.
The text defines the TSDC objectives as quantities to maximize, but later assignment expressions and Algorithm 3 print an argmin of similarity. The reference code uses maximum similarity to match the stated objectives. This is an explicit editorial interpretation of the inconsistency, not an unreported change to a fully verified benchmark reproduction.
The paper discusses absolute cosine for signed cases. The included TSDC reference is restricted to nonnegative observations and uses ordinary cosine, avoiding a claim that one implementation covers every signed variant. Its zero vector convention assigns zero directional contribution, and it prevents a community from becoming empty.
Theorem 5 establishes existence of a pure strategy Nash equilibrium and, under its assumptions, that the true structure is such an equilibrium with high probability. The authors explain that multiple equilibria can exist. The result does not show that the equilibrium attained by TSDC necessarily converges to the true labels.
“may admit multiple PSNEs”
Jing, Li, Wang and Wang, Remark 15, explaining the limit of the TSDC equilibrium result.
What the consistency results require
The identifiability analysis assumes nonzero popularity entries and a general position condition within each community. It also places a lower bound on the network dimensions relative to the community counts. These conditions help rule out alternative partitions that reproduce the same rank one block structure.
The mean matrix estimation theorem has a different role. Theorem 2 bounds normalized squared Frobenius error for a penalized optimization estimator. It does not require all the assumptions used to uniquely identify communities. Mean estimation and label identification are therefore distinct targets in the paper itself.
For community counts, the theoretical criterion includes a complexity penalty. The practical experiment uses a reduced penalty dominated by the leading term, with a rough noise estimate based on a residual operator norm. Recovering the count is tested over a specified candidate grid. It is not an unrestricted guarantee of discovering any number of communities in any network.
Small or indistinguishable communities can weaken label recovery even if mean estimation remains useful. Very sparse observations also leave directional comparisons unstable. The Bernoulli discussion in the paper connects the error condition to a growing average degree under the specified regime. There is no general permission to ignore sparse data just because the matrix has many rows.
The same distinction between a characterized estimator and its implementation appears in our article on inference in constrained optimization. In TNPM, report the algorithm, objective, initialization and stopping rule alongside any invocation of consistency.
The runtime gap is large and specific to the experiment
The runtime comparison uses MATLAB implementations on a single processor of an Intel Core i9 12900K CPU at 3.20 GHz. The authors average over 100 simulations. Table 1 varies square matrix sizes from 360 through 1320 under Gaussian observations at two noise levels.
| Matrix size | Gaussian noise standard deviation | DOM | TSDC | SVDK |
|---|---|---|---|---|
| 360 by 360 | 0.1 | 45.44 | 0.07 | 0.03 |
| 840 by 840 | 0.1 | 421.12 | 0.21 | 0.10 |
| 1320 by 1320 | 0.1 | 1482.88 | 0.57 | 0.19 |
| 1320 by 1320 | 0.5 | 1657.89 | 0.59 | 0.19 |
TSDC is much faster than DOM in these rows. It is not the fastest of every compared method, as SVDK demonstrates. The practical choice should consider both accuracy and runtime, and timings from this implementation and hardware should not be promised for a different graph representation or processor.
The paper also combines DOM with subsampling frameworks. Local communities are detected in overlapping subnetworks, labels are aligned on shared nodes, and results are stitched together. Repetitions can improve alignment and coverage, but they add work. The overlap design is part of the method, not a detail that can be dropped without consequence.
In Table 2 at noise level 0.1, the 2000 by 2000 example reports 6594.1 seconds for DOM. DOM with SONNET, overlap sizes of 100 on each side, 20 subnetworks and two repetitions takes 239.43 seconds with reported row and column NMI of 1.00 and 1.00. Those are simulation results under a known generating model, not guarantees for every large network.
Unknown community count experiments likewise show a tradeoff. For a 600 by 600 network with true counts of three and four at noise 0.3, Table 3 reports correct count frequencies of 0.99 for DOM and 0.90 for TSDC across 100 replications. Fast fitting and reliable model selection need not rank the algorithms identically.
Trade networks reveal different importing and exporting roles
The first real application uses 2010 trade in cereals and cigarettes. The authors exclude countries with negligible trade volume using their stated first quantile rule, leaving 95 countries, and apply a logarithmic transformation to obtain two directed 95 by 95 matrices.
DOM estimates two outgoing and three incoming communities for both networks. TSDC produces the same counts for cereals but two and two for cigarettes. The authors ultimately use two and three. This disagreement belongs in the interpretation because community count selection is itself an uncertain modeling step.
No true community labels are available for these networks. The paper assesses interpretability, rearranged block patterns and latent embeddings. Those displays can support a plausible descriptive account, but they do not establish an objectively correct geopolitical partition or quantify a causal trade relationship.
Community detection groups interaction patterns. It does not explain what would happen if a country changed policy. Readers interested in that separate question can consult our article on experiment design for causal identification. The graph roles and evidence required for an intervention claim differ from the descriptive roles in TNPM.
MovieLens shows association rather than recommendation accuracy
The paper constructs a matrix with 943 users and 1682 movies, using three user groups and four movie groups. It examines how popularity varies across blocks and compares movie clusters with recorded genre information. The analysis uses the subset of 833 movies with a single genre to simplify the external comparison.
There is a source discrepancy worth correcting. Section 6.2 says 10,000 ratings, but the official GroupLens dataset README confirms 100,000 ratings from 943 users on 1682 movies. This article uses the official count and identifies the paper’s apparent typo rather than silently repeating it.
| Method | Clustering error reported in Section 6.2 |
|---|---|
| DOM | 0.384 |
| TSDC | 0.388 |
| NEM | 0.604 |
| KBCG | 0.527 |
The proposed methods have lower error under the paper’s comparison. The authors also report chi squared tests linking inferred clusters and genre categories. A small independence test probability supports an association in that table. It is not by itself an effect size, a recommendation quality score or proof that all genre distinctions have been recovered.
No held out ranking improvement, click through gain or causal preference estimate is established by this application. Patterns of rating activity can reflect who encountered which films as well as what users liked. A community model can still be useful descriptively without answering those additional questions.
This is also why preserving the encoding of missing ratings matters. The dense matrix objective treats supplied entries as information. An analyst extending the method to prediction should explicitly model missingness or observation exposure and evaluate the actual target task, rather than interpreting every zero as a negative preference.
Limitations and possible clinical translation
The rank one block assumption is both the model’s strength and its restriction. It explains how node specific scale can vary while directions align. A community pair with genuinely multiple independent interaction directions may not fit that structure. Adding communities can reduce the residual while fragmenting the interpretation.
Conditional entry independence and controlled tails are also assumptions to examine. Real networks may contain correlated observations, structural zeros and changing observation processes. General position and balance conditions appear in different parts of the theory, and the equilibrium result does not resolve sensitivity to initialization or competing equilibria.
The real datasets do not provide a universal validation set. Trade labels are unknown. Movie genres overlap, and the single genre subset excludes the remaining films from that comparison. The reported clustering association should not be generalized into a recommendation improvement for all users or a stable partition across time.
The clinical translation gap
The introduction and references mention biological network analysis, including brain connectivity research. This paper reports no patient cohort size, diagnostic performance, clinical outcome or hospital validation. There is therefore no clinical sample size or measured clinical dataset bias to quote from its applications.
A future clinical use would need a justified network construction, a clear clinical target and independent evaluation. Correlation or estimated connectivity can produce dependent edge measurements, while scanner conditions and population differences can change the matrix structure. These are questions to test in an application, not biases measured by the trade and movie experiments.
For such a project, interpreting a community as a biomarker would require additional biological and clinical evidence. A popularity factor or an interaction cluster is not a diagnosis. The article’s related medical reading provides broader context for validation questions, without claiming that those studies validate TNPM.
What this model changes
TNPM’s central contribution is a more specific view of popularity. A node is not simply active or inactive. Its activity can depend on the community it encounters, and the receiving node can respond differently across source communities. A rectangular mean matrix makes these two roles explicit.
The conceptual payoff is the rank one block structure. It turns community specific popularity into a testable matrix geometry and provides two algorithmic routes. DOM examines reconstruction error, while TSDC compares directions within estimated blocks. Their different computational costs make the choice relevant to real analysis budgets.
Transfer to other interaction datasets is plausible when separate row and column roles and community dependent activity are meaningful. That might include sender and receiver systems or collections of objects linked to a different object type. The construction, observation model and missing value semantics still need to match the application.
The remaining limitations are substantial. A richer popularity model can overfit partitions, local algorithms can reach different solutions, and sparse or dependent observations can weaken the theoretical rationale. The TSDC equilibrium result is valuable precisely when stated with its limitation, rather than promoted into a guarantee of recovering the true labels.
A useful next step is to compare simple degree correction with the richer block popularity structure, inspect residuals, vary initialization and evaluate the task that actually matters. If the intended output is a recommendation, test recommendations. If it is a descriptive partition, examine its stability and interpretation. If it is a causal conclusion, use a causal design.
The paper earns attention by asking where popularity goes. Preserve that question in implementation, and make the strength of the conclusion match the evidence used to answer it.
PyTorch reference implementation
The listing includes a TNPM mean model, an illustrative Bernoulli simulator, block rank one fitting, deletion based coordinate updates, divided cosine centers, a training loop, evaluation and a runnable smoke test. It contains no neural layers because the proposed model is statistical rather than neural.
The DOM reference computes exact insertion costs through small singular value decompositions. It omits the paper’s incremental acceleration, so it is designed for small matrices and should not be expected to reproduce the runtime table. It uses known community counts and does not implement the penalized count search or SONNET stitching.
The TSDC reference uses nonnegative observations, maximum similarity and a sequential row then column schedule. It explicitly handles zero vectors, protects nonempty groups and stops when labels stabilize or an iteration cap is reached. These are disclosed engineering choices. Its rank one residual is monitored but is not asserted to decrease because TSDC optimizes a different objective.
Syntax and independent numerical checks passed. The PyTorch runtime is unavailable here, so the included smoke test was not executed. No simulated output is presented as a reproduced paper result. Compare the reference with the authors’ implementation before claiming replication.
"""Editorial CPU float64 PyTorch reference for TNPM.
Implements TNPM simulation, block rank-one fitting, exact delete-one
coordinate costs, and divided cosine clustering for nonnegative data.
Requires torch, numpy, scikit-learn. No neural architecture is invented.
The DOM reference recomputes small SVDs instead of the paper's fast
incremental singular-value operations. No SONNET stitching is included.
TSDC uses maximum similarity, consistent with objectives 19 and 20.
Nonempty groups, sequential reassignment, label-stability stopping and
zero-vector handling are explicit editorial safeguards.
"""
import torch
from torch import nn

DTYPE = torch.float64


def validate(a, k, l):
    a = torch.as_tensor(a, dtype=DTYPE, device='cpu')
    if a.ndim != 2 or not torch.isfinite(a).all():
        raise ValueError('Need a finite rectangular adjacency matrix')
    if not 1 <= k <= a.shape[0] or not 1 <= l <= a.shape[1]:
        raise ValueError('Invalid number of row or column groups')
    return a


def unit_rows(a):
    length = torch.linalg.vector_norm(a, dim=1, keepdim=True)
    return a / length.clamp_min(torch.finfo(a.dtype).eps)


def rank_one(a):
    if a.numel() == 0:
        return torch.zeros_like(a)
    u, s, vh = torch.linalg.svd(a, full_matrices=False)
    return s[0] * u[:, :1] @ vh[:1, :]


def rank_error(a):
    if a.numel() == 0:
        return 0.0
    return float((a - rank_one(a)).square().sum())


def balanced_labels(n, groups, seed):
    generator = torch.Generator().manual_seed(seed)
    return (torch.arange(n) % groups)[torch.randperm(n, generator=generator)]


def initialize(a, k, l, seed=42):
    """SVD/K-means initialization, with explicit nonempty fallback."""
    from sklearn.cluster import KMeans
    u, _, vh = torch.linalg.svd(a, full_matrices=False)
    dimension = min(max(k, l), min(a.shape))
    c = torch.as_tensor(KMeans(k, n_init=10, random_state=seed)
                        .fit_predict(u[:, :dimension].numpy()), dtype=torch.long)
    z = torch.as_tensor(KMeans(l, n_init=10, random_state=seed)
                        .fit_predict(vh.T[:, :dimension].numpy()), dtype=torch.long)
    if torch.unique(c).numel() != k:
        c = balanced_labels(a.shape[0], k, seed)
    if torch.unique(z).numel() != l:
        z = balanced_labels(a.shape[1], l, seed + 1)
    return c, z


class TNPM(nn.Module):
    def __init__(self, a, k, l, seed=42):
        super().__init__()
        a = validate(a, k, l)
        c, z = initialize(a, k, l, seed)
        self.k, self.l = k, l
        self.register_buffer('A', a)
        self.register_buffer('c', c)
        self.register_buffer('z', z)
        self.register_buffer('P', torch.zeros_like(a))

    @torch.no_grad()
    def fit_mean(self):
        self.P.zero_()
        for k in range(self.k):
            rows = torch.where(self.c == k)[0]
            for l in range(self.l):
                cols = torch.where(self.z == l)[0]
                block = self.A[rows[:, None], cols[None, :]]
                self.P[rows[:, None], cols[None, :]] = rank_one(block)
        return self.P

    def forward(self):
        return self.P

    @torch.no_grad()
    def loss(self):
        self.fit_mean()
        return float((self.A - self.P).square().sum())


def deletion_cost(a, labels, opposite, node, candidate, opposite_groups):
    """Insertion loss in one candidate community after deleting the node.

    Sum the change in best rank-one residual over opposite communities.
    Removed-node blocks are independent of its next candidate label.
    This is the exact leave-one-out objective, without acceleration.
    """
    base = torch.where((labels == candidate) & (torch.arange(len(labels)) != node))[0]
    extended = torch.cat((base, torch.tensor([node])))
    cost = 0.0
    for group in range(opposite_groups):
        cols = torch.where(opposite == group)[0]
        before = a[base[:, None], cols[None, :]]
        after = a[extended[:, None], cols[None, :]]
        cost += rank_error(after) - rank_error(before)
    return cost


@torch.no_grad()
def fit_dom(model, max_iter=20, tol=1e-7):
    history = [model.loss()]
    for _ in range(max_iter):
        changed = 0
        for a, labels, opposite, groups, opposite_groups in [
                (model.A, model.c, model.z, model.k, model.l),
                (model.A.T, model.z, model.c, model.l, model.k)]:
            for node in range(len(labels)):
                current = int(labels[node])
                # Explicit safeguard prevents deleting a group's sole node.
                if int((labels == current).sum()) == 1:
                    continue
                costs = [deletion_cost(a, labels, opposite, node, group, opposite_groups)
                         for group in range(groups)]
                best = min(range(groups), key=lambda group: costs[group])
                if costs[best] < costs[current] - tol:
                    labels[node] = best
                    changed += 1
        loss = model.loss()
        if loss > history[-1] + 1e-6 * max(1., history[-1]):
            raise RuntimeError('Coordinate objective unexpectedly increased')
        history.append(loss)
        if changed == 0:
            return history, 'labels stable'
    return history, 'iteration cap reached'


def block_centers(a, labels, opposite, groups, opposite_groups):
    centers = torch.zeros((groups, a.shape[1]), dtype=DTYPE)
    for group in range(groups):
        rows = torch.where(labels == group)[0]
        if not len(rows):
            raise ValueError('Empty group')
        for other in range(opposite_groups):
            cols = torch.where(opposite == other)[0]
            block = a[rows[:, None], cols[None, :]]
            centers[group, cols] = unit_rows(block).mean(0)
    return centers


def divided_scores(a, centers, opposite, opposite_groups):
    scores = torch.zeros((a.shape[0], centers.shape[0]), dtype=DTYPE)
    for group in range(opposite_groups):
        index = torch.where(opposite == group)[0]
        scores += unit_rows(a[:, index]) @ unit_rows(centers[:, index]).T
    return scores / opposite_groups


def reassign(scores, labels, groups):
    counts = torch.bincount(labels, minlength=groups)
    changed = 0
    for node in range(len(labels)):
        old = int(labels[node]); new = int(scores[node].argmax())
        if old != new and counts[old] > 1 and scores[node, new] > scores[node, old] + 1e-12:
            labels[node] = new
            counts[old] -= 1; counts[new] += 1
            changed += 1
    return changed


@torch.no_grad()
def fit_tsdc(model, max_iter=50):
    """Nonnegative cosine variant. Not the signed absolute-cosine variant."""
    if (model.A < 0).any():
        raise ValueError('This reference TSDC variant requires nonnegative observations')
    history = []
    for _ in range(max_iter):
        row_centers = block_centers(model.A, model.c, model.z, model.k, model.l)
        scores = divided_scores(model.A, row_centers, model.z, model.l)
        changed = reassign(scores, model.c, model.k)
        # Recompute column centers after the row stage for an explicit
        # sequential alternating schedule rather than using stale centers.
        col_centers = block_centers(model.A.T, model.z, model.c, model.l, model.k)
        scores_col = divided_scores(model.A.T, col_centers, model.c, model.k)
        changed += reassign(scores_col, model.z, model.l)
        history.append(dict(changed=changed, rank_one_loss=model.loss()))
        # Rank-one loss is monitored, not asserted to decrease for TSDC.
        if changed == 0:
            return history, 'labels stable'
    return history, 'iteration cap reached'


def simulate(n=80, m=70, k=2, l=3, seed=42):
    """Illustrative Bernoulli TNPM, not the paper's benchmark generator."""
    generator = torch.Generator().manual_seed(seed)
    c = balanced_labels(n, k, seed); z = balanced_labels(m, l, seed + 1)
    v = 0.1 + 0.8 * torch.rand((n, l), generator=generator, dtype=DTYPE)
    vt = 0.1 + 0.8 * torch.rand((m, k), generator=generator, dtype=DTYPE)
    p = v[:, z] * vt[:, c].T
    a = torch.bernoulli(p, generator=generator)
    return a, p, c, z


def evaluate(model, p=None, row_truth=None, col_truth=None):
    from sklearn.metrics import adjusted_rand_score, normalized_mutual_info_score
    model.fit_mean()
    report = dict(rank_one_loss=model.loss())
    if p is not None:
        report['mean_matrix_mse'] = float((model.P - p).square().mean())
    for label, fitted, truth in [('rows', model.c, row_truth), ('columns', model.z, col_truth)]:
        if truth is not None:
            report[label + '_ari'] = adjusted_rand_score(truth.numpy(), fitted.numpy())
            report[label + '_nmi'] = normalized_mutual_info_score(truth.numpy(), fitted.numpy())
    return report


def smoke_test():
    a, p, c, z = simulate(n=24, m=21, seed=9)
    model = TNPM(a, 2, 3)
    model.c.copy_(c); model.z.copy_(z)
    for k in range(2):
        for l in range(3):
            block = p[c == k][:, z == l]
            torch.testing.assert_close(rank_one(block), block, atol=1e-10, rtol=1e-10)
    # Check scale ambiguity does not change a rank-one block.
    v = torch.tensor([1., 2.], dtype=DTYPE); w = torch.tensor([3., 4.], dtype=DTYPE)
    torch.testing.assert_close(torch.outer(v, w), torch.outer(5*v, w/5))
    model = TNPM(a, 2, 3, seed=2)
    history, status = fit_dom(model, max_iter=3)
    assert all(b <= a + 1e-6 for a, b in zip(history, history[1:]))
    tsdc = TNPM(a, 2, 3, seed=2)
    _, cosine_status = fit_tsdc(tsdc, max_iter=10)
    assert torch.unique(tsdc.c).numel() == 2 and torch.unique(tsdc.z).numel() == 3
    print('Reference checks passed', status, cosine_status)


if __name__ == '__main__':
    smoke_test()
Frequently asked questions
How is TNPM different from a single popularity score?
A row node has a popularity parameter for each column community, and a column node has a parameter for each row community. Popularity can therefore vary across the opposite side’s groups.
Can the same directed node have two community labels?
Yes. Its outgoing and incoming roles are represented separately, and the row and column community counts can differ.
What is the difference between DOM and TSDC?
DOM minimizes block rank one reconstruction error through deletion based label updates. TSDC compares normalized directions separately within estimated opposite communities.
Does the TSDC theorem guarantee recovery of true labels?
No. It establishes equilibrium results under stated assumptions. Multiple equilibria can exist, so the attained solution is not guaranteed to converge to the true community labels.
How many ratings are in MovieLens 100K?
The official GroupLens README gives 100,000 ratings from 943 users on 1682 movies. The paper’s statement of 10,000 ratings appears to be a typo.
Has the PyTorch code reproduced the paper’s results?
No. It is an editorial reference with disclosed safeguards and scope limits. Syntax and independent numerical checks passed, but the PyTorch smoke test was not run here. Runtime, subsampling and benchmark reproduction are not claimed.
Read the research and inspect its implementation
Compare the model assumptions, fitting objectives and experiment settings with the network you intend to analyze.
Read the published paperOpen the authors’ codeBing-Yi Jing, Ting Li, Jiangzhou Wang and Ya Wang. Two Way Node Popularity Model for Directed and Bipartite Networks. Journal of Machine Learning Research, volume 27, article 43, pages 1 to 73, 2026. Publisher record.
This analysis is based on the published paper and an independent evaluation of its claims.
Related reading in Machine Learning
These articles provide neighboring graph, optimization and medical research context. They do not supply independent validation of TNPM.