Knowledge Distillation

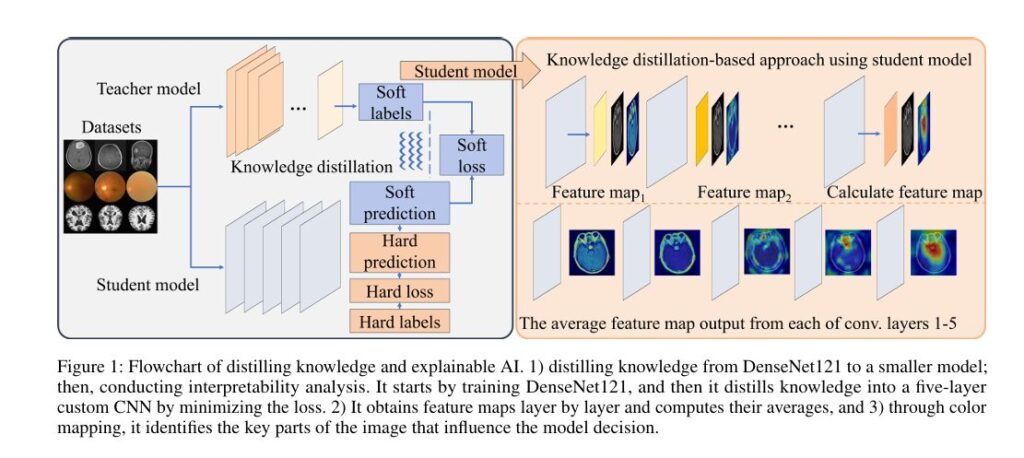
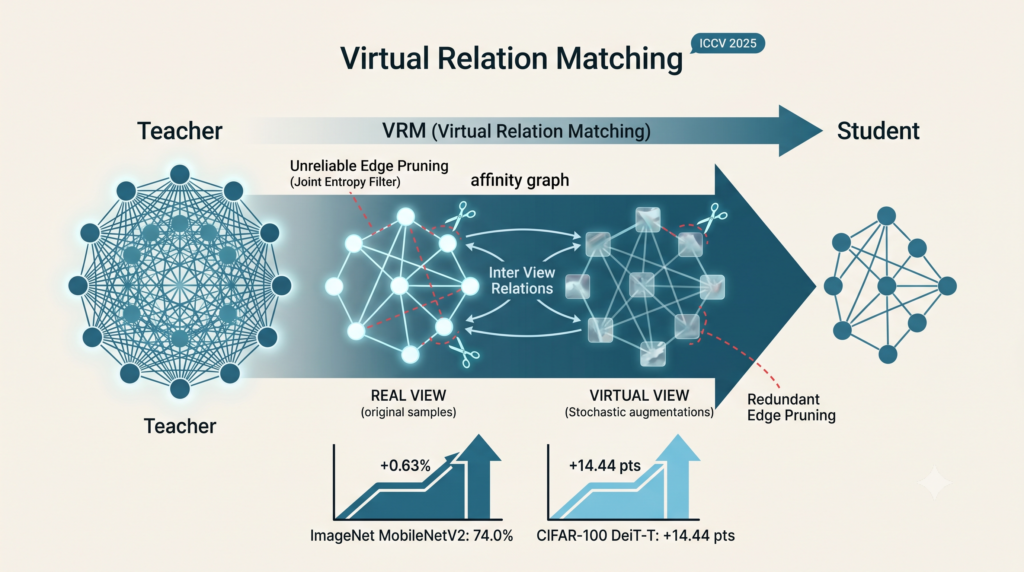
Knowledge distillation is how a small, fast model learns to behave like a large, accurate one, keeping most of the quality while shedding the cost of running it. This category collects plain language breakdowns of the research that moves the field forward, from the classic KL divergence losses through newer token level and ranking based objectives. Every analysis explains the core idea, the math that makes it work, and the limitations the authors are honest about, and most ship with runnable code you can drop straight into your own training pipeline. It is built for practitioners who want to understand a method well enough to use it, not just cite it.

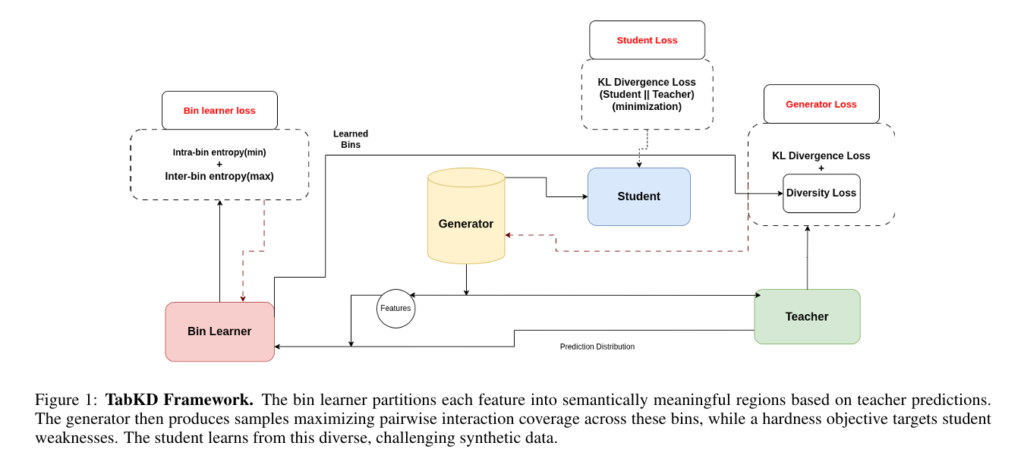
TabKD: Data-Free Knowledge Distillation for Tabular Models via Interaction Diversity.

TabKD: Data-Free Knowledge Distillation for Tabular Models via Interaction Diversity

Researchers at UT Arlington built a data-free knowledge distillation framework for tabular models that borrows a principle from software testing — systematically covering all pairs of feature interactions — and achieves the best student-teacher agreement in 14 of 16 benchmark…

TabKD: Data-Free Knowledge Distillation for Tabular Models via Interaction Diversity Read More »

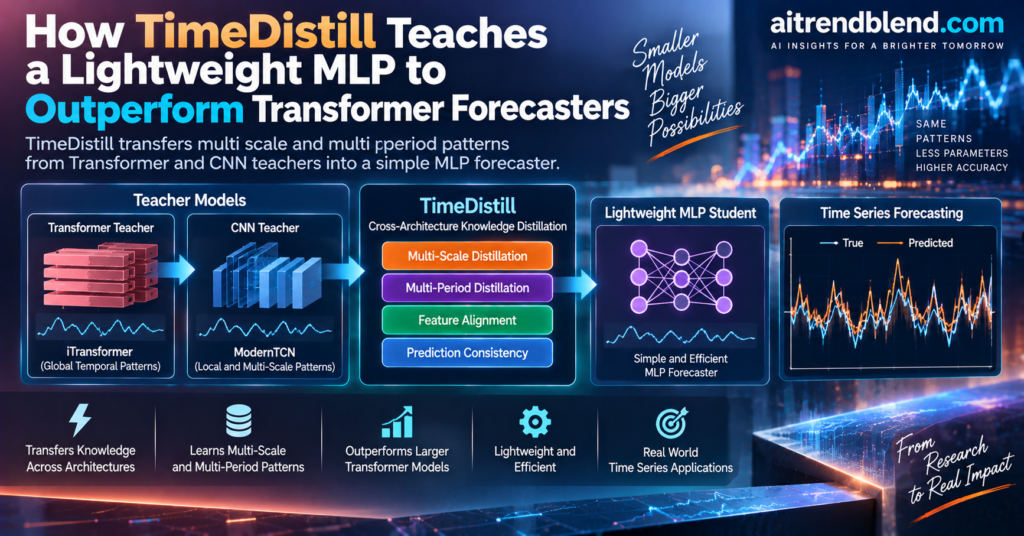
How TimeDistill Teaches a Lightweight MLP to Outperform Transformer Forecasters

How TimeDistill Teaches a Lightweight MLP to Outperform Transformer Forecasters

Forecasting research has spent the last few years arguing with itself. Transformers arrived promising to capture long range dependencies across a time series, and models like Informer and Autoformer chased that promise with increasingly elaborate attention mechanisms. Then a 2023…

How TimeDistill Teaches a Lightweight MLP to Outperform Transformer Forecasters Read More »

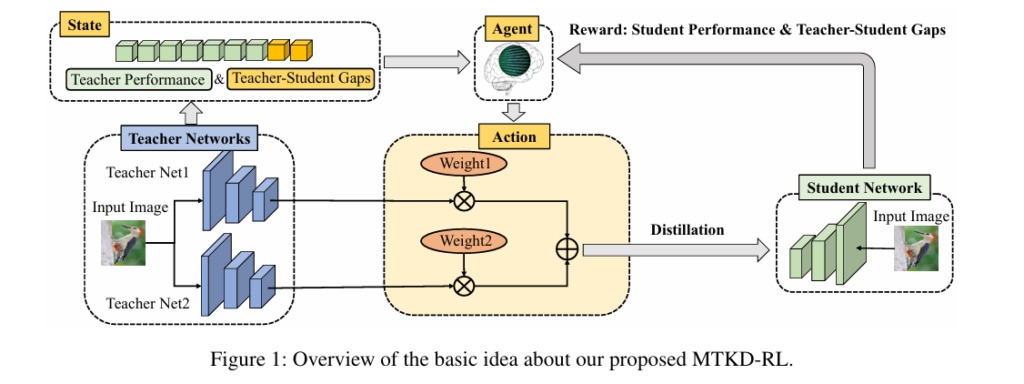
Diagram of Multi-Teacher Knowledge Distillation with Reinforcement Learning (MTKD-RL)

Multi-Teacher Knowledge Distillation with RL — Teaching the Agent Which Teacher to Trust

MTKD-RL from the Institute of Computing Technology, Chinese Academy of Sciences — an RL agent arbitrates teacher weights dynamically, improving student accuracy across image classification, object detection, and semantic segmentation.

Multi-Teacher Knowledge Distillation with RL — Teaching the Agent Which Teacher to Trust Read More »