Knowledge Distillation

Knowledge distillation is how a small, fast model learns to behave like a large, accurate one, keeping most of the quality while shedding the cost of running it. This category collects plain language breakdowns of the research that moves the field forward, from the classic KL divergence losses through newer token level and ranking based objectives. Every analysis explains the core idea, the math that makes it work, and the limitations the authors are honest about, and most ship with runnable code you can drop straight into your own training pipeline. It is built for practitioners who want to understand a method well enough to use it, not just cite it.

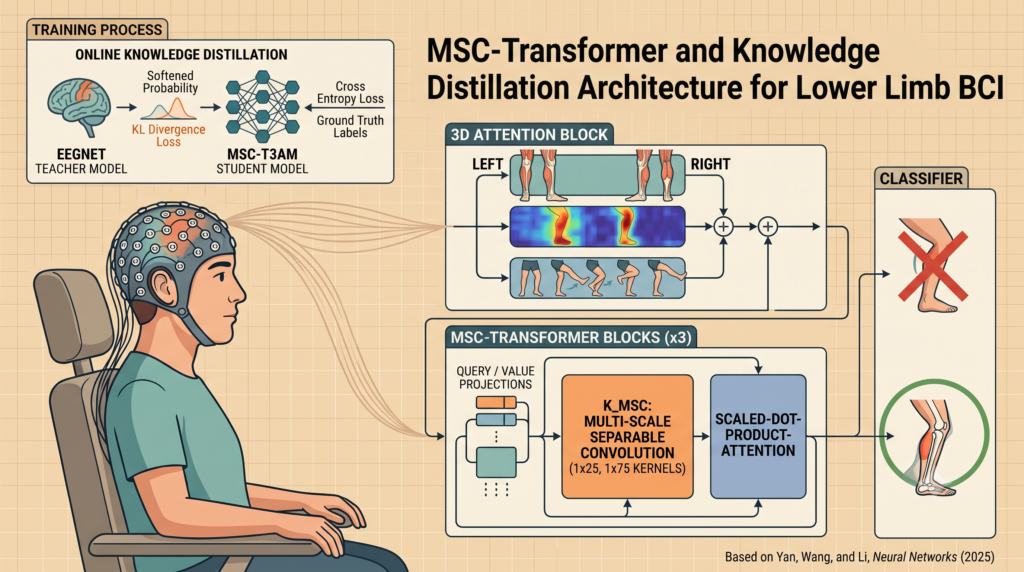
How a Transformer MSC-T3AM Learns to Tell Your Left Leg From Your Right on EEG.

How a Transformer MSC-T3AM Learns to Tell Your Left Leg From Your Right on EEG

Motor imagery research has a long history, and most of it points at the hands. You imagine gripping something, a classifier tries to figure out which hand you meant, and there are entire competition datasets built around exactly that setup.…

How a Transformer MSC-T3AM Learns to Tell Your Left Leg From Your Right on EEG Read More »

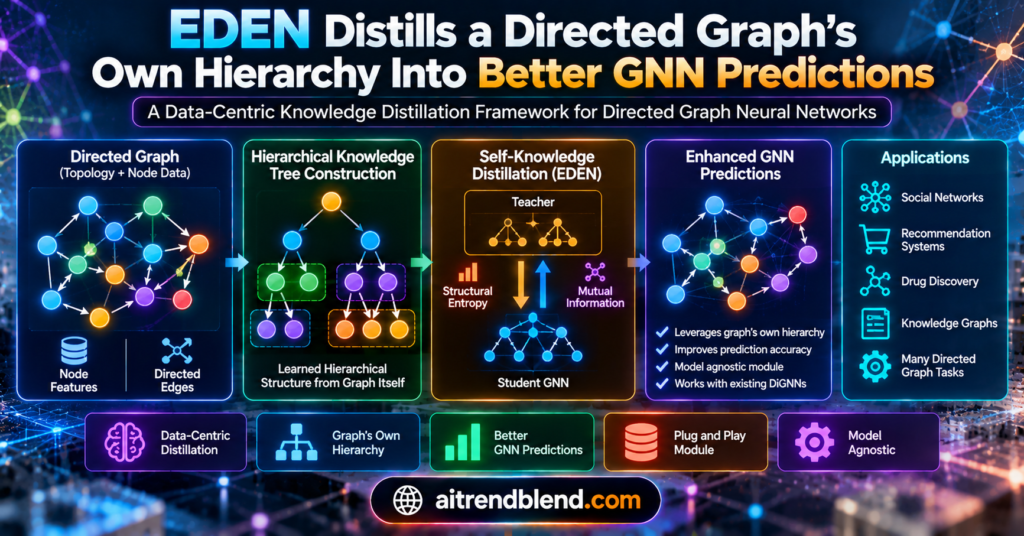
EDEN Distills a Directed Graph's Own Hierarchy Into Better GNN Predictions

EDEN Distills a Directed Graph’s Own Hierarchy Into Better GNN Predictions

Graph neural networks have posted strong results on node classification, link prediction and graph level tasks for years now, but the field’s research energy has overwhelmingly gone into model architecture. New attention mechanisms, new convolution operators, new ways of combining…

EDEN Distills a Directed Graph’s Own Hierarchy Into Better GNN Predictions Read More »