Vision Transformers & Attention

Attention mechanisms, vision transformers, and the architectures replacing convolutions across vision tasks. We unpack how attention is used, misused, and reinvented in current research, from efficient attention branches to Mamba-style state space models.

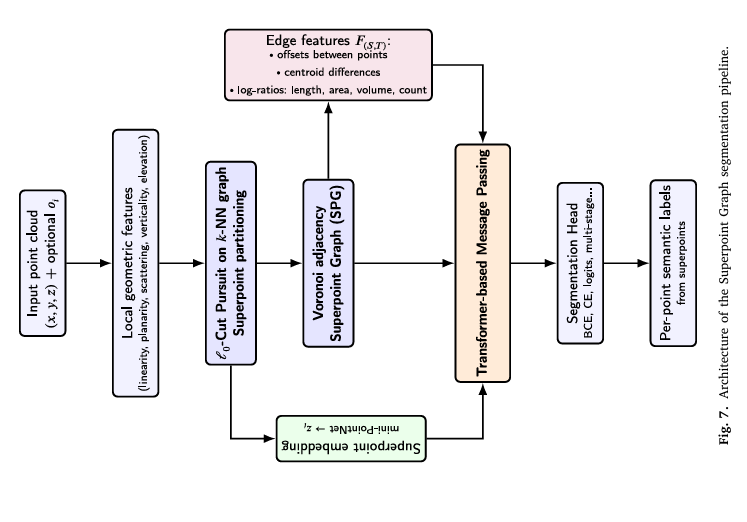
Railway Sinkhole Detection with Physics-Informed Synthetic Data and SuperPoint Transformer.

Railway Sinkhole Detection with Physics-Informed Synthetic Data and SuperPoint Transformer

When you only have a handful of real sinkhole examples, you either accept poor detection or get creative about generating training data. Researchers at Arts et Métiers ParisTech and SNCF Réseau chose the latter — building physics-informed synthetic sinkholes, embedding…

Railway Sinkhole Detection with Physics-Informed Synthetic Data and SuperPoint Transformer Read More »

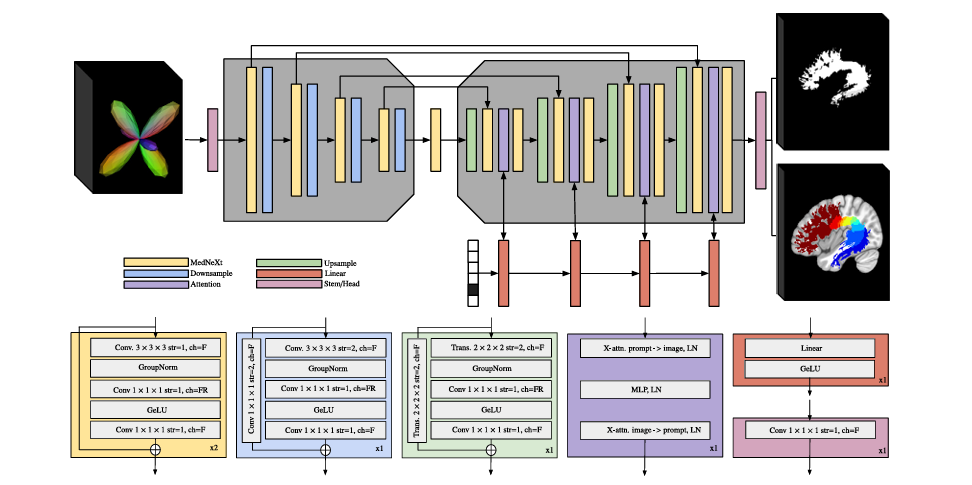
BundleParc: Tractography-Free White Matter Bundle Parcellation with MedNeXt + Cross-Attention

BundleParc: Tractography-Free White Matter Bundle Parcellation with MedNeXt + Cross-Attention

Researchers at Université de Sherbrooke built a prompt-conditioned MedNeXt encoder-decoder that reads fiber orientation maps and outputs anatomically consistent white matter parcellations in seconds — without generating a single streamline — outperforming all competing methods on reproducibility across healthy subjects,…

BundleParc: Tractography-Free White Matter Bundle Parcellation with MedNeXt + Cross-Attention Read More »

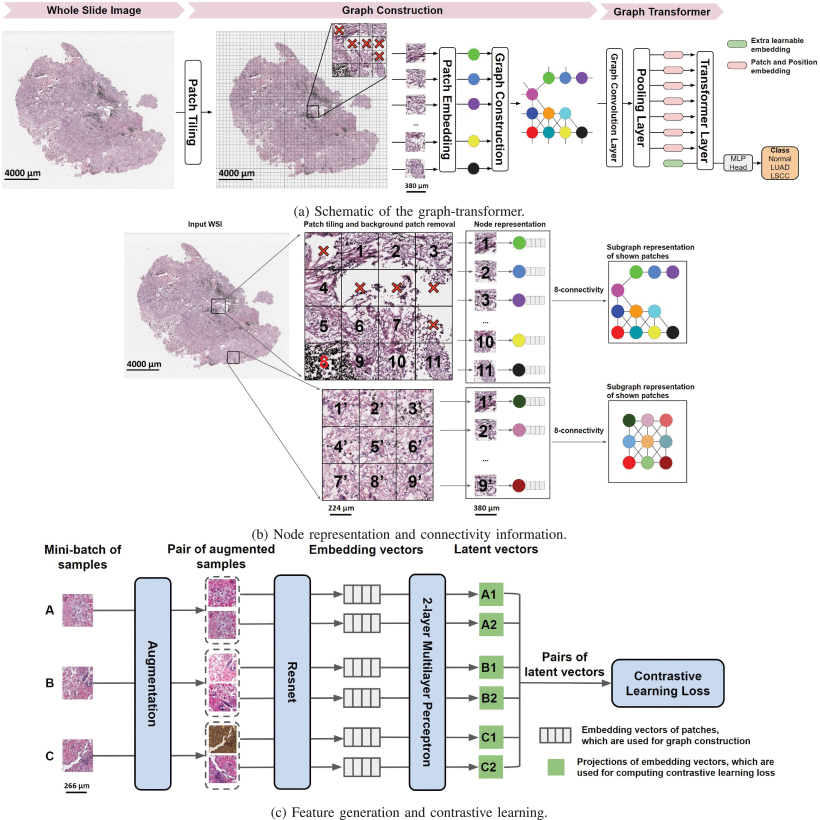
GTP: The Graph-Transformer That Reads Whole Slide Pathology Images Like a Pathologist

GTP: The Graph-Transformer That Reads Whole Slide Pathology Images Like a Pathologist

A team at Boston University built GTP — a Graph-Transformer for Pathology that fuses graph convolutional networks with vision transformers to classify gigapixel whole slide images of lung cancer at 91.2% accuracy, plus a novel GraphCAM technique that highlights exactly…

GTP: The Graph-Transformer That Reads Whole Slide Pathology Images Like a Pathologist Read More »

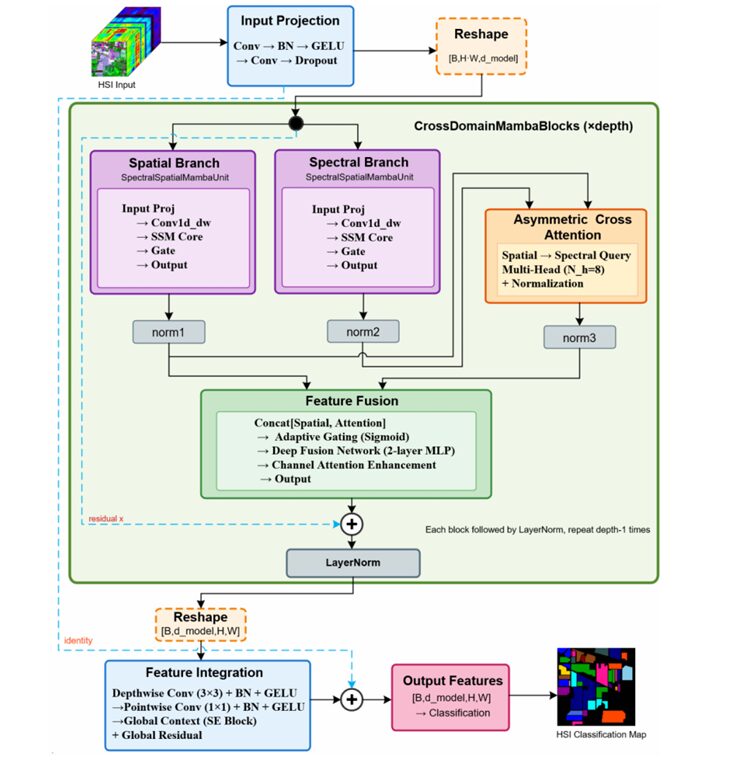
SSA-Mamba: The Hyperspectral Classifier That Finally Lets Spatial and Spectral Features Talk to Each Other

SSA-Mamba: The Hyperspectral Classifier That Finally Lets Spatial and Spectral Features Talk to Each Other

Researchers at Guangzhou Maritime University diagnosed a fundamental flaw in every existing hyperspectral classification model — spatial and spectral features are either forced to share the same representation space, or kept so separate they never productively interact. SSA-Mamba fixes both…

SSA-Mamba: The Hyperspectral Classifier That Finally Lets Spatial and Spectral Features Talk to Each Other Read More »

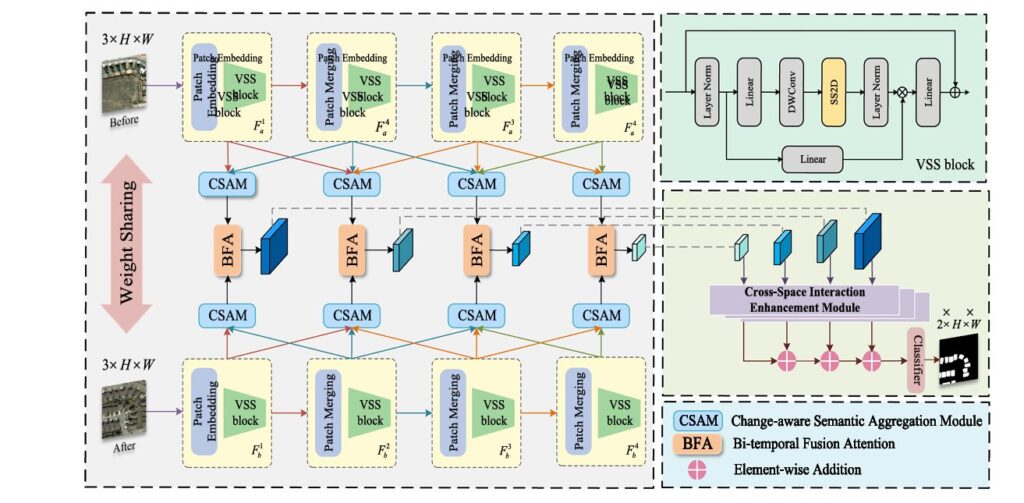
GLMamba: How Global-Local Mamba Detects Change in Satellite Images Better Than CNNs and Transformers.

GLMamba: How Global-Local Mamba Detects Change in Satellite Images Better Than CNNs and Transformers

Shengyan Liu and Min Xia at NUIST introduce GLMamba: a Siamese Mamba network that pairs global state-space modeling with local convolutional detail extraction for remote sensing change detection. On LEVIR-CD it posts F1=91.27% and IoU=83.94%, outperforming ChangeMamba, ChangeFormer, and nine…

GLMamba: How Global-Local Mamba Detects Change in Satellite Images Better Than CNNs and Transformers Read More »

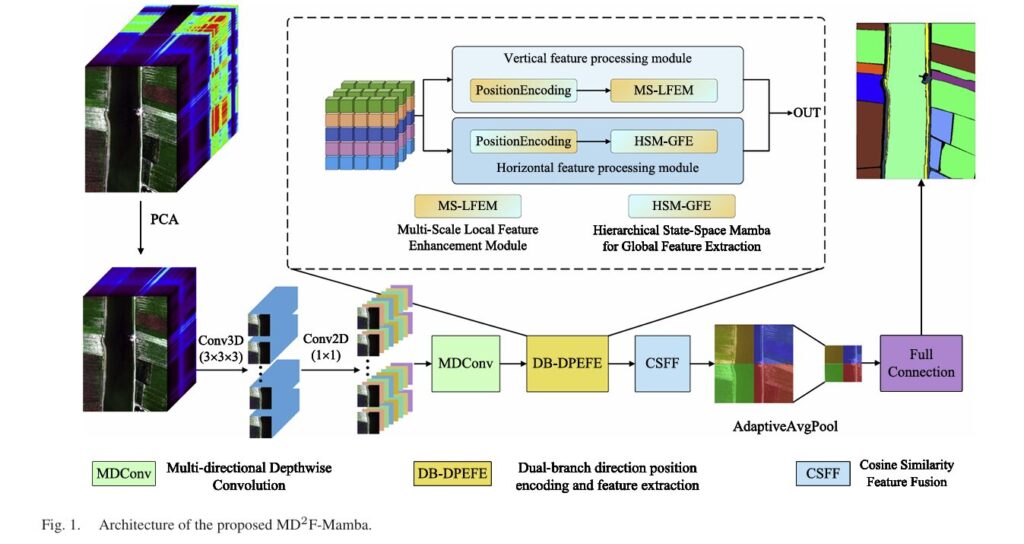
MD2F-Mamba: How Directional Convolution and Dual-Branch Mamba Crack Hyperspectral Image Classification.

MD2F-Mamba: How Directional Convolution and Dual-Branch Mamba Crack Hyperspectral Image Classification

Xiaoqing Wan and colleagues at Hengyang Normal University introduce MD2F-Mamba: a dual-branch architecture pairing multidirectional depthwise convolution with a hierarchical state-space Mamba for hyperspectral classification. With just 92K parameters and 8.3M FLOPs, it posts 99.81% overall accuracy on Pavia University…

MD2F-Mamba: How Directional Convolution and Dual-Branch Mamba Crack Hyperspectral Image Classification Read More »

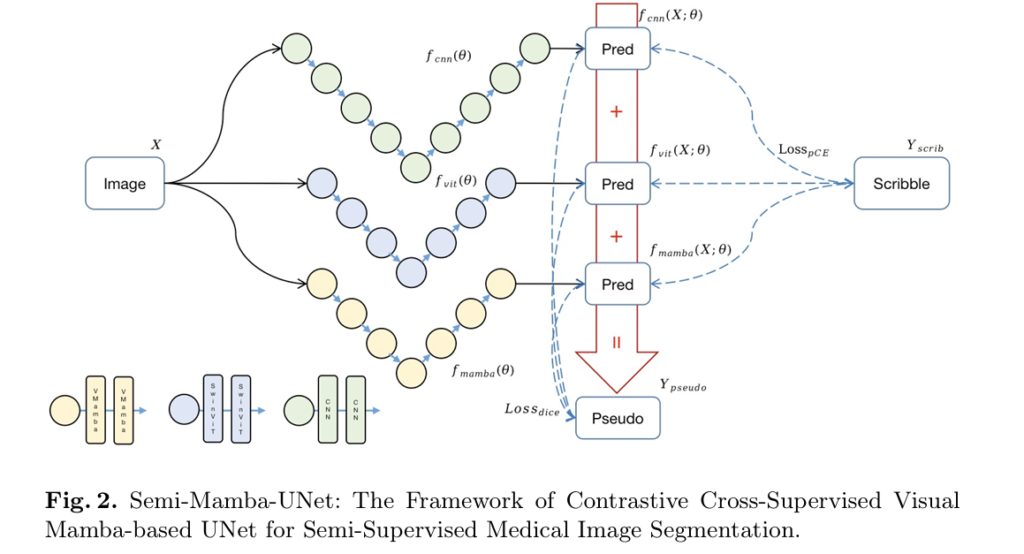
Weak-Mamba-UNet: How CNN, ViT, and Visual Mamba Collaborate to Segment Medical Images from Scribbles

Weak-Mamba-UNet: How CNN, ViT, and Visual Mamba Collaborate to Segment Medical Images from Scribbles

Ziyang Wang at Oxford and Chao Ma introduce Weak-Mamba-UNet: the first weakly-supervised framework that runs CNN, Vision Transformer, and Visual Mamba together under scribble supervision, letting each architecture’s strengths cover the others’ blind spots. On MRI cardiac segmentation, it achieves…

Weak-Mamba-UNet: How CNN, ViT, and Visual Mamba Collaborate to Segment Medical Images from Scribbles Read More »

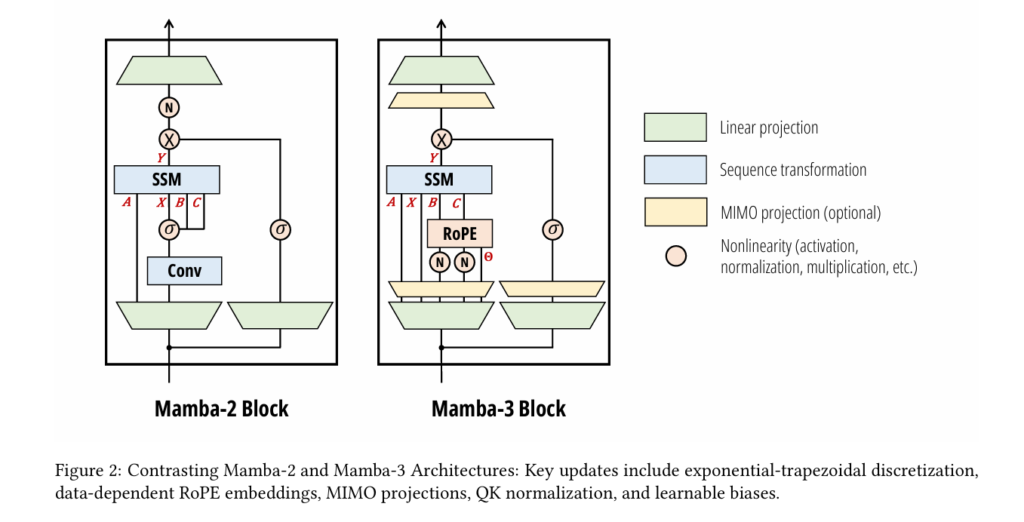
Mamba-3: Three Simple Ideas That Finally Fix What Transformers Get Wrong at Inference.

Mamba-3: Three Simple Ideas That Finally Fix What Transformers Get Wrong at Inference

Researchers at Carnegie Mellon and Princeton took a hard look at why sub-quadratic models keep losing to Transformers on capability while supposedly winning on efficiency — then fixed it. Mamba-3 combines a theoretically grounded discretization, complex-valued states for real tracking…

Mamba-3: Three Simple Ideas That Finally Fix What Transformers Get Wrong at Inference Read More »

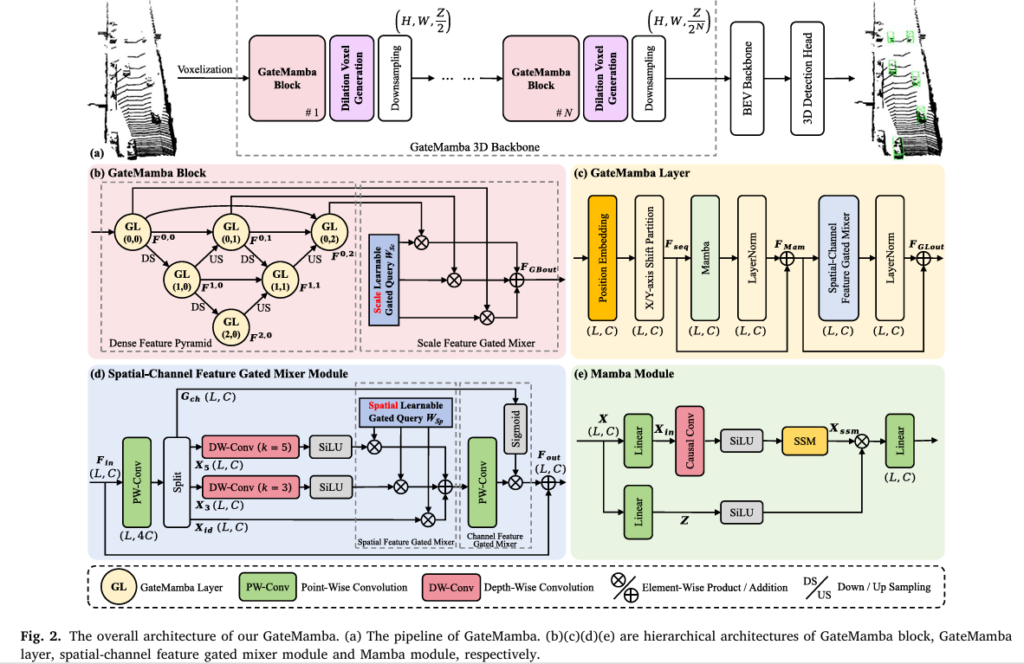
GateMamba: Feature Gated Mixer in State Space Model for Point Cloud 3D Object Detection.

GateMamba: Feature Gated Mixer in State Space Model for Point Cloud 3D Object Detection

Mamba-based 3D detectors achieve impressive overall numbers but consistently under-perform on small and distant targets — the problem is architectural: unidirectional scanning and crude downsampling let weak foreground signals drown in background noise. Researchers at NUDT and Sun Yat-sen University…

GateMamba: Feature Gated Mixer in State Space Model for Point Cloud 3D Object Detection Read More »