A diabetes research team can predict whether a patient’s HbA1c will be controlled after a year, but a colleague asks a harder question. Which recorded characteristics actually drive the fitted decision rule, and how uncertain are those coefficients? A support vector machine can classify well without supplying a valid answer. This paper builds an inference procedure for that gap, including settings where there are more candidate variables than observations.
- The target is a coefficient or sparse projection of a population surrogate loss minimizer.
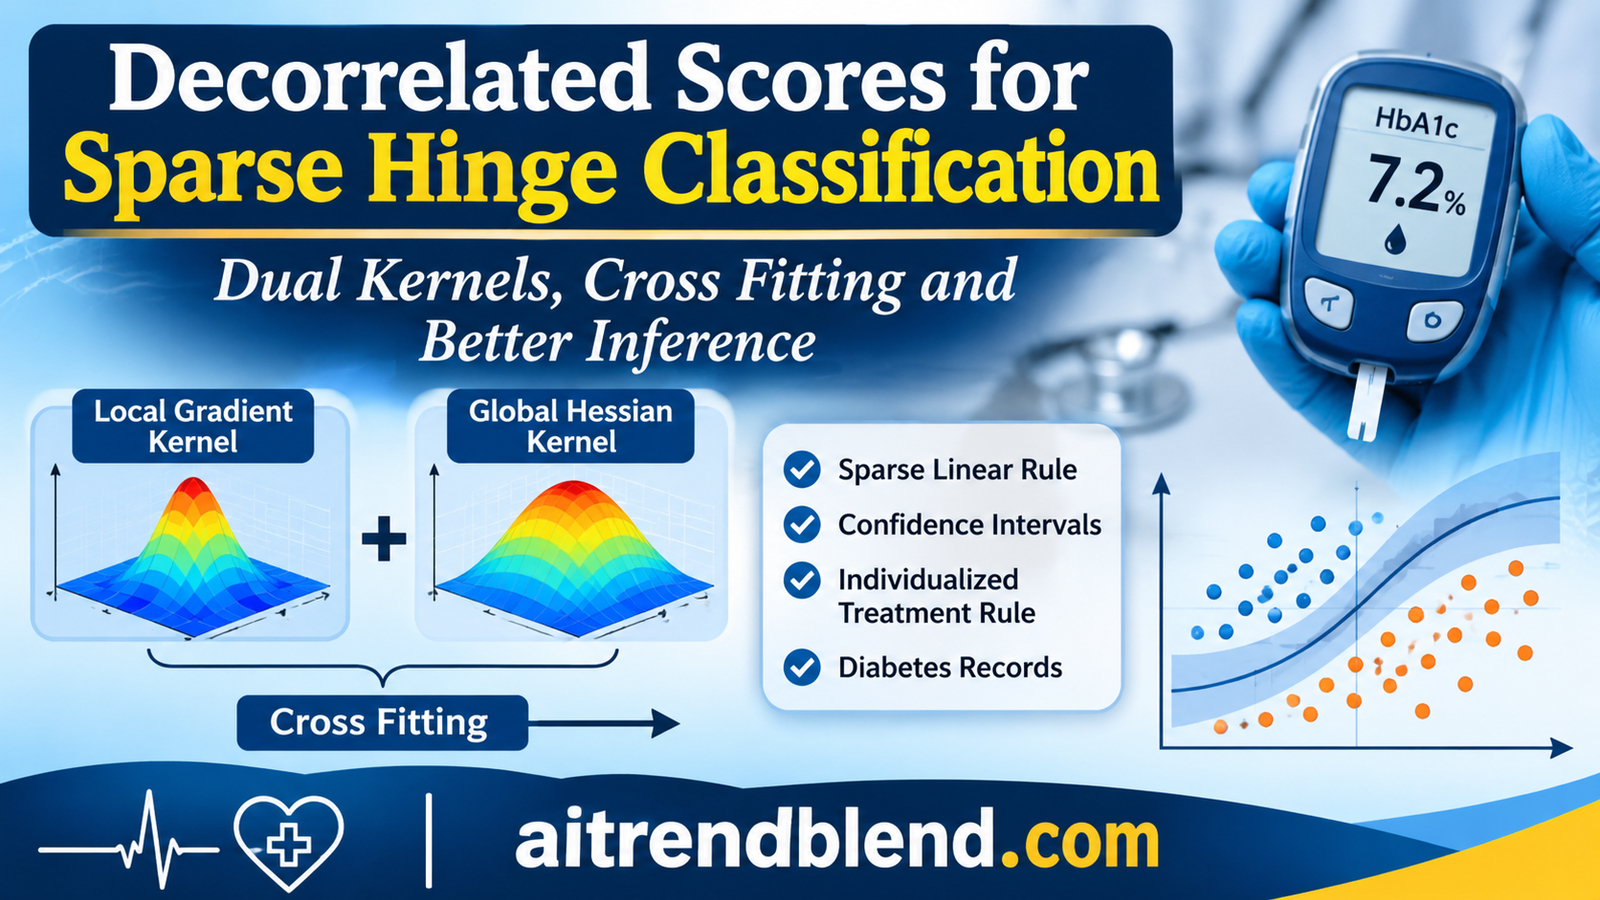
- A local kernel smooths the discontinuous gradient, while a global kernel approximates the curvature needed for decorrelation.
- Sample splitting separates classifier fitting from score evaluation, with another cross fitting layer when weights contain estimated nuisance functions.
- The theory allows dimension to exceed sample size under sparsity, bounded design and convergence conditions.
- The diabetes analysis uses 9101 patients and 120 screened predictors, but does not establish a validated treatment policy.
- Reported clinical values and apparent formula ambiguities require careful interpretation before reuse.
This article explains published research. It is not medical advice, diagnosis or treatment. Consult a qualified health professional about personal care. No medical reviewer was supplied, and the statistical examples do not recommend a treatment for any individual.
Why a good classifier still needs an inference procedure
Accuracy measures how often predicted labels match observed labels. It does not measure how much a particular coefficient would vary if the dataset were collected again. That difference matters when a fitted rule is used to generate scientific hypotheses or explain which variables contribute to a decision.
Muxuan Liang, Yang Ning, Maureen A Smith and Ying Qi Zhao address this issue in their published study of inference with a nondifferentiable surrogate loss. The paper appears in the Journal of Machine Learning Research, volume 27, article 53, in 2026. Its authors work across MD Anderson Cancer Center, Cornell University, the University of Wisconsin and Fred Hutchinson Cancer Center.
The method is statistical machinery around a linear decision rule. It is not a new deep neural architecture. Its purpose is to construct hypothesis tests and interval estimators when penalization and a kinked loss prevent ordinary coefficient inference from working directly.
The clinical examples place the article in the Medical AI collection within Machine Learning. The central practical question is whether uncertainty statements about a learned rule are justified. That question deserves separate attention from the quality of the rule’s predictions.
The coefficient target is defined by the chosen loss
The ordinary classification setup observes a covariate vector and a binary label. A linear score determines the decision through its sign. Instead of directly minimizing classification error, the analyst fits a convex surrogate such as the hinge loss, with an absolute value penalty to encourage sparsity.
The inferential target is the population minimizer of the unpenalized surrogate risk. A selected coordinate or a known sparse projection of that vector is the quantity tested. It is not automatically a regression coefficient for the outcome probability, a biological mechanism or a causal treatment effect.
The distinction becomes essential when comparing hinge and logistic methods. Changing the loss can change the population parameter. Better estimation of one target need not mean better estimation of another. The paper explicitly warns that a hinge risk minimizer within the linear class need not equal the linear rule that minimizes classification error.
There is also a scale issue. Multiplying a score by a positive constant preserves its predicted label but changes its coefficients. The authors normalize certain comparisons using the first coefficient. Readers should therefore compare reported coefficient magnitudes only after checking the scale and target definition.
The hinge kink is at the margin rather than the decision boundary
A binary classifier changes label when its raw score crosses zero. The hinge loss changes slope when the signed margin reaches one. Those are different locations. Confusing them makes the statistical difficulty harder to understand.
Away from its kink, the hinge gradient is simple. Its ordinary second derivative vanishes wherever it exists. Yet population curvature can arise from how observations are distributed near the margin threshold. Ordinary automatic differentiation of a finite sample hinge loss does not recover that distributional curvature.
This is why simply asking a software library for a Hessian is insufficient. The matrix may be zero almost everywhere even though the statistical problem has meaningful local information. The paper represents the curvature through Dirac masses at the slope jumps and then approximates those masses with kernels.
Our earlier article on smoothed support vector machine inference examines a different paper and a different smoothing construction. The present contribution adds sparse high dimensional decorrelation and general weighted problems with nuisance estimation. It should have its own framing rather than repeat the earlier article’s general claim that smoothing helps inference.
Two kernels solve two different problems
For a convex piecewise linear loss, the derivative can be described as a baseline slope plus a series of jumps. The method replaces each step in that derivative with a smooth transition over a narrow neighborhood. It leaves the derivative unchanged outside those neighborhoods.
The local transition function is zero to the left of its interval and one to the right. The paper supplies a polynomial example within the interval. For hinge loss there is one slope jump, at a margin of one, from negative one to zero.
The second kernel estimates the curvature weights used to remove the effect of the remaining covariates. This global kernel has support over the entire real line and is positive everywhere mathematically. Its bandwidth need not equal the local smoothing bandwidth.
Why not differentiate the local smoother and use that for everything? Its derivative has compact support. Only observations very close to a kink would then contribute to the curvature fit. The paper argues that this can slow convergence and impose stronger conditions. The global kernel distributes the weighting more broadly.
Global support does not make every observation equally influential. Points far from the relevant margin can receive very small weights. In finite precision, some kernel evaluations can even underflow. A practical implementation must distinguish mathematical positivity from the numerical conditioning of its weighted regression.
The local kernel controls the bias introduced by smoothing a discontinuous gradient. The global kernel estimates the geometry used for decorrelation. Treating them as one interchangeable smoothing parameter misses the method’s design.
Decorrelation removes the main nuisance direction
Suppose the scientific question concerns one coefficient. All remaining coefficients are nuisance quantities for that question. Their estimates contain error, and high dimension makes that error too large to ignore in a naive score test.
The method regresses the target covariate on the remaining covariates using curvature weights and a sparsity penalty. The resulting residual is designed to reduce first order sensitivity of the score to errors in the nuisance coefficient vector.
The test score combines this residual with the label and smoothed margin derivative. Under the null, the target coordinate in the fitted coefficient vector is replaced by zero before evaluating the score. This construction differs from reporting the penalized coefficient divided by a naive standard error.
Decorrelation is about sensitivity to estimation error. It does not mean the covariates become causally unrelated, nor that a residualized variable becomes randomized. A coefficient test remains a statement about the statistical target defined by the surrogate objective.
The same broad need to match uncertainty calculations to an estimator appears in our discussion of inference for constrained stochastic optimization. The algorithms and assumptions differ, but both require more than an optimizer returning a plausible parameter vector.
Sample splitting changes which observations can influence a fit
Algorithm 1 divides the observations into folds. Each classifier is trained outside the fold where its margins and scores are evaluated. The authors use two folds in their simulations and real data analysis.
The decorrelation vector is estimated through a pooled objective formed from fold specific losses. This is a deliberate detail. Averaging separately estimated decorrelation vectors would generally produce a different result from minimizing the averaged loss, especially with an absolute value penalty.
Cross fitting recovers information from all folds while limiting direct dependence between an observation and the fitted classifier used to evaluate it. It is not equivalent to the familiar use of cross validation for selecting a tuning parameter. The paper uses cross validation for penalties as well, but the two operations have different jobs.
For interval estimation, a one step update corrects the average fitted coefficient using the full fitted score and an information estimate. The corresponding standard error includes both the score variance and the estimated information. A small information value can make the interval unstable even if prediction is good.
Weighted classification brings another layer of uncertainty
The general framework assigns covariate dependent weights to the two decisions. It can express problems with missing labels and problems where the goal is to select a treatment with favorable expected outcomes. The weights often depend on quantities that must themselves be estimated.
For missing labels, those quantities include the probability that a label is observed and the conditional class probabilities. The paper assumes labels are missing at random given the observed covariates, together with a positivity condition. Missingness driven by unrecorded information would require a different justification.
For treatment rules, the nuisance functions include treatment assignment probabilities and conditional outcomes. The causal interpretation assumes consistency, no interference in the stated potential outcome framework and no unmeasured confounding conditional on the covariates. Treatment probabilities must stay away from zero and one.
The framework uses augmented weighting with a double robustness property for the population objective when one of the relevant nuisance components is correctly specified. That statement should not be abbreviated to a promise that all inference remains valid whenever any convenient model works. The theorem still requires convergence rates, boundedness, smoothness and control of the remaining bias.
Algorithm 2 adds an outer split. Nuisance functions are estimated on one half and used to form weights on the other half, where the classification inference procedure is run. The roles are then reversed and the scores are aggregated. This nested data separation is an essential part of the weighted extension.
What the theory permits and what it requires
The paper allows the number of covariates to grow faster than sample size. That is meaningful because classical low dimensional asymptotics cannot simply be applied after a sparse variable selection step. However, dimension alone is not the condition that determines validity.
The analysis requires bounded covariates, regular conditional densities and control of how probability concentrates near the loss kinks. It also requires suitable sparsity and convergence of both the classifier estimate and the decorrelation estimate. The variance must remain well behaved.
For estimated weights, additional rate conditions enter. Their interaction with the global bandwidth is explicit. An error that appears small as a nuisance prediction error can matter more when divided by a shrinking bandwidth. Cross fitting addresses dependence, but it does not eliminate this rate accounting.
The normal approximation is asymptotic. It does not say that every dataset with more variables than observations will produce calibrated tests. For hypotheses whose dimension grows, the supplementary material develops a bootstrap procedure. Testing many coordinates individually is not the same procedure as applying that joint test.
A large covariate count is allowed within a structured regime. Sparsity, margin behavior, bandwidths and nuisance convergence determine whether that permission applies to a particular analysis.
Simulations test calibration rather than accuracy alone
The simulations consider ordinary classification and individualized treatment rules. Both begin with two latent population groups sampled with probabilities 0.4 and 0.6. A separation parameter changes how easily the groups can be distinguished.
The study varies covariate dimension from 500 to 1600 and sample size from 500 to 1600. Each setting is repeated 500 times. The reported evaluations include false positive behavior for null coordinates, power for signal coordinates, coverage of nominal confidence intervals and interval length.
A comparator first selects variables using a penalized hinge fit, then refits without the penalty and applies a low dimensional inference method. This resembles a tempting applied workflow, but variable selection changes the inferential problem. The simulations report inflated false positive behavior for that comparator and more favorable calibration for the proposed method.
The authors also compare a logistic loss inference method. Their interpretation must account for the different population targets. The simulation reference coefficients are approximated through larger sample fits averaged over repeated runs, with very small average coordinates set to zero. They are not an exact symbolic ground truth for every surrogate parameter.
| Approach | Purpose | What the paper reports | Interpretive limit |
|---|---|---|---|
| Kernel smoothed decorrelated score | Inference after sparse hinge fitting | Favorable error control and interval coverage in the tested settings | The asymptotic conditions still matter |
| Selection followed by unpenalized refitting | Apply classical inference after screening | Inflated false positive behavior in simulations | Selection cannot be ignored when calculating uncertainty |
| Logistic loss inference | Inference for another surrogate objective | Comparison of estimation and decision performance | Population coefficients need not match hinge coefficients |
| Weighted extension | Treatment rule inference with estimated nuisance functions | Simulations include estimated treatment and outcome components | Not proof of robustness to arbitrary confounding or nuisance error |
The diabetes analysis uses 9101 patients
The real data come from electronic medical records linked with Medicare claims for patients with type 2 diabetes and complex comorbidities. The paper describes data collected through the University of Wisconsin program. The analysis starts from 40 baseline covariates and their interactions, then selects 120 candidate predictors using a variance ranking.
The outcome is whether HbA1c is below 8 percent after one year. That is the study’s outcome definition, not a recommendation that every patient should have the same treatment target. The first analysis predicts this outcome under existing care. The second estimates a rule choosing between hypoglycemic agents and usual care.
The prediction model achieves cross validated accuracy of 0.895 with a reported standard deviation of 0.003. After false discovery rate control at 0.05, Table 1 identifies valvular disease and an interaction between hypertension and the recorded race category as significant coefficients of the rule.
These are associations within the fitted surrogate rule. They should not be converted into statements that a condition causes poor control or that a demographic category biologically determines treatment response. Interactions can reflect measurement, care patterns, coding and the joint covariate distribution as well as clinical processes.
| Reported quantity | Published value | What it measures |
|---|---|---|
| Patient count | 9101 | Linked records and claims sample |
| Screened predictors | 120 | Selected from covariates and interactions |
| Prediction accuracy | 0.895 with standard deviation 0.003 | Cross validated label prediction |
| Current practice outcome estimate | 0.860 with standard deviation 0.008 | Reported success rate comparison |
| Estimated treatment rule outcome | 0.871 with standard deviation 0.013 | Cross validated estimated rule value |
| Prediction interval average lengths | 0.122 proposed and 0.244 comparator | Coefficient intervals, not patient outcome intervals |
| Treatment rule interval average lengths | 0.122 proposed and 0.423 comparator | Coefficient intervals for the rule |
The estimated rule’s outcome value exceeds the current practice estimate in this analysis. The two reported standard deviations are not a confidence interval for their difference. They also do not establish that implementing the rule improves outcomes in a new population.
Clinical translation gap
The paper analyzes existing records. It does not report a prospective trial in which clinicians follow the estimated rule. Estimated policy value and realized benefit after deployment are different kinds of evidence. A rule can perform favorably in internal evaluation while failing when prescribing patterns or patient populations change.
Treatment assignment in observational records is influenced by clinical judgment. The no unmeasured confounding assumption is therefore consequential. A model cannot repair missing information about why a treatment was chosen merely by adding interactions among the variables that were recorded.
The clinical analysis uses fewer predictors than patients, even though the theory and simulations address more demanding dimension regimes. That application demonstrates one use of the procedure. It is not itself an empirical demonstration of inference with thousands more covariates than patients.
Future validation would need to examine transport across institutions, outcome measurement, missingness and whether relevant covariate groups receive adequate support under both decisions. These are evaluation needs inferred from the study design. They are not additional results reported by the authors.
Our article on causal inference across healthcare populations discusses a neighboring problem involving population differences. It estimates a different causal target. Sharing a concern about observational evidence does not make its guarantees interchangeable with inference for a decision rule coefficient.
Published details that need reconciliation
Algorithm 1’s final line prints a normal tail calculation with inverse square root sample size multiplying the score. Theorem 5, however, states the limiting normal approximation with square root sample size multiplying the empirical average score. The reference below follows the theorem. Copying the algorithm line literally would make a fixed nonzero average score look less significant as sample size grows.
The bandwidth sentence immediately before Algorithm 1 also prints a negative one fifth exponent for the ratio of log dimension to sample size. In the usual regime where that ratio shrinks, the displayed choice grows rather than shrinks. The theory discusses approximation by shrinking kernels. The companion therefore labels its positive one fifth exponent as an editorial choice and does not claim exact reproduction of the published tuning.
There is a separate reporting question in Table 2. The hypertension coefficient is reported as negative 0.0451 with a p value of 0.000832, while its reported 95 percent interval runs from negative 0.0918 to positive 0.0016. That interval contains zero. A score test and an interval from a different approximation need not agree exactly in a finite sample, so this alone does not prove a transcription error. It does require clarification before the row is used as a straightforward significance claim.
These observations come from checking the displayed PDF pages, not from an audit of the authors’ implementation. The publisher links an R package, which is the appropriate starting point for reproducing their computational choices. This article does not silently repair the published clinical table or invent replacement values.
Limitations of the clinical and statistical evidence
The total clinical sample is substantial, but the paper does not provide every subgroup count needed to assess the stability of each interaction in the reported tables. The overall patient count should not be treated as the effective sample size for every subgroup comparison.
Screening by variance can discard a low variance predictor that carries useful clinical information. The reported results are tied to the selected representation of the records. They do not constitute an exhaustive search over every plausible patient factor.
Population and dataset bias remain possible. Medicare linked records from one described program need not represent younger patients, other insurance systems or different care environments. The article does not supply an independent multicenter validation or a fairness analysis for the interaction involving race.
The mathematical scope is also limited. The results require convex piecewise linear surrogate losses and bounded designs in the main analysis. The authors identify extension to other design tails, nonconvex losses, distributed computation and online inference as future directions.
False discovery rate adjustment and a valid test address specified forms of statistical error. They do not establish clinical usefulness, causal mechanism or suitability for implementation. Any intended decision support use would require validation appropriate to that intended use and setting, beyond the evidence summarized here.
“identifying the driving factors of the estimated decision rule”Liang, Ning, Smith and Zhao, describing the inferential target in the paper’s abstract.
A better route from sparse fitting to uncertainty
The paper’s achievement is an inference framework for a setting where the obvious classical calculation breaks. Sparse penalization creates bias, the hinge kink obstructs ordinary curvature calculations, and estimated weights introduce further nuisance error. The method gives each difficulty a separate treatment.
The conceptual shift is to smooth what the inference procedure needs while retaining a clearly defined surrogate target. Local smoothing handles the score discontinuity. Global smoothing supplies curvature weights. Decorrelation and fold separation reduce the damage caused by estimating many other quantities.
The framework can serve ordinary classification, missing label problems and individualized treatment rule research. Each transfer carries its own assumptions. A procedure that is valid for observed binary labels cannot be reused unchanged when weights are estimated from observational treatment data.
The clinical example is useful as an application of the method, with measured outcome definitions and explicit uncertainty comparisons. It remains exploratory evidence about a learned rule. The displayed formula and table questions further reinforce the need for careful replication before clinical interpretation.
The next step is more than another accuracy score. Reproducible calibration studies, complete tuning details, resolution of the reporting ambiguities and external policy evaluation would make the bridge stronger. A classifier’s coefficients become scientifically useful when their target and uncertainty are both clear.
Complete PyTorch reference for ordinary hinge classification
The code implements the ordinary classification specialization of Algorithm 1. It includes a linear model, the exact hinge training objective, an alternating direction solver for the absolute value penalty, custom local smoothing, Gaussian curvature weights, penalized weighted projection, fold aggregation, a score test, a one step interval, evaluation and a runnable synthetic smoke test.
The solver checks primal and dual residuals for classifier fitting and an optimality residual for the weighted projection. It refuses to report a completed estimate when those stopping checks fail. Such checks address numerical optimization, not inferential calibration.
Fixed penalties and an explicitly shrinking global bandwidth are demonstration choices. The code does not implement the paper’s cross validated tuning, generalized weighted losses, Algorithm 2, treatment rules, multiple testing or the authors’ R package. It does not use patient records or claim that synthetic regression coefficients equal the population hinge parameter.
Python syntax and independent numerical checks passed. PyTorch was unavailable in the execution environment, so the included runtime smoke test remains unexecuted. No prediction result, p value calibration or interval coverage is claimed from this reference. The author repository is linked separately for reproduction work.
"""Editorial PyTorch reference: Algorithm 1, ordinary hinge classification.
Liang et al., JMLR 27(53), 2026. CPU float64. Requires PyTorch.
No clinical data, weighted treatment rule, Algorithm 2, or coverage claim.
Fixed demonstration tuning replaces the paper's cross-validation.
Uses sqrt(n) score normalization from Theorem 5, not the n^(-1/2)
printed in Algorithm 1's p-value line. Uses a shrinking global bandwidth;
the negative exponent printed before Algorithm 1 is not copied.
"""
import math
import torch
from torch import nn


def soft_threshold(x, threshold):
    return x.sign() * torch.relu(x.abs() - threshold)


class LinearRule(nn.Module):
    """No intercept, matching X^T beta. Add a constant explicitly if needed."""
    def __init__(self, dimension):
        super().__init__()
        self.beta = nn.Parameter(torch.zeros(dimension, dtype=torch.float64))

    def forward(self, x):
        return x @ self.beta


class HingeLoss(nn.Module):
    def forward(self, scores, labels):
        return torch.relu(1 - labels * scores).mean()


class LocalGradient(nn.Module):
    """Derivative -1 + H((margin - 1)/h) for hinge loss."""
    def __init__(self, bandwidth):
        super().__init__()
        if bandwidth <= 0:
            raise ValueError('bandwidth must be positive')
        self.bandwidth = bandwidth

    def forward(self, margin):
        u = (margin - 1) / self.bandwidth
        v = u.clamp(-1, 1)
        h = 0.5 + 15 / 16 * (v - 2 / 3 * v**3 + v**5 / 5)
        h = torch.where(u <= -1, torch.zeros_like(h), h)
        h = torch.where(u >= 1, torch.ones_like(h), h)
        return -1 + h


def gaussian_kernel(distance, bandwidth):
    return torch.exp(-0.5 * (distance / bandwidth)**2) / (
        bandwidth * math.sqrt(2 * math.pi))


@torch.no_grad()
def fit_hinge_admm(x, labels, penalty, max_iter=10000, tolerance=2e-5):
    """Solve mean hinge + penalty*||beta||_1 without smoothing the fit.

    Splits u = diag(labels) X beta and v = beta. Checks primal and dual
    residuals; refuses to return an unconverged fit as a finished result.
    """
    n, p = x.shape
    a = labels[:, None] * x
    rho = 1 / n
    factor = torch.linalg.cholesky(a.T @ a + torch.eye(p, dtype=x.dtype))
    beta = torch.zeros(p, dtype=x.dtype)
    u, v = torch.zeros(n, dtype=x.dtype), beta.clone()
    du, dv = torch.zeros_like(u), torch.zeros_like(v)
    for iteration in range(max_iter):
        rhs = a.T @ (u - du) + v - dv
        beta = torch.cholesky_solve(rhs[:, None], factor).squeeze(1)
        ab = a @ beta
        old_u, old_v = u.clone(), v.clone()
        z = ab + du
        threshold = 1 / (n * rho)
        u = torch.where(z < 1 - threshold, z + threshold,
                        torch.where(z > 1, z, torch.ones_like(z)))
        v = soft_threshold(beta + dv, penalty / rho)
        du += ab - u
        dv += beta - v
        primal = torch.sqrt((ab - u).square().sum() + (beta - v).square().sum())
        dual = rho * torch.linalg.vector_norm(a.T @ (u - old_u) + v - old_v)
        scale = 1 + torch.linalg.vector_norm(ab) + torch.linalg.vector_norm(beta)
        if primal <= tolerance * scale and dual <= tolerance * (1 + torch.linalg.vector_norm(rho * (a.T @ du + dv))):
            model = LinearRule(p)
            model.beta.copy_(v)
            return model, {'iterations': iteration + 1,
                           'primal': primal.item(), 'dual': dual.item()}
    raise RuntimeError('Hinge ADMM did not converge; increase budget or inspect scaling')


@torch.no_grad()
def fit_weighted_projection(z, response, weights, penalty,
                            max_iter=20000, tolerance=1e-7):
    """Proximal gradient for mean weights*(response-z w)^2 + mu*||w||1.

    No added ridge or silent weight floor. Stops using the proximal gradient
    mapping. Gaussian weights may underflow; reports an unusable design.
    """
    n, p = z.shape
    gram = 2 * (z.T @ (weights[:, None] * z)) / n
    linear = 2 * z.T @ (weights * response) / n
    lipschitz = torch.linalg.eigvalsh(gram).max().item()
    if not math.isfinite(lipschitz) or lipschitz <= 1e-14:
        raise RuntimeError('Insufficient weighted curvature')
    step = 1 / lipschitz
    w = torch.zeros(p, dtype=z.dtype)
    for iteration in range(max_iter):
        gradient = gram @ w - linear
        new_w = soft_threshold(w - step * gradient, step * penalty)
        mapping = torch.linalg.vector_norm((w - new_w) / step, ord=float('inf'))
        w = new_w
        if mapping <= tolerance:
            return w, {'iterations': iteration + 1, 'kkt': mapping.item()}
    raise RuntimeError('Weighted projection did not converge')


@torch.no_grad()
def evaluate(model, x, labels):
    scores = model(x)
    predictions = torch.where(scores >= 0, 1., -1.)
    return {'accuracy': (predictions == labels).double().mean().item(),
            'hinge': HingeLoss()(scores, labels).item()}


@torch.no_grad()
def infer_coordinate(x, labels, index, penalty=0.025, mu=0.015, seed=8):
    """Two equal folds, pooled projection objective, one coordinate target.

    Fixed lambda/mu are demonstration choices. Does not prove the estimator
    rates or any theorem condition for the supplied data.
    """
    x, labels = x.double(), labels.double()
    n, p = x.shape
    if n % 2 or n < 8 or p < 2 or not 0 <= index < p:
        raise ValueError('Require even n >= 8, p >= 2 and valid index')
    if not torch.isfinite(x).all() or not torch.all((labels == 1) | (labels == -1)):
        raise ValueError('Require finite covariates and labels in {-1,+1}')
    rng = torch.Generator().manual_seed(seed)
    folds = torch.randperm(n, generator=rng).chunk(2)
    keep = torch.arange(p) != index
    full_margin = torch.empty(n, dtype=x.dtype)
    null_margin = torch.empty_like(full_margin)
    beta_values, fits = [], []
    for k in range(2):
        test, train = folds[k], folds[1 - k]
        model, diagnostic = fit_hinge_admm(x[train], labels[train], penalty)
        beta_values.append(model.beta[index].item())
        full_margin[test] = labels[test] * model(x[test])
        beta_null = model.beta.clone()
        beta_null[index] = 0
        null_margin[test] = labels[test] * (x[test] @ beta_null)
        fits.append(diagnostic)
    # Shrinking plug-in rates, explicitly an editorial interpretation.
    h_local = 1 / math.sqrt(n * math.log(n))
    h_global = (math.log(p) / n)**0.2
    weights = gaussian_kernel(1 - full_margin, h_global)
    z, response = x[:, keep], x[:, index]
    w, projection = fit_weighted_projection(z, response, weights, mu)
    residual = response - z @ w
    gradient = LocalGradient(h_local)
    full_score = labels * gradient(full_margin) * residual
    null_score = labels * gradient(null_margin) * residual
    variance = full_score.square().mean().item()
    information = (weights * residual.square()).mean().item()
    if variance <= 1e-14 or information <= 1e-12:
        raise RuntimeError('Score variance or information is degenerate')
    sigma = math.sqrt(variance)
    score = null_score.mean().item()
    statistic = math.sqrt(n) * score / sigma
    p_value = math.erfc(abs(statistic) / math.sqrt(2))
    debiased = sum(beta_values) / 2 - full_score.mean().item() / information
    standard_error = sigma / (math.sqrt(n) * information)
    return {'coordinate': index, 'null_score': score, 'z': statistic,
            'p_value': p_value, 'one_step': debiased,
            'standard_error': standard_error,
            'interval_95': (debiased - 1.96 * standard_error,
                            debiased + 1.96 * standard_error),
            'h_local': h_local, 'h_global': h_global,
            'information': information, 'fits': fits, 'projection': projection,
            'scope': 'fixed tuning educational example, coverage unvalidated'}


def synthetic(n, p, generator):
    x = 2 * torch.rand(n, p, generator=generator, dtype=torch.float64) - 1
    latent = 1.2 * x[:, 0] - x[:, 1] + 0.7 * x[:, 2]
    noise = 0.5 * torch.randn(n, generator=generator, dtype=torch.float64)
    labels = torch.where(latent + noise >= 0, 1., -1.)
    return x, labels


def smoke_test():
    gradient = LocalGradient(0.1)
    values = gradient(torch.tensor([0., 1., 2.], dtype=torch.float64))
    assert torch.allclose(values, torch.tensor([-1., -.5, 0.], dtype=torch.float64))
    assert abs(math.erfc(1.96 / math.sqrt(2)) - 0.05) < 0.001
    rng = torch.Generator().manual_seed(42)
    x, labels = synthetic(96, 120, rng)
    test_x, test_labels = synthetic(128, 120, rng)
    model, diagnostic = fit_hinge_admm(x, labels, 0.025)
    print({'predictive_check': evaluate(model, test_x, test_labels),
           'solver': diagnostic})
    result = infer_coordinate(x, labels, index=5)
    assert 0 <= result['p_value'] <= 1
    assert result['interval_95'][0] <= result['interval_95'][1]
    print(result)
    print('No population coefficient or interval coverage is known from this run.')


if __name__ == '__main__':
    smoke_test()
Frequently asked questions
What does the decorrelated score test?
It tests a coefficient or specified sparse projection of the population surrogate risk minimizer. A nonzero coefficient is not automatically a causal effect, a biological mechanism or a treatment recommendation.
Why does the method use two kernels?
A local kernel smooths the discontinuous loss gradient near its kinks. A global kernel estimates curvature weights for the penalized projection used to reduce nuisance estimation bias.
Can the method handle more variables than observations?
The theory permits that regime under sparsity, bounded design, margin regularity and convergence conditions. A large variable count alone does not guarantee that the tests or intervals are calibrated.
What does cross fitting contribute?
It separates observations used to fit a classifier from those used to evaluate its score. The weighted extension adds an outer split for estimating nuisance functions before classification inference.
Does the diabetes study prove a better treatment policy?
No. It reports cross validated estimated outcomes using observational records from 9101 patients. It does not establish prospective benefit from deploying the rule or remove the need for causal assumptions and external validation.
Does the PyTorch code reproduce the clinical analysis?
No. It implements an educational ordinary hinge classification specialization with fixed tuning and disclosed formula choices. It does not implement treatment rule inference or reproduce the authors’ R package. PyTorch runtime testing remains unavailable.
Read the paper and inspect the reference
Use the published paper for assumptions and proofs, and the authors’ R package for their implementation. The editorial PyTorch reference remains a separate educational specialization.
Muxuan Liang, Yang Ning, Maureen A Smith and Ying Qi Zhao. Inference with nondifferentiable surrogate loss in a general high dimensional classification framework. Journal of Machine Learning Research, volume 27, article 53, pages 1 to 76, 2026. Formal title punctuation normalized for the article’s prose style.
This analysis is based on the published paper and an independent evaluation of its claims.