You are fitting a tensor decomposition. Every factor update solves a manageable problem, the reconstruction error keeps falling, and the run eventually seems to settle. Then another initialization takes much longer. Adding a small quadratic penalty helps, until you impose orthogonal columns and the advantage nearly disappears. What changed? The answer involves the geometry of the feasible factors, not just a different setting in the optimizer.
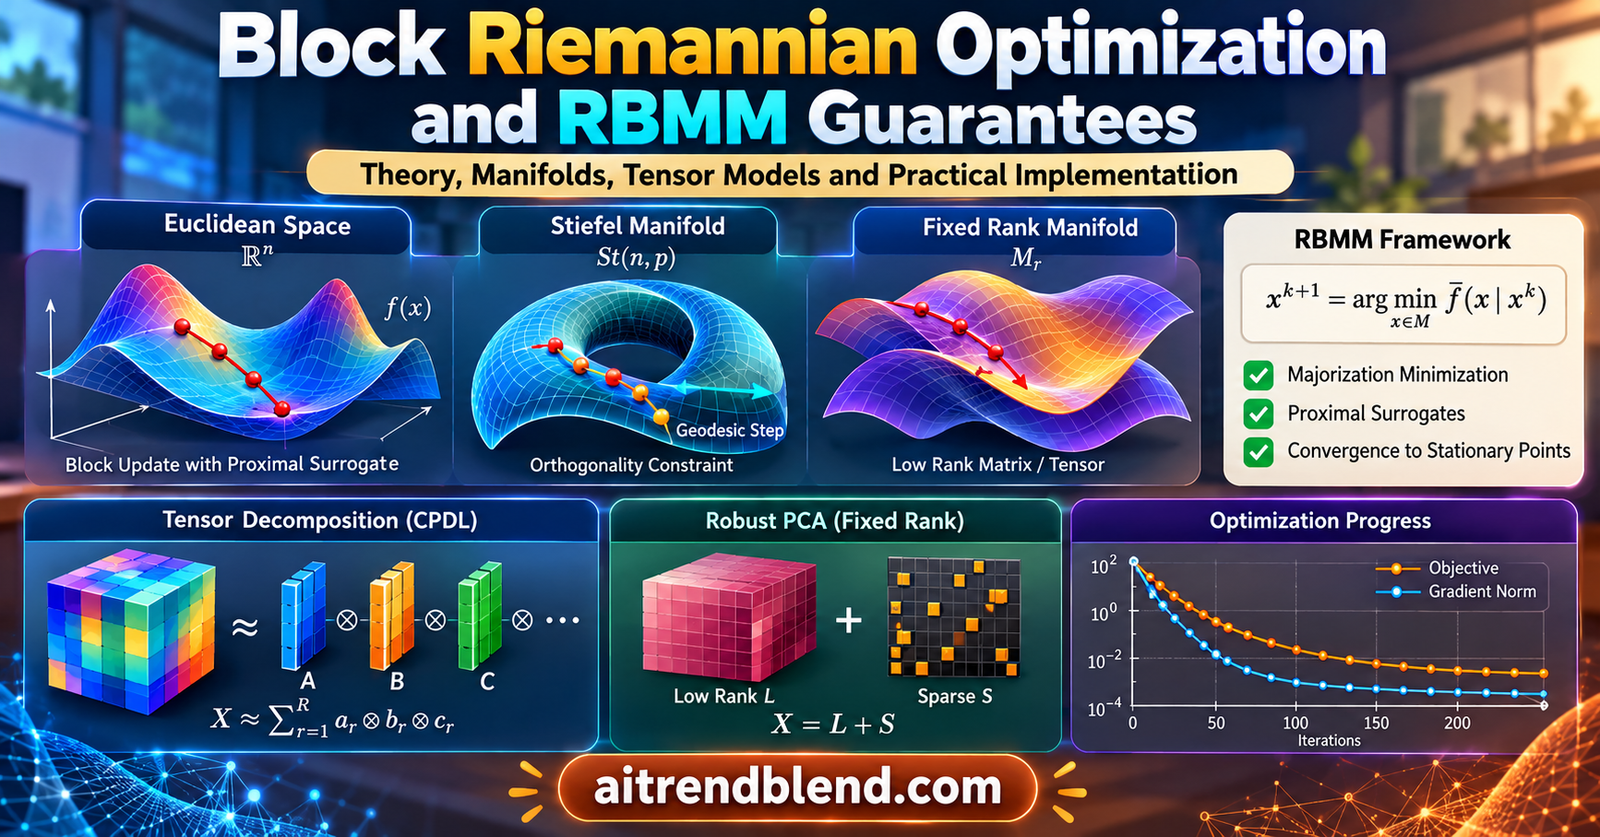
- Block Riemannian majorization minimization updates one parameter block at a time through a surrogate that touches and upper bounds the current objective.
- The paper separates asymptotic stationarity from a bound on the number of iterations needed to reach approximate stationarity.
- Under the applicable assumptions, the complexity is \(\widetilde O(\epsilon^{-2})\), with logarithmic factors hidden.
- Euclidean and Stiefel factors admit especially practical conditions. Fixed rank constraints support a narrower convergence claim in the tensor application.
- The synthetic experiments show advantages for proximal updates in some settings and little separation in the Stiefel example.
- A diminishing proximal schedule can work experimentally while falling outside the positive lower bound required by the tensor corollary.
The promise behind a familiar alternating loop
Many learning problems contain parameters that naturally belong in different blocks. A tensor model has one factor matrix for each mode. A robust matrix decomposition separates a low rank component from sparse corruption. A subspace estimator represents a basis whose columns must remain orthogonal. Updating everything together can make the constraints awkward, while updating one block at a time preserves a problem structure that we know how to solve.
The danger is assuming that a convenient loop inherits a convenient theorem. A decreasing objective is useful evidence, but it does not establish that the parameters approach a stationary point. Nor does a stationary point necessarily give the best fit. For several blocks, even exact coordinate optimization can behave badly without further conditions. The paper recalls the counterexample of Powell from 1973 as a reason to take the extra assumptions seriously.
Yuchen Li and Hanbaek Lyu of the University of Wisconsin Madison, Laura Balzano of the University of Michigan, and Deanna Needell of the University of California Los Angeles address this gap in their JMLR paper on convergence and complexity of block Riemannian optimization. Their contribution is a framework for analyzing a family of algorithms. It is not another neural architecture, a benchmark leaderboard, or a claim that every alternating procedure is safe.
The most useful reading is therefore an audit. Which objective is being minimized? Which geometry describes each factor? How accurately are the block subproblems solved? Which theorem still applies after a practical modification? Those questions place this analysis in Optimization & Learning Theory, where the assumptions behind an algorithm are part of its behavior rather than decorative details.
What a block surrogate actually guarantees
Write the parameters as a tuple of blocks. Each block belongs to a feasible subset of a Riemannian manifold. The objective has a smooth part and a separable penalty. The penalty can be nonsmooth, but each block penalty must satisfy the stated geodesic convexity assumptions. Separability matters because it keeps a block update from unexpectedly changing a penalty attached to another block.
During a sweep, earlier blocks already contain their new values. Later blocks still contain their previous values. The marginal objective for the current block is constructed with this mixed tuple. This is a sequential algorithm. Building every block update from the same old tuple and applying all updates together produces a different procedure whose convergence is not automatically covered by Algorithm 1.
A majorizing surrogate lies above the smooth marginal objective everywhere in its domain and agrees with it at the current point. The update minimizes this surrogate plus the current block penalty over the feasible set. Exact minimization gives a simple chain of inequalities. The new objective is bounded by the new surrogate, which cannot exceed the old surrogate, which equals the old objective.
The touching condition also aligns the gradients at the base point under the differentiability conditions. This connection is what makes the surrogate relevant to stationarity of the original problem. A convenient auxiliary loss that merely correlates with reconstruction error would not provide the same argument. The surrogate must satisfy the required relationship, not just look numerically useful.
A proximal surrogate adds a nonnegative squared distance from the previous block. It still touches the objective because that distance is zero at the old point. Away from that point, it discourages large moves. This penalty is about movement between iterates. It is distinct from a permanent sparsity or weight decay penalty in the original model objective.
Log the original objective separately from the surrogate value. Rebuild a marginal objective after each block update. A falling auxiliary loss and a parallel update schedule do not substitute for the algorithm analyzed in the paper.
The distance choice is an algorithm choice
On a Euclidean space, a straight line gives the ordinary distance between two points. On a sphere, the intrinsic distance follows a great circle. The straight chord through the surrounding space is shorter and describes a different penalty. Both can be meaningful, but treating them as interchangeable erases the geometric part of the problem.
The paper analyzes smooth surrogates, proximal surrogates based on Riemannian distance, and proximal surrogates based on ambient Euclidean distance. The latter can be easier to differentiate and implement for an embedded manifold. Its general route requires compact feasible sets alongside the other assumptions. The intrinsic route can cover settings where an ambient compactness requirement would be unsuitable.
Geodesic smoothness also differs from blindly comparing gradients in an array. Gradients based at two manifold points belong to different tangent spaces. The analysis compares them using parallel transport. This controls how much the local approximation can change as the parameters move along the manifold. A numerical library that exposes an ordinary gradient does not by itself establish this property.
Stiefel manifolds are a helpful special case. They contain matrices with orthonormal columns. The paper establishes a route from Euclidean smoothness to geodesic smoothness on these manifolds. Consequently, practical algorithms can use familiar matrix derivatives and ambient quadratic penalties while the proof uses manifold geometry. Additional feasible subsets still need the stated geodesic convexity condition. Without additional constraints, the full manifold is the feasible domain and that extra subset condition becomes vacuous.
This distinction matters when adapting code. Adding orthogonality and adding a fixed rank constraint are both changes to the feasible factors, but their theoretical consequences differ. The constraint name alone is insufficient. You must specify the underlying manifold, the feasible subset, the distance in the surrogate, and the smoothness properties of the objective in that setting.
Stationarity and complexity answer different questions
Theorem 5 establishes that every limit point is stationary under its assumptions, including the required control of surrogate gaps. It does not require geodesic convexity of the feasible subsets. This is valuable for embedded constraints that are nonconvex in the surrounding Euclidean space. It should not be rewritten as a guarantee that every run reaches a unique solution or the global minimum.
Theorems 7 and 10 add a quantitative result under stronger conditions, including geodesic convexity of the constraint sets. Their complexity counts outer iterations needed to encounter an approximately stationary point. The displayed rate concerns the best stationarity measure among the iterates considered. It is not a promise that the final iterate achieves that rate or that every successive iterate improves its gradient measure.
Here the constant depends on the theorem assumptions and problem quantities, and the tilde hides logarithmic factors. It is not a universal runtime prediction. Tightening the stationarity tolerance can increase the worst case iteration budget sharply, even before the cost of solving the block subproblems is considered. A single outer sweep may involve an expensive decomposition or an iterative manifold solve.
For a smooth problem with the entire manifold available as the feasible domain, the stationarity measure reduces to the sum of the norms of the block Riemannian gradients. With extra constraints or a nonsmooth penalty, the paper uses a directional measure that also accounts for feasible tangent directions and penalty changes along the exponential map. An ordinary ambient gradient norm can be misleading at a constrained stationary point.
| Setting | Source result | What to retain |
|---|---|---|
| Many blocks with suitable distance regularization | Theorem 5 | Stationary limit points under the stated assumptions without requiring geodesic convexity of feasible subsets |
| Applicable proximal surrogates and geodesically convex constraints | Theorem 7 | Approximate stationarity within a complexity bound that hides logarithmic factors |
| Smooth surrogates with quadratic gap growth | Theorem 10 | A comparable complexity guarantee when the additional conditions hold |
| Euclidean or Stiefel factors | Corollaries 11 and 22 | Practical smoothness conditions and tensor complexity under the specified proximal assumptions |
| Fixed rank factors in the tensor example | Section 5.4 and Theorem 5 | Asymptotic stationarity through the ambient formulation without the same complexity claim |
The neighboring analysis of escaping saddle points in bilevel optimization addresses a different target. A first order stationary point can still be a saddle. The present framework does not automatically inherit a saddle escape guarantee. Likewise, statistical inference for constrained optimization asks questions about uncertainty that an iteration complexity result does not answer.
“converges to the set of stationary points”Li, Balzano, Needell and Lyu, Corollary 22. The set qualification matters.
Inexact block solves need a budget
Exact surrogate minimization is often unrealistic. The paper allows inexact updates, but the error is measured as the objective gap between the returned block and the true infimum of its surrogate subproblem. It requires the sequence of these gaps to be summable. It also requires the returned blocks to approach exact minimizing blocks in distance. Under suitable strong convexity, the gap condition can imply the distance condition.
A fixed nonzero gap tolerance does not meet that infinite sum requirement. A schedule that decays sufficiently fast can have a finite error budget, but choosing a schedule is not the same as proving that the actual subproblem error follows it. An inner gradient threshold is also not automatically a surrogate objective gap certificate when the subproblem is nonconvex.
The practical implication is to record what an inner solver really certifies. Does it return a global surrogate minimizer, a local stationary point, or a capped iterative approximation? If the answer changes between blocks, that change belongs in the method description. Otherwise, a supposedly faithful implementation can silently replace the central assumption with an unrelated stopping rule.
The broader lesson resembles the distinction explored in biased gradients and generalization. An optimization shortcut needs its own error model. Its numerical convenience does not establish that the theorem tolerates its bias or approximation. Here the relevant object is the surrogate gap, not a generic impression that the inner solve is accurate enough.
Tensor decomposition makes the tradeoff visible
The tensor application uses CANDECOMP/PARAFAC dictionary learning. A rank parameter specifies how many components contribute to the reconstruction. Each component is an outer product of one column from each factor matrix. The loss is the squared Frobenius reconstruction error. Kolda and Bader from 2009, cited by the source paper, provide the background for this representation and the alternating least squares baseline.
Holding the other factors fixed turns one block into a matrix least squares problem. Ordinary ALS solves that problem directly. RBMM adds a squared displacement penalty. In equation 42 the coefficient is written without a factor of one half, so the implementation must follow that normalization rather than copying the earlier generic expression blindly.
The displayed closed form applies to a Euclidean factor. Numerically, solve the linear system instead of constructing an explicit inverse. A positive proximal coefficient makes the block matrix positive definite even when the design Gram matrix is singular. This improves the algebra of the update, but it does not turn the joint tensor problem into a convex problem.
For a Stiefel factor, the quadratic traces are constant because the columns are orthonormal. The update becomes an orthogonal Procrustes problem involving the data cross term and the previous factor. A polar factor from an SVD solves this subproblem. This explains why the same proximal term can have a different practical effect once orthogonality has already removed degrees of freedom.
What Figure 6 reports
The authors generate synthetic tensors of shape 30 by 20 by 10. For the Euclidean and Stiefel examples, the factor matrices have three columns. They compare ALS with a constant proximal coefficient of 0.1 and a diminishing schedule of \(0.1\times0.5^n\). Each algorithm is run from 100 independent random initializations, with average relative error and variation shown in the figure.
| Figure panel | Reported comparison | Interpretation boundary |
|---|---|---|
| A with Euclidean factors | RBMM reaches error around \(10^{-14}\) while ALS remains around \(10^{-3}\) | A synthetic example where proximal updates help considerably |
| B with Euclidean factors | At 0.25 seconds the diminishing schedule reaches around \(10^{-14}\) while the others remain around \(10^{-2}\) | Reported elapsed time for that experiment rather than a transferable speed guarantee |
| C with a Stiefel first factor | All three methods perform well with little separation | Orthogonality changes the effect of the added quadratic term |
| D with first factor rank five and ten component columns | Constant RBMM takes 5.16 seconds and diminishing RBMM 5.51 seconds versus ALS at 9.66 seconds to reach around \(10^{-13}\) | Empirical benefit under fixed rank constraints without the same complexity theorem |
These are reconstruction experiments. They do not report classification accuracy, forecasting quality, or recovery of interpretable latent factors on a deployed dataset. An error near machine precision is plausible for a suitably generated synthetic tensor, but it does not establish a comparable advantage for noisy or misspecified data. The figure is evidence about these fits, not a universal ranking of alternating algorithms.
The diminishing schedule deserves a separate warning about interpretation. Corollary 22 assumes the proximal coefficients have a strictly positive lower bound. The sequence used in the diminishing experiment tends to zero, so it does not satisfy that requirement. Its favorable performance is an empirical observation. It cannot be cited as a direct demonstration of the corollary under that schedule.
Keep the constant schedule when testing the stated tensor corollary. Treat a vanishing schedule as a separate experimental variant. Report objective, stationarity, constraint residuals, elapsed time and initialization variability separately so one attractive curve does not stand in for every claim.
Robust PCA exposes the nonsmooth side
The second reference example decomposes a matrix into a component constrained to rank exactly \(r\) and a sparse component. The loss combines a squared residual with an entrywise absolute value penalty. This is the fixed rank formulation in equation 46, attributed in the paper to Rodriguez and Wohlberg from 2013. It is not the nuclear norm relaxation also discussed in the background.
Adding the proximal terms in equation 48 yields two manageable updates. The low rank block uses a truncated SVD of a weighted combination of the current residual target and the old low rank matrix. The sparse block uses soft thresholding of a similar weighted combination. The included implementation calls the movement coefficient rho to avoid confusing it with the sparsity penalty lambda.
A subtle issue appears at the rank boundary. Matrices of rank exactly \(r\) do not form a closed set. Truncation can return a matrix with lower rank if the retained singular values vanish. The code checks the retained singular value and raises an error for numerical rank deficiency. Quietly accepting that output would switch the feasible set to rank at most \(r\), which is a different model.
Corollary 23 states asymptotic convergence to the set of stationary points for its proximal procedure. The article does not assign this example the Euclidean and Stiefel tensor complexity guarantee. Nor does stationary convergence establish recovery of the true clean matrix and corruption. Recovery needs assumptions about the data generating components beyond the algorithm settling down.
Limits that matter before reuse
The general theory assumes smoothness, a lower bounded objective, compact sublevel sets, controlled geometry and suitable surrogate properties. These conditions require checking for the actual problem. Tensor factors can have scaling ambiguities, so a small reconstruction loss alone does not certify bounded factors or compact sublevel sets. The application corollary is useful guidance, but an adaptation with extra penalties or constraints still deserves its own assumption audit.
The quantitative guarantee counts outer iterations rather than total arithmetic operations. Different surrogates can exchange fewer outer steps for more expensive inner solves. Timing comparisons should include the decompositions, memory requirements, stopping criterion and numerical precision. The reported tensor timings cannot settle those tradeoffs for a much larger problem.
Several outcomes remain outside the claim. The framework does not guarantee global optimality, latent factor identification, superiority on every dataset, or statistical generalization. Related work on pruning and generalization theory illustrates how model performance requires a different layer of analysis. Convergence of the training procedure is one piece of evidence about a learning system.
The experiments are valuable because they show both improvement and a setting where the improvement largely disappears. They are still small synthetic illustrations. The paper does not provide a comprehensive deployment benchmark for every application listed in its framework. A new application should compare against a strong specialized solver rather than assuming the shared theorem settles the empirical question.
A better way to read an alternating algorithm
The achievement is a shared analysis of constrained block updates across several geometries. Instead of proving each alternating routine from scratch, researchers can identify its marginal objectives, surrogates and feasible sets, then determine which result applies. That can turn a familiar numerical pattern into a method with explicit convergence conditions.
The conceptual shift is to treat movement control as part of the proof. A touching upper bound explains why an exact block step descends. A sufficiently regular surrogate gap helps control the path of the iterates. Geometry determines how this movement relates to gradients and feasible directions. Those are separate links in the argument, and omitting one can change the conclusion.
The framework transfers naturally to problems with orthogonal bases, structured factorizations and sparse components. Transfer is most credible when the block subproblems remain easy to solve and the geometry is clearly specified. The Euclidean and Stiefel cases offer an accessible starting point because their useful updates can be implemented through ordinary matrix operations.
The remaining limits are substantial. A stationary point may still be undesirable, an inexact inner solve may miss the required gap budget, and a fixed rank constraint may preserve asymptotic convergence without preserving the iteration bound. The synthetic tensor results also show that a theoretically motivated proximal term need not create a large practical advantage in every geometry.
A useful next experiment would pair each schedule with measured stationarity and constraint residuals across larger noisy problems, while recording the cost of every inner solve. That would make the empirical comparison better aligned with the theorem without pretending that runtime and asymptotic complexity are identical. For practitioners, the immediate action is simpler. Keep the algorithm, the assumptions and the claimed outcome on the same page.
Complete PyTorch reference for two applications
The code below implements the full three mode tensor model, its Euclidean and first factor Stiefel proximal updates, and the fixed rank robust PCA objective and updates. It includes custom reconstruction, model classes, loss functions, fitting loops, evaluation and a runnable synthetic smoke test. It is an editorial reference rather than the authors’ implementation. It does not implement every manifold application in the paper.
The tensor routine uses a constant positive coefficient and exact block formulas. Its gradient diagnostic uses the induced Frobenius metric for the Stiefel factor. The robust PCA routine reports objective, residual, rank and sparse support after a fixed budget. Those diagnostics are not a nonsmooth stationarity certificate. The synthetic smoke test checks numerical descent and feasibility rather than reproducing Figure 6 or proving recovery.
Python syntax and independent NumPy checks of the block formulas passed. PyTorch is unavailable in the current execution environment, so the included PyTorch smoke test has not been run here. Install PyTorch and run the downloaded file to execute it. No benchmark score or runtime result is claimed for this reference.
"""Editorial RBMM reference for two applications in Li et al., JMLR 2026.

Requires Python 3.10+ and PyTorch. Uses CPU float64 and exact block solves.
Implements CPDL equations (39), (42) and fixed-rank RPCA (46), (48).
Not the authors' code, not a universal manifold solver or benchmark reproduction.
Run: python rbmm_reference.py
"""
import math
import torch
from torch import nn

DTYPE = torch.float64


def polar(matrix):
    """Thin polar factor, an exact orthogonal Procrustes minimizer."""
    left, _, right = torch.linalg.svd(matrix, full_matrices=False)
    return left @ right


class CPReconstruction(nn.Module):
    """Custom reconstruction layer for a three-mode rank-R CP dictionary."""
    def forward(self, factors):
        a, b, c = factors
        return torch.einsum("ir,jr,kr->ijk", a, b, c)


class CPDictionary(nn.Module):
    def __init__(self, shape, rank, stiefel_first=False, seed=0):
        super().__init__()
        if len(shape) != 3 or rank < 1 or min(shape) < 1:
            raise ValueError("Use a positive three-mode shape and rank.")
        if stiefel_first and shape[0] < rank:
            raise ValueError("Stiefel factor needs rows >= columns.")
        generator = torch.Generator().manual_seed(seed)
        self.factors = nn.ParameterList([
            nn.Parameter(torch.randn(size, rank, generator=generator,
                                     dtype=DTYPE), requires_grad=False)
            for size in shape
        ])
        self.stiefel_first = stiefel_first
        self.reconstruction = CPReconstruction()
        if stiefel_first:
            with torch.no_grad():
                self.factors[0].copy_(polar(self.factors[0]))

    def forward(self):
        return self.reconstruction(self.factors)

    def loss(self, x):
        # Equation (39), with no factor 1/2.
        return torch.sum((x - self()) ** 2)

    def block_system(self, x, block):
        others = [self.factors[j] for j in range(3) if j != block]
        # Ordering agrees with movedim(...).reshape(...).
        design = torch.einsum("ir,jr->ijr", *others).reshape(
            -1, self.factors[block].shape[1])
        unfolding = x.movedim(block, 0).reshape(x.shape[block], -1)
        return design.T @ design, unfolding @ design

    @torch.no_grad()
    def sweep(self, x, proximal):
        if not math.isfinite(proximal) or proximal <= 0:
            raise ValueError("This reference uses a constant positive proximal.")
        for block, factor in enumerate(self.factors):
            gram, cross = self.block_system(x, block)
            old = factor.clone()
            rhs = cross + proximal * old
            if self.stiefel_first and block == 0:
                # On U.T U = I, both quadratic traces are constant.
                updated = polar(rhs)
            else:
                identity = torch.eye(gram.shape[0], dtype=x.dtype,
                                     device=x.device)
                updated = torch.linalg.solve(
                    gram + proximal * identity, rhs.T).T
            # Earlier factors are updated before later block systems are built.
            factor.copy_(updated)


@torch.no_grad()
def evaluate_cp(model, x):
    norms = []
    for block, factor in enumerate(model.factors):
        gram, cross = model.block_system(x, block)
        gradient = 2 * (factor @ gram - cross)
        if model.stiefel_first and block == 0:
            product = factor.T @ gradient
            symmetric = (product + product.T) / 2
            gradient = gradient - factor @ symmetric
        norms.append(torch.linalg.vector_norm(gradient))
    orthogonality = 0.0
    if model.stiefel_first:
        u = model.factors[0]
        identity = torch.eye(u.shape[1], dtype=x.dtype, device=x.device)
        orthogonality = float(torch.linalg.vector_norm(u.T @ u - identity))
    return {
        "objective": float(model.loss(x)),
        "relative_error": float(torch.linalg.vector_norm(x - model()) /
                                torch.linalg.vector_norm(x).clamp_min(1e-30)),
        "sum_gradient_norms": float(torch.stack(norms).sum()),
        "orthogonality_residual": orthogonality,
    }


def fit_cp(model, x, sweeps=100, proximal=0.1, tolerance=1e-6):
    """Stop by a gradient diagnostic, not merely by loss stagnation."""
    x = x.to(dtype=DTYPE, device="cpu")
    history = [evaluate_cp(model, x)]
    for _ in range(sweeps):
        model.sweep(x, proximal)
        metrics = evaluate_cp(model, x)
        previous = history[-1]["objective"]
        if metrics["objective"] > previous + 1e-10 * max(1.0, previous):
            raise RuntimeError("Exact proximal sweep increased objective.")
        history.append(metrics)
        if metrics["sum_gradient_norms"] <= tolerance:
            break
    return history


def soft_threshold(x, threshold):
    return torch.sign(x) * torch.clamp(torch.abs(x) - threshold, min=0)


def rank_projection(x, rank, threshold=1e-12):
    """Nearest rank-r matrix when the retained r-th singular value is positive.

    Rank exactly r is not a closed set. Fail rather than silently returning
    a rank-deficient point outside the fixed-rank manifold.
    """
    left, values, right = torch.linalg.svd(x, full_matrices=False)
    if not 1 <= rank <= len(values):
        raise ValueError("Invalid fixed rank.")
    if float(values[rank - 1]) <= threshold * max(1.0, float(values[0])):
        raise RuntimeError("Rank-r projection is numerically rank deficient.")
    return (left[:, :rank] * values[:rank]) @ right[:rank, :]


class FixedRankRPCA(nn.Module):
    def __init__(self, matrix, rank, sparsity_weight=0.1, noise_scale=1.0):
        super().__init__()
        if sparsity_weight <= 0 or noise_scale <= 0:
            raise ValueError("Use positive model weights.")
        self.rank = rank
        self.sparsity_weight = sparsity_weight  # lambda in equation (46)
        self.noise_scale = noise_scale          # mu in equation (46)
        self.register_buffer("matrix", matrix.to(dtype=DTYPE, device="cpu"))
        self.register_buffer("low", rank_projection(self.matrix, rank))
        self.register_buffer("sparse", torch.zeros_like(self.matrix))

    def forward(self):
        return self.low + self.sparse

    def loss(self):
        residual = self.matrix - self()
        return (self.sparsity_weight * self.sparse.abs().sum() +
                residual.square().sum() / (2 * self.noise_scale))

    @torch.no_grad()
    def sweep(self, proximal=0.1):
        # proximal = rho here, lambda_k in equation (48), distinct from
        # the sparsity penalty lambda in equation (46).
        if not math.isfinite(proximal) or proximal <= 0:
            raise ValueError("Use a positive proximal parameter.")
        denominator = 1 + self.noise_scale * proximal
        target = (self.matrix - self.sparse +
                  self.noise_scale * proximal * self.low) / denominator
        self.low.copy_(rank_projection(target, self.rank))
        center = (self.matrix - self.low +
                  self.noise_scale * proximal * self.sparse) / denominator
        threshold = self.noise_scale * self.sparsity_weight / denominator
        self.sparse.copy_(soft_threshold(center, threshold))


@torch.no_grad()
def evaluate_rpca(model):
    return {
        "objective": float(model.loss()),
        "relative_error": float(torch.linalg.vector_norm(model.matrix - model()) /
                                torch.linalg.vector_norm(model.matrix).clamp_min(1e-30)),
        "rank": int(torch.linalg.matrix_rank(model.low)),
        "nonzero_sparse_entries": int(torch.count_nonzero(model.sparse)),
    }


def fit_rpca(model, sweeps=100, proximal=0.1):
    # Fixed budget. No nonsmooth stationarity certificate is inferred.
    history = [evaluate_rpca(model)]
    for _ in range(sweeps):
        model.sweep(proximal)
        metrics = evaluate_rpca(model)
        previous = history[-1]["objective"]
        if metrics["objective"] > previous + 1e-10 * max(1.0, previous):
            raise RuntimeError("RPCA exact proximal sweep increased objective.")
        history.append(metrics)
    return history


def smoke_test():
    torch.manual_seed(7)
    for constrained in (False, True):
        truth = CPDictionary((12, 10, 8), 3, constrained, seed=1)
        x = truth().detach()
        model = CPDictionary(x.shape, 3, constrained, seed=2)
        history = fit_cp(model, x, sweeps=40)
        assert history[-1]["objective"] <= history[0]["objective"] + 1e-9
        assert all(math.isfinite(v) for v in history[-1].values())
        if constrained:
            assert history[-1]["orthogonality_residual"] < 1e-10
        print("CPDL Stiefel=" + str(constrained), history[-1])
    low = torch.randn(14, 2, dtype=DTYPE) @ torch.randn(2, 11, dtype=DTYPE)
    sparse = torch.zeros_like(low)
    sparse[::4, ::3] = 3.0
    model = FixedRankRPCA(low + sparse, rank=2)
    history = fit_rpca(model, sweeps=40)
    assert history[-1]["rank"] == 2
    assert history[-1]["objective"] <= history[0]["objective"] + 1e-9
    assert all(math.isfinite(v) for v in history[-1].values())
    print("Fixed-rank RPCA", history[-1])


if __name__ == "__main__":
    smoke_test()
Frequently asked questions
What is block Riemannian majorization minimization?
It updates parameter blocks sequentially by minimizing touching upper bounds over feasible subsets of manifolds. Earlier block updates are used immediately when constructing later marginal objectives.
Does RBMM guarantee the global optimum?
No. The paper establishes stationary limit points and, under stronger assumptions, an iteration bound for approximate stationarity. Neither result guarantees a global minimum or a unique solution.
What does the approximate stationarity bound count?
It counts outer iterations needed to encounter an approximately stationary iterate. The complexity hides logarithmic factors and does not include a universal bound on the cost of each block solve.
Why do Stiefel constraints change the proximal update?
Orthonormal columns make the quadratic traces constant in the block objective. The constrained update becomes an orthogonal Procrustes problem, and the synthetic example shows little separation between the compared methods.
Does the diminishing tensor schedule satisfy Corollary 22?
No. The experimental schedule tends to zero, while that corollary requires a strictly positive lower bound on the proximal coefficients. Its reported advantage is empirical evidence outside that schedule requirement.
Has the included PyTorch code been executed?
No. Python syntax and independent NumPy checks of the update formulas passed, but PyTorch was unavailable. The code includes a runnable synthetic smoke test and does not claim to reproduce the authors’ benchmark results.
Read the research and inspect the reference
The publisher page links the complete paper and bibliographic record. The second download contains the editorial implementation shown above. An authors’ code repository was not supplied on the publisher page.
Read the JMLR paperDownload reference codeYuchen Li, Laura Balzano, Deanna Needell and Hanbaek Lyu. Convergence and complexity of block majorization minimization for constrained block Riemannian optimization. Journal of Machine Learning Research, volume 27, article 42, pages 1 to 77, 2026. Equations 11 to 18, Theorems 5, 7 and 10, Corollaries 11, 22 and 23, and Sections 5.4 and 5.5 support the analysis above.
This analysis is based on the published paper and an independent evaluation of its claims.