Optimization & Learning Theory

The mathematics under the hood: optimization methods, convergence guarantees, and the theory that explains when and why deep learning works. Explainers that take proofs seriously without losing the reader.

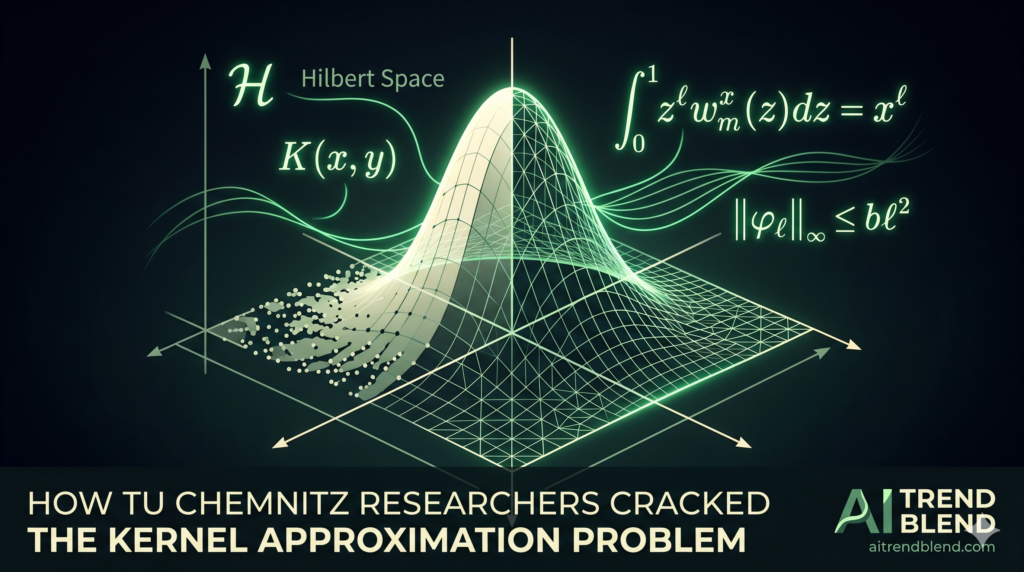
How Dommel and Pichler Finally Cracked the Kernel Approximation Problem That Was Holding Machine Learning Back.

How Dommel and Pichler Finally Cracked the Kernel Approximation Problem That Was Holding Machine Learning Back

Paul Dommel and Alois Pichler from TU Chemnitz developed a Taylor series based approach to approximate kernel functions in reproducing kernel Hilbert spaces. Their work produces the first non-exponential eigenfunction bounds ever recorded and opens the door to regularization parameters…
How Dommel and Pichler Finally Cracked the Kernel Approximation Problem That Was Holding Machine Learning Back Read More »

Sliced-Wasserstein Distances and Flows on Cartan-Hadamard Manifolds.

Sliced-Wasserstein Distances and Flows on Cartan-Hadamard Manifolds

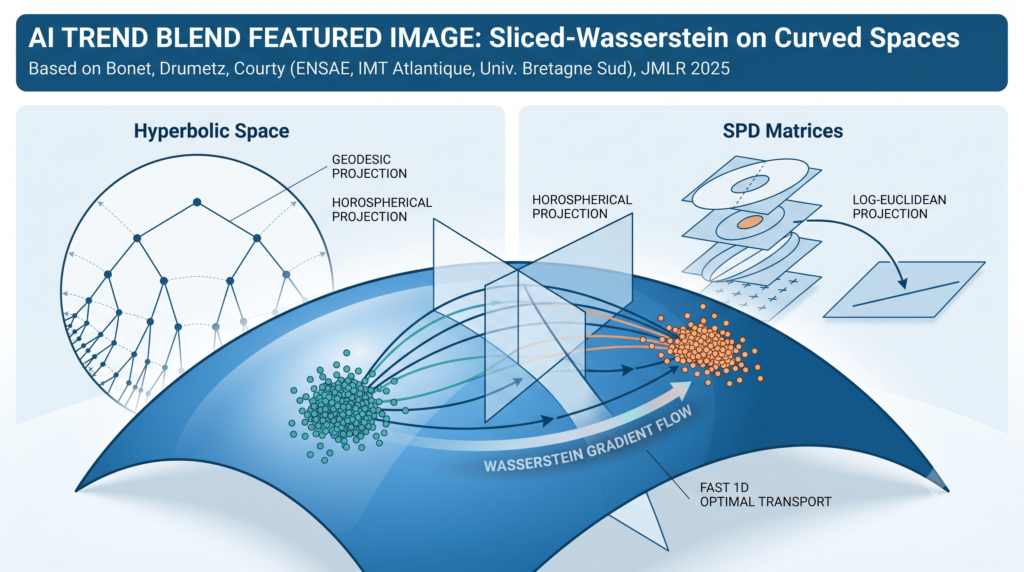
Bonet, Drumetz, and Courty from ENSAE, IMT Atlantique, and Universite Bretagne Sud extend the Sliced-Wasserstein distance to Cartan-Hadamard manifolds, covering hyperbolic spaces and symmetric positive definite matrices with both geodesic and horospherical projections, then prove theoretical guarantees and derive non-parametric…

Sliced-Wasserstein Distances and Flows on Cartan-Hadamard Manifolds Read More »

Statistical Inference via Sketched StoSQP: Online Second-Order Methods for Constrained Optimization.

Statistical Inference via Sketched StoSQP: Online Second-Order Methods for Constrained Optimization

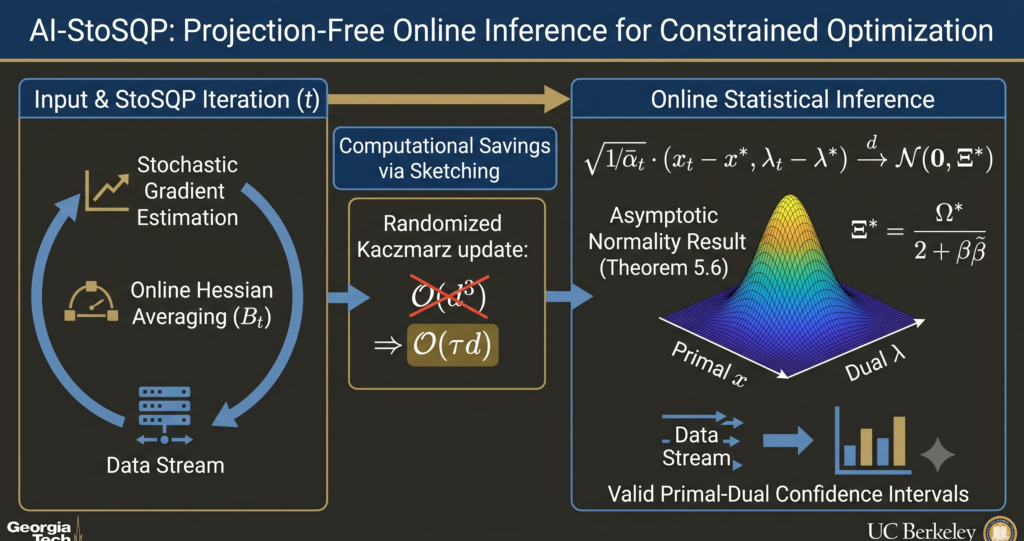
Sen Na at Georgia Tech and Michael Mahoney at UC Berkeley prove that a sketched, adaptive Stochastic SQP method achieves asymptotic normality for constrained nonlinear stochastic optimization — the first online estimator that handles equality constraints without ever computing a…

Statistical Inference via Sketched StoSQP: Online Second-Order Methods for Constrained Optimization Read More »

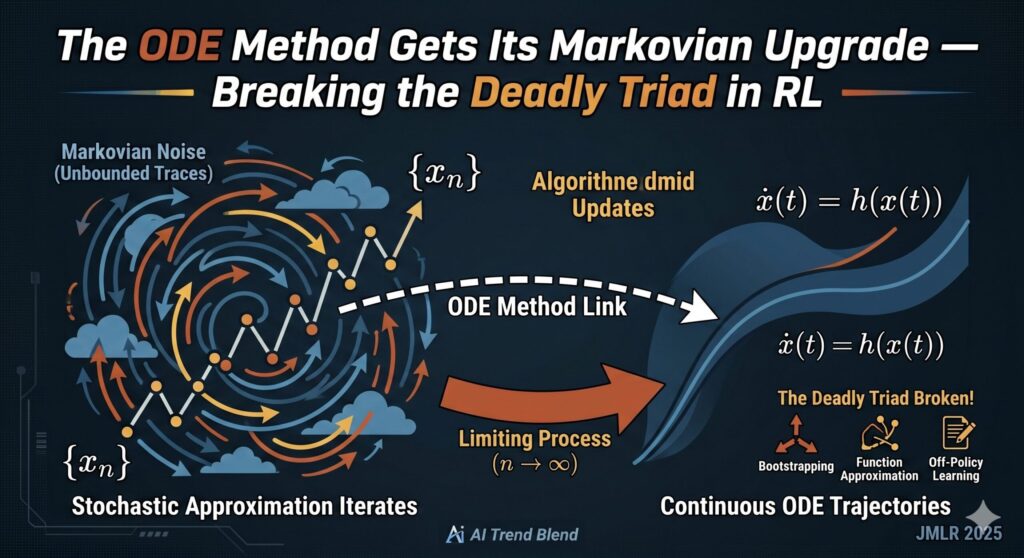
The ODE Method for Stochastic Approximation with Markovian Noise: Breaking the Deadly Triad in Reinforcement Learning.

The ODE Method for Stochastic Approximation with Markovian Noise: Breaking the Deadly Triad in Reinforcement Learning

A team from the University of Virginia and Scaled Foundations has extended the celebrated Borkar-Meyn theorem to handle Markovian noise, unlocking the first rigorous almost-sure convergence guarantees for GTD(λ) and ETD(λ) — the two principal algorithms for tackling the deadly…

The ODE Method for Stochastic Approximation with Markovian Noise: Breaking the Deadly Triad in Reinforcement Learning Read More »

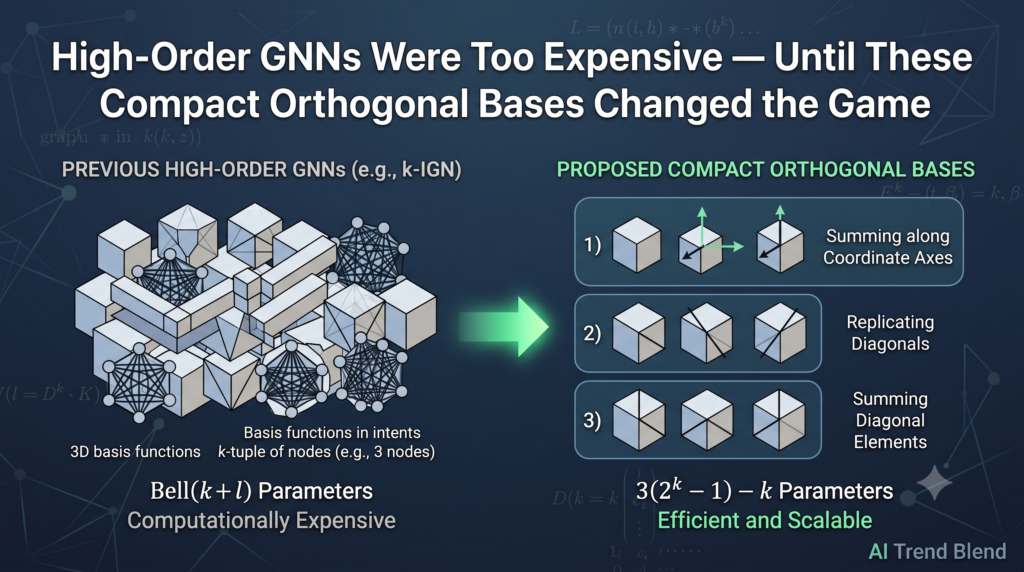
Orthogonal Bases for Equivariant Graph Learning with Provable k-WL Expressive Power.

Orthogonal Bases for Equivariant Graph Learning with Provable k-WL Expressive Power

Jia He and Maggie X. Cheng from Illinois Institute of Technology have found a way to build GNNs with the same k-WL and k-FWL expressive power as the best known high-order networks — using a fraction of the parameters and…

Orthogonal Bases for Equivariant Graph Learning with Provable k-WL Expressive Power Read More »

Riemannian Bilevel Optimization — When Machine Learning Leaves Flat Space Behind.

Riemannian Bilevel Optimization — When Machine Learning Leaves Flat Space Behind

Two researchers from the University of Minnesota and Rice University have cracked open a new frontier: bilevel optimization on Riemannian manifolds. Their algorithms, RieBO and RieSBO, achieve the same theoretical complexity as flat-space methods — unlocking meta-learning, robust estimation, and…

Riemannian Bilevel Optimization — When Machine Learning Leaves Flat Space Behind Read More »

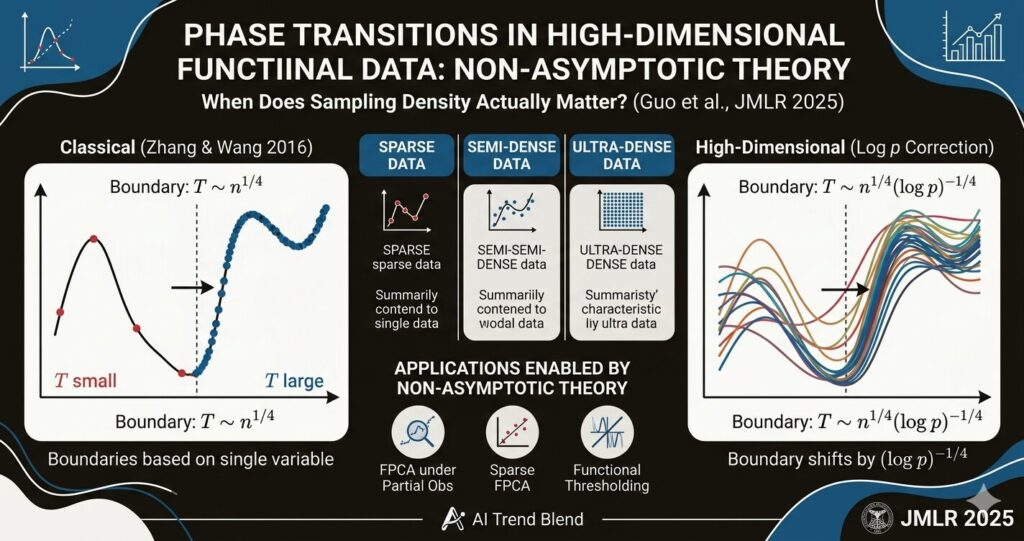
From Sparse to Dense Functional Data in High Dimensions: Phase Transitions Revisited.

From Sparse to Dense Functional Data in High Dimensions: Phase Transitions Revisited

A team from Renmin University of China, Tsinghua University, and the University of Hong Kong proved that the classical sparse-to-dense transition in functional data analysis shifts when the number of functional variables grows large — and derived the exact non-asymptotic…

From Sparse to Dense Functional Data in High Dimensions: Phase Transitions Revisited Read More »

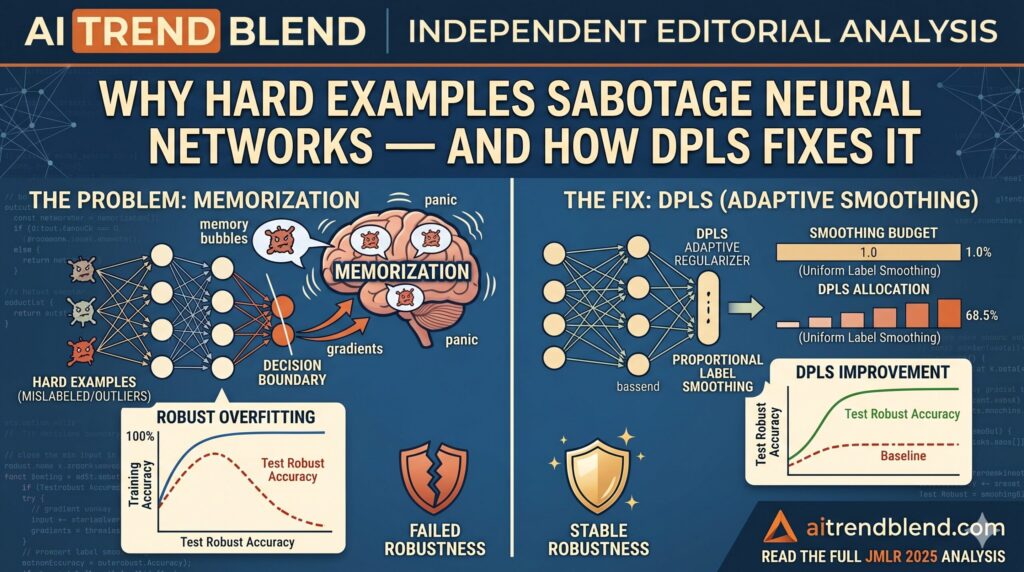
Why Hard Training Examples Hurt Neural Networks — And How DPLS Fixes It.

Why Hard Training Examples Hurt Neural Networks — And How DPLS Fixes It

A team from Seoul National University and Ewha Womans University pinpointed a root cause of robust overfitting — the model memorizes tricky outliers during adversarial training rather than learning from them. Their remedy, difficulty proportional label smoothing, costs almost nothing…

Why Hard Training Examples Hurt Neural Networks — And How DPLS Fixes It Read More »

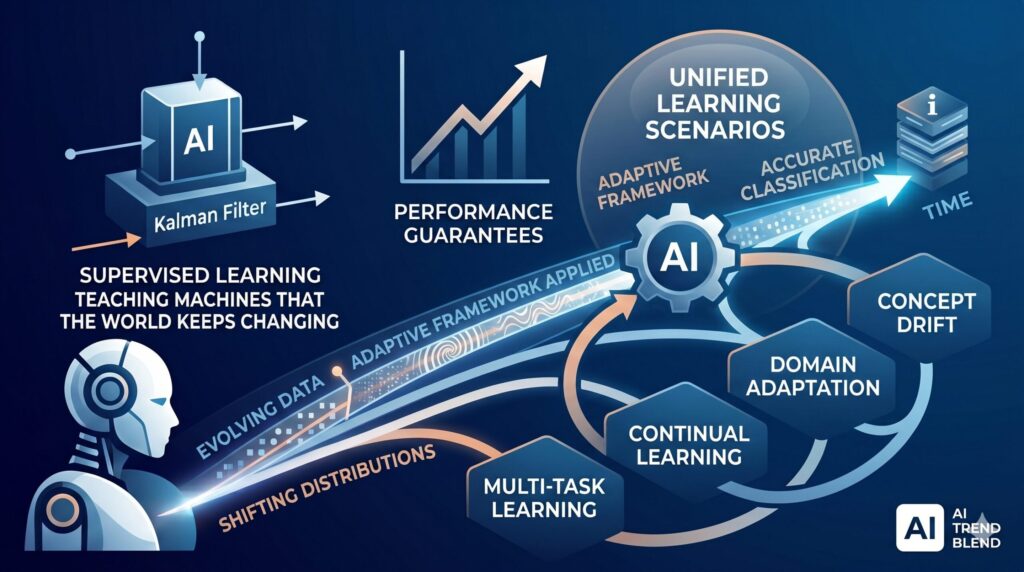
Teaching Machines That the World Keeps Changing: Supervised Learning with Evolving Tasks and Performance Guarantees

Teaching Machines That the World Keeps Changing: Supervised Learning with Evolving Tasks and Performance Guarantees

Verónica Álvarez, Santiago Mazuelas, and Jose A. Lozano show that a single Kalman-filter-based methodology can unify multi-task learning, continual learning, domain adaptation, and concept drift — while being the first to provide computable, tight error-probability guarantees and a closed-form characterization…

Teaching Machines That the World Keeps Changing: Supervised Learning with Evolving Tasks and Performance Guarantees Read More »