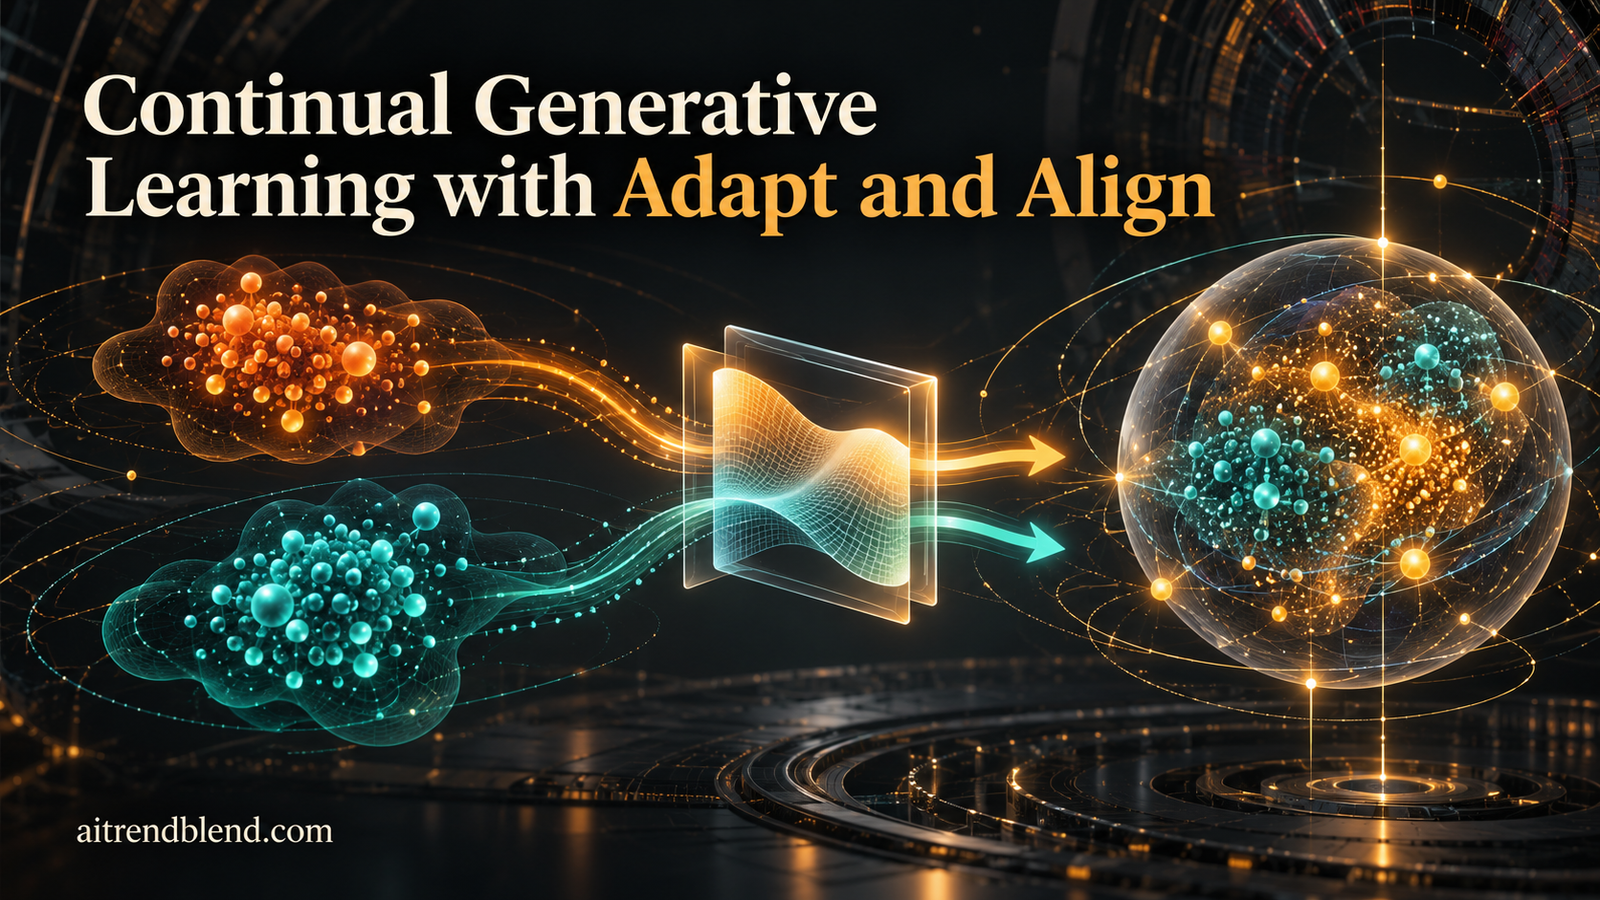
Deep beneath the Franco Swiss border, the Zero Degree Calorimeter inside the ALICE experiment at CERN records subatomic particle showers striking a dense grid of optical fibers. Whenever operators adjust beam energies between experimental runs, the spatial distribution of those energy depositions shifts. If physicists retrain a neural simulator on the new collision stream alone, the network rapidly overwrites its ability to simulate earlier beam energies. Kamil Deja, Bartosz Cywiński, Jan Rybarczyk, and Tomasz Trzciński at Warsaw University of Technology, Ideas Research Institute, and Tooploox designed Adapt and Align to solve this exact failure mode by decoupling local feature acquisition from global latent space consolidation.
Key Research Takeaways
- Adapt and Align splits continual generative modeling into a local training stage that captures current task features and a global consolidation stage that aligns representations via a two layer translator network.
- Unlike standard generative replay, which suffers from progressive memory degradation, the framework freezes the global decoder first to locate an interference free region of the latent space before joint fine tuning.
- A cosine similarity controlled forgetting gate (\(\gamma = 0.9\)) replaces distorted rehearsed generations with fresh real samples whenever new tasks contain overlapping data distributions.
- Extending the framework from Variational Autoencoders (Multiband VAE) to Wasserstein GANs with Gradient Penalty (Multiband GAN) drops Fréchet Inception Distance on Split-MNIST to 9 and reaches 99 percent precision and recall.
- Training a downstream ResNet feature extractor to invert the aligned global latent space yields 51.1 percent classification accuracy on 5 task CIFAR-10 in 9.52 GPU hours, beating diffusion replay (DDGR) at 43.7 percent and 111.96 GPU hours.
Why Generative Replay Degrades Over Streaming Tasks
The problem runs deeper than it first appears. When a neural network trains on a sequence of data batches with shifting distributions, gradient updates tuned for the newest batch overwrite weights that encoded earlier tasks, a phenomenon Robert French formalized in 1999 as catastrophic forgetting. In discriminative classifiers, this failure shows up as a sudden drop in accuracy on older classes. In generative models such as Variational Autoencoders (VAEs) and Generative Adversarial Networks (GANs), forgetting corrupts the learned data manifold so that synthetic samples from earlier tasks blur, collapse, or morph into hybrids of newer classes.
Most continual generative learning systems attempt to stop this decay through one of three mechanisms. Regularization strategies such as Elastic Weight Consolidation (EWC) by Kirkpatrick et al. and Synaptic Intelligence (SI) by Zenke et al. penalize changes to weights deemed important for prior tasks. Dynamic architecture approaches such as Continual Unsupervised Representation Learning (CURL) by Rao et al. or HyperCL by von Oswald et al. expand the network or use hypernetworks to generate task specific weights. Finally, generative rehearsal methods, pioneered in Deep Generative Replay (DGR) by Shin et al. and extended to VAEs by van de Ven and Tolias, use the model itself to synthesize pseudo samples of old tasks and mix them with incoming real data.
None of this comes for free. Standard generative replay forces a single encoder and decoder to absorb new distributions while simultaneously rehearsing its own imperfect reconstructions. As Alemohammad et al. demonstrated in their study of self consuming generative loops, repeatedly training a generator on its own synthetic outputs compounds approximation errors across generations. Worse, almost every benchmark in the literature evaluates models exclusively under a strict class incremental (CI) assumption where Task 1 contains only digits zero and one, Task 2 contains only two and three, and no class ever reappears.
Real data streams rarely behave that neatly. In production pipelines, incoming batches frequently share partial overlap with historical data while introducing gradual drift. When standard generative replay encounters a new class, it fails to separate the new encodings from existing ones immediately, deforming previously stored representations in the process. Conversely, when it encounters additional examples of a class it saw three tasks ago, it lacks a mechanism to merge the fresh, high fidelity examples with its degraded internal memory. A truly capable continual learner should exhibit both forward knowledge transfer, where prior representations accelerate learning on a new task, and backward knowledge transfer, where new data actively sharpens generations of older tasks.
How the Adapt and Align Architecture Separates Acquisition from Consolidation
To prevent new gradients from wrecking established representations while still allowing cross task synergy, the authors of the Adapt and Align paper in Neurocomputing build upon their earlier IJCAI Multiband VAE work and divide every task update into two distinct phases called Local Training and Global Training. For readers following our broader coverage of representation learning on the generative AI and diffusion models hub , this architectural split mirrors how biological systems separate rapid hippocampal encoding from slower neocortical consolidation.
During Phase 1, called Local Training, the system instantiates a local generative model and trains it exclusively on the newly arrived dataset \(D_i\) for task \(i\). Because this local model only needs to represent the current batch \(x_j^i\), its encoder \(q_\phi\) and local decoder \(p_\psi\) can adapt rapidly without any regularization pressure or rehearsal overhead from past tasks. On the very first task (\(i = 1\)), local training is the entire procedure, and the resulting local decoder is promoted directly to serve as the initial global decoder.
Here is where it gets interesting. Instead of partitioning the global latent space into isolated, orthogonal slots for each subsequent task, which would block any sharing of visual primitives across tasks, Phase 2 introduces a lightweight neural network called the translator \(t_\rho(\lambda^i, i)\). The translator takes the task specific latent vector \(\lambda^i\) produced by the local encoder, along with the task identity \(i\), and maps them into a unified, task agnostic global latent space \(\mathcal{Z}\).
Only the lightweight translator network (two fully connected layers) and the global decoder or generator are kept in memory between tasks. The local encoder and local decoder are temporary scaffolding freed immediately after task consolidation finishes, keeping permanent memory footprint constant regardless of how many tasks arrive.
If you updated the translator and the global decoder \(p_\omega(x | \mathcal{Z})\) at the same time from the very first step of Phase 2, random initial gradients from the translator would scramble the weights of the global decoder. Adapt and Align prevents this by splitting global consolidation into two sequential sub stages. First, the global decoder \(p_\omega\) is completely frozen while the translator \(t_\rho\) trains for \(N_T\) steps. Forced to work through a fixed decoder, the translator searches the existing global manifold \(\mathcal{Z}\) to find coordinates that already decode into features resembling the new task, placing novel bands of data in unoccupied regions while snapping familiar classes directly onto their existing global coordinates.
Once the translator has aligned the local latent space \(\lambda^i\) with \(\mathcal{Z}\), the global decoder is unfrozen. Both \(t_\rho\) and \(p_\omega\) are then trained jointly for \(N_G\) steps using auto rehearsal pairs. For the current task \(k\), the training pairs consist of real images \(x^k\) paired with their local encodings \(\lambda\). For all previous tasks \(i \in \{1, \dots, k-1\}\), the system samples random prior noise \(\xi \sim \mathcal{N}(\vec{0}, I)\) and passes it through a frozen snapshot of the translator and global decoder taken at the start of the task to produce synthetic rehearsal targets \(\tilde{x}^i\).
Mathematical Formulations of Multiband VAE and WGAN
To see why this two step alignment holds up mathematically across both likelihood based autoencoders and adversarial networks, let us examine the exact optimization objectives used in each stage. In the Variational Autoencoder implementation, called Multiband VAE, Local Training follows the standard Kingma and Welling variational lower bound (ELBO) on the log likelihood of current task samples \(x\).
In Equation 1, \(\phi\) and \(\theta\) denote the parameters of the local encoder and local decoder, while \(D_{KL}\) measures the Kullback-Leibler divergence between the approximate posterior \(q_\phi(\lambda | x)\) and the standard Gaussian prior \(\mathcal{N}(\vec{0}, I)\).
During Stage 2 (Translator Training with Frozen Global Decoder), the global decoder parameters \(\omega\) are locked. Given \(k\) total tasks seen so far, the translator parameters \(\rho\) are optimized by minimizing the sum of squared reconstruction errors across rehearsed past tasks and the current task \(k\).
During Stage 3 (Joint Global Update), the lock on \(\omega\) is released and the exact same L2 reconstruction objective is minimized jointly with respect to both \(\rho\) and \(\omega\).
Binary Latent Space Disentanglement via Gumbel-Softmax
Think about what happens inside a standard continuous VAE latent space when a single task contains multiple distinct object categories. As Tomczak and Welling as well as Mathieu et al. observed, a subset of continuous latent dimensions stops following a smooth Gaussian bell curve and instead splits into bimodal peaks just to separate class identities. When you later sample near zero between those peaks during generative replay, the decoder outputs ghostly, malformed blends of two classes, and rehearsing those blends compounds degradation.
Deja et al. eliminate this bottleneck by augmenting the local encoder with a discrete binary latent vector \(\lambda_b\) alongside the continuous vector \(\lambda_c \sim \mathcal{N}(\mu_m, \text{diag}(\mu_\sigma^2))\). Using the Gumbel-Softmax categorical reparameterization trick introduced by Jang et al., the encoder outputs Bernoulli probabilities \(\mu_p\) from which binary codes \(\lambda_b \sim B(\mu_p)\) are sampled. On MNIST digits zero and one, histograms of the latent space confirm that the very first binary variable cleanly absorbs the categorical class split, freeing all eight continuous dimensions to model smooth intra class traits such as stroke thickness and slant. During inference, binary variables are sampled using the average probability vector \(\mu_p’\) recorded during the final epoch of local training.
Controlled Forgetting in Overlapping Streams
What if Task 4 contains crisp, real photographs of a class that the model previously saw in Task 1? Standard replay blindly trains the decoder to reproduce blurred Task 1 rehearsal reconstructions alongside the crisp Task 4 images. Adapt and Align introduces a controlled forgetting mechanism that refreshes stale memories. After the translator aligns the current task data into the subset \(\mathcal{Z}^i = t_\rho(q_\phi(X^i), i)\), every rehearsed latent vector \(z_j = t_\rho(\lambda_j^l, l)\) from an older task \(l < i\) is compared against all current task embeddings in \(\mathcal{Z}^i\) using cosine similarity.
Whenever \(\text{sim}(z_j) \ge \gamma\), where \(\gamma = 0.9\) serves as the default threshold across benchmarks (and \(0.95\) for Dirichlet splits), the algorithm discards the synthetic rehearsal image \(\tilde{x}_j^l\) and substitutes the closest real image from the current dataset \(X^i\) as the reconstruction target. Old distorted memories are selectively overwritten by ground truth data.
Extending Adapt and Align to Wasserstein GANs
Because VAEs optimize pixelwise L2 reconstruction, their generations on complex natural images tend to look overly smooth. To prove that Adapt and Align is a universal framework rather than a VAE trick, the authors extend it to Wasserstein GANs with Gradient Penalty (WGAN-GP) following Arjovsky et al. and Gulrajani et al. During Local Training, a local generator \(G_\theta\) and local critic \(D_\phi\) (using layer normalization instead of batch normalization to preserve valid per sample gradient norms) minimize the WGAN-GP critic and generator losses with penalty coefficient \(\lambda = 10\).
Because a GAN has no encoder \(q_\phi\) to map real images into latents during global consolidation, Multiband GAN turns the local generator into a teacher for knowledge distillation. If you have read our technical breakdowns on knowledge distillation and model compression , the mechanism here is remarkably clean. For both past tasks (via the frozen global generator) and the current task (via the newly trained local generator), the system samples Gaussian noise vectors \(\xi\) and generates synthetic images \(\tilde{x}^i\). The translator \(t_\rho(\xi, i)\) and global generator \(G_\theta\) then minimize the L2 distillation distance between \(\tilde{x}^i\) and \(G_\theta(t_\rho(\xi, i))\), first with \(G_\theta\) frozen and then jointly.
Inverting the Global Manifold for Downstream Classification
Can a continually aligned generative latent space power a discriminative classifier without freezing layers or pretraining on external datasets? Deja et al. attach a two part classification pipeline directly to \(\mathcal{Z}\). First, a feature extractor network \(f_\tau\) (such as an MLP, ResNet-18, or ResNet-32) is trained to invert the global decoder by mapping generated images \(\tilde{x}\) back to their post translator global latent coordinates \(z\) via Mean Squared Error. Second, a lightweight single hidden layer classifier head \(c_\psi(z)\) with 100 neurons trains on top of those aligned latents using standard cross entropy loss.
Experimental Benchmarks Across Vision and CERN Physics Simulations
The numbers tell a complicated story for older continual learning methods, especially when tasks share overlapping distributions. Alongside standard Class Incremental (CI) splits on Split-MNIST (5 tasks), Split-Fashion-MNIST (5 tasks), and Split-Omniglot (5 and 20 tasks), the authors evaluate non independent task streams drawn from a Dirichlet distribution \(q \sim \text{Dir}(\alpha p)\). Setting the concentration parameter to \(\alpha = 1\) creates highly imbalanced 10 task or 20 task streams where individual classes randomly dominate certain batches and reappear later, whereas \(\alpha = 100\) distributes classes almost evenly across batches.
| Method | Split-MNIST (CI 5) FID ↓ / Prec ↑ / Rec ↑ | MNIST (Dir α=1, 10) FID ↓ / Prec ↑ / Rec ↑ | Split-Fashion (CI 5) FID ↓ / Prec ↑ / Rec ↑ | Omniglot (Dir α=1, 20) FID ↓ / Prec ↑ / Rec ↑ | CERN ALICE (CI 5) Wass ↓ |
|---|---|---|---|---|---|
| Synaptic Intelligence (SI) | 129 / 77 / 80 | 153 / 75 / 76 | 134 / 28 / 24 | 140 / 18 / 16 | 21.1 |
| Elastic Weight Consolidation (EWC) | 136 / 73 / 82 | 120 / 79 / 83 | 126 / 25 / 25 | 106 / 74 / 38 | 29.7 |
| Standard Generative Replay (GR) | 120 / 79 / 87 | 254 / 70 / 65 | 96 / 43 / 58 | 75 / 53 / 92 | 11.1 |
| Variational Continual Learning (VCL) | 68 / 85 / 94 | 127 / 78 / 80 | 104 / 30 / 32 | 127 / 71 / 25 | 24.3 |
| HyperCL | 62 / 91 / 87 | 78 / 148 / 75 | 108 / 46 / 33 | 115 / 84 / 38 | 7.8 |
| CURL | 107 / 95 / 77 | 181 / 84 / 74 | 64 / 47 / 86 | 26 / 94 / 92 | 16.8 |
| BooVAE | 46 / 95 / 93 | 53 / 95 / 92 | 60 / 77 / 68 | 47 / 97 / 99 | 8.2 |
| MeRGAN | 88 / 88 / 88 | 22 / 87 / 94 | 99 / 47 / 35 | 37 / 71 / 4 | — |
| Multiband VAE (Dense) | 24 / 94 / 97 | 41 / 92 / 96 | 61 / 69 / 66 | 41 / 95 / 83 | 6.6 |
| Multiband VAE (Conv) | 23 / 92 / 98 | 30 / 92 / 97 | 56 / 65 / 72 | 24 / 91 / 96 | 8.1 |
| Multiband GAN (Conv) | 9 / 99 / 99 | 20 / 98 / 98 | 34 / 92 / 92 | 4 / 96 / 93 | 10.3 |
Look closely at what happens to standard Generative Replay on MNIST when moving from the 5 task Class Incremental split to the 10 task Dirichlet \(\alpha = 1\) split in Table 1. Its Fréchet Inception Distance (FID, where lower is better) degrades from 120 to 254. By contrast, dense Multiband VAE cuts that Dirichlet FID to 41, convolutional Multiband VAE lowers it to 30, and convolutional Multiband GAN brings it down to 20 with 98 percent distribution precision and 98 percent recall. An ablation study on the MNIST Dirichlet \(\alpha = 1\) benchmark reveals how each mechanism contributes step by step.
- Baseline Generative Replay starts at an average FID of 254.
- Splitting updates into Two Step Local and Global Training drops FID by 190 points down to 64.
- Adding the Translator network lowers FID to 53.
- Incorporating the Gumbel-Softmax Binary Latent Space reduces FID to 44.
- Enabling Controlled Forgetting (\(\gamma = 0.95\)) trims FID to 41.
- Upgrading from the 9 layer dense autoencoder to a Convolutional architecture reaches an FID of 30.
On the real world CERN ALICE Zero Degree Calorimeter dataset containing 117,817 GEANT4 simulated particle showers of \(44 \times 44\) resolution split across 5 increasing particle energy regimes, dense Multiband VAE achieves a Wasserstein distance of 6.6 between real and generated energy channel distributions, beating EWC (29.7), VCL (24.3), CURL (16.8), standard Generative Replay (11.1), and BooVAE (8.2). Tracking the task matrix across all 5 CERN energy stages shows both forward transfer, where Task 4 starts immediately at a Wasserstein distance of 6.1 compared to 17.8 for standard replay, and backward transfer, where training on later high energy particle showers improves Task 0 simulation distance from 7.8 down to 7.2.
“To our knowledge, this is the first work that experimentally shows that with continually growing data from even partially similar distribution, we can observe both forward and backward knowledge transfer, resulting in improved performance.”
Kamil Deja, Bartosz Cywiński, Jan Rybarczyk, and Tomasz Trzciński, Neurocomputing (2025)
On the 200,000 image CelebA face dataset (\(64 \times 64\) resolution partitioned into 10 hair attribute classes), Multiband VAE under Dirichlet \(\alpha = 100\) achieves an FID of 89 with 36.2 percent precision and 28 percent recall, matching the stationary upper bound of a joint VAE trained on all data at once (88 FID, 35 precision, 30 recall). Multiband GAN pushes CelebA performance even further, achieving an FID of 39 in the 5 task Class Incremental setting and 37 in the 10 task Dirichlet \(\alpha = 100\) setting, outperforming MeRGAN at 57 and 46 respectively.
Downstream Class Incremental Classification and GPU Runtime
When Adapt and Align GAN is paired with a downstream feature extractor and classifier head, it establishes a wide lead over both regularization baselines and recent feature or diffusion replay architectures, a topic we also explore in our coverage of generative representations for image classification.
| Method Category | Algorithm | MNIST (5 Tasks) Accuracy % ↑ | CIFAR-10 (5 Tasks) Accuracy % ↑ | CIFAR-100 (20 Tasks) Accuracy % ↑ | CIFAR-10 Runtime (GPU-Hours) ↓ |
|---|---|---|---|---|---|
| Regularization | Elastic Weight Consolidation (EWC) | 19.8 ± 0.1 | 19.5 ± 0.1 | 9.5 ± 0.83 | — |
| Regularization | Learning without Forgetting (LwF) | 24.2 ± 0.3 | 19.6 ± 0.1 | 14.1 ± 0.87 | — |
| Generative Replay | Deep Generative Replay (DGR) | 91.2 ± 0.3 | 27.3 ± 1.3 | 7.41 ± 0.13 | 1.28 |
| Generative Replay | DGR + Distillation | 91.8 ± 0.3 | 28.4 ± 0.7 | 7.28 ± 0.40 | 1.35 |
| Generative Replay | Replay Through Feedback (RTF) | 92.6 ± 0.2 | 28.7 ± 0.2 | 7.88 ± 0.54 | 1.09 |
| Feature Replay | Brain Inspired Replay (BIR) | 92.8 ± 1.1 | 20.7 ± 0.2 | 6.38 ± 0.65 | 2.49 |
| Feature Replay | Generative Feature Replay (GFR) | — | 26.7 ± 1.9 | 9.5 ± 0.59 | 1.76 |
| Diffusion Replay | Deep Diffusion Generative Replay (DDGR) | 93.5 ± 0.1 | 43.7 ± 2.6 | 7.38 ± 0.01 | 111.96 |
| Latent Alignment | Adapt and Align GAN (Ours) | 95.7 ± 0.1 | 51.1 ± 0.6 | 16.6 ± 0.3 | 9.52 |
As shown in Table 2 above, Brain Inspired Replay (BIR) drops to 20.7 percent accuracy on 5 task CIFAR-10 when evaluated fairly without external pretraining. Deep Diffusion Generative Replay (DDGR) by Gao and Liu reaches 43.7 percent on CIFAR-10, but requires 111.96 GPU hours of compute and collapses to 7.38 percent on 20 task CIFAR-100. Adapt and Align GAN achieves 51.1 percent on CIFAR-10 and 16.6 percent on CIFAR-100 while finishing the CIFAR-10 benchmark in 9.52 GPU hours, more than eleven times faster than diffusion replay.
When deploying continual classifiers on edge servers or constrained GPU clusters, inverting a WGAN translator manifold gives you a 7.4 percentage point accuracy advantage over diffusion replay on CIFAR-10 at less than one tenth of the GPU compute budget.
Honest Limitations and Open Challenges
Despite strong gains across ten datasets, the experimental evidence highlights three concrete limitations that engineers must weigh before putting Adapt and Align into production.
First, the sequence in which tasks arrive materially alters final generation fidelity, a sensitivity also documented in discriminative continual learning by Masana et al. In the cross domain DoubleMNIST experiments, where a model trains across 10 tasks combining handwritten digits (MNIST) and clothing items (FashionMNIST), Multiband GAN achieves an FID of 26 with 93 percent precision and 91 percent recall when trained on simpler MNIST digits first and harder FashionMNIST clothing second. Reversing that curriculum so the network starts on FashionMNIST and transitions to MNIST degrades final FID to 31 and lowers precision and recall to 89 and 87 percent. Starting on a simpler manifold makes it easier for the global generator to establish clean foundational primitives.
Second, scaling to long task horizons on diverse natural images remains an unsolved bottleneck for compact WGAN backbones. On CIFAR-10 split across 5 tasks, Multiband GAN achieves an FID of 73 (86 percent precision, 65 percent recall) compared to a stationary upper bound FID of 43 (92 percent precision, 79 percent recall). However, when CIFAR-100 is split into 20 sequential tasks of 5 classes each, the continual FID climbs to 144 (77 percent precision, 52 percent recall) compared to the stationary upper bound FID of 40 (96 percent precision, 84 percent recall). Over 20 consecutive distillation cycles, high frequency texture details on complex natural scenes still erode.
Third, although memory complexity remains constant between tasks, splitting training epochs into local acquisition (70 epochs for VAE, 120 for GAN), translator warm up (5 epochs), and global consolidation (140 epochs for VAE, 200 for GAN) increases training time to 9.52 GPU hours on CIFAR-10 compared to 1.28 GPU hours for vanilla DGR.
Conclusion and Future Directions
Adapt and Align reframes how generative models accumulate knowledge over time. Rather than forcing a single encoder and decoder to absorb raw distributional shocks simultaneously, separating local representation learning from translator mediated global consolidation prevents latent space deformation before it can start.
The conceptual shift here lies in treating the global decoder not as a static storage buffer, but as a shared rendering engine addressed by a task aware coordinate translator. By freezing the global decoder during the initial translator alignment phase, new tasks discover compatible regions of the existing manifold, turning overlapping data streams from a source of interference into a catalyst for forward and backward transfer.
Because the architecture makes zero assumptions about the underlying generative paradigm, the same two phase blueprint transfers cleanly from dense and convolutional Variational Autoencoders to Wasserstein GANs, and from academic vision benchmarks to GEANT4 particle physics calorimeters at CERN. Furthermore, training a discriminative feature extractor to invert the aligned latent space proves that generative consolidation can directly anchor continual classification without pretraining tricks.
Remaining challenges center on closing the fidelity gap over 20 plus task horizons on high complexity datasets such as CIFAR-100 and reducing sensitivity to task curriculum ordering. Future work combining this lightweight translator alignment mechanism with latent diffusion backbones or parameter efficient low rank adapters could bring constant memory continual learning to foundation scale models. Until then, Adapt and Align stands as one of the most practical, mathematically grounded blueprints for keeping generative models sharp in a changing world.
Complete PyTorch Implementation of Adapt and Align
Below is a complete, self contained, runnable PyTorch implementation of the Multiband VAE Adapt and Align framework, including the Gumbel-Softmax binary latent space, the task conditioned Translator network, the three stage training loop (Local ELBO, Frozen Global Translator Alignment, and Joint Global Consolidation), the cosine similarity Controlled Forgetting gate, the downstream Feature Extractor and Classifier inversion pipeline, and a smoke test on synthetic task streams.
import copy
import torch
import torch.nn as nn
import torch.nn.functional as F
from torch.utils.data import DataLoader, TensorDataset

# =====================================================================
# 1. GUMBEL-SOFTMAX BINARY SAMPLER & MULTIBAND LOCAL VAE ENCODER/DECODER
# =====================================================================

def sample_gumbel_bernoulli(logits: torch.Tensor, temperature: float = 0.5, hard: bool = True) -> torch.Tensor:
    """Differentiable binary latent sampling via Gumbel-Softmax approximation."""
    probs = torch.sigmoid(logits)
    probs_2d = torch.stack([1.0 - probs, probs], dim=-1)
    log_probs = torch.log(probs_2d + 1e-10)
    gumbel_out = F.gumbel_softmax(log_probs, tau=temperature, hard=hard, dim=-1)
    return gumbel_out[..., 1], probs


class LocalEncoder(nn.Module):
    """Dense Encoder mapping 784->512->128->64 into continuous + binary latents (Appendix B & D)."""
    def __init__(self, input_dim: int = 784, cont_dim: int = 8, bin_dim: int = 4):
        super().__init__()
        self.cont_dim = cont_dim
        self.bin_dim = bin_dim
        self.net = nn.Sequential(
            nn.Linear(input_dim, 512),
            nn.LeakyReLU(0.2),
            nn.Linear(512, 128),
            nn.LeakyReLU(0.2),
            nn.Linear(128, 64),
            nn.LeakyReLU(0.2),
        )
        self.fc_mu = nn.Linear(64, cont_dim)
        self.fc_logvar = nn.Linear(64, cont_dim)
        self.fc_bin_logits = nn.Linear(64, bin_dim)

    def forward(self, x: torch.Tensor):
        h = self.net(x)
        mu = self.fc_mu(h)
        logvar = self.fc_logvar(h)
        std = torch.exp(0.5 * logvar)
        eps = torch.randn_like(std)
        lambda_c = mu + eps * std
        bin_logits = self.fc_bin_logits(h)
        lambda_b, probs_b = sample_gumbel_bernoulli(bin_logits)
        return lambda_c, lambda_b, mu, logvar, probs_b


class TranslatorNetwork(nn.Module):
    """Maps (lambda_c, lambda_b, task_code) -> Global Latent Space Z (dim 384)."""
    def __init__(self, cont_dim: int = 8, bin_dim: int = 4, max_tasks: int = 10, z_dim: int = 384):
        super().__init__()
        self.max_tasks = max_tasks
        self.task_branch = nn.Sequential(
            nn.Linear(max_tasks, 18),
            nn.LeakyReLU(0.2),
            nn.Linear(18, 12),
            nn.LeakyReLU(0.2),
        )
        self.bin_branch = nn.Sequential(
            nn.Linear(bin_dim, 8),
            nn.LeakyReLU(0.2),
            nn.Linear(8, 12),
            nn.LeakyReLU(0.2),
        )
        combined_dim = cont_dim + 12 + 12  # 32 for MNIST
        self.shared_mlp = nn.Sequential(
            nn.Linear(combined_dim, 192),
            nn.LeakyReLU(0.2),
            nn.Linear(192, z_dim),
        )

    def forward(self, lambda_c: torch.Tensor, lambda_b: torch.Tensor, task_ids: torch.Tensor) -> torch.Tensor:
        task_onehot = F.one_hot(task_ids, num_classes=self.max_tasks).float()
        t_feat = self.task_branch(task_onehot)
        b_feat = self.bin_branch(lambda_b)
        merged = torch.cat([lambda_c, b_feat, t_feat], dim=-1)
        return self.shared_mlp(merged)


class DecoderNetwork(nn.Module):
    """Global/Local Decoder mapping Z (384) -> 512 -> 1024 -> 784."""
    def __init__(self, z_dim: int = 384, output_dim: int = 784):
        super().__init__()
        self.net = nn.Sequential(
            nn.Linear(z_dim, 512),
            nn.LeakyReLU(0.2),
            nn.Linear(512, 1024),
            nn.LeakyReLU(0.2),
            nn.Linear(1024, output_dim),
            nn.Sigmoid(),
        )

    def forward(self, z: torch.Tensor) -> torch.Tensor:
        return self.net(z)


# =====================================================================
# 2. LOSS FUNCTIONS & CONTROLLED FORGETTING GATE
# =====================================================================

def vae_elbo_loss(x: torch.Tensor, x_hat: torch.Tensor, mu: torch.Tensor, logvar: torch.Tensor) -> torch.Tensor:
    """Equation 1: Negative ELBO = Reconstruction MSE + KL Divergence."""
    recon_loss = F.mse_loss(x_hat, x, reduction='sum') / x.size(0)
    kl_loss = -0.5 * torch.sum(1 + logvar - mu.pow(2) - logvar.exp()) / x.size(0)
    return recon_loss + 0.1 * kl_loss


def apply_controlled_forgetting(
    rehearsal_z: torch.Tensor,
    rehearsal_imgs: torch.Tensor,
    current_z: torch.Tensor,
    current_imgs: torch.Tensor,
    gamma: float = 0.9
) -> torch.Tensor:
    """Equation 7: Substitutes rehearsal targets with real current images if cos_sim >= gamma."""
    reh_norm = F.normalize(rehearsal_z, p=2, dim=-1)
    cur_norm = F.normalize(current_z, p=2, dim=-1)
    sim_matrix = torch.matmul(reh_norm, cur_norm.t())  # [N_reh, N_cur]
    max_sims, best_idx = torch.max(sim_matrix, dim=-1)
    mask = (max_sims >= gamma).unsqueeze(-1)
    substituted_imgs = torch.where(mask, current_imgs[best_idx], rehearsal_imgs)
    return substituted_imgs


# =====================================================================
# 3. ADAPT & ALIGN CONTINUAL TRAINER (ALGORITHM 1)
# =====================================================================

class AdaptAndAlignVAE:
    def __init__(self, input_dim=784, cont_dim=8, bin_dim=4, z_dim=384, max_tasks=10, gamma=0.9, device='cpu'):
        self.cont_dim = cont_dim
        self.bin_dim = bin_dim
        self.z_dim = z_dim
        self.gamma = gamma
        self.device = device

        self.encoder = LocalEncoder(input_dim, cont_dim, bin_dim).to(device)
        self.translator = TranslatorNetwork(cont_dim, bin_dim, max_tasks, z_dim).to(device)
        self.global_decoder = DecoderNetwork(z_dim, input_dim).to(device)
        self.task_bin_priors = {}  # Stores empirical binary probabilities per task

    def train_task(self, task_id: int, dataset: TensorDataset, n_local=5, n_trans=3, n_global=5, batch_size=32):
        loader = DataLoader(dataset, batch_size=batch_size, shuffle=True)

        # Frozen copies of previous global state for generative rehearsal
        prev_translator = copy.deepcopy(self.translator).eval()
        prev_decoder = copy.deepcopy(self.global_decoder).eval()

        # --- STAGE 1: LOCAL TRAINING ---
        local_translator = copy.deepcopy(self.translator).train()
        local_decoder = copy.deepcopy(self.global_decoder).train()
        self.encoder.train()
        opt_local = torch.optim.Adam(
            list(self.encoder.parameters()) + list(local_translator.parameters()) + list(local_decoder.parameters()),
            lr=1e-3
        )

        avg_bin_prob = torch.zeros(self.bin_dim, device=self.device)
        total_batches = 0

        for epoch in range(n_local):
            for (x_batch,) in loader:
                x_batch = x_batch.to(self.device)
                t_ids = torch.full((x_batch.size(0),), task_id, dtype=torch.long, device=self.device)
                opt_local.zero_grad()
                lc, lb, mu, logvar, probs_b = self.encoder(x_batch)
                z = local_translator(lc, lb, t_ids)
                x_hat = local_decoder(z)
                loss = vae_elbo_loss(x_batch, x_hat, mu, logvar)
                loss.backward()
                opt_local.step()
                if epoch == n_local - 1:
                    avg_bin_prob += probs_b.detach().mean(dim=0)
                    total_batches += 1

        self.task_bin_priors[task_id] = (avg_bin_prob / max(1, total_batches)).clamp(0.05, 0.95)

        # On first task, local model directly becomes the global model
        if task_id == 0:
            self.translator.load_state_dict(local_translator.state_dict())
            self.global_decoder.load_state_dict(local_decoder.state_dict())
            return

        # --- PREPARE KNOWLEDGE CONSOLIDATION DATASET (D_KC) ---
        self.encoder.eval()
        all_x = dataset.tensors[0].to(self.device)
        with torch.no_grad():
            cur_lc, cur_lb, _, _, _ = self.encoder(all_x)
            cur_t = torch.full((all_x.size(0),), task_id, dtype=torch.long, device=self.device)

            # Sample rehearsal latents for all previous tasks j < task_id
            n_reh = all_x.size(0)
            reh_lc = torch.randn(n_reh, self.cont_dim, device=self.device)
            reh_t = torch.randint(0, task_id, (n_reh,), device=self.device)
            reh_probs = torch.stack([self.task_bin_priors[int(t.item())] for t in reh_t])
            reh_lb = torch.bernoulli(reh_probs)
            reh_z_old = prev_translator(reh_lc, reh_lb, reh_t)
            reh_imgs = prev_decoder(reh_z_old)

        # --- STAGE 2: TRANSLATOR TRAINING (FROZEN GLOBAL DECODER) ---
        for p in self.global_decoder.parameters():
            p.requires_grad = False
        opt_trans = torch.optim.Adam(self.translator.parameters(), lr=1e-3)

        kc_dataset = TensorDataset(
            torch.cat([cur_lc, reh_lc]),
            torch.cat([cur_lb, reh_lb]),
            torch.cat([cur_t, reh_t]),
            torch.cat([all_x, reh_imgs])
        )
        kc_loader = DataLoader(kc_dataset, batch_size=batch_size, shuffle=True)

        for _ in range(n_trans):
            for b_lc, b_lb, b_t, b_target in kc_loader:
                opt_trans.zero_grad()
                z_pred = self.translator(b_lc, b_lb, b_t)
                x_pred = self.global_decoder(z_pred)
                loss_t = F.mse_loss(x_pred, b_target)
                loss_t.backward()
                opt_trans.step()

        # Apply Controlled Forgetting substitution in aligned space Z
        with torch.no_grad():
            aligned_cur_z = self.translator(cur_lc, cur_lb, cur_t)
            aligned_reh_z = self.translator(reh_lc, reh_lb, reh_t)
            refreshed_reh_imgs = apply_controlled_forgetting(
                aligned_reh_z, reh_imgs, aligned_cur_z, all_x, gamma=self.gamma
            )

        # --- STAGE 3: GLOBAL JOINT UPDATE ---
        for p in self.global_decoder.parameters():
            p.requires_grad = True
        opt_global = torch.optim.Adam(
            list(self.translator.parameters()) + list(self.global_decoder.parameters()), lr=1e-3
        )

        kc_dataset_refreshed = TensorDataset(
            torch.cat([cur_lc, reh_lc]),
            torch.cat([cur_lb, reh_lb]),
            torch.cat([cur_t, reh_t]),
            torch.cat([all_x, refreshed_reh_imgs])
        )
        kc_loader_refreshed = DataLoader(kc_dataset_refreshed, batch_size=batch_size, shuffle=True)

        for _ in range(n_global):
            for b_lc, b_lb, b_t, b_target in kc_loader_refreshed:
                opt_global.zero_grad()
                z_pred = self.translator(b_lc, b_lb, b_t)
                x_pred = self.global_decoder(z_pred)
                loss_g = F.mse_loss(x_pred, b_target)
                loss_g.backward()
                opt_global.step()

    def sample_generations(self, num_samples: int, seen_tasks: int):
        """Samples synthetic images and their aligned Z representations across seen tasks."""
        self.translator.eval()
        self.global_decoder.eval()
        with torch.no_grad():
            t_ids = torch.randint(0, seen_tasks, (num_samples,), device=self.device)
            lc = torch.randn(num_samples, self.cont_dim, device=self.device)
            probs = torch.stack([self.task_bin_priors[int(t.item())] for t in t_ids])
            lb = torch.bernoulli(probs)
            z = self.translator(lc, lb, t_ids)
            x_gen = self.global_decoder(z)
        return x_gen, z, t_ids


# =====================================================================
# 4. DOWNSTREAM FEATURE EXTRACTOR & CLASSIFIER HEAD (SECTION 5.3)
# =====================================================================

class LatentAlignedClassifier(nn.Module):
    """MLP400 Feature Extractor (inverts Decoder to Z) + 100-unit Classifier Head."""
    def __init__(self, input_dim: int = 784, z_dim: int = 384, num_classes: int = 10):
        super().__init__()
        self.feature_extractor = nn.Sequential(
            nn.Linear(input_dim, 400),
            nn.ReLU(),
            nn.Linear(400, 400),
            nn.ReLU(),
            nn.Linear(400, z_dim),
        )
        self.classifier_head = nn.Sequential(
            nn.Linear(z_dim, 100),
            nn.ReLU(),
            nn.Linear(100, num_classes),
        )

    def encode(self, x: torch.Tensor) -> torch.Tensor:
        return self.feature_extractor(x)

    def classify_z(self, z: torch.Tensor) -> torch.Tensor:
        return self.classifier_head(z)

    def forward(self, x: torch.Tensor) -> torch.Tensor:
        z_hat = self.encode(x)
        return self.classify_z(z_hat)


# =====================================================================
# 5. RUNNABLE SMOKE TEST ON 3 CONTINUAL TASKS
# =====================================================================

if __name__ == "__main__":
    torch.manual_seed(42)
    model = AdaptAndAlignVAE(input_dim=784, cont_dim=8, bin_dim=4, z_dim=384, max_tasks=5, gamma=0.9)

    for task_idx in range(3):
        # Generate synthetic task distribution shifted by task_idx
        synthetic_images = torch.sigmoid(torch.randn(128, 784) + task_idx * 0.5)
        task_ds = TensorDataset(synthetic_images)
        model.train_task(task_idx, task_ds, n_local=3, n_trans=2, n_global=3, batch_size=32)
        print(f"[Task {task_idx}] Consolidated into Global Latent Space Z.")

    # Train downstream feature extractor (Eq. 10) and classifier head (Eq. 11)
    downstream = LatentAlignedClassifier(input_dim=784, z_dim=384, num_classes=3)
    opt_fe = torch.optim.Adam(downstream.feature_extractor.parameters(), lr=1e-3)
    opt_clf = torch.optim.Adam(downstream.classifier_head.parameters(), lr=1e-3)

    x_syn, z_syn, y_syn = model.sample_generations(num_samples=192, seen_tasks=3)
    for _ in range(5):
        opt_fe.zero_grad()
        loss_fe = F.mse_loss(downstream.encode(x_syn), z_syn)
        loss_fe.backward()
        opt_fe.step()

        opt_clf.zero_grad()
        logits = downstream.classify_z(z_syn.detach())
        loss_clf = F.cross_entropy(logits, y_syn)
        loss_clf.backward()
        opt_clf.step()

    preds = downstream(x_syn).argmax(dim=-1)
    acc = (preds == y_syn).float().mean().item() * 100.0
    print(f"Smoke Test Complete | FE Inversion MSE: {loss_fe.item():.4f} | Aligned Classifier Acc: {acc:.1f}%")
Frequently Asked Questions
How does Adapt and Align stop catastrophic forgetting in generative models?
Adapt and Align divides training into two stages called local training and global consolidation. First, a local model learns representations exclusively for the new task. Second, a translator network maps those local representations into a shared global latent space while the global decoder is initially frozen, preventing new gradients from overwriting previously learned features before joint fine tuning begins.
Why does Multiband VAE use both binary and continuous latent spaces?
When a standard Variational Autoencoder encodes multiple classes into a single continuous space, some variables drift away from a normal Gaussian distribution to separate class categories, causing blurred hybrids when sampled near zero. Adding a Gumbel-Softmax binary latent space lets the network store categorical class identity in discrete bits while preserving smooth Gaussian distributions for continuous visual features such as stroke width or rotation.
What is controlled forgetting in the Adapt and Align framework?
Controlled forgetting is a mechanism that refreshes degraded rehearsal memories when new tasks contain examples similar to past tasks. During global consolidation, the algorithm calculates the cosine similarity in the global latent space between rehearsed past samples and current real samples. If the similarity meets or exceeds a threshold of 0.9, the synthetic rehearsal target is replaced with the crisp real image from the current task.
How does Adapt and Align compare to diffusion replay methods like DDGR in training speed and accuracy?
On the 5 task CIFAR-10 class incremental benchmark, Adapt and Align with a WGAN backbone achieves 51.1 percent classification accuracy in 9.52 GPU hours. By comparison, Deep Diffusion Generative Replay (DDGR) reaches 43.7 percent accuracy while requiring 111.96 GPU hours of computation.
Does Adapt and Align increase memory usage as more tasks are added?
No, the permanent memory footprint stays constant across any number of tasks. Between tasks, the system only stores the global decoder or generator and the lightweight two layer translator network. The local model used during phase one is temporary and freed from memory as soon as task consolidation finishes.
How was Adapt and Align tested on real physics data from CERN?
The researchers evaluated the framework on 117,817 GEANT4 simulated particle shower responses from the Zero Degree Calorimeter in the ALICE experiment at CERN. The 44 by 44 resolution calorimeter grids were split into 5 sequential tasks ordered by increasing input particle energy. Multiband VAE achieved a Wasserstein distance of 6.6, outperforming standard generative replay at 11.1 and Elastic Weight Consolidation at 29.7.
Explore the Primary Research and Official Code
Inspect the full mathematical proofs, architectural hyperparameters, and official PyTorch repositories released by the Warsaw University of Technology and Ideas Research Institute team.
Academic Citation Deja, K., Cywiński, B., Rybarczyk, J., & Trzciński, T. (2025). Adapt & Align Continual Learning with Generative Models’ Latent Space Alignment. Neurocomputing, 650, 130748. https://doi.org/10.1016/j.neucom.2025.130748
This analysis is based on the published paper and an independent evaluation of its claims.
Your point of view caught my eye and was very interesting. Thanks. I have a question for you.