Optimization & Learning Theory

The mathematics under the hood: optimization methods, convergence guarantees, and the theory that explains when and why deep learning works. Explainers that take proofs seriously without losing the reader.

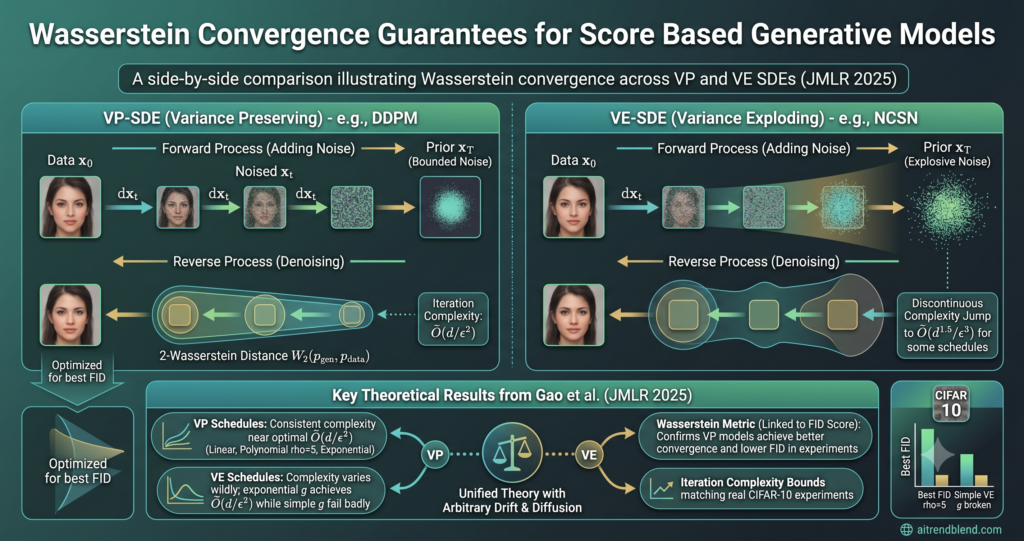
Wasserstein Convergence Guarantees for Score-Based Generative Models.

Wasserstein Convergence Guarantees for Score-Based Generative Models

A research team from the Chinese University of Hong Kong and Florida State University has delivered the first unified convergence theory for a broad class of score based generative models in 2-Wasserstein distance, and it shows that the forward process…

Wasserstein Convergence Guarantees for Score-Based Generative Models Read More »

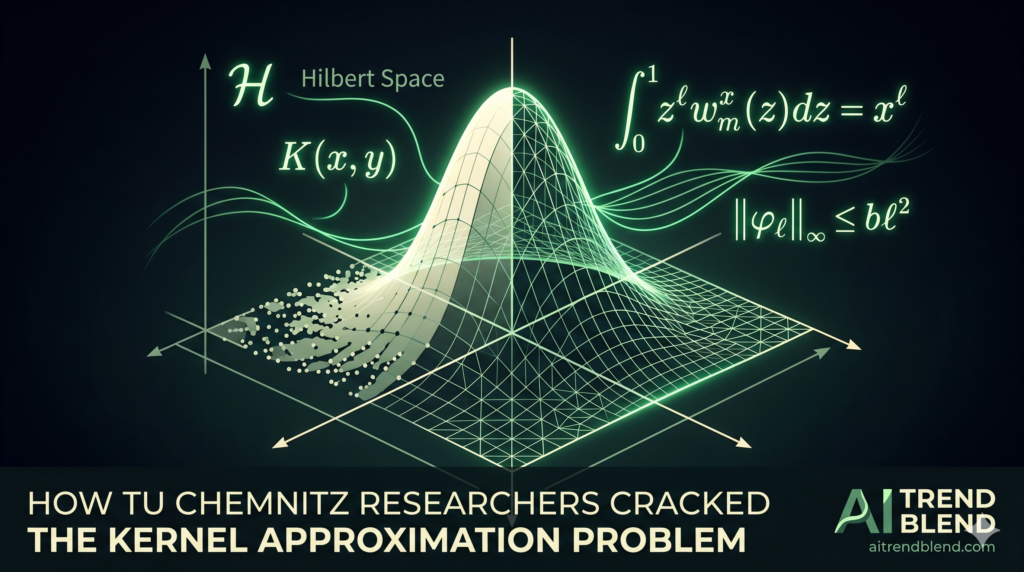
How Dommel and Pichler Finally Cracked the Kernel Approximation Problem That Was Holding Machine Learning Back.

How Dommel and Pichler Finally Cracked the Kernel Approximation Problem That Was Holding Machine Learning Back

Paul Dommel and Alois Pichler from TU Chemnitz developed a Taylor series based approach to approximate kernel functions in reproducing kernel Hilbert spaces. Their work produces the first non-exponential eigenfunction bounds ever recorded and opens the door to regularization parameters…

How Dommel and Pichler Finally Cracked the Kernel Approximation Problem That Was Holding Machine Learning Back Read More »

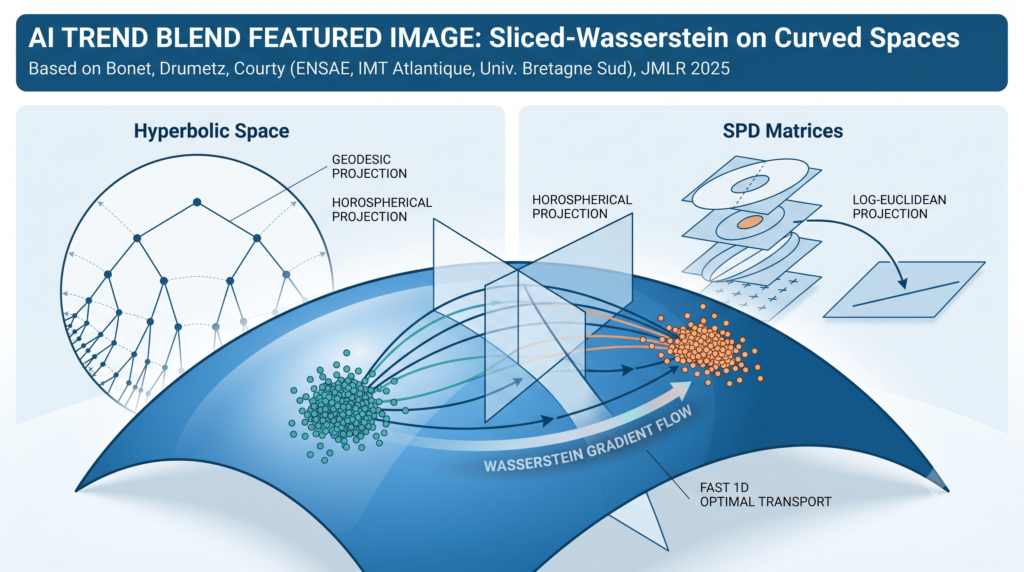
Sliced-Wasserstein Distances and Flows on Cartan-Hadamard Manifolds.

Sliced-Wasserstein Distances and Flows on Cartan-Hadamard Manifolds

Bonet, Drumetz, and Courty from ENSAE, IMT Atlantique, and Universite Bretagne Sud extend the Sliced-Wasserstein distance to Cartan-Hadamard manifolds, covering hyperbolic spaces and symmetric positive definite matrices with both geodesic and horospherical projections, then prove theoretical guarantees and derive non-parametric…

Sliced-Wasserstein Distances and Flows on Cartan-Hadamard Manifolds Read More »

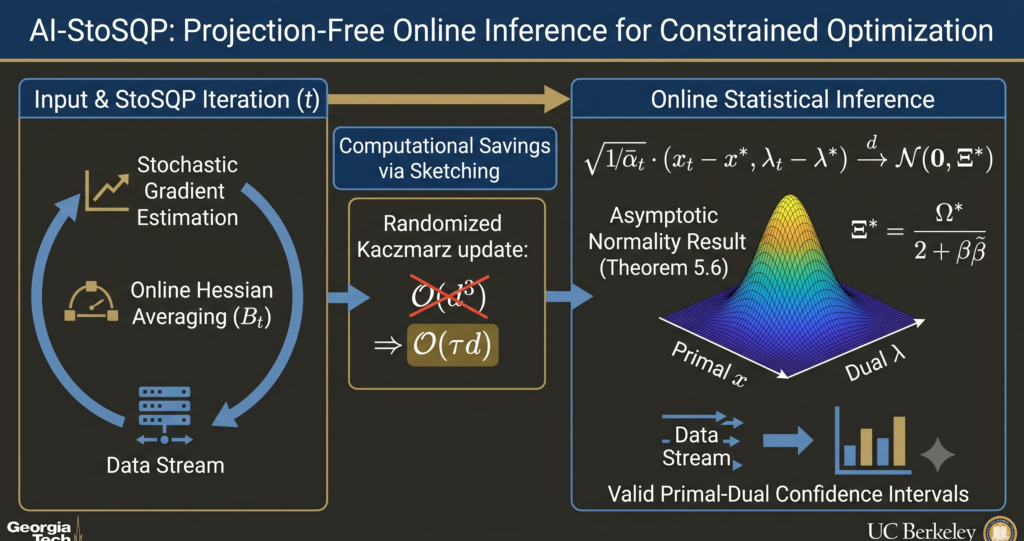
Statistical Inference via Sketched StoSQP: Online Second-Order Methods for Constrained Optimization.

Statistical Inference via Sketched StoSQP: Online Second-Order Methods for Constrained Optimization

Sen Na at Georgia Tech and Michael Mahoney at UC Berkeley prove that a sketched, adaptive Stochastic SQP method achieves asymptotic normality for constrained nonlinear stochastic optimization — the first online estimator that handles equality constraints without ever computing a…

Statistical Inference via Sketched StoSQP: Online Second-Order Methods for Constrained Optimization Read More »

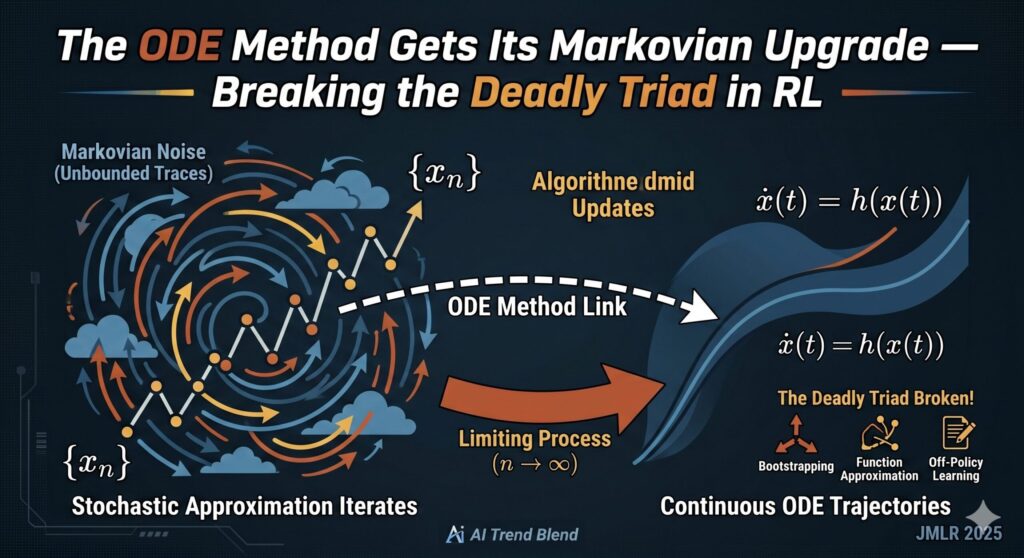
The ODE Method for Stochastic Approximation with Markovian Noise: Breaking the Deadly Triad in Reinforcement Learning.

The ODE Method for Stochastic Approximation with Markovian Noise: Breaking the Deadly Triad in Reinforcement Learning

A team from the University of Virginia and Scaled Foundations has extended the celebrated Borkar-Meyn theorem to handle Markovian noise, unlocking the first rigorous almost-sure convergence guarantees for GTD(λ) and ETD(λ) — the two principal algorithms for tackling the deadly…

The ODE Method for Stochastic Approximation with Markovian Noise: Breaking the Deadly Triad in Reinforcement Learning Read More »