- Classification metrics
- Micro and macro averaging
- Multilabel evaluation
- Confusion matrix algebra
- Decision thresholds
- Soft labels
- PyTorch
A reviewer reads a results table with four columns for a ten class image benchmark. Accuracy 0.912, micro precision 0.912, micro recall 0.912, micro F1 0.912. The authors present them as four pieces of evidence. The reviewer suspects they are one number printed four times, but cannot quite say why. Two rows down, a different paper on the same benchmark reports a balanced accuracy of 0.44 for a baseline and calls it a weak result, without saying that a model which is wrong on every single image would score exactly that.
Ronaldo Prati of the Universidade Federal do ABC in Brazil has written the paper that settles both questions, and many like them. His unified algebraic framework represents labels as binary matrices and builds every averaged metric from three summation operators. Once you see metrics this way, several things that practitioners half know become exact statements, and a few things almost nobody checks turn out to matter.
Key points
- Actual and predicted labels become binary matrices, and four Boolean combinations of them give true positive, false positive, false negative and true negative matrices.
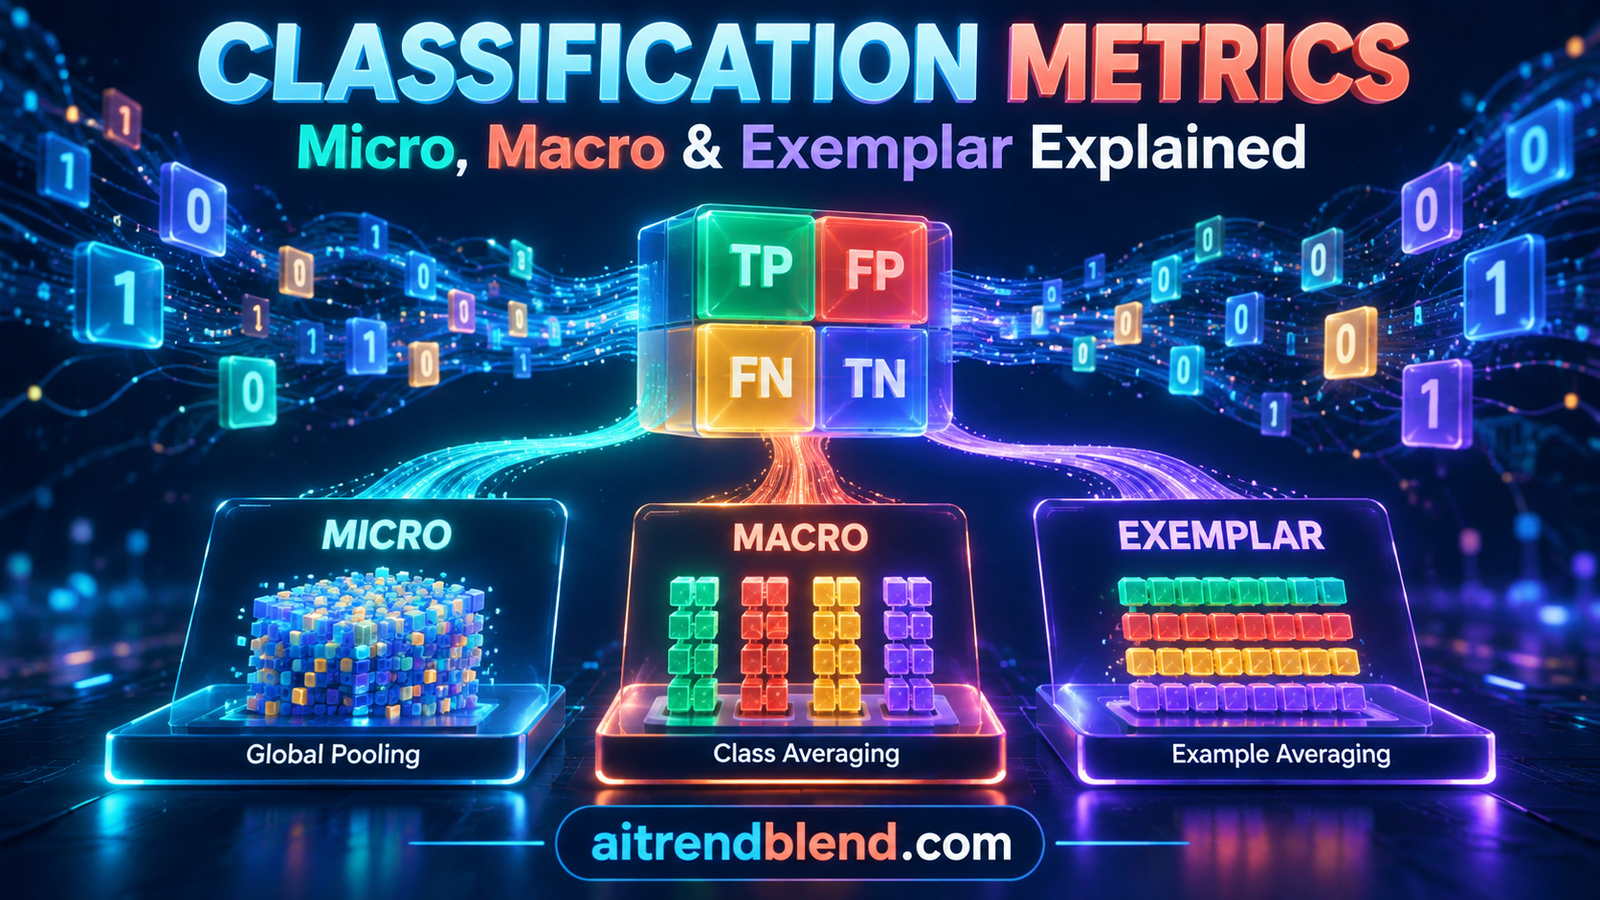
- Summing those matrices globally, by column or by row gives micro, macro and exemplar averaging. Any binary metric written in the four counts extends to multiclass and multilabel problems by swapping the operator.
- For ratio metrics such as precision, recall and F1, micro averaging is exactly macro averaging weighted by each class’s denominator, and the gap between them is a covariance.
- In single label multiclass problems, micro precision, micro recall and micro F1 all equal accuracy. Our own check shows exemplar precision, recall and F1 collapse onto it as well.
- Metrics that still depend on true negatives when there are no true positives have floors under one hot encoding. On ten classes, a model that is always wrong scores a balanced accuracy of 0.444 and an MCC of minus 0.111.
- We reimplemented the framework in PyTorch and every identity we tested holds to machine precision. Our reading of the threshold experiment is more cautious than the paper’s.
Why metrics fragment beyond the binary case
Binary evaluation is well understood. A confusion matrix has four cells, and every familiar metric is some arithmetic on them. Precision divides true positives by predicted positives. Recall divides them by actual positives. F1 is the harmonic mean of the two. Sokolova and Lapalme catalogued twelve such measures and their properties in 2009, and the list has kept growing.
The trouble starts with more than two classes. A ten class problem has ten one versus rest confusion matrices, and you must decide how to combine them. Pool the counts and compute once, and you get micro averaging. Compute per class and average, and you get macro averaging. Weight that average by class size, and you get weighted averaging. In multilabel problems, where an example can carry several labels at once, you can also compute per example and average, which is exemplar averaging. Each combination produces a different number from the same predictions, and each tends to be derived separately for each metric, as Sebastiani did for text categorisation and Tsoumakas and Katakis did for multilabel learning.
That piecemeal history has consequences. Ferri and colleagues showed that classifier rankings depend heavily on which metric you choose. Hand, Christen and Ziyad recently argued that the measure must be matched to the problem. What has been missing is a single mechanism that produces all the variants at once and lets you prove things about all of them together. That is what this paper supplies.
The framework in three steps
Labels as indicator matrices
For \(n\) examples and \(m\) classes or labels, the actual labels form a binary matrix \(Y \in \{0,1\}^{n\times m}\) and the predictions form \(\hat Y\). In multiclass problems each row has exactly one entry equal to 1, which is ordinary one hot encoding. In multilabel problems a row can have several. The four count matrices follow from Boolean operations applied entry by entry.
Three ways of summing
Global aggregation \(\Sigma_1\) adds every entry and returns a scalar. Column aggregation \(\Sigma_m\) adds down each column and returns one count per class. Row aggregation \(\Sigma_n\) adds across each row and returns one count per example. The averaging schemes are then simply which operator you apply before plugging counts into a binary formula \(M(tp, fp, fn, tn)\).
Here \(\mathcal{D}\) is the set of classes or examples on which the metric is defined. That small detail matters, and we come back to it below.
Error rate becomes a disagreement count
A quick example shows the style. Because false positives and false negatives never overlap, the error rate is the number of entries where the two indicator vectors disagree, \(\Sigma_1(y \oplus \hat y)/n\). Apply the same expression to matrices and you get Hamming loss for multilabel problems, \(\Sigma_1(Y \oplus \hat Y)/(nm)\), with no extra derivation. Hamming loss and label accuracy then add to exactly 1, since every entry either agrees or disagrees.
Micro, macro and exemplar averaging are not three metrics. They are one metric read through three different summations of the same four matrices. aitrendblend analysis of Prati, Information Fusion 2027
What the algebra proves
Micro averaging is a weighted macro average, for ratio metrics
Call a measure aggregation decomposable if it can be written as one ratio of two linear forms in the counts, \(\langle a, v\rangle / \langle b, v\rangle\) with \(v = (tp, fp, fn, tn)\). Accuracy, error rate, precision, recall, specificity, the F family and the Jaccard index all qualify. Balanced accuracy, the G mean, MCC and Cohen’s kappa do not, because they mix rates with different denominators, take roots, or correct for chance with quadratic terms.
Read the first identity slowly. Micro recall is macro recall weighted by how many actual examples each class has. Micro precision is macro precision weighted by how often each class is predicted, which depends on the model, not the data. The second identity says the gap between micro and macro is the covariance between those weights and the per class scores. If the model does best on its biggest classes, micro beats macro. If it does best on rare classes, macro wins. Micro and macro agree for every possible set of per class scores only when all denominators are equal.
Outside this class, there is no weighting that recovers the micro value at all. The paper’s Example 1 makes the point with a three class problem of 275 examples. We rebuilt the confusion matrix from the stated class sizes and reproduced every number.
| Measure | Class 1 | Class 2 | Class 3 | Macro | Micro, pooled |
|---|---|---|---|---|---|
| Recall, decomposable | 0.846 | 0.615 | 0.625 | 0.695 | 0.727, inside the range |
| Specificity, decomposable | 0.690 | 0.929 | 0.923 | 0.847 | 0.864, inside the range |
| Balanced accuracy | 0.768 | 0.772 | 0.774 | 0.771 | 0.795, above every class |
| G mean | 0.764 | 0.756 | 0.760 | 0.760 | 0.792, above every class |
| MCC | 0.539 | 0.578 | 0.586 | 0.568 | 0.591, above every class |
Table A. Example 1 of Prati, with confusion matrix rows (110, 10, 10), (20, 40, 5) and (25, 5, 50). Our implementation reproduces the micro values 0.795, 0.793 and 0.591 to three decimals, the G mean to within rounding.
A pooled score that sits above every individual class score is a strong hint that pooling is the wrong operation for that metric. Anyone who reports micro balanced accuracy or micro MCC in a multiclass paper is reporting something that no per class reading can explain.
Micro metrics collapse onto accuracy
Under one hot encoding, every wrong prediction creates exactly one false positive, in the predicted class, and one false negative, in the true class. So the pooled false positive and false negative counts are equal, and both equal the number of errors.
where \(C\) is the number of correct predictions. The reviewer’s suspicion in our opening was right. Those four columns are one number. Micro Jaccard is a different number, but a strictly increasing function of accuracy, so it carries no new information either. The differences people see between micro precision and micro recall in published work come from multilabel problems, where rows can contain zero or several ones.
Here is where it gets interesting. Running our own implementation, we noticed that the exemplar operator collapses too. With one hot rows, each example has one predicted label and one true label, so its precision, recall and F1 are all 1 when it is right and 0 when it is wrong. Averaging over examples gives accuracy again. In single label multiclass work, all six micro and exemplar variants of precision, recall and F1 are the same statistic as accuracy. Only macro and weighted averaging carry information beyond accuracy.
If a multiclass paper reports accuracy and micro F1 as different numbers, something is off. Either the task is really multilabel, the model can abstain or predict several classes, or the metric was computed incorrectly. The scikit-learn documentation notes the same equality for its micro averaged scores.
How many numbers are worth reporting
With class sizes fixed, an \(m\) class confusion matrix has \(m(m-1)\) free entries. Any list of more than \(m(m-1)\) metrics is therefore redundant. In binary classification there are two degrees of freedom, so recall and specificity determine everything once the class prior is known. Accuracy is \(\pi\,\text{rec} + (1-\pi)\,\text{spec}\) and balanced accuracy is their plain average.
The paper’s advice in Remark 2 is to avoid reporting measures with collinear gradients, giving accuracy alongside balanced accuracy and F1 as an example. That needs a small refinement. As functions of recall and specificity, accuracy and balanced accuracy have gradients \((\pi, 1-\pi)\) and \((\tfrac12, \tfrac12)\), which are collinear only when the classes are balanced. With imbalanced classes, those two numbers together pin down recall and specificity exactly. What is redundant is the trio, since three numbers cannot carry more than two degrees of freedom. The practical advice stands, and the paper’s own recommendation to pair a row conditioned measure such as macro recall with a column conditioned one such as macro precision is a sound default.
Floors that never reach zero
This is the result most likely to change how people read tables. In binary and multilabel problems, the worst possible prediction is the exact complement of the truth, which makes true positives and true negatives both zero. Under one hot multiclass encoding that prediction is impossible, because every row must contain exactly one 1. A model that is wrong on every example still produces \(n(m-2)\) true negatives, one for each class that was neither the truth nor the guess.
Any metric whose value at zero true positives still depends on true negatives is lifted off its minimum. We computed every row of the paper’s Table 7 and they match.
| Measure at the worst prediction | Closed form | m = 3 | m = 5 | m = 10 |
|---|---|---|---|---|
| Accuracy, recall, precision, F1, Jaccard, G mean | 0 | 0 | 0 | 0 |
| Label accuracy | \((m-2)/m\) | 0.333 | 0.600 | 0.800 |
| Specificity | \((m-2)/(m-1)\) | 0.500 | 0.750 | 0.889 |
| Balanced accuracy | \((m-2)/(2(m-1))\) | 0.250 | 0.375 | 0.444 |
| MCC and Cohen’s kappa | \(-1/(m-1)\) | minus 0.500 | minus 0.250 | minus 0.111 |
Table B. Attainable floors of micro averaged measures under one hot encoding, from Table 7 of Prati and confirmed by our implementation.
Think about what the last row means. MCC and kappa are designed to read minus 1 for total disagreement and 0 for chance. On ten classes, total failure lands at minus 0.111, barely distinguishable from chance on the measure’s own scale. A balanced accuracy of 0.444 on a ten class problem is not a weak model. It is the score of a model that never gets anything right. The G mean escapes, because a zero recall multiplies everything to zero, while balanced accuracy, an arithmetic mean, does not.
The remedy is simple. Map the floor to 0 and the maximum to 1 with \((M – M_{floor})/(1 – M_{floor})\), or report the floor alongside the score. The test for whether a metric needs it is equally simple. Set \(tp = 0\) in its formula and see whether \(tn\) survives.
Soft labels and the product t norm
When ground truth is uncertain, for example a probability from several annotators, the indicator matrices become real valued in [0, 1] and Boolean AND has to be replaced. Fuzzy logic offers t norms, including the product \(ab\), the minimum, called Gödel, and Łukasiewicz \(\max(a+b-1, 0)\). The paper asks which choice keeps the soft confusion matrix behaving like a contingency table, with true positives plus false negatives equal to the actual membership in every cell.
The proof uses only the t norm axioms, building the result up from dyadic fractions, with no continuity assumption. In our check on random soft matrices, the product t norm reproduced the marginals exactly, while Gödel and Łukasiewicz were off by up to 0.37 in a single cell. One interpretive note the paper leaves implicit. The product \(ab\) is the probability that two independent events both happen. Using it treats annotation uncertainty and prediction uncertainty as independent, which is reasonable for a model trained on hard labels but less so for one trained to mimic the same soft labels, as in knowledge distillation with soft targets.
Ordinal error is a cost matrix
Cost sensitive evaluation enters as a bilinear form, the total cost \(\mathrm{tr}(Y K \hat Y^{\top})\) for a cost matrix \(K\). Theorem 4 shows that mean absolute error and mean squared error for ordered classes are this form with \(K_{jk} = |j-k|\) and \((j-k)^2\). Our implementation returns the same value both ways on random ordinal data. It is a modest result, but it means ordinal regression losses and cost sensitive classification live in one place.
Which metrics ignore class skew
In the binary case, a prior shift rescales the positive and negative rows of the confusion matrix by independent factors. Theorem 5 shows that a measure is unaffected by every such rescaling if and only if it is a function of recall and specificity alone. Recall, specificity, balanced accuracy and the G mean pass. Precision, F1, Jaccard, accuracy, MCC and kappa do not. Proposition 8 adds that a non constant measure can be both skew invariant and a single linear ratio only if it is essentially recall or specificity in disguise.
The multiclass story is subtler. Per class recall stays prior free, because it only depends on how the model treats that class’s own examples. One versus rest specificity does not, because its negatives are a mixture of all other classes, and their proportions change with the prior. The paper tests this on the digits dataset, holding a model’s conditional error rates fixed and sliding the prior on class 0 from 0.10 to 0.85.
| Classifier | Accuracy | Error pattern spread | Drift in macro recall | Drift in macro specificity | Drift in macro balanced accuracy |
|---|---|---|---|---|---|
| Logistic regression | 0.933 | 0.0086 | 0.0000 | 0.0053 | 0.0026 |
| Decision tree, depth 3 | 0.459 | 0.0505 | below 1e minus 15 | 0.0439 | 0.0219 |
Table C. Drift across a prior sweep on digits, from Table 12 of Prati. Balanced accuracy drifts exactly half as much as specificity because recall contributes none.
Multiclass balanced accuracy is therefore only approximately prior free, and the approximation is worst for exactly the weak, lopsided models where you most want a fair metric.
Thresholds in closed form
For a measure whose numerator is linear in the counts and whose denominator does not depend on the predictions, the best decision rule is a simple threshold on the calibrated probability \(\eta(x)\).
Accuracy, with \((1,0,0,1)\), gives 0.5. A cost sensitive objective where a missed positive costs five times a false alarm, \((0,1,5,0)\), gives 1/6. Standard training targets the measure exactly when \(\alpha + \gamma = \beta + \delta\), which is the familiar condition for the 0.5 threshold. Our grid search over 2,001 thresholds on calibrated synthetic probabilities landed within 0.0005 of every closed form we tried.
The paper notes that precision and the F measures fall outside this class and admit no such closed form. That is true for a formula in the coefficients alone, but F1 has a neat implicit characterisation that follows from the same style of argument. Adding an example with probability \(\eta\) to the predicted positives raises the expected F1 exactly when \(\eta\) exceeds half the current F1. So at the optimum, the threshold equals half the best achievable F1. On our synthetic data the best threshold was 0.2710 and half the best F1 was 0.2711. It is not a closed form, since you need the optimum to find it, but it explains why F1 optimal thresholds sit well below 0.5 on imbalanced problems.
What the experiments show
The empirical section is presented as illustration rather than benchmark, and it is best read that way. The synthetic checks, 1,200 random five class classifiers for the covariance identity and Dirichlet soft labels for the t norms, behave exactly as the algebra predicts. The real data experiments make three practical points.
The operator can decide the winner. On the yeast multilabel benchmark, with 2,417 examples and 14 labels whose prevalence ranges from 0.014 to 0.751, five binary relevance classifiers were ranked by ten metric and operator combinations. Macro F1 and macro recall put the decision tree first, a model ranked last by all eight other measures, and macro F1 against micro precision gave a complete reversal, Kendall’s tau of minus 1. On the nearly balanced emotions benchmark, the same ten measures largely agreed, with a minimum tau of 0.2. Imbalance, not the metric family, is what drives disagreement.
The undefined value convention moves results. When a class is never predicted, its precision is 0 divided by 0. The paper averages only over defined entries. The scikit-learn default substitutes 0. On yeast, that choice shifted macro precision by up to 0.110, and on emotions exemplar precision by up to 0.087. Rankings happened to survive on these datasets, but a 0.110 shift is larger than the margins separating most published methods.
Every reported macro or exemplar metric needs three facts stated next to it. Which operator, how undefined entries were handled, and whether the task is single label or multilabel. Without them the number cannot be compared to anything.
A closer look at the threshold experiment
The paper tests Proposition 9 on two medical screening datasets, Breast Cancer Wisconsin with 228 test cases and Mammography with 4,474 and a prevalence of 0.023, using logistic regression with and without Platt scaling. In expectation under the model’s own probabilities, every closed form threshold is recovered exactly, which is a check of the algebra. Against the real test labels, it reports the interval of thresholds that achieve the best empirical score.
| Objective | Closed form t* | Breast | Breast plus Platt | Mammography | Mammography plus Platt |
|---|---|---|---|---|---|
| Accuracy | 0.500 | 0.264 to 0.423 | 0.526 to 0.531 | 0.519 to 0.534 | 0.488 to 0.504 |
| Weighted accuracy, w = 0.75 | 0.250 | 0.264 to 0.267 | 0.398 to 0.428 | 0.147 to 0.172 | 0.164 |
| Clinical net benefit, pt = 0.333 | 0.333 | 0.264 to 0.267 | 0.398 to 0.428 | 0.241 to 0.252 | 0.228 to 0.238 |
| Cost 5 to 1 | 0.167 | 0.264 to 0.267 | 0.398 to 0.428 | 0.121 | 0.102 to 0.104 |
| Cost 10 to 1 | 0.091 | 0.264 to 0.267 | 0.398 to 0.428 | 0.076 | 0.076 |
Table D. Selected rows of Table 11 of Prati. Each cell is the interval of thresholds that maximise the empirical score on test labels.
The paper concludes that calibration aligns the empirical plateau with the theoretical optimum, citing the calibrated mammography accuracy interval of 0.488 to 0.504, which does contain 0.5. Read across the whole table and the picture is more mixed. Recall and specificity have degenerate thresholds of 0 and 1, and error rate duplicates accuracy, so the informative comparison is accuracy plus the five asymmetric objectives, the general linear objective included. Across those twelve calibrated cells, only the mammography accuracy interval contains its closed form. On breast cancer, every asymmetric objective, from equal costs to ten to one, lands on the same empirical interval, before and after calibration, because 228 test cases simply do not have enough examples near the threshold to separate them.
This does not undermine Proposition 9. The theorem is about population quantities, and the expected value check confirms it. What the table actually shows is that small test sets cannot verify thresholds, and that Platt scaling, a monotone transform of a well ranked model, moves plateaus around without reliably centring them. The honest recommendation is the one the paper gestures at. Calibrate on a separate set, then set the threshold from the formula, rather than tuning it on test labels.
Where this fits in practice
For anyone writing or reviewing papers, the framework turns into a short checklist. In single label multiclass work, report accuracy once and do not add micro precision, recall or F1. Add macro recall and macro precision, which carry information accuracy does not. Never pool balanced accuracy, MCC or the G mean across classes and call it micro. If you report balanced accuracy, specificity, MCC or kappa on a multiclass problem, state the floor for your number of classes, or renormalise. State the operator and the undefined value convention for every macro or exemplar number. Choose thresholds from the formula for your cost structure on calibrated probabilities, rather than from a test set.
We have come across several of these issues on this site. Our analysis of ETF-UML for incomplete ICU data noted that a training loss which shifts probabilities by the class prior makes them unusable as risks without correction, which is exactly the calibration Proposition 9 relies on. FALCON’s active clustering results are reported in adjusted Rand index, a chance corrected agreement measure with its own subtleties. And our piece on overconfident models covers why the calibrated probability \(\eta(x)\) is harder to obtain than it looks.
The broader lesson echoes the axiomatic tradition, from Hartigan’s axioms for clustering to Gösgens and colleagues’ properties for classification measures. Properties that justify choosing a binary metric do not automatically survive when the metric is extended. The value of an algebraic framework is that it lets you check, once, for every metric at the same time.
Limitations
Scope of the empirical section. The rank reversal result rests on five classifiers and two multilabel datasets. It illustrates that reversals happen, not how often. The threshold experiment uses one model family on two datasets, with intervals measured on the test set itself.
Calibration claim. As shown above, the statement that calibration aligns empirical plateaus with the closed form holds in one of the twelve calibrated cells that test it. The theory is unaffected, but the empirical support for the practical recommendation is thin.
Uncertainty in metric estimates. All identities concern point values on a fixed test set. Confidence intervals, and how the micro versus macro choice affects their width, are left for future work, which the author acknowledges.
Breadth versus depth. The paper covers twelve settings, from abstaining and open set classifiers to hierarchical and partial labels. Several of these are mappings into the framework rather than new results, and the most consequential findings are concentrated in Sections 7.1 to 7.9.
Code availability. Code and data are distributed as supplementary material, with a public repository promised. We did not have access to the supplementary files, so our checks rely on our own independent implementation.
Wording. Remark 2’s description of accuracy and balanced accuracy as having collinear gradients holds only at balanced priors, as discussed above.
Reproducing the framework in PyTorch
The listing below is our independent implementation of the framework from the paper’s definitions. It builds the four count matrices with any of the three t norms, applies the three operators, extends eleven binary measures with an explicit undefined value convention, and implements the micro as weighted macro identity, the covariance gap, the one hot floors with renormalisation, total cost for cost sensitive and ordinal evaluation, the closed form threshold, the ERM consistency test and the expected F1 curve. A small softmax regression is trained on an imbalanced four class problem and reported under every operator.
Running it reproduces Example 1, confirms the multiclass collapse, Theorem 1 and Corollary 6 to six decimals on random problems, every floor in Table 7, the marginal consistency of the product t norm, Theorem 4, the closed form thresholds against a grid search, and the half F1 threshold. It also shows the exemplar collapse, with exemplar precision, recall and F1 all equal to accuracy.
# Indicator matrix evaluation framework (aitrendblend reconstruction)
# Based on Prati, "A unified algebraic framework for classification performance evaluation",
# Information Fusion 138 (2027) 104767. Independent implementation in PyTorch, written from the
# paper's definitions. The paper's own code is distributed as supplementary material.

import math
import torch
import torch.nn as nn
import torch.nn.functional as F

# ---------------------------------------------------------------------------
# 1. Indicator matrices and the four count matrices (Definitions 1 and 2)
# ---------------------------------------------------------------------------
def one_hot(labels, m):
    return F.one_hot(labels, m).float()


def t_norm(a, b, kind="product"):
    """Product, Godel (minimum) and Lukasiewicz t norms, used for soft labels."""
    if kind == "product":
        return a * b
    if kind == "godel":
        return torch.minimum(a, b)
    if kind == "lukasiewicz":
        return torch.clamp(a + b - 1, min=0)
    raise ValueError(kind)


def count_matrices(Y, Yh, kind="product"):
    """TP = Y and Yh, FP = not Y and Yh, FN = Y and not Yh, TN = not Y and not Yh.
    For 0/1 inputs every t norm reduces to Boolean AND. For soft inputs the
    product t norm is the only one whose cells reproduce the marginals (Theorem 3)."""
    T = lambda a, b: t_norm(a, b, kind)
    return {"tp": T(Y, Yh), "fp": T(1 - Y, Yh), "fn": T(Y, 1 - Yh), "tn": T(1 - Y, 1 - Yh)}


# ---------------------------------------------------------------------------
# 2. The three aggregation operators (Definitions 3 to 5)
# ---------------------------------------------------------------------------
def agg(Mx, op):
    if op == "global":      # Sigma_1, micro
        return Mx.sum()
    if op == "column":      # Sigma_m, per class or label, macro and weighted
        return Mx.sum(0)
    if op == "row":         # Sigma_n, per example, exemplar
        return Mx.sum(1)
    raise ValueError(op)


# ---------------------------------------------------------------------------
# 3. Binary measures written on (tp, fp, fn, tn) (Table 2)
# ---------------------------------------------------------------------------
def _div(a, b):
    return torch.where(b > 0, a / torch.where(b > 0, b, torch.ones_like(b)), torch.full_like(a, float("nan")))


MEASURES = {
    "accuracy":    lambda tp, fp, fn, tn: _div(tp + tn, tp + fp + fn + tn),   # label accuracy when micro
    "error":       lambda tp, fp, fn, tn: _div(fp + fn, tp + fp + fn + tn),
    "precision":   lambda tp, fp, fn, tn: _div(tp, tp + fp),
    "recall":      lambda tp, fp, fn, tn: _div(tp, tp + fn),
    "specificity": lambda tp, fp, fn, tn: _div(tn, tn + fp),
    "f1":          lambda tp, fp, fn, tn: _div(2 * tp, 2 * tp + fp + fn),
    "jaccard":     lambda tp, fp, fn, tn: _div(tp, tp + fp + fn),
    "balanced_acc": lambda tp, fp, fn, tn: 0.5 * (_div(tp, tp + fn) + _div(tn, tn + fp)),
    "gmean":       lambda tp, fp, fn, tn: torch.sqrt(_div(tp, tp + fn) * _div(tn, tn + fp)),
    "mcc":         lambda tp, fp, fn, tn: _div(tp * tn - fp * fn,
                                               torch.sqrt((tp + fp) * (tp + fn) * (tn + fp) * (tn + fn))),
    "kappa":       lambda tp, fp, fn, tn: _kappa(tp, fp, fn, tn),
}


def _kappa(tp, fp, fn, tn):
    n = tp + fp + fn + tn
    po = _div(tp + tn, n)
    pe = _div((tp + fn) * (tp + fp) + (tn + fp) * (tn + fn), n * n)
    return _div(po - pe, 1 - pe)


# Linear forms <a, v> / <b, v> for decomposable measures (Proposition 1), v = (tp, fp, fn, tn)
LINEAR_FORMS = {
    "accuracy":  ((1, 0, 0, 1), (1, 1, 1, 1)),
    "precision": ((1, 0, 0, 0), (1, 1, 0, 0)),
    "recall":    ((1, 0, 0, 0), (1, 0, 1, 0)),
    "specificity": ((0, 0, 0, 1), (0, 1, 0, 1)),
    "f1":        ((2, 0, 0, 0), (2, 1, 1, 0)),
    "jaccard":   ((1, 0, 0, 0), (1, 1, 1, 0)),
}


# ---------------------------------------------------------------------------
# 4. Measure extension by operator substitution (Eqs. 5 to 8)
# ---------------------------------------------------------------------------
def extend(name, Y, Yh, op, weighted=False, kind="product", undefined="exclude"):
    C = count_matrices(Y, Yh, kind)
    v = [agg(C[k], op) for k in ("tp", "fp", "fn", "tn")]
    vals = MEASURES[name](*v)
    if op == "global":
        return vals.item()
    if undefined == "zero":                      # scikit learn style default
        vals = torch.nan_to_num(vals, nan=0.0)
    ok = ~torch.isnan(vals)
    if weighted and op == "column":              # prevalence weighted average
        w = Y.sum(0)[ok]
        return (vals[ok] * w).sum().item() / w.sum().item()
    return vals[ok].mean().item()                # Eq. 8, average over defined entries


# ---------------------------------------------------------------------------
# 5. Identities from Section 7
# ---------------------------------------------------------------------------
def micro_as_weighted_macro(name, Y, Yh):
    """Theorem 1, micro = denominator weighted average of per class values."""
    a, b = (torch.tensor(x, dtype=torch.float) for x in LINEAR_FORMS[name])
    C = count_matrices(Y, Yh)
    V = torch.stack([agg(C[k], "column") for k in ("tp", "fp", "fn", "tn")], 1)  # (m, 4)
    num, den = V @ a, V @ b
    return (num.sum() / den.sum()).item(), ((den * (num / den)).sum() / den.sum()).item()


def micro_macro_gap(name, Y, Yh):
    """Corollary 6, micro minus macro equals Cov(w, M) divided by mean(w)."""
    a, b = (torch.tensor(x, dtype=torch.float) for x in LINEAR_FORMS[name])
    C = count_matrices(Y, Yh)
    V = torch.stack([agg(C[k], "column") for k in ("tp", "fp", "fn", "tn")], 1)
    w, M = V @ b, (V @ a) / (V @ b)
    cov = ((w - w.mean()) * (M - M.mean())).mean()
    return (V @ a).sum().item() / w.sum().item() - M.mean().item(), (cov / w.mean()).item()


def worst_case_floor(name, m):
    """Table 7, value of the micro measure when every one hot prediction is wrong."""
    n = 1.0
    tp, fp, fn, tn = (torch.tensor(x) for x in (0.0, n, n, n * (m - 2)))
    return MEASURES[name](tp, fp, fn, tn).item()


def renormalise(value, floor, top=1.0):
    """Affine map that sends the attainable floor to 0 and the maximum to 1."""
    return (value - floor) / (top - floor)


# ---------------------------------------------------------------------------
# 6. Cost sensitive and ordinal evaluation (Eq. 16, Theorem 4)
# ---------------------------------------------------------------------------
def total_cost(Y, Yh, cost):
    """Bilinear form sum_ij (Y K Yh^T)_ii, i.e. trace(Y K Yh^T)."""
    return torch.einsum("ij,jk,ik->", Y, cost, Yh).item()


def ordinal_cost(m, p=1):
    idx = torch.arange(m, dtype=torch.float)
    return (idx[:, None] - idx[None, :]).abs() ** p        # p = 1 gives MAE, p = 2 gives MSE


# ---------------------------------------------------------------------------
# 7. Bayes optimal thresholds (Proposition 9) and the F1 fixed point
# ---------------------------------------------------------------------------
def bayes_threshold(alpha, beta, gamma, delta):
    return (beta + delta) / (alpha + beta + gamma + delta)


def erm_consistent(alpha, beta, gamma, delta):
    return math.isclose(alpha + gamma, beta + delta)


def expected_linear_objective(eta, t, alpha, beta, gamma, delta):
    f = (eta >= t).float()
    return (f * (alpha * eta - beta * (1 - eta)) + (1 - f) * (-gamma * eta + delta * (1 - eta))).mean().item()


def expected_f1_curve(eta, grid):
    """Expected F1 under calibrated probabilities, 2E[TP] / (2E[TP] + E[FP] + E[FN])."""
    out = []
    for t in grid:
        f = (eta >= t).float()
        tp, fp, fn = (f * eta).sum(), (f * (1 - eta)).sum(), ((1 - f) * eta).sum()
        out.append((2 * tp / (2 * tp + fp + fn)).item())
    return torch.tensor(out)


# ---------------------------------------------------------------------------
# 8. A small classifier to evaluate (training loop and evaluation function)
# ---------------------------------------------------------------------------
class SoftmaxRegression(nn.Module):
    def __init__(self, d, m):
        super().__init__()
        self.lin = nn.Linear(d, m)

    def forward(self, x):
        return self.lin(x)


def train_classifier(x, y, m, epochs=300, lr=0.05):
    model = SoftmaxRegression(x.size(1), m)
    opt = torch.optim.Adam(model.parameters(), lr=lr)
    for _ in range(epochs):
        opt.zero_grad(); F.cross_entropy(model(x), y).backward(); opt.step()
    return model


def evaluate_report(Y, Yh, measures=("precision", "recall", "f1", "balanced_acc", "mcc")):
    rows = {}
    for name in measures:
        rows[name] = {"micro": extend(name, Y, Yh, "global"),
                      "macro": extend(name, Y, Yh, "column"),
                      "weighted": extend(name, Y, Yh, "column", weighted=True),
                      "exemplar": extend(name, Y, Yh, "row")}
    return rows


# ---------------------------------------------------------------------------
# 9. Smoke test, every identity checked numerically
# ---------------------------------------------------------------------------
if __name__ == "__main__":
    torch.manual_seed(0)

    # Example 1 of the paper, rebuilt from its class sizes and confusion matrix
    Cmat = torch.tensor([[110, 10, 10], [20, 40, 5], [25, 5, 50]])
    y = torch.cat([torch.full((int(Cmat[i].sum()),), i) for i in range(3)])
    yh = torch.cat([torch.cat([torch.full((int(Cmat[i, j]),), j) for j in range(3)]) for i in range(3)])
    Y, Yh = one_hot(y, 3), one_hot(yh, 3)
    print("Example 1, micro BA, G-mean, MCC:",
          [round(extend(k, Y, Yh, "global"), 3) for k in ("balanced_acc", "gmean", "mcc")])
    print("Example 1, macro BA, G-mean, MCC:",
          [round(extend(k, Y, Yh, "column"), 3) for k in ("balanced_acc", "gmean", "mcc")])

    # Theorem 2, micro precision = micro recall = micro F1 = accuracy in multiclass
    acc = (y == yh).float().mean().item()
    print("Theorem 2:", round(acc, 4), [round(extend(k, Y, Yh, "global"), 4) for k in ("precision", "recall", "f1")])

    # Theorem 1 and Corollary 6 on random imbalanced 5 class problems
    for _ in range(3):
        m = 5; n = 400
        pri = torch.distributions.Dirichlet(torch.ones(m)).sample()
        yt = torch.multinomial(pri, n, replacement=True)
        yp = torch.where(torch.rand(n) < 0.7, yt, torch.randint(0, m, (n,)))
        Yt, Yp = one_hot(yt, m), one_hot(yp, m)
        a, b = micro_as_weighted_macro("f1", Yt, Yp)
        g1, g2 = micro_macro_gap("recall", Yt, Yp)
        print(f"Theorem 1 micro F1 {a:.6f} = weighted macro {b:.6f}   Corollary 6 gap {g1:+.6f} = {g2:+.6f}")

    # Table 7 floors and their renormalisation
    for m in (3, 10):
        print(f"m={m} floors:", {k: round(worst_case_floor(k, m), 3)
                                 for k in ("accuracy", "specificity", "balanced_acc", "mcc", "kappa", "f1")})

    # Theorem 3, product t norm reproduces soft marginals, Godel and Lukasiewicz do not
    Ys, Yps = torch.rand(6, 4), torch.rand(6, 4)
    for kind in ("product", "godel", "lukasiewicz"):
        C = count_matrices(Ys, Yps, kind)
        err = ((C["tp"] + C["fn"]) - Ys).abs().max().item()
        print(f"t norm {kind:12s} max marginal error {err:.4f}")

    # Theorem 4, ordinal MAE equals cost sensitive evaluation with |i - j| costs
    yo, ypo = torch.randint(0, 5, (50,)), torch.randint(0, 5, (50,))
    print("Theorem 4:", (yo - ypo).abs().float().mean().item(),
          total_cost(one_hot(yo, 5), one_hot(ypo, 5), ordinal_cost(5)) / 50)

    # Proposition 9 against a grid search, and the F1 fixed point t* = F1*/2
    eta = torch.distributions.Beta(0.6, 2.5).sample((20000,))
    grid = torch.linspace(0, 1, 2001)
    for coef in [(1, 0, 0, 1), (0, 1, 5, 0), (3, 1, 2, 0)]:
        best = grid[torch.tensor([expected_linear_objective(eta, t, *coef) for t in grid]).argmax()].item()
        print(f"Prop 9 {coef}: closed form {bayes_threshold(*coef):.4f}, grid {best:.4f}, ERM consistent {erm_consistent(*coef)}")
    f1 = expected_f1_curve(eta, grid)
    print(f"F1: best threshold {grid[f1.argmax()].item():.4f}, half of best F1 {f1.max().item() / 2:.4f}")

    # Train a small classifier and report every operator
    m, d, n = 4, 8, 2000
    centers = torch.randn(m, d) * 1.5
    prior = torch.tensor([0.7, 0.2, 0.07, 0.03])
    yy = torch.multinomial(prior, n, replacement=True)
    xx = centers[yy] + torch.randn(n, d)
    model = train_classifier(xx[:1500], yy[:1500], m)
    with torch.no_grad():
        pred = model(xx[1500:]).argmax(1)
    rep = evaluate_report(one_hot(yy[1500:], m), one_hot(pred, m))
    for k, v in rep.items():
        print(f"{k:13s}", {a: round(b, 3) for a, b in v.items()})
Two practical notes. The extend function takes an undefined argument, so you can report both the exclusion convention and the zero convention side by side. And because the count matrices accept real values, the same code evaluates soft labels without modification.
What one algebra adds to evaluation
The core achievement of this paper is a generative mechanism. Write a binary metric in terms of four counts, pick one of three summation operators, and you have its micro, macro, weighted and exemplar versions for multiclass and multilabel problems, with soft labels, costs and ordinal structure handled by the same machinery. No metric needs its own derivation again.
The conceptual shift is from treating averaging schemes as conventions to treating them as algebra. Once micro averaging is a weighted macro average, its gap is a covariance. Once one hot encoding is a constraint on admissible matrices, metric floors follow. Once the confusion matrix has a fixed number of degrees of freedom, redundancy in a results table can be counted. Each of these turns a vague intuition into a test you can run.
The ideas transfer readily. Segmentation metrics are per pixel versions of the same four counts, and Dice is F1 under a different name. Retrieval, recommendation and anomaly detection all use precision and recall with their own averaging choices. Any field that summarises many binary decisions into one number faces the same operator choice and the same pitfalls.
The limits are mostly on the empirical side. The illustrations are small, the threshold experiment supports the theory in expectation but not convincingly on finite test sets, and the paper does not yet address uncertainty in the metric estimates themselves. None of that touches the algebra, which held up in every check we ran.
Future work could add confidence intervals under each operator, extend the indicator matrices to sequences and graphs, and connect this algebraic view to the decision theoretic view of metrics as expected losses. For now, the most useful thing a reader can take away is short. Before trusting a number in a results table, ask which operator produced it, what happens when a class is missing, and what the same metric would say about a model that is always wrong.
Frequently asked questions
What is the difference between micro, macro and exemplar averaging?
Micro averaging pools true and false positives and negatives across all classes and computes the metric once. Macro averaging computes the metric per class and averages the results. Exemplar averaging computes it per example and averages, which mainly matters for multilabel problems.
Why does micro F1 equal accuracy in multiclass classification?
With one label per example, every wrong prediction adds exactly one false positive and one false negative, so pooled false positives and false negatives are equal. Micro precision, micro recall and micro F1 then all reduce to correct predictions divided by the number of examples, which is accuracy.
When is micro averaging a weighted macro average?
For metrics that are a single ratio of linear counts, such as precision, recall, F1 and Jaccard, micro averaging equals macro averaging weighted by each class’s denominator. For balanced accuracy, MCC and the G mean no such weighting exists, and the pooled value can even exceed every per class value.
What score does a completely wrong classifier get?
Under one hot encoding with ten classes, a classifier wrong on every example still gets a label accuracy of 0.8, a specificity of 0.889, a balanced accuracy of 0.444 and an MCC of minus 0.111, while accuracy, precision, recall and F1 correctly reach 0.
How do I choose a decision threshold for a cost sensitive metric?
For metrics with a linear numerator and a denominator that does not depend on predictions, threshold calibrated probabilities at the sum of the coefficients favouring a negative prediction divided by the sum of all coefficients. For a five to one cost of missed positives to false alarms this gives about 0.167. For F1, the optimal threshold equals half the best achievable F1.
Which t norm should be used for soft labels?
The product t norm is the only one under which the soft confusion matrices reproduce the actual and predicted label memberships, so it behaves like an ordinary contingency table. It implicitly treats label uncertainty and prediction uncertainty as independent.
Read the full paper
The open access article includes all proofs, the full catalogue of extended measures, the twelve special settings and the supplementary code.
Prati, R. C. (2027). A unified algebraic framework for classification performance evaluation. Information Fusion, 138, 104767. doi.org/10.1016/j.inffus.2026.104767. Open access under CC BY 4.0.
This analysis is based on the published paper and an independent evaluation of its claims. The exemplar collapse observation, the half F1 threshold derivation and check, the reading of Table 11, the gradient remark and the PyTorch implementation are the aitrendblend team’s own work. All other figures are taken from the paper.